Data modeling is the process of conceptualizing and visualizing how data is captured, stored, and used by an organization. A data model defines the entities, attributes, and relationships a database must support, so teams build one before they write a schema.
For the full process, benefits, and tooling, read our guide to data modeling techniques and tools.
Types of data models covered
Relational: Organizes data into tables, rows, and columns connected by keys.
Entity-relationship (ER): Diagrams entities, attributes, and relationships before you build a database.
Dimensional: Structures data into facts and dimensions for analytics and reporting.
Hierarchical: Arranges records in a tree of parent-child relationships.
Network: Connects records through owner-member sets, so one record can belong to several parents.
Object-oriented: Stores data as objects with properties and methods.
NoSQL: Covers document, key-value, column-family, and graph models built for flexibility and scale.
What is data modeling?
In data modeling, you typically define entities (such as objects, people, or concepts), their attributes (characteristics or properties), and the relationships between these entities. Teams often capture this in ER diagrams or Unified Modeling Language (UML) diagrams.
A model built before the schema prevents the rework that comes from discovering a missing relationship after tables are populated.
3 levels of data modeling
Data modeling has three levels: conceptual, logical, and physical. Each level adds detail to the one before it.
Conceptual data model: A high-level representation of the key entities in a domain and how they relate, without technical detail. Teams build it first to define the scope of a new database and give stakeholders a shared understanding of the domain.
Logical data model: A detailed blueprint of entities, attributes, relationships, and constraints that is independent of any specific database technology. Designers use it as the basis for the database schema.
Physical data model: The implementation design for a specific database system, including data types, indexes, storage structures, and optimization settings. At this level, you're ready to build the database.
Types of data models
The types below describe how a model organizes data, and each one fits different purposes in data management.
Model type | Structure | Best use case | Example |
Relational | Tables, rows, and columns linked by primary and foreign keys | Transactional systems such as banking and e-commerce orders | MySQL, PostgreSQL, Oracle |
Entity-relationship | Entities, attributes, and relationships drawn as a diagram | Planning a database before you build it, such as an enterprise system or a customer relationship management database | Library system with Book, Author, and Member entities |
Dimensional | Fact tables of measures joined to dimension tables of descriptive attributes | Data warehousing and analytics, such as retail sales analysis and financial reporting | Sales fact table with date, product, and customer dimensions |
Hierarchical | Tree of parent-child records under a single root | Data with a natural tree shape, such as file systems and configuration settings | IBM Information Management System (IMS), Windows Registry |
Network | Records linked through owner-member sets | Data where one record relates to several parents | Databases built on the Conference on Data Systems Languages (CODASYL) standard |
Object-oriented | Objects with properties and methods | Complex data such as computer-aided design and manufacturing (CAD/CAM), multimedia, and geographic information systems | Java or C++ objects stored in an object database |
NoSQL | Document, key-value, column-family, or graph structures | Workloads that need flexible schemas, scalability, or specialized access patterns | MongoDB, Redis, Cassandra, Neo4j |
What is a relational data model?
Used solely for relational databases, the relational data model defines data in terms of tables, rows, and columns. It's the foundation of relational database management systems like MySQL, PostgreSQL, and Oracle. In a relational data model, entities are represented as tables, attributes as columns, and relationships as foreign keys. Relational models suit transactional systems that need consistent, structured records, such as banking and e-commerce order processing.
What is an entity-relationship data model?
A conceptual and visual representation used to describe the data and relationships within a system or organization, ER models are particularly useful in database design. In an ER model, entities represent real-world objects or concepts (e.g., a person, a product, a company) and are depicted as rectangles. Relationships between entities are shown with lines connecting them to indicate how entities are related to each other.
Attributes are also a key component of an ER model. They describe properties or characteristics of entities and are typically listed within the entity rectangles.
ER models help stakeholders, including database designers, developers, and business analysts, to communicate effectively about data requirements and system structure before implementing it. They give a high-level overview of the database schema, which makes the design process easier and helps the resulting database meet the organization's needs. Teams commonly use them to plan enterprise systems and customer relationship management databases.
What is dimensional data modeling?
Dimensional data modeling organizes data into fact tables (containing numerical measures) and dimension tables (containing descriptive attributes). Used primarily in data warehousing and business intelligence applications, dimensional models are optimized for querying and analysis, typically using online analytical processing techniques. Retail sales analysis and financial reporting dashboards are common uses.
What is a hierarchical data model?
Often used in early database management systems, a hierarchical data model organizes data into a tree-like structure. Records connect through parent-child relationships. Each node (record) has one parent and can have multiple children, but children can only have one parent. The top node of this hierarchy is called the root, and it does not have a parent.
Hierarchical data models use single-path navigation. To access a particular record, you start from the root and traverse through the tree following a single path.
The relationships between records are predefined, meaning the structure is fixed and cannot be changed without significant redesign. This rigidity impairs scalability and adaptation.
Hierarchical models still appear where data follows a tree. IBM IMS, which banks and insurance companies still use for high-volume transaction processing, is a hierarchical database, and so is the Windows Registry. XML documents also follow a tree structure.
What is an object-oriented data model?
An object-oriented data model represents data as objects with properties (attributes) and methods. It's used in object-oriented programming environments, typically with languages such as Java and C++, and in object-oriented database management systems (OODBMS). It suits complex data such as computer-aided design and manufacturing (CAD/CAM) files, multimedia content, and geographic information systems.
What is a network data model?
A network data model organizes data as collections of records linked through owner-member sets. Unlike the hierarchical model, a record can take part in several sets, so it can have more than one parent. CODASYL defined the standard for network databases. Each set links one owner record to many member records, so a many-to-many relationship needs an intermediate link record.
Network data models give you flexibility in representing complex relationships between records and support efficient traversal for certain types of queries. However, they also have limitations, including model complexity and the need for specialized query languages. Graph databases carry the idea forward with nodes and edges, and teams use them for connected data such as supply chains and logistics routing.
What are NoSQL data models?
NoSQL databases use data models that differ from the relational model, and each one is optimized for specific use cases. They may offer advantages in scalability, flexibility, and performance.
Document-oriented (for example, MongoDB): Stores flexible documents. Common uses include content management and product catalogs.
Key-value (for example, Redis): Maps unique keys to values. Common uses include caching and session storage.
Column-family (for example, Cassandra): Groups data into column families. Common uses include time-series and analytics workloads.
Graph (for example, Neo4j): Stores nodes and the relationships between them. Common uses include supply chain, fraud detection, and recommendation systems.
5 examples of data modeling
Relational data model example
A relational data model organizes data into tables connected by primary and foreign key relationships. A basic example is the "Employee" database, which has two tables.
Tables
Employees: Contains information about each employee. Columns: EmployeeID (primary key), FirstName, LastName, BirthDate, HireDate, and DepartmentID (foreign key).
Departments: Contains information about each department. Columns: DepartmentID (primary key), DepartmentName, ManagerID (foreign key), and Location.
Relationships
Each employee belongs to exactly one department. The DepartmentID column in the Employees table is a foreign key that references DepartmentID in the Departments table.
Each department can have multiple employees. The same key relationship shows this: one DepartmentID in the Departments table matches many rows in the Employees table.
This model stores employee and department information in separate tables and links them with primary and foreign keys. It's a fundamental concept in database design and management.
Entity-relationship data model example
An entity-relationship data model describes the entities in a system, their attributes, and the relationships between them. Consider a simplified model for a library management system. It has entities such as Book, Author, and Member, along with relationships between them.
Entities
Book: Represents individual books in the library. It might have attributes like BookID, Title, ISBN, and PublicationYear.
Author: Represents authors of the books. Attributes could include AuthorID, Name, and Nationality.
Member: Represents library members who borrow books. Attributes might include MemberID, Name, and Address.
Relationships
Authored By: Connects the Book and Author entities, indicating which authors wrote which books. It is a many-to-many relationship because one book can have multiple authors, and one author can write multiple books.
Borrowed By: Connects the Member and Book entities, indicating which members borrowed which books and when. It is a one-to-many relationship because one member can borrow multiple books, but each book can be borrowed by only one member at a time.
ER models are visually oriented, so the easiest way to understand them is to look at a diagram of the entities and the relationships between them.
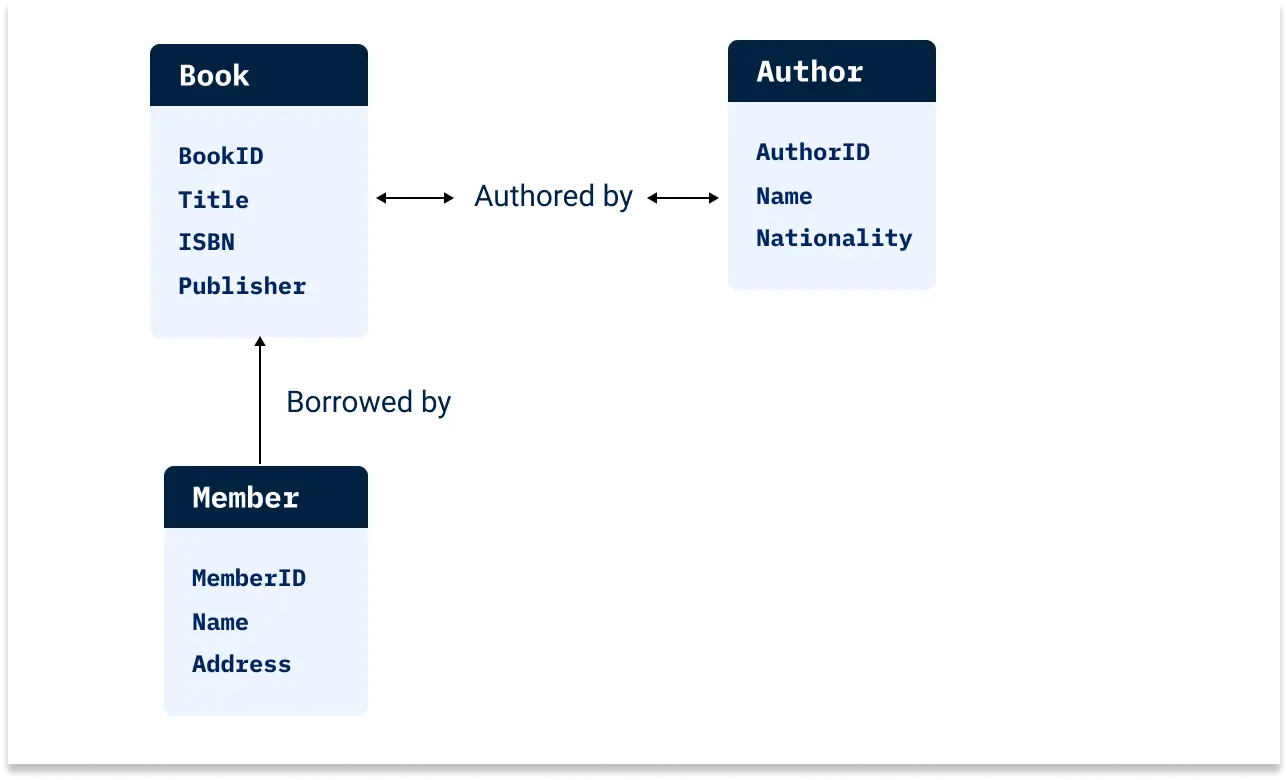
In this diagram:
Headers (names above lists) are entities.
The lists under each entity are attributes.
Lines indicate relationships between entities. An arrow means multiple; no arrow means singular.
This model shows how books, authors, and members relate to each other, which makes it well suited to designing the database schema and implementing the system.
Hierarchical data model example
A hierarchical data model arranges data in a tree of parent-child relationships. Each parent can have multiple children, but each child has only one parent, which is the defining feature of the model. A file system is a common example:
Root
Blogs
Work
Personal
Restaurant reviews
Italian.docx
Thai.docx
In this hierarchical data model:
The root node represents the top-level directory of the file system.
Each directory (for example, Work) is a parent node.
Each file (for example, Thai.docx) is a leaf node, or child node.
Each directory can contain multiple files and subdirectories.
This structure reflects a typical file system, where directories contain files and other directories in a nested hierarchy. The Windows Registry, which stores operating system configuration settings, follows the same tree structure.
Network data model example
A network data model links records through owner-member sets, so one record can relate to several others in a non-hierarchical way. In a school database, for example, Student and Course records each own sets of Enrollment link records, which is how the model represents the many-to-many relationship between students and courses.
The key components of a network data model are:
Records (nodes): The fundamental units of data. Each record typically represents an entity, such as a person, place, or thing, with attributes that describe it.
Sets (links): The owner-member connections between record types. A member record can take part in several sets, and many-to-many relationships use an intermediate link record.
Schema: Defines the structure of the data by specifying the record types, the set types, and the attributes of each.
Traversal: Navigating from one record to another along the sets to retrieve related data.
Dimensional data model example
A dimensional data model organizes data into a central fact table of measures and surrounding dimension tables of descriptive attributes. Dimensional models often arise from data warehousing requirements, where the focus is efficient querying and analysis of large volumes of data. A simple example is the "Sales" data model, commonly used in retail businesses.
Fact table
A Sales table is a common example of a fact table. It contains:
Each row in the fact table holds data about one sales transaction. You can extend the table with more refined breakdowns of sales and revenue.
Dimension tables
This example has one fact table and three dimension tables, a layout known as a star schema.
Date dimension: Contains details about dates, such as DateKey (primary key), Date, DayOfWeek, Month, Quarter, and Year. You can use this dimension to analyze sales trends over time.
Product dimension: Contains data about products, including ProductKey (primary key), ProductName, Category, and Brand. This dimension captures attributes of your products.
Customer dimension: Stores data about customers, including CustomerKey (primary key), CustomerName, Address, and Phone. This dimension lets you analyze sales by customer demographics.
Relationships
The fact table (Sales) connects to each dimension table (Date, Product, Customer) through foreign key relationships (DateKey, ProductKey, CustomerKey). These relationships let you make requests to the fact table for sales data and retrieve related details from the dimension tables, such as the date of sale, the product sold, and the customer. Because every dimension is one join away from the fact table, queries stay simple.
Data modeling with CData Connect AI
CData Connect AI includes a virtual data layer that models live data from hundreds of sources into business views, without moving the data. With it, you can:
Define business logic once, in SQL, so every tool and AI agent works from the same definitions.
Organize models into virtual schemas and build views on top of views, from raw source structures up to a business layer.
Join data across systems in a single request, and choose live, cached, or materialized delivery for each dataset.
Enforce permissions down to a single column, with row-level security and column masking.
Trace any view back to its source tables and columns with data lineage.
Because Connect AI checks permissions on every request, a model you define once behaves the same way in every tool that uses it. The virtual data layer in CData Connect AI Gateway lets you define business views once over live data from hundreds of sources, with permissions enforced on every request.
Get a trial of CData Connect AI





