




JD Edwards to Apache Kafka Data Integration
The leading hybrid-cloud solution for Apache Kafka integration. Automated continuous ETL/ELT data replication from JD Edwards to Apache Kafka.
Whether you're managing operational reporting, connecting data for analytics, or ensuring disaster recovery, CData Sync's no-code approach to data integration simplifies the process of putting JD Edwards data to work.


JD Edwards:
JD Edwards is an integrated enterprise resource planning (ERP) suite from Oracle designed for asset-intensive and project-driven industries such as manufacturing, construction, and distribution. It provides end-to-end management of financials, procurement, inventory, manufacturing, and human resources, and is available across cloud, on-premises, and hybrid deployment models to suit a wide range of organizational needs.

Apache Kafka:
Apache Kafka is an open-source distributed event streaming platform that is designed to handle high volumes of real-time data. It allows for the seamless integration of various systems and applications, enabling the efficient processing, storing, and streaming of data in a fault-tolerant and scalable manner. Kafka is widely used for building real-time data pipelines and streaming applications.
Integrate JD Edwards and Apache Kafka with CData Sync
CData Sync provides a straightforward way to continuously pipeline your JD Edwards data to any database, data lake, or data warehouse, making it easily available to analytics, reporting, AI, and machine learning.
- Synchronize data with a wide range of traditional and emerging databases including Apache Kafka.
- Replicate JD Edwards data to database's and data warehouse systems to facilitate operational reporting, BI, and analytics.
- Offload queries from JD Edwards to reduce load and increase performance.
- Connect JD Edwards to business analytics for BI and decision support.
- Archive JD Edwards data for disaster recovery.
Integrate JD Edwards with Apache Kafka
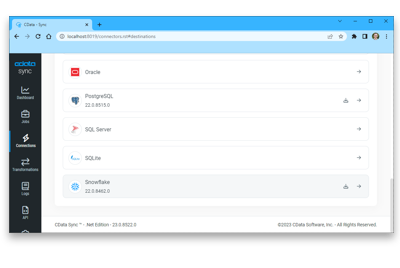
JD Edwards Data Integration Features
Ditch the code and complex setups to move more data in less time. Connect JD Edwards to any destination with drag-and-drop ease.
Incremental updates and automatic schema replication eliminate the headaches of JD Edwards data integration, ensuring Apache Kafka always has the latest data.
Replicate all the data that matters with predictable, transparent pricing. Unlimited replication between JD Edwards and Apache Kafka.
Other JD Edwards Data Integration Tools
Easily create data pipelines that integrate and replicate data from JD Edwards to any supported data store, including:


