




Load BugHerd Data to a Database Using Embulk
Embulk is an open source bulk data loader. When paired with the CData API Driver for JDBC, Embulk easily loads data from BugHerd to any supported destination. In this article, we explain how to use the CData API Driver for JDBC in Embulk to load BugHerd data to a MySQL dtabase.
With built-in optimized data processing, the CData JDBC Driver offers unmatched performance for interacting with live BugHerd data. When you issue complex SQL queries to BugHerd, the driver pushes supported SQL operations, like filters and aggregations, directly to BugHerd and utilizes the embedded SQL engine to process unsupported operations client-side (often SQL functions and JOIN operations).
Configure a JDBC Connection to BugHerd Data
Before creating a bulk load job in Embulk, note the installation location for the JAR file for the JDBC Driver (typically C:\Program Files\CData\CData API Driver for JDBC\lib).
Embulk supports JDBC connectivity, so you can easily connect to BugHerd and execute SQL queries. Before creating a bulk load job, create a JDBC URL for authenticating with BugHerd.
Start by setting the Profile connection property to the location of the BugHerd Profile on disk (e.g. C:\profiles\BugHerd.apip). Next, set the ProfileSettings connection property to the connection string for BugHerd (see below).
BugHerd API Profile Settings
BugHerd uses HTTP Basic authentication with an API key as the username. To obtain an API key:
- Sign in to your BugHerd account at https://www.bugherd.com
- Navigate to Settings > General Settings
- Locate the API Key section and copy the generated key
After obtaining your API key, set the following connection properties:
- AuthScheme: Set this to APIKey.
Set the following in the ProfileSettings connection property:
- APIKey: Set this to your BugHerd API key. The driver uses the key as the Basic auth username and sets the password internally to the literal value 'x' as required by BugHerd.
Built-in Connection String Designer
For assistance in constructing the JDBC URL, use the connection string designer built into the BugHerd JDBC Driver. Either double-click the JAR file or execute the jar file from the command-line.
java -jar cdata.jdbc.api.jar
Fill in the connection properties and copy the connection string to the clipboard.
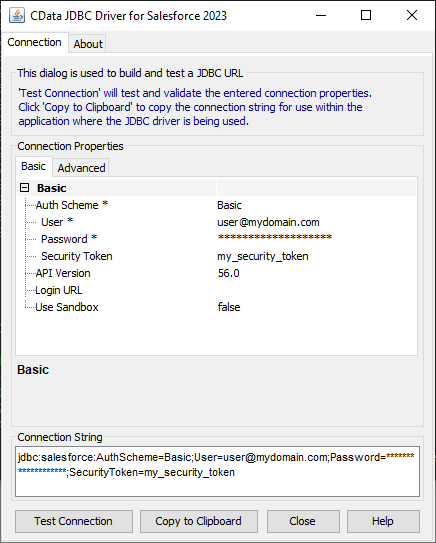
Below is a typical JDBC connection string for BugHerd:
jdbc:api:Profile=C:\profiles\BugHerd.apip;AuthScheme=APIKey;ProfileSettings='APIKey=your_api_key';
Load BugHerd Data in Embulk
After installing the CData JDBC Driver and creating a JDBC connection string, install the required Embulk plugins.
Install Embulk Input & Output Plugins
- Install the JDBC Input Plugin in Embulk.
https://github.com/embulk/embulk-input-jdbc/tree/master/embulk-input-jdbc - In this article, we use MySQL as the destination database. You can also choose SQL Server, PostgreSQL, or Google BigQuery as the destination using the output Plugins.
https://github.com/embulk/embulk-output-jdbc/tree/master/embulk-output-mysqlembulk gem install embulk-output-mysql
embulk gem install embulk-input-jdbc
With the input and output plugins installed, we are ready to load BugHerd data into MySQL using Embulk.
Create a Job to Load BugHerd Data
Start by creating a config file in Embulk, using a name like api-mysql.yml.
- For the input plugin options, use the CData API Driver for JDBC, including the path to the driver JAR file, the driver class (e.g. cdata.jdbc.api.APIDriver), and the JDBC URL from above
- For the output plugin options, use the values and credentials for the MySQL database
Sample Config File (api-mysql.yml)
in:
	type: jdbc
	driver_path: C:\Program Files\CData\CData API Driver for JDBC 20xx\lib\cdata.jdbc.api.jar
	driver_class: cdata.jdbc.api.APIDriver
	url: jdbc:api:Profile=C:\profiles\BugHerd.apip;AuthScheme=APIKey;ProfileSettings='APIKey=your_api_key';
	table: "Tasks"
out:
	type: mysql
	host: localhost
	database: DatabaseName
	user: UserId
	password: UserPassword
	table: "Tasks"
	mode: insert
After creating the file, run the Embulk job.
embulk run api-mysql.yml
After running the the Embulk job, find the Salesforce data in the MySQL table.
Load Filtered BugHerd Data
In addition to loading data directly from a table, you can use a custom SQL query to have more granular control of the data loaded. You can also perform increment loads by setting a last updated column in a SQL WHERE clause in the query field.
in:
	type: jdbc
	driver_path: C:\Program Files\CData\CData API Driver for JDBC 20xx\lib\cdata.jdbc.api.jar
	driver_class: cdata.jdbc.api.APIDriver
	url: jdbc:api:Profile=C:\profiles\BugHerd.apip;AuthScheme=APIKey;ProfileSettings='APIKey=your_api_key';
	query: "SELECT Id, Title FROM Tasks WHERE [RecordId] = 1"
out:
	type: mysql
	host: localhost
	database: DatabaseName
	user: UserId
	password: UserPassword
	table: "Tasks"
	mode: insert
More Information & Free Trial
By using CData API Driver for JDBC as a connector, Embulk can integrate BugHerd data into your data load jobs. And with drivers for more than 200+ other enterprise sources, you can integrate any enterprise SaaS, big data, or NoSQL source as well. Download a 30-day free trial and get started today.