




How to Work with Claude Compliance Data in AWS Glue Jobs Using JDBC
AWS Glue is an ETL service from Amazon that allows you to easily prepare and load your data for storage and analytics. Using the PySpark module along with AWS Glue, you can create jobs that work with data over JDBC connectivity, loading the data directly into AWS data stores. In this article, we walk through uploading the CData JDBC Driver for Claude Compliance into an Amazon S3 bucket and creating and running an AWS Glue job to extract Claude Compliance data and store it in S3 as a CSV file.
Upload the CData JDBC Driver for Claude Compliance to an Amazon S3 Bucket
In order to work with the CData JDBC Driver for Claude Compliance in AWS Glue, you will need to store it (and any relevant license files) in an Amazon S3 bucket.
- Open the Amazon S3 Console.
- Select an existing bucket (or create a new one).
- Click Upload
- Select the JAR file (cdata.jdbc.claudecompliance.jar) found in the lib directory in the installation location for the driver.
Configure the Amazon Glue Job
- Navigate to ETL -> Jobs from the AWS Glue Console.
- Click Add Job to create a new Glue job.
- Fill in the Job properties:
- Name: Fill in a name for the job, for example: ClaudeComplianceGlueJob.
- IAM Role: Select (or create) an IAM role that has the AWSGlueServiceRole and AmazonS3FullAccess permissions policies. The latter policy is necessary to access both the JDBC Driver and the output destination in Amazon S3.
- Type: Select "Spark".
- Glue Version: Select "Spark 2.4, Python 3 (Glue Version 1.0)".
- This job runs: Select "A new script to be authored by you".
Populate the script properties: - Script file name: A name for the script file, for example: GlueClaudeComplianceJDBC
- S3 path where the script is stored: Fill in or browse to an S3 bucket.
- Temporary directory: Fill in or browse to an S3 bucket.
- Expand Security configuration, script libraries and job parameters (optional). For Dependent jars path, fill in or browse to the S3 bucket where you uploaded the JAR file. Be sure to include the name of the JAR file itself in the path, i.e.: s3://mybucket/cdata.jdbc.claudecompliance.jar
- Click Next. Here you will have the option to add connection to other AWS endpoints. So, if your Destination is Redshift, MySQL, etc, you can create and use connections to those data sources.
- Click "Save job and edit script" to create the job.
- In the editor that opens, write a python script for the job. You can use the sample script (see below) as an example.
Sample Glue Script
To connect to Claude Compliance using the CData JDBC driver, you will need to create a JDBC URL, populating the necessary connection properties. Additionally, you will need to set the RTK property in the JDBC URL (unless you are using a Beta driver). You can view the licensing file included in the installation for information on how to set this property.
The driver connects to Claude Compliance using a Compliance Access Key, the only supported authentication method. Set the following connection property:
- APIKey: The Compliance Access Key you created.
Creating a Compliance Access Key
- Enable the Compliance API for your organization.
- Sign in to claude.ai as a primary owner or organization owner and open Organization settings > API > Keys.
- Select Create Key and assign only the scopes your integration needs:
- read:compliance_activities for Activities and the typed activity views.
- read:compliance_org_data for organizations, roles, groups, and settings.
- read:compliance_user_data for users, chats, files, projects, and downloads.
- delete:compliance_user_data for the explicit Delete stored procedures.
- Create the key and copy it when it appears. The key starts with sk-ant-api01- and is shown only once.
Optionally, set OrganizationUUID to limit organization-scoped views (such as OrganizationUsers and ComplianceRoles) to a single linked organization. If it is left empty, those views default to the first available organization and do not include data from all linked organizations.
Built-in Connection String Designer
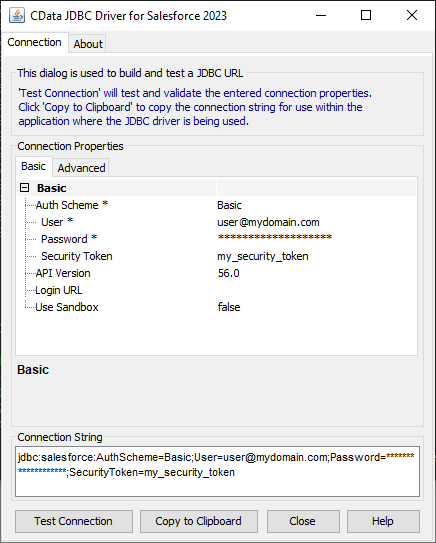
For assistance in constructing the JDBC URL, use the connection string designer built into the Claude Compliance JDBC Driver. Either double-click the JAR file or execute the JAR file from the command-line.
java -jar cdata.jdbc.claudecompliance.jar
Fill in the connection properties and copy the connection string to the clipboard.
To host the JDBC driver in Amazon S3, you will need a license (full or trial) and a Runtime Key (RTK). For more information on obtaining this license (or a trial), contact our sales team.
Below is a sample script that uses the CData JDBC driver with the PySpark and AWSGlue modules to extract Claude Compliance data and write it to an S3 bucket in CSV format. Make any necessary changes to the script to suit your needs and save the job.
import sys
from awsglue.transforms import *
from awsglue.utils import getResolvedOptions
from pyspark.context import SparkContext
from awsglue.context import GlueContext
from awsglue.dynamicframe import DynamicFrame
from awsglue.job import Job

args = getResolvedOptions(sys.argv, ['JOB_NAME'])

sparkContext = SparkContext()
glueContext = GlueContext(sparkContext)
sparkSession = glueContext.spark_session

##Use the CData JDBC driver to read Claude Compliance data from the Projects table into a DataFrame
##Note the populated JDBC URL and driver class name
source_df = sparkSession.read.format("jdbc").option("url","jdbc:claudecompliance:RTK=5246...;APIKey=your_compliance_access_key;").option("dbtable","Projects").option("driver","cdata.jdbc.claudecompliance.ClaudeComplianceDriver").load()

glueJob = Job(glueContext)
glueJob.init(args['JOB_NAME'], args)

##Convert DataFrames to AWS Glue's DynamicFrames Object
dynamic_dframe = DynamicFrame.fromDF(source_df, glueContext, "dynamic_df")

##Write the DynamicFrame as a file in CSV format to a folder in an S3 bucket.
##It is possible to write to any Amazon data store (SQL Server, Redshift, etc) by using any previously defined connections.
retDatasink4 = glueContext.write_dynamic_frame.from_options(frame = dynamic_dframe, connection_type = "s3", connection_options = {"path": "s3://mybucket/outfiles"}, format = "csv", transformation_ctx = "datasink4")

glueJob.commit()
Run the Glue Job
With the script written, we are ready to run the Glue job. Click Run Job and wait for the extract/load to complete. You can view the status of the job from the Jobs page in the AWS Glue Console. Once the Job has succeeded, you will have a CSV file in your S3 bucket with data from the Claude Compliance Projects table.
Using the CData JDBC Driver for Claude Compliance in AWS Glue, you can easily create ETL jobs for Claude Compliance data, whether writing the data to an S3 bucket or loading it into any other AWS data store.
Ready to get started?
Download a free trial of the Claude Compliance Driver to get started:
Download NowLearn more:
 Claude Compliance JDBC Driver
Rapidly create and deploy powerful Java applications that integrate with Claude Compliance data including Activities, Chats, ChatMessages, CodeArtifacts, ComplianceRoles, Organizations, OrganizationUsers, Projects, and more!