




How to work with DeTrack Data in Apache Spark using SQL
Apache Spark is a fast and general engine for large-scale data processing. When paired with the CData JDBC Driver for DeTrack, Spark can work with live DeTrack data. This article describes how to connect to and query DeTrack data from a Spark shell.
The CData JDBC Driver offers unmatched performance for interacting with live DeTrack data due to optimized data processing built into the driver. When you issue complex SQL queries to DeTrack, the driver pushes supported SQL operations, like filters and aggregations, directly to DeTrack and utilizes the embedded SQL engine to process unsupported operations (often SQL functions and JOIN operations) client-side. With built-in dynamic metadata querying, you can work with and analyze DeTrack data using native data types.
Install the CData JDBC Driver for DeTrack
Download the CData JDBC Driver for DeTrack installer, unzip the package, and run the JAR file to install the driver.
Start a Spark Shell and Connect to DeTrack Data
- Open a terminal and start the Spark shell with the CData JDBC Driver for DeTrack JAR file as the jars parameter:
$ spark-shell --jars /CData/CData JDBC Driver for DeTrack/lib/cdata.jdbc.api.jar - With the shell running, you can connect to DeTrack with a JDBC URL and use the SQL Context load() function to read a table.
Start by setting the Profile connection property to the location of the DeTrack Profile on disk (e.g. C:\profiles\DeTrack.apip). Next, set the ProfileSettings connection property to the connection string for DeTrack (see below).
DeTrack API Profile Settings
DeTrack uses API Key authentication. Your DeTrack API key is used to authenticate all requests via the X-API-Key header. You can obtain your API key from your DeTrack account settings at app.detrack.com under Settings > API & Webhooks.
After setting the following connection properties, you are ready to connect:
- AuthScheme: Set this to APIKey.
- APIKey: Set this to your DeTrack API key.
Built-in Connection String Designer
For assistance in constructing the JDBC URL, use the connection string designer built into the DeTrack JDBC Driver. Either double-click the JAR file or execute the jar file from the command-line.
java -jar cdata.jdbc.api.jarFill in the connection properties and copy the connection string to the clipboard.
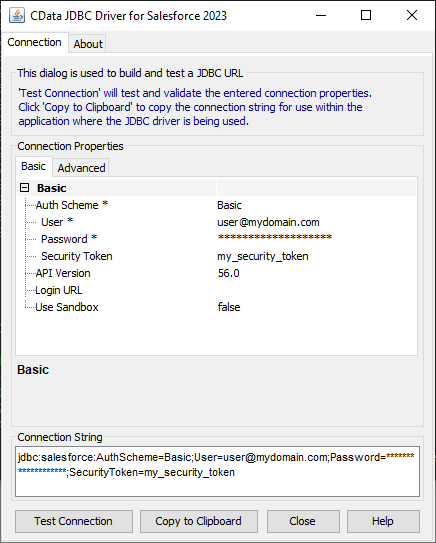
Configure the connection to DeTrack, using the connection string generated above.
scala> val api_df = spark.sqlContext.read.format("jdbc").option("url", "jdbc:api:Profile=C:\profiles\DeTrack.apip;AuthScheme=APIKey;ProfileSettings='APIKey=your_api_key';").option("dbtable","Routes").option("driver","cdata.jdbc.api.APIDriver").load() - Once you connect and the data is loaded you will see the table schema displayed.
Register the DeTrack data as a temporary table:
scala> api_df.registerTable("routes")-
Perform custom SQL queries against the Data using commands like the one below:
scala> api_df.sqlContext.sql("SELECT Id, Name FROM Routes WHERE Date = 2026-05-20").collect.foreach(println)You will see the results displayed in the console, similar to the following:

Using the CData JDBC Driver for DeTrack in Apache Spark, you are able to perform fast and complex analytics on DeTrack data, combining the power and utility of Spark with your data. Download a free, 30 day trial of any of the hundreds of CData JDBC Drivers and get started today.