




Build Pipelines with Live JD Edwards Data in Google Cloud Data Fusion (via CData Connect AI)

Google Cloud Data Fusion simplifies building and managing data pipelines by offering a visual interface to connect, transform, and move data across various sources and destinations, streamlining data integration processes. When combined with CData Connect AI, it provides access to JD Edwards data for building and managing ELT/ETL data pipelines. This article explains how to use CData Connect AI to create a live connection to JD Edwards and how to connect and access live JD Edwards data from the Cloud Data Fusion platform.
Configure JD Edwards Connectivity for Cloud Data Fusion
Connectivity to JD Edwards from Cloud Data Fusion is made possible through CData Connect AI. To work with JD Edwards data from Cloud Data Fusion, we start by creating and configuring a JD Edwards connection.
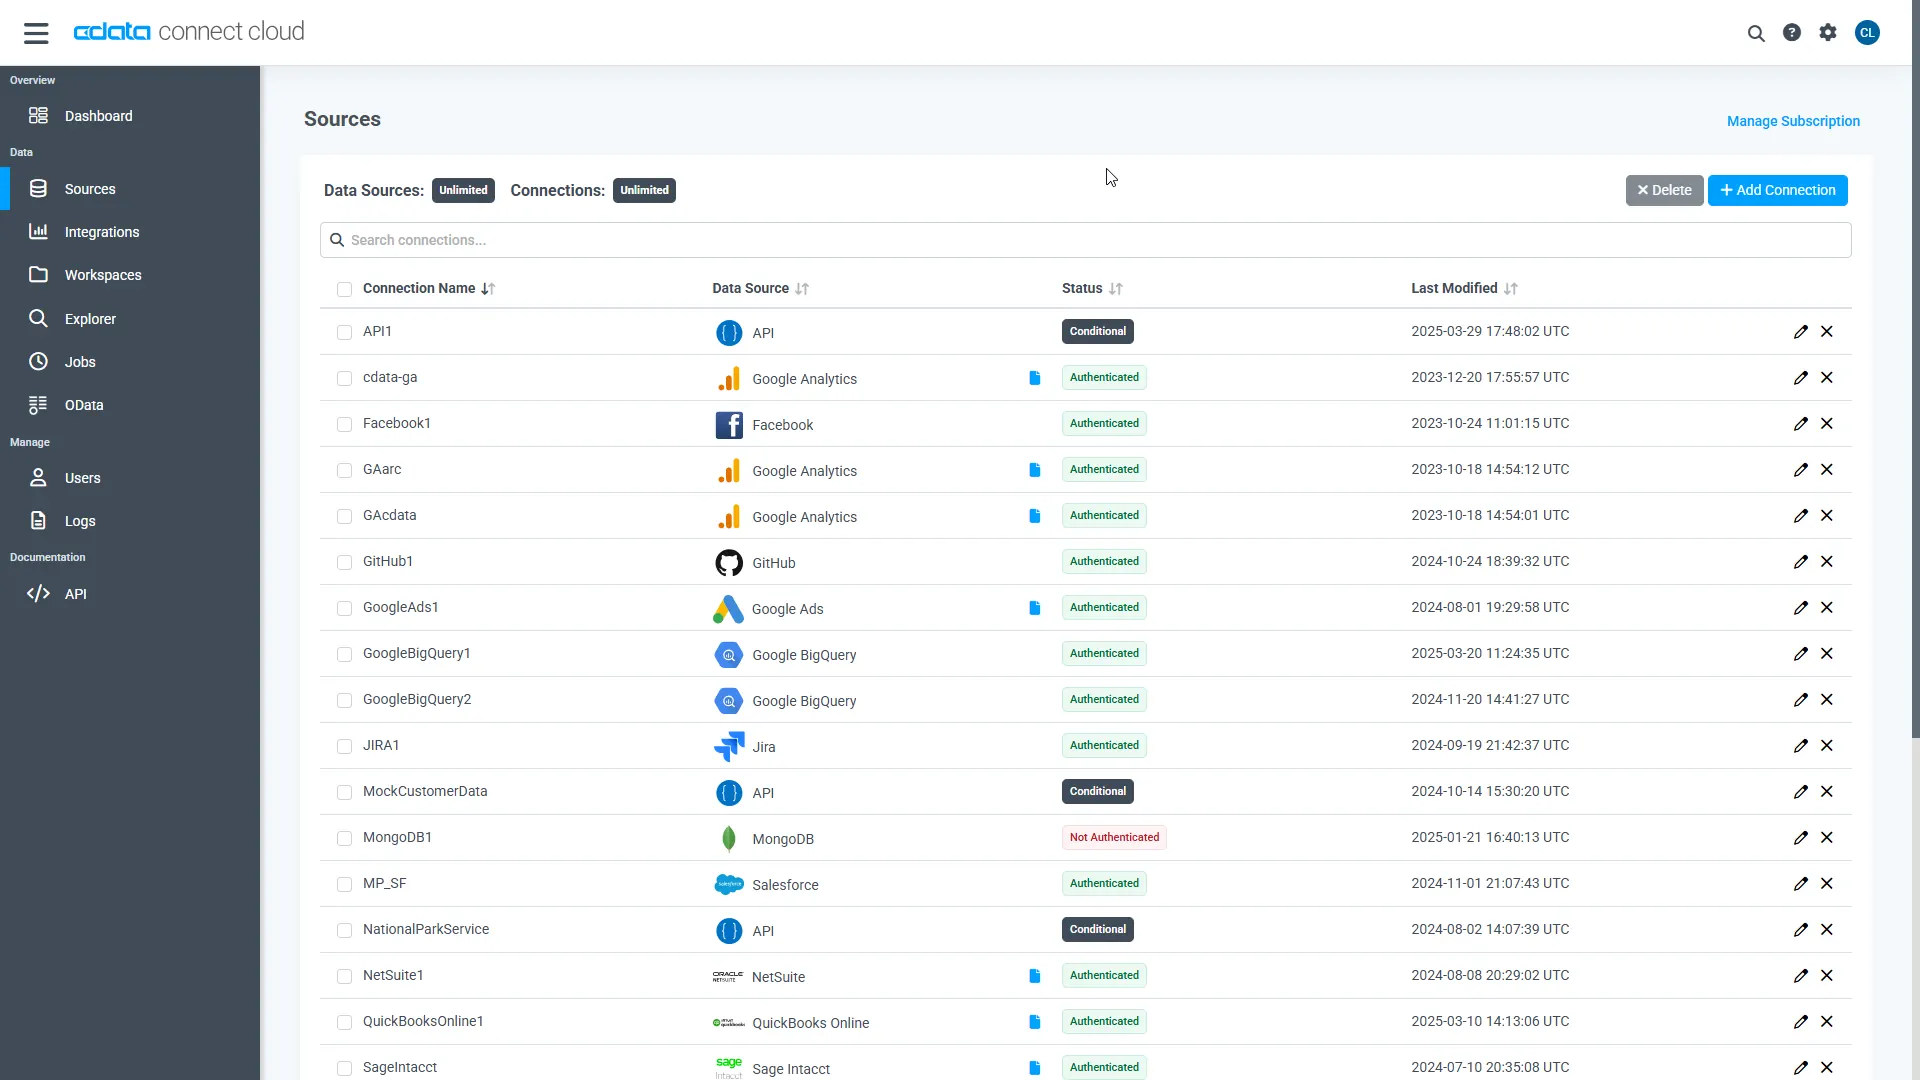
- Log into Connect AI, click Sources, and then click Add Connection
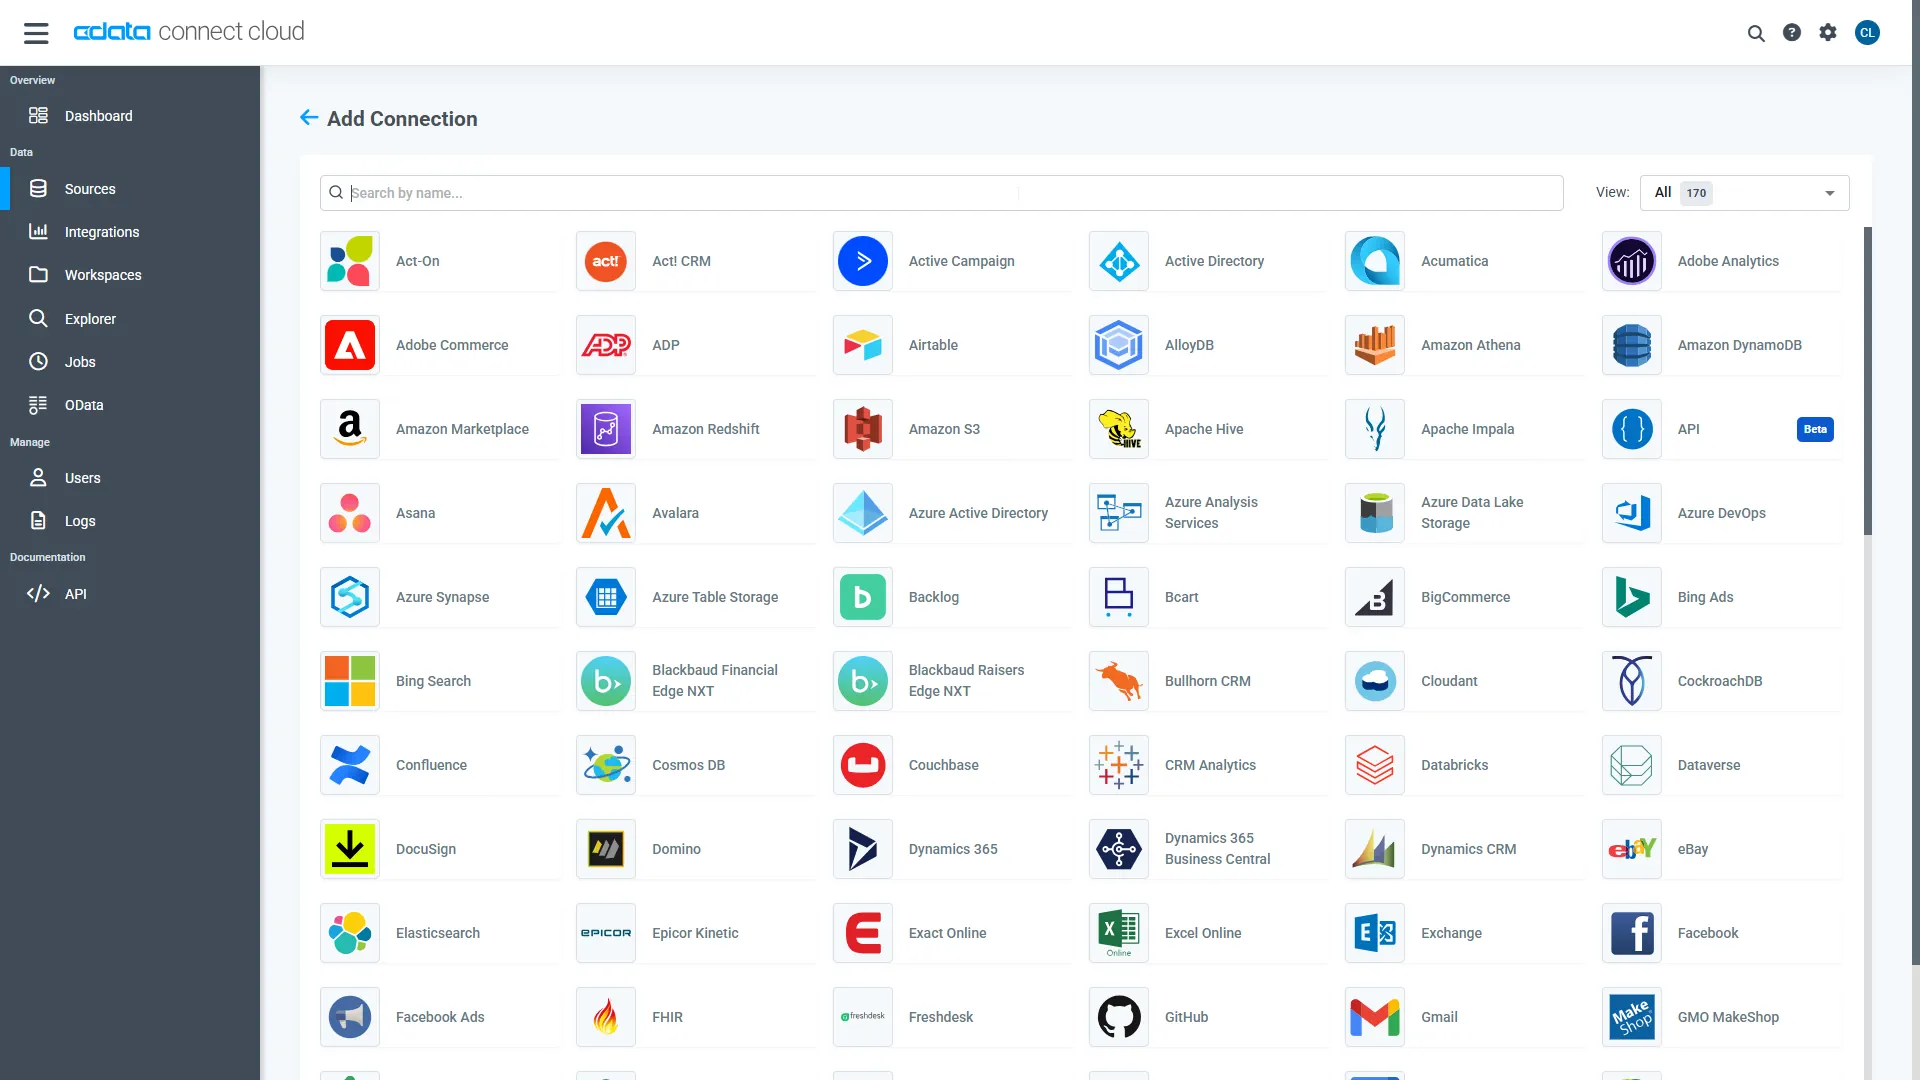
- Select "JD Edwards" from the Add Connection panel
-
Enter the necessary authentication properties to connect to JD Edwards.
The driver connects to JD Edwards through your Application Interface Services (AIS) Server. Set the following connection properties:
- URL: The base HTTPS URL of your AIS Server (e.g., https://jde-ais.example.com:8300).
- User: Your JD Edwards username.
- Password: Your JD Edwards password.
- Environment (optional): The JD Edwards environment to use (e.g., PD920 for production or DV920 for development). If not specified, the AIS Server's default environment is used.
- Role (optional): The JD Edwards role for the session. If not specified, the AIS Server's default role is used.
- DeviceName (optional): An identifier for the connecting device or application, used for auditing and logging on the AIS Server.
- Jasserver (optional): The specific Java Application Server (JAS) instance to route requests through, useful in clustered environments.
Choosing Which Data Is Exposed
JD Edwards organizes tables and business views by System Code, and the driver exposes each System Code as its own schema. Use these properties to control which schemas are available:
- DataModel: One or more ERP modules (comma-separated) whose System Codes are exposed as schemas, or All to expose every System Code in the connected instance. Defaults to FinancialManagement.
- SystemCodes: A comma-separated list of additional System Codes to expose alongside those from DataModel (e.g., 42,43).
When you connect, the driver sends your credentials to the AIS Server to obtain a session token and caches it. The driver requests a new token automatically before the session expires.
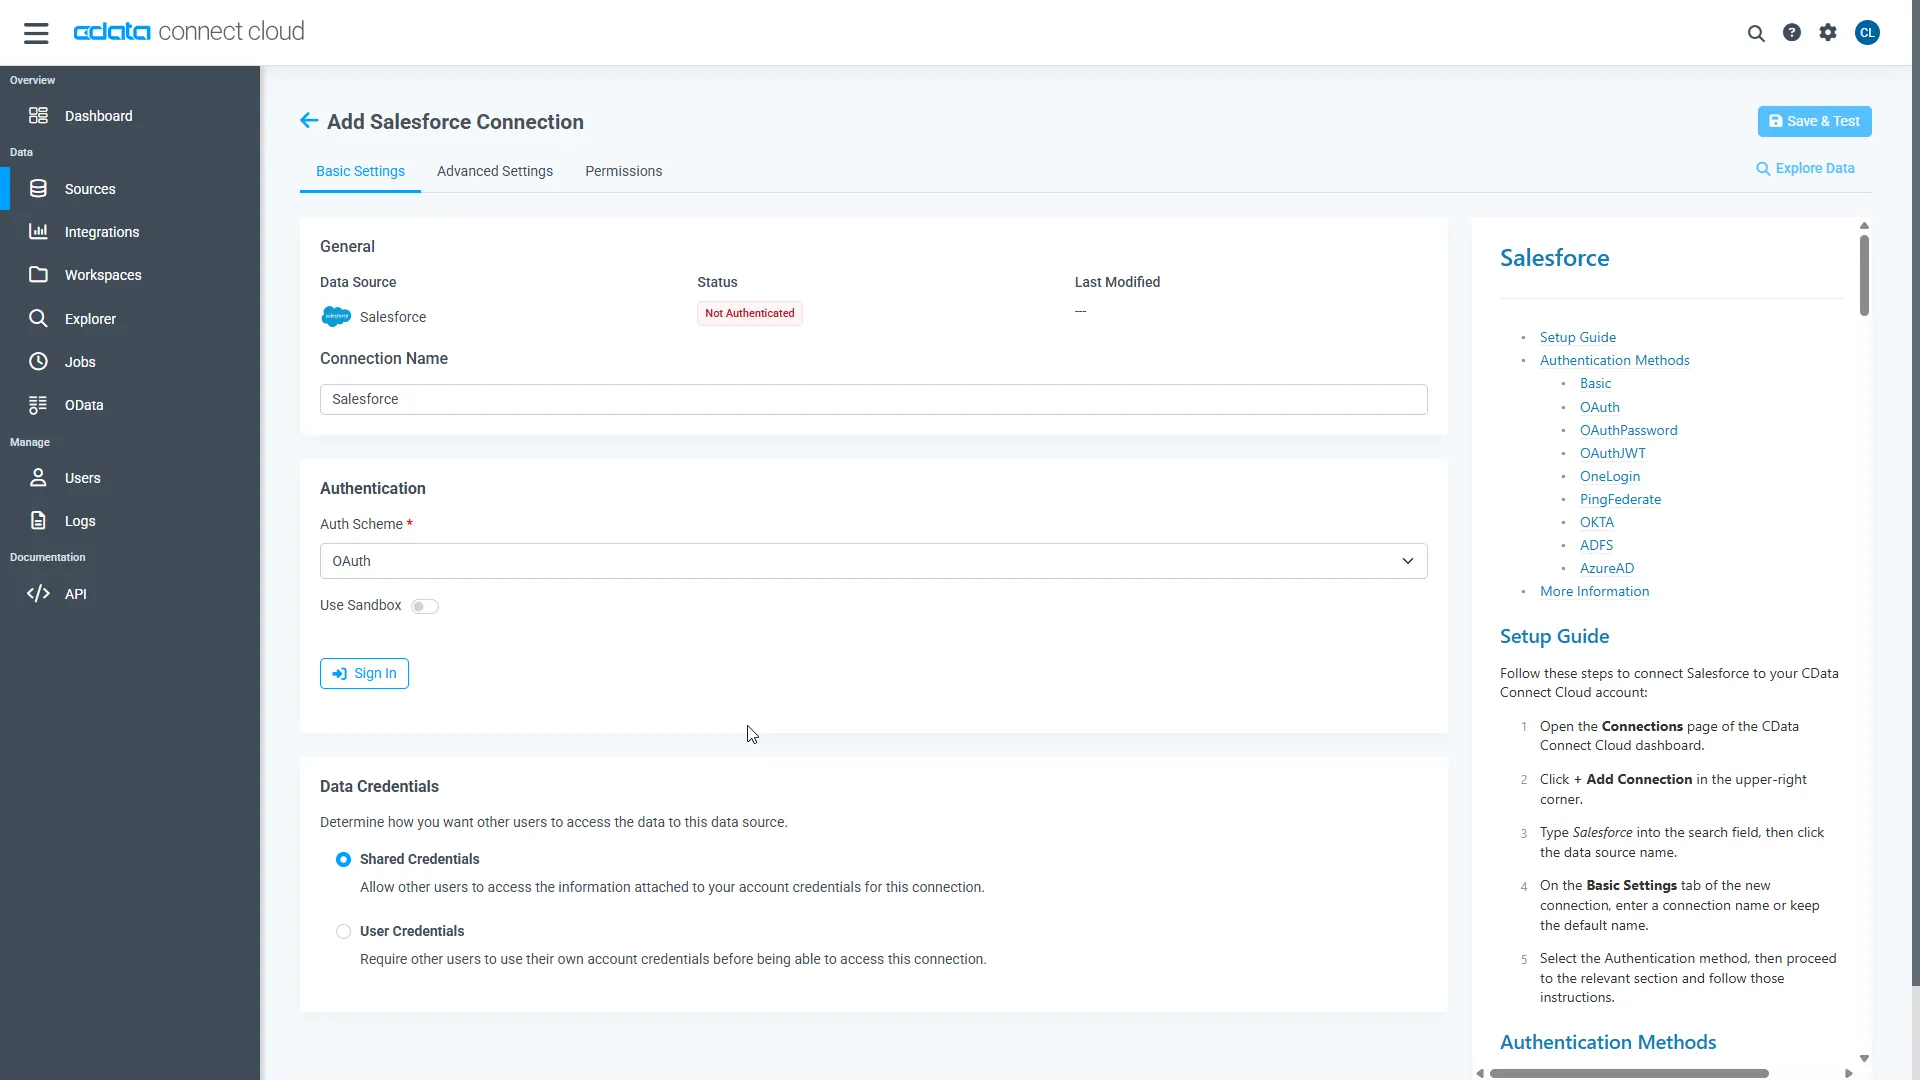
- Click Save & Test
-
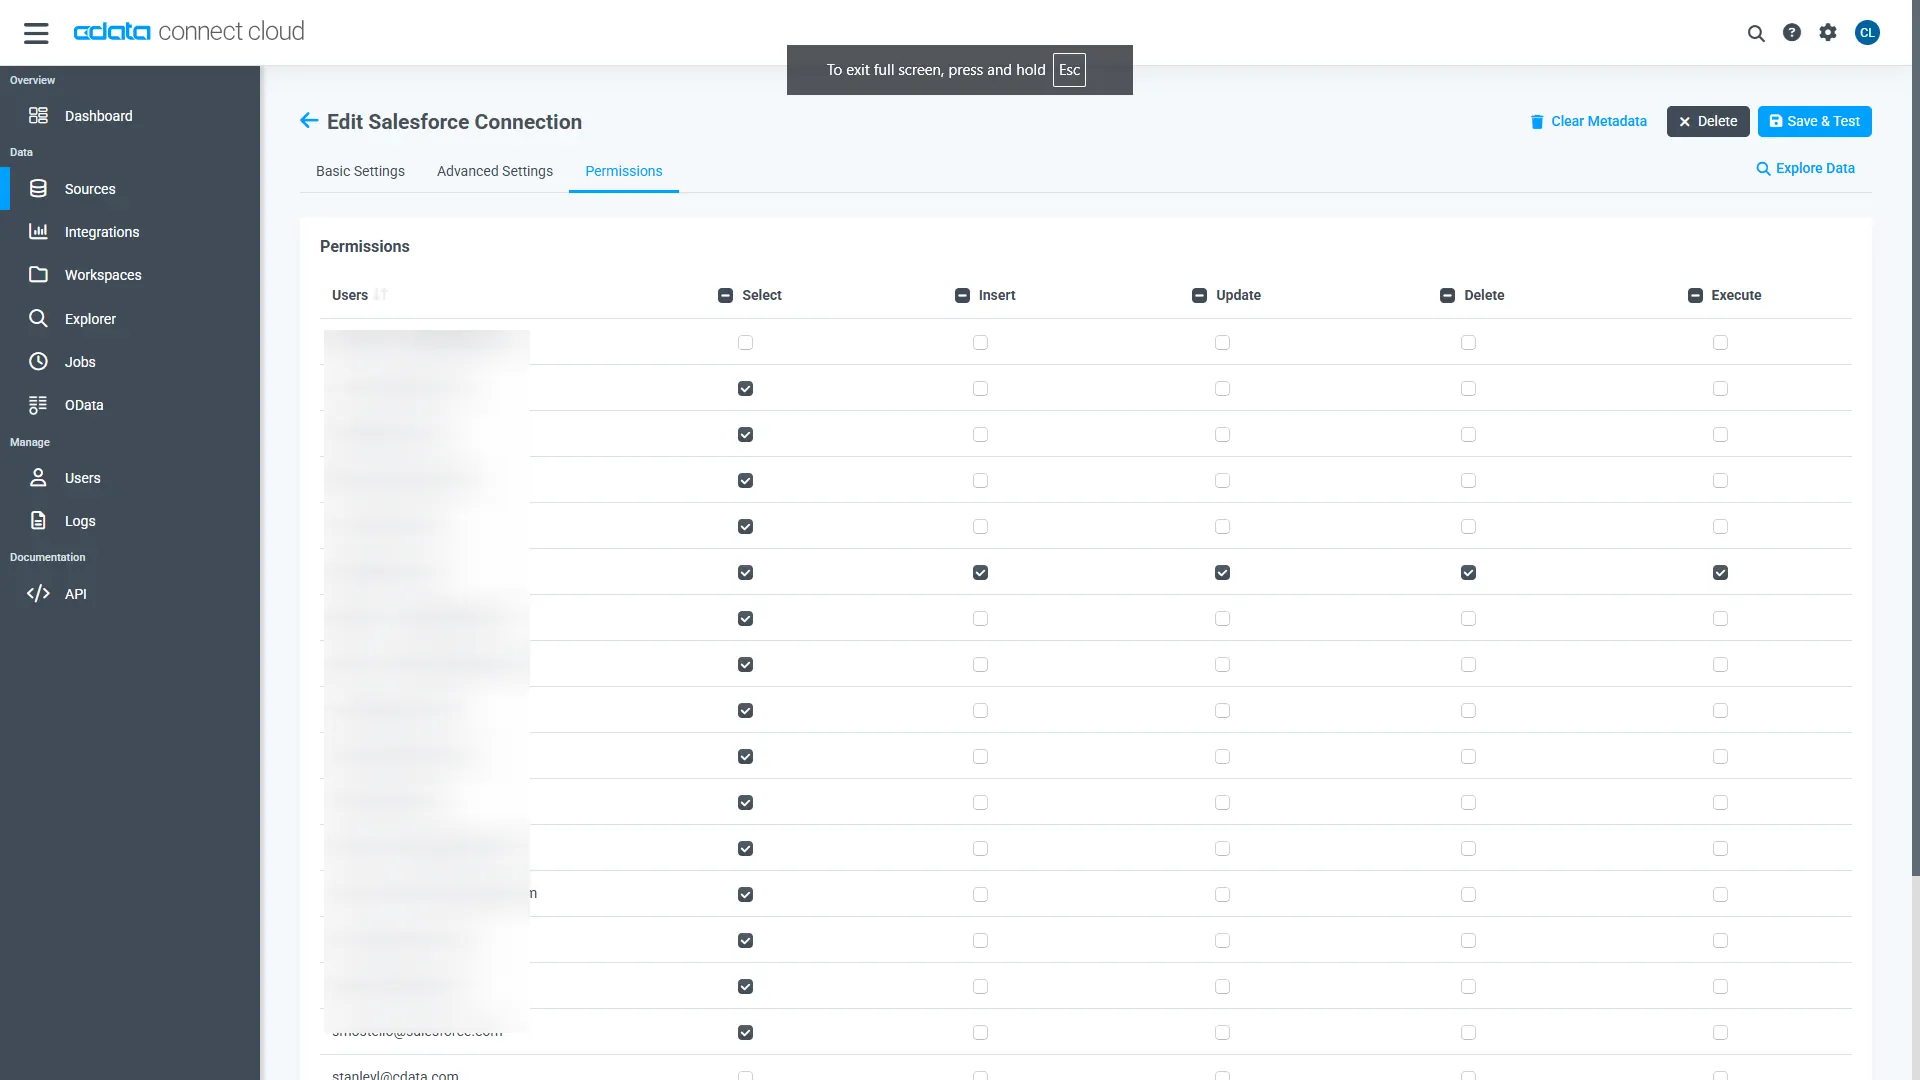
Navigate to the Permissions tab in the Add JD Edwards Connection page and update the User-based permissions.
Add a Personal Access Token
When connecting to Connect AI through the REST API, the OData API, or the Virtual SQL Server, a Personal Access Token (PAT) is used to authenticate the connection to Connect AI. It is best practice to create a separate PAT for each service to maintain granularity of access.
- Click on the Gear icon () at the top right of the Connect AI app to open the settings page.
- On the Settings page, go to the Access Tokens section and click Create PAT.
-
Give the PAT a name and click Create.
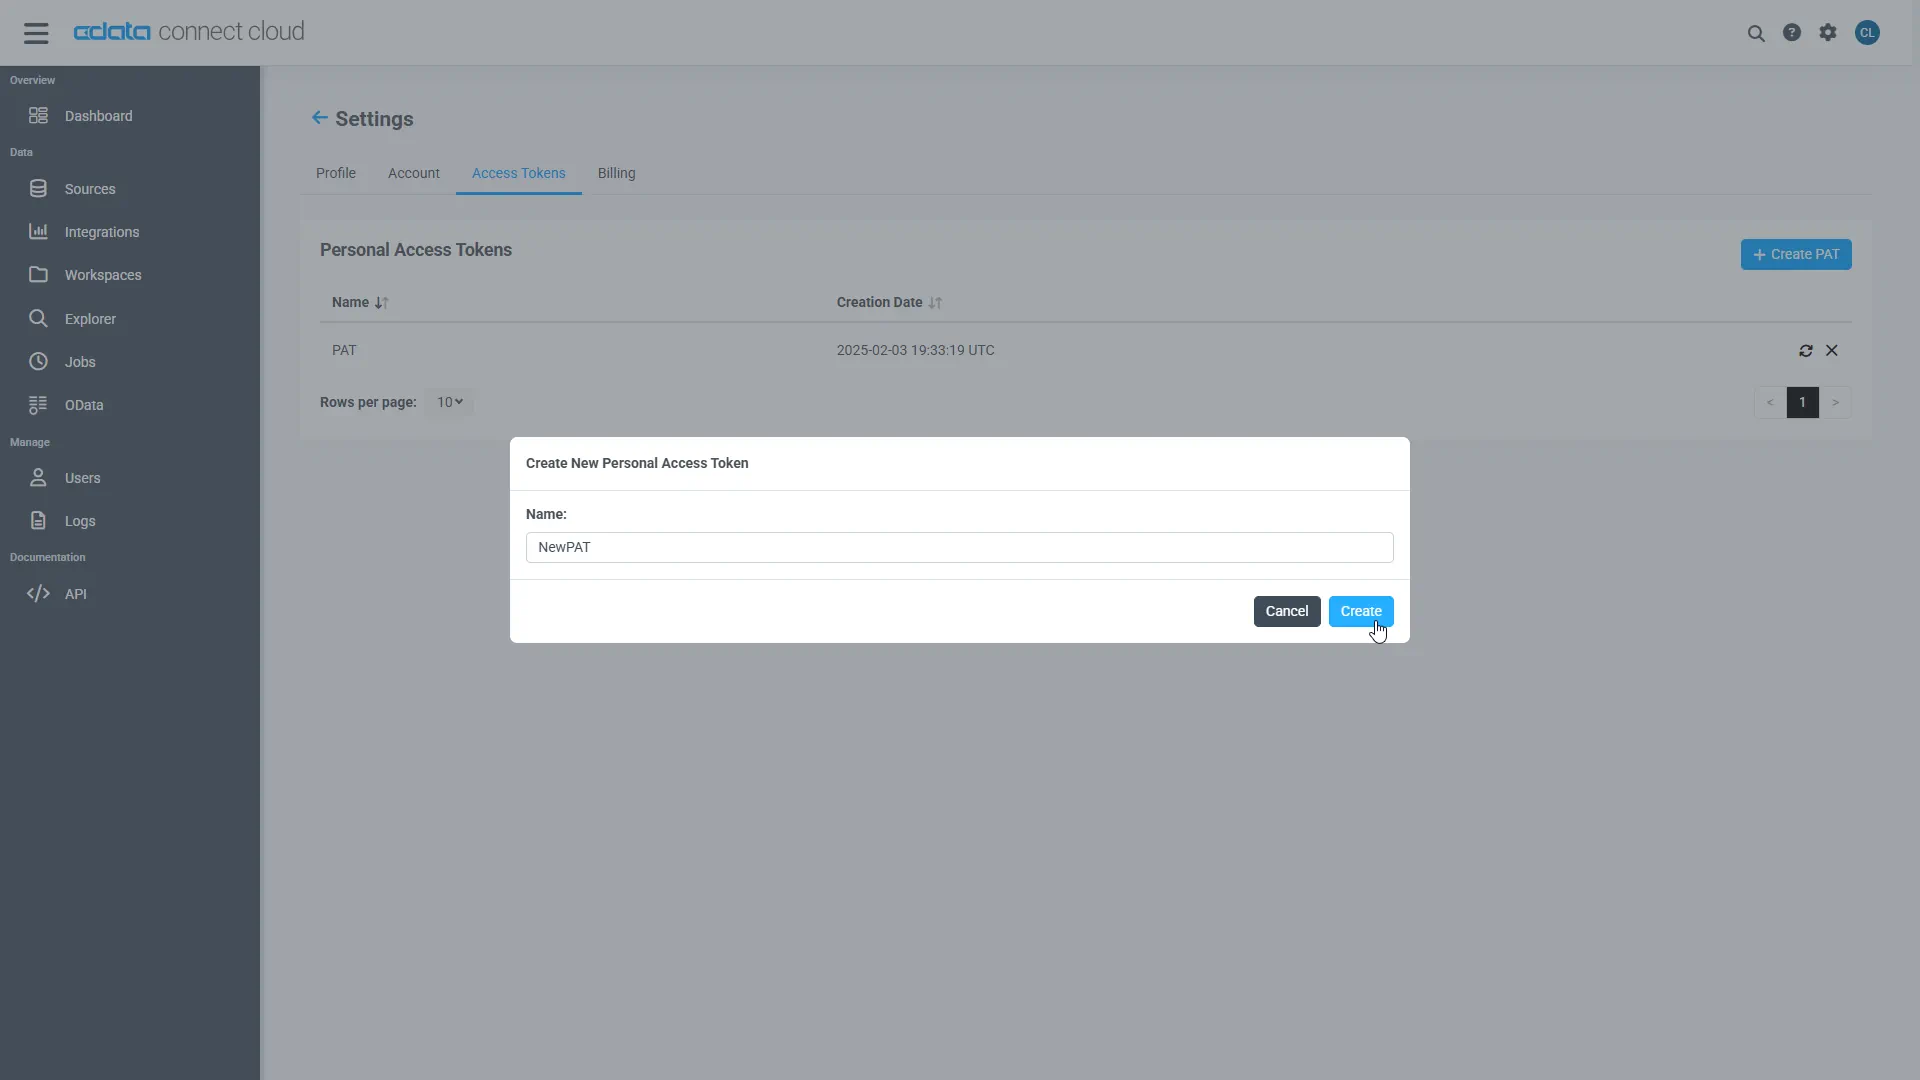
- The personal access token is only visible at creation, so be sure to copy it and store it securely for future use.
With the connection configured and a PAT generated, you are ready to connect to JD Edwards data from Cloud Data Fusion.
Connecting to JD Edwards from Cloud Data Fusion
Follow these steps to establish a connection from Cloud Data Fusion to JD Edwards through the CData Connect AI JDBC driver:
- Download and install the CData Connect AI JDBC driver:
- Open the Integrations page of CData Connect AI.
- Search for and select JDBC.
- Download and run the setup file.
- When the installation is complete, copy the JAR file(cdata.jdbc.connect.jar) from the installation directory (e.g., C:\Program Files\CData\JDBC Driver for CData Connect\lib).
- Log into Cloud Data Fusion.
- Click the green "+" button at the top right to add an entity.
- Under Driver, click Upload.
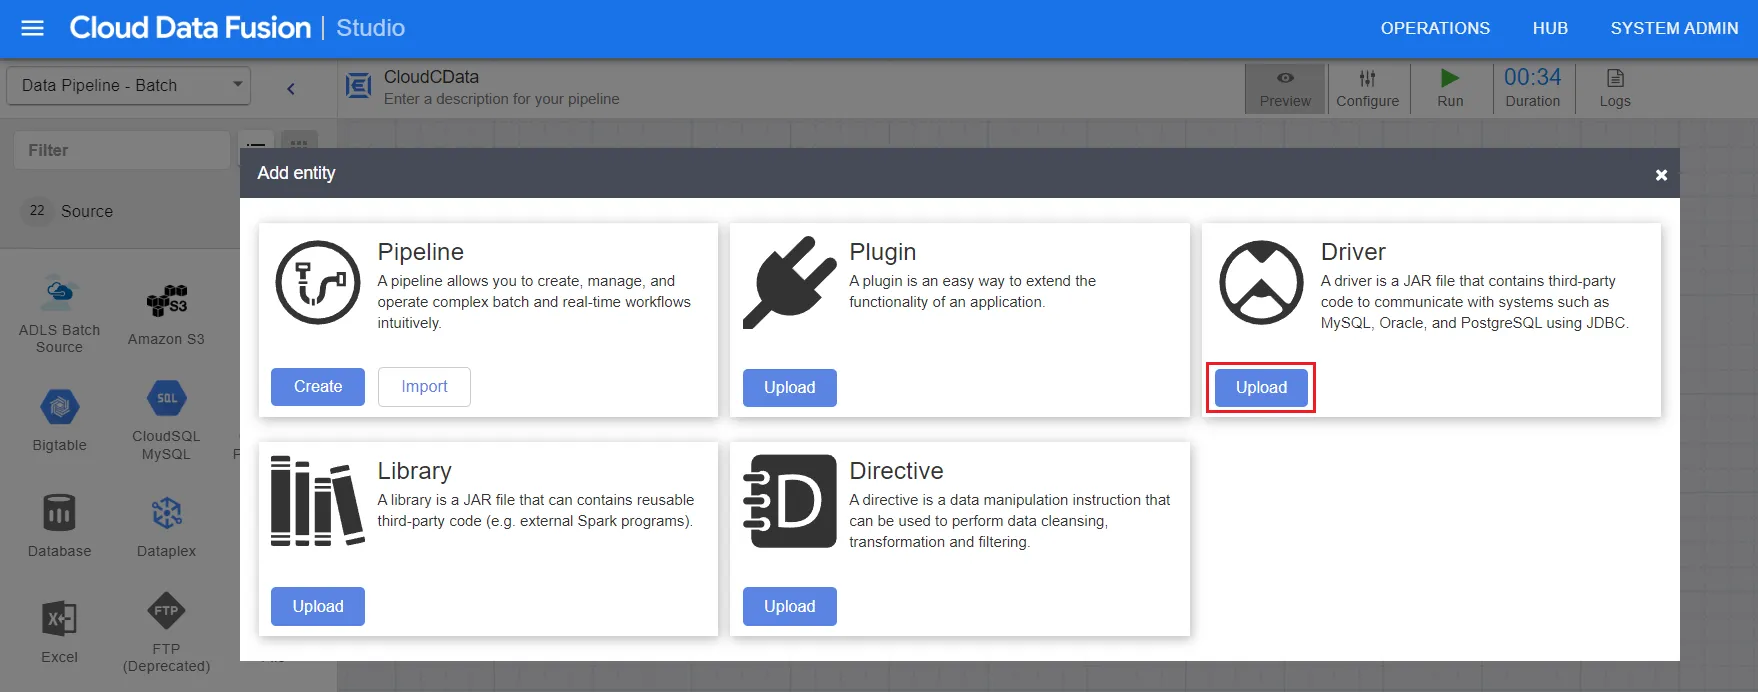
- Now, upload the CData Connect AI JDBC driver (JAR file).
- Enter the driver settings:
- Name: Enter the name of the driver
- Class name: Enter "cdata.jdbc.connect.ConnectDriver"
- Version: Enter the driver version
- Description (optional): Enter a description for the driver
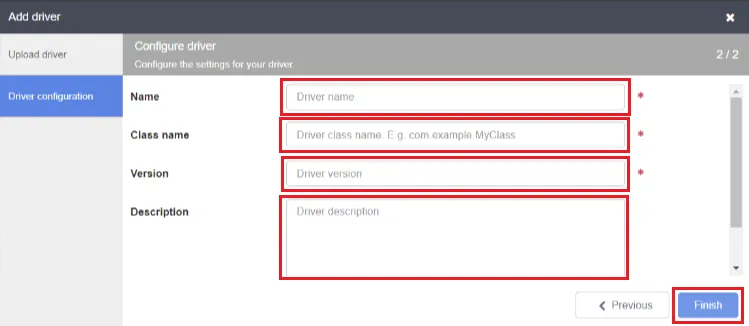
- Click on Finish.
- Enter source configuration settings:
- Label: Helps to identify the connection
- JDBC driver name: Enter the JDBC driver name to identify the driver configured in Step 6.
- Connection string: Enter the JDBC connection string, for example:
jdbc:connect:AuthScheme=Basic;user=username;password=PAT; - User: Enter your CData Connect AI username, displayed in the top-right corner of the CData Connect AI interface. For example, "[email protected]"
- Password: Enter the PAT you generated on the Settings page.
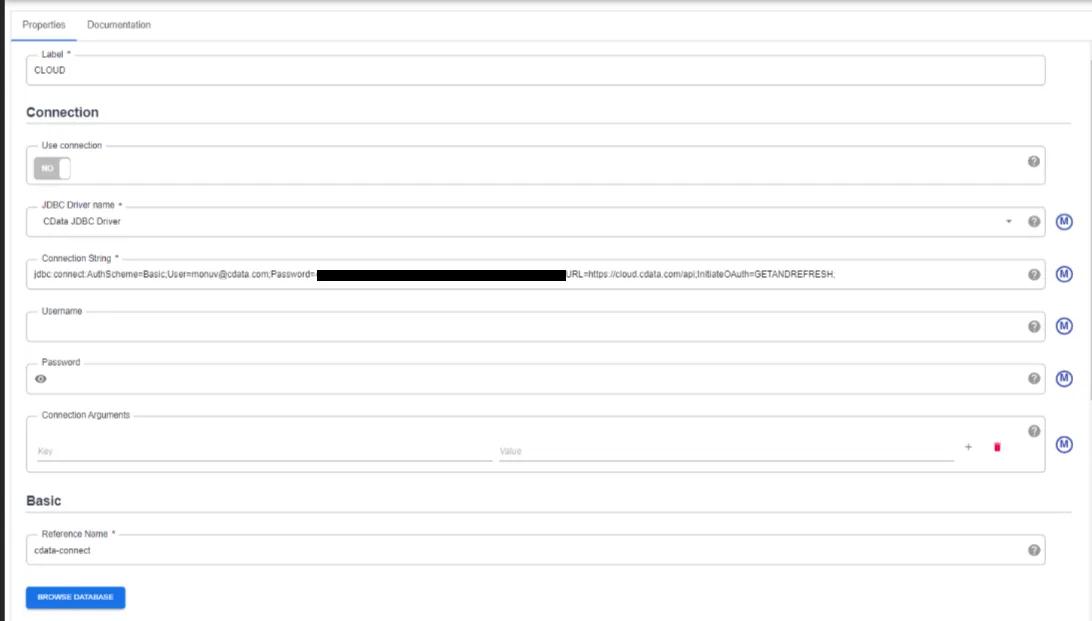
- Click Validate in the top right corner.
- If the connection is successful, you can manage the pipeline by editing it through the UI.
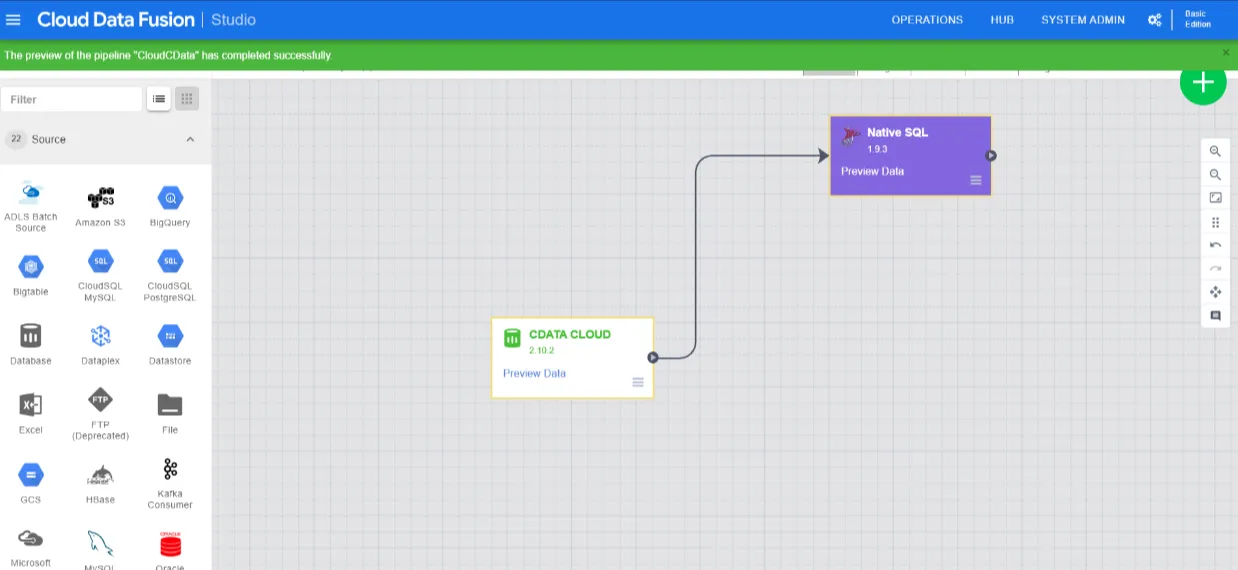
- Run the pipepline created.
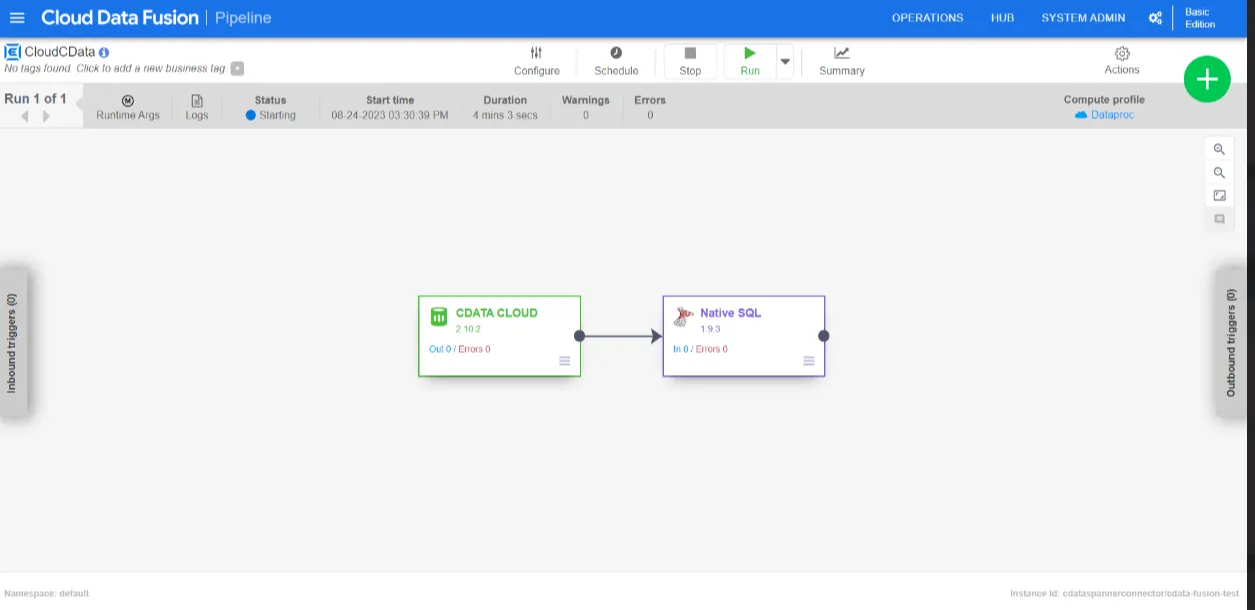
Troubleshooting
Please be aware that there is a known issue in Cloud Data Fusion where "int" types from source data are automatically cast as "long".
Live Access to JD Edwards Data from Cloud Applications
Now you have a direct connection to live JD Edwards data from from Google Cloud Data Fusion. You can create more connections to ensure a smooth movement of data across various sources and destinations, thereby streamlining data integration processes - all without replicating JD Edwards data.
To get real-time data access to hundreds of SaaS, Big Data, and NoSQL sources (including JD Edwards) directly from your cloud applications, explore the CData Connect AI.