




How to Visualize JD Edwards Data in Python with pandas via CData Connect AI
The rich ecosystem of Python modules lets you get to work quickly and integrate your systems more effectively. With the CData Connect AI Python SDK, the pandas and Matplotlib modules, you can build JD Edwards-connected Python applications and scripts for visualizing JD Edwards data. This article shows how to connect to Connect AI and use the pandas and Matplotlib built-in functions to query JD Edwards data and visualize the results.
The Connect AI Python SDK (cdata-connect-ai) is a DB-API 2.0 (PEP 249) compliant client, so pandas can read query results directly from the SDK connection object. There is no driver to install per source and no SQLAlchemy engine to configure: connect with a Personal Access Token and pass the connection straight to pandas.read_sql.
Connect to JD Edwards in Connect AI
CData Connect AI uses a straightforward, point-and-click interface to connect to data sources.
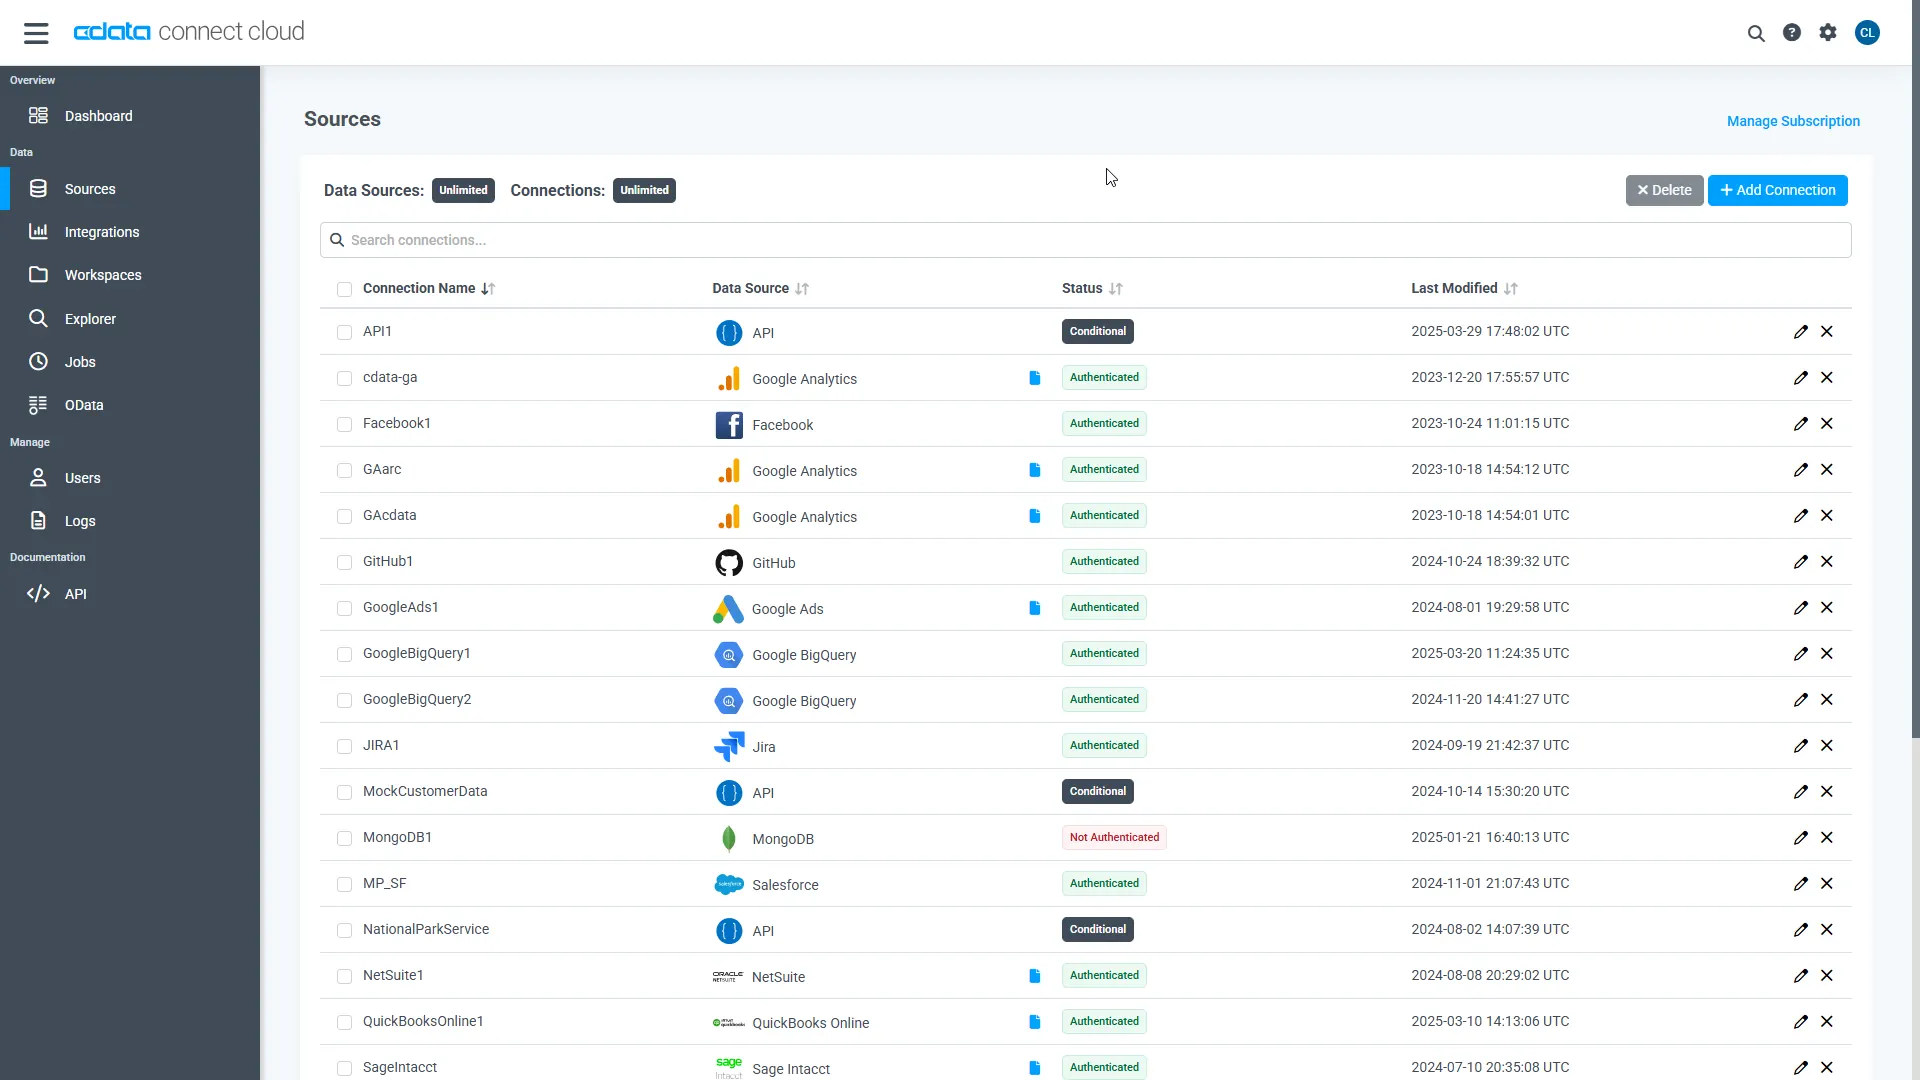
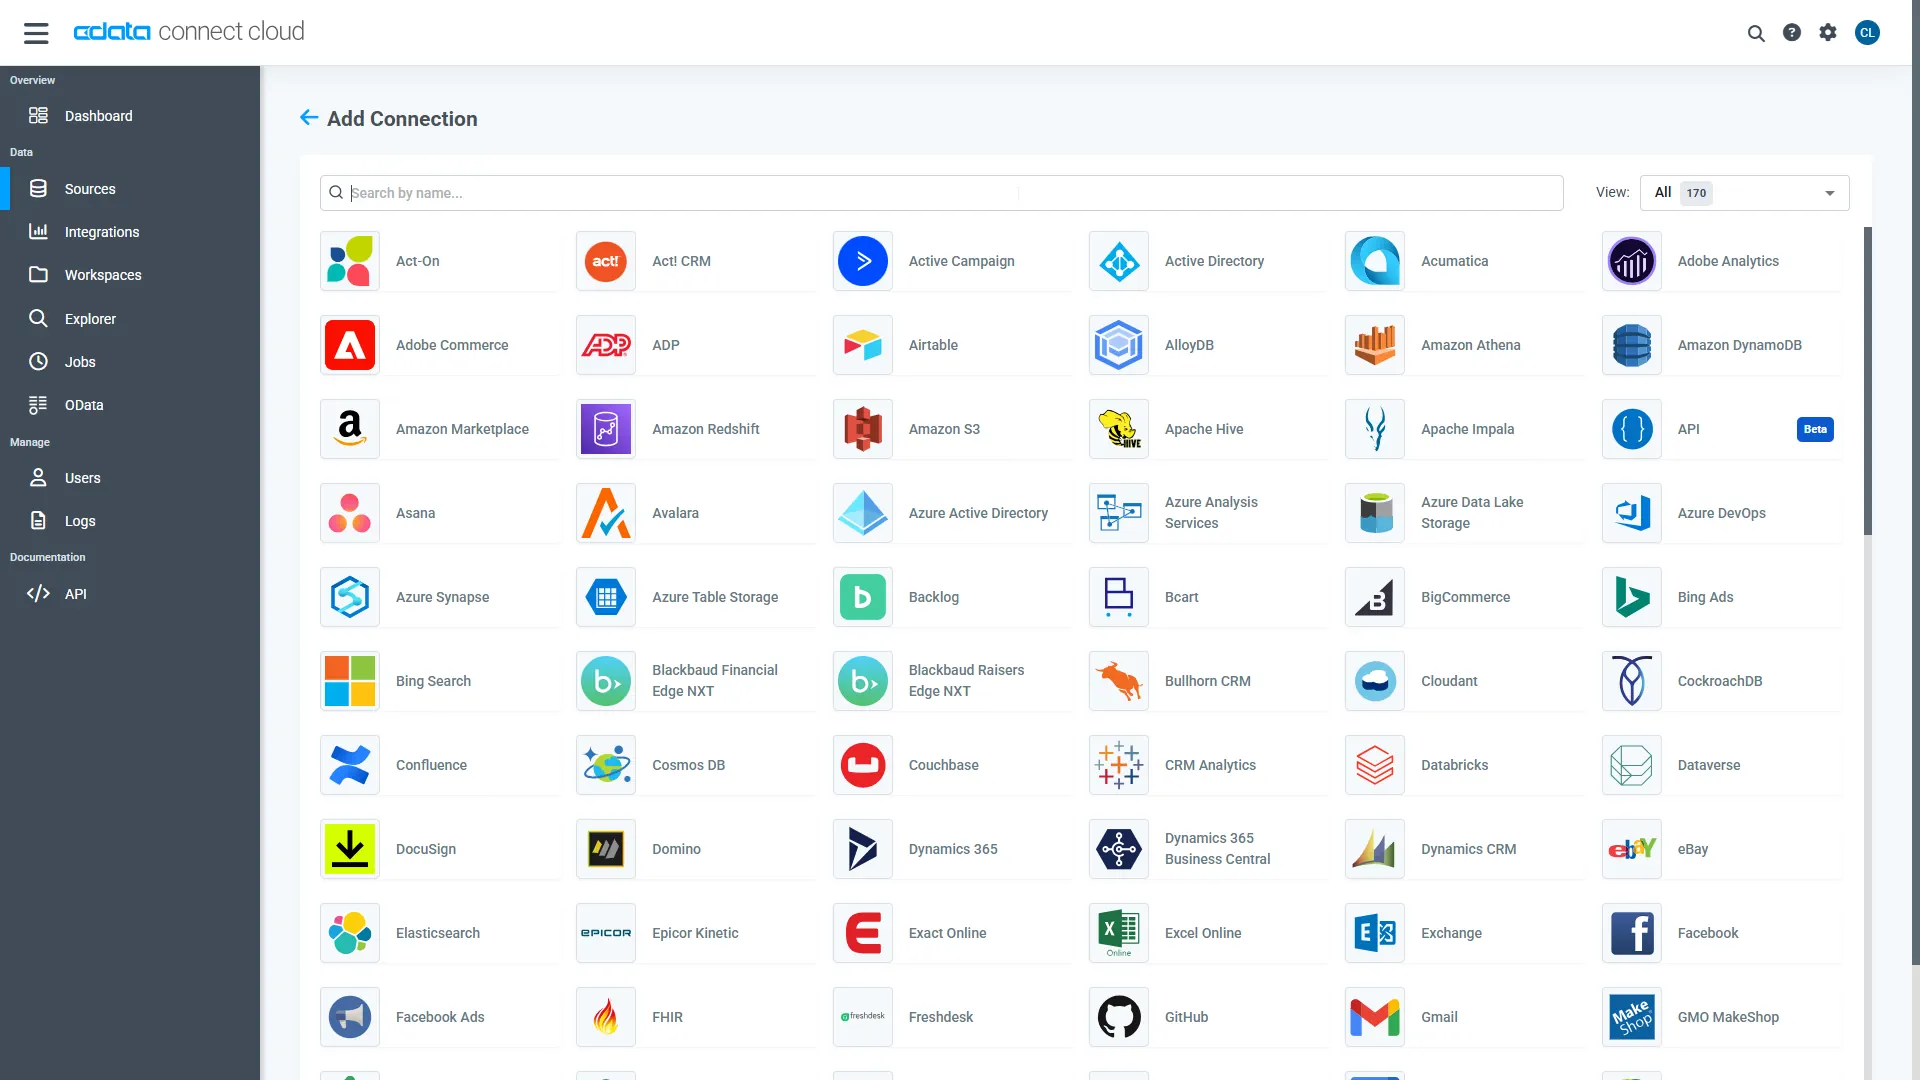
- Log into Connect AI, click Sources, and then click Add Connection
- Select "JD Edwards" from the Add Connection panel
-
Enter the necessary authentication properties to connect to JD Edwards.
The driver connects to JD Edwards through your Application Interface Services (AIS) Server. Set the following connection properties:
- URL: The base HTTPS URL of your AIS Server (e.g., https://jde-ais.example.com:8300).
- User: Your JD Edwards username.
- Password: Your JD Edwards password.
- Environment (optional): The JD Edwards environment to use (e.g., PD920 for production or DV920 for development). If not specified, the AIS Server's default environment is used.
- Role (optional): The JD Edwards role for the session. If not specified, the AIS Server's default role is used.
- DeviceName (optional): An identifier for the connecting device or application, used for auditing and logging on the AIS Server.
- Jasserver (optional): The specific Java Application Server (JAS) instance to route requests through, useful in clustered environments.
Choosing Which Data Is Exposed
JD Edwards organizes tables and business views by System Code, and the driver exposes each System Code as its own schema. Use these properties to control which schemas are available:
- DataModel: One or more ERP modules (comma-separated) whose System Codes are exposed as schemas, or All to expose every System Code in the connected instance. Defaults to FinancialManagement.
- SystemCodes: A comma-separated list of additional System Codes to expose alongside those from DataModel (e.g., 42,43).
When you connect, the driver sends your credentials to the AIS Server to obtain a session token and caches it. The driver requests a new token automatically before the session expires.
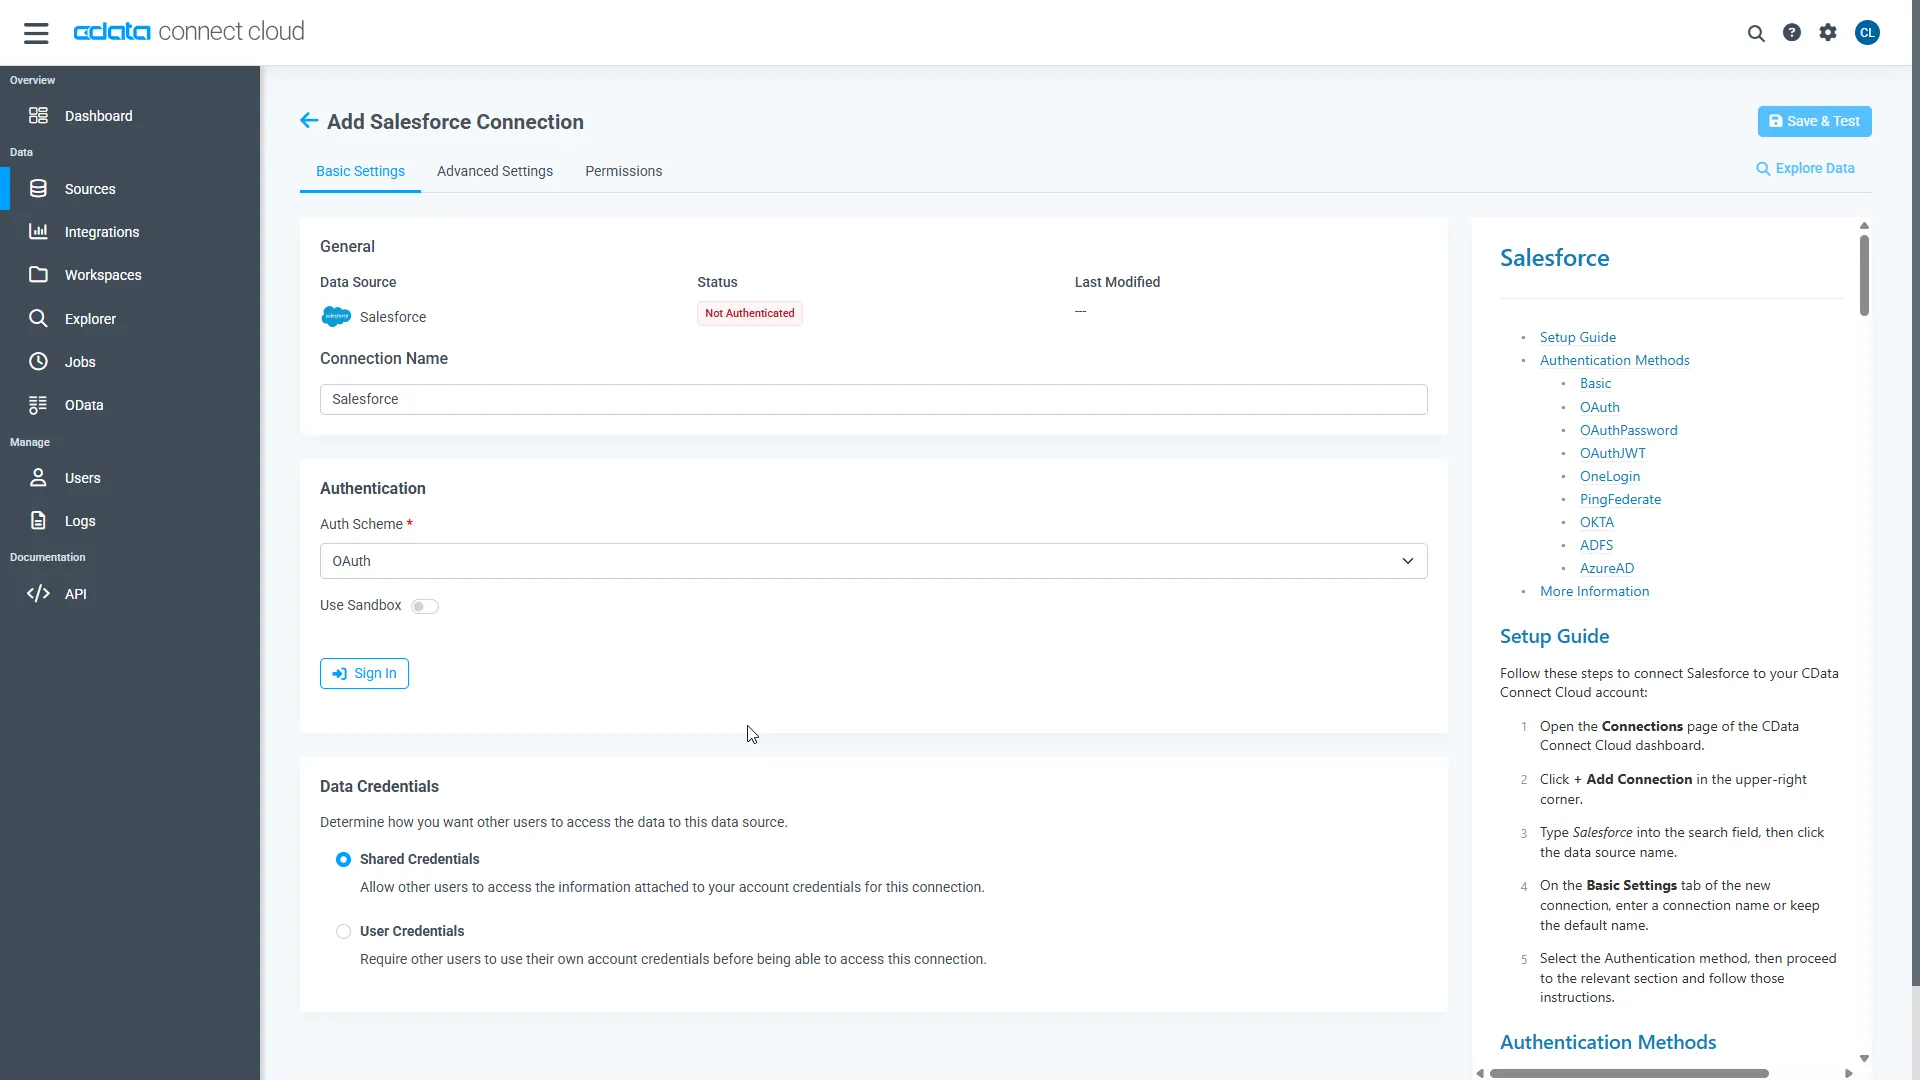
- Click Save & Test
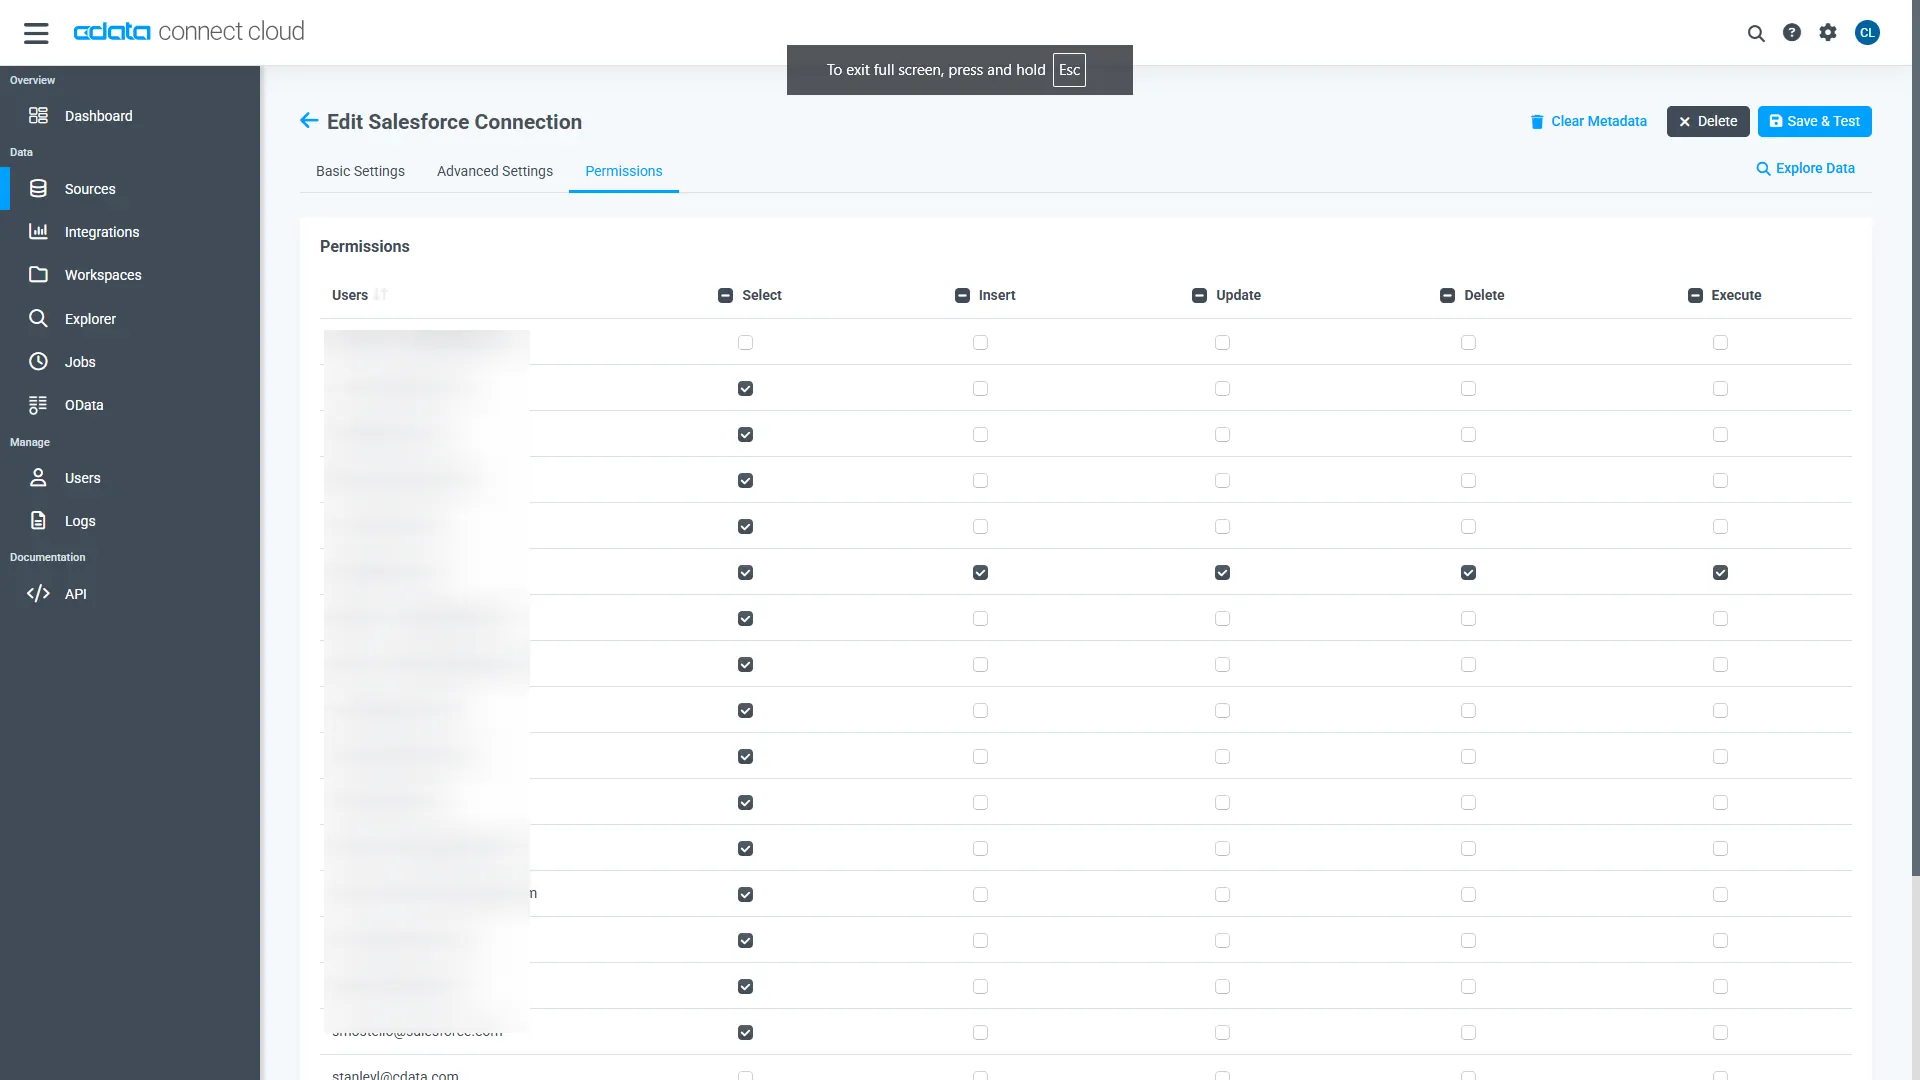
- Navigate to the Permissions tab and update the user-based permissions.
Generate a Personal Access Token (PAT)
The Python SDK authenticates to Connect AI with your account email and a Personal Access Token (PAT). It is best practice to create a separate PAT for each application to maintain granularity of access.
- Click the Gear icon () at the top right of the Connect AI app to open the Settings page.
- On the Settings page, go to the Access Tokens section and click Create PAT.
- Give the PAT a name and click Create.
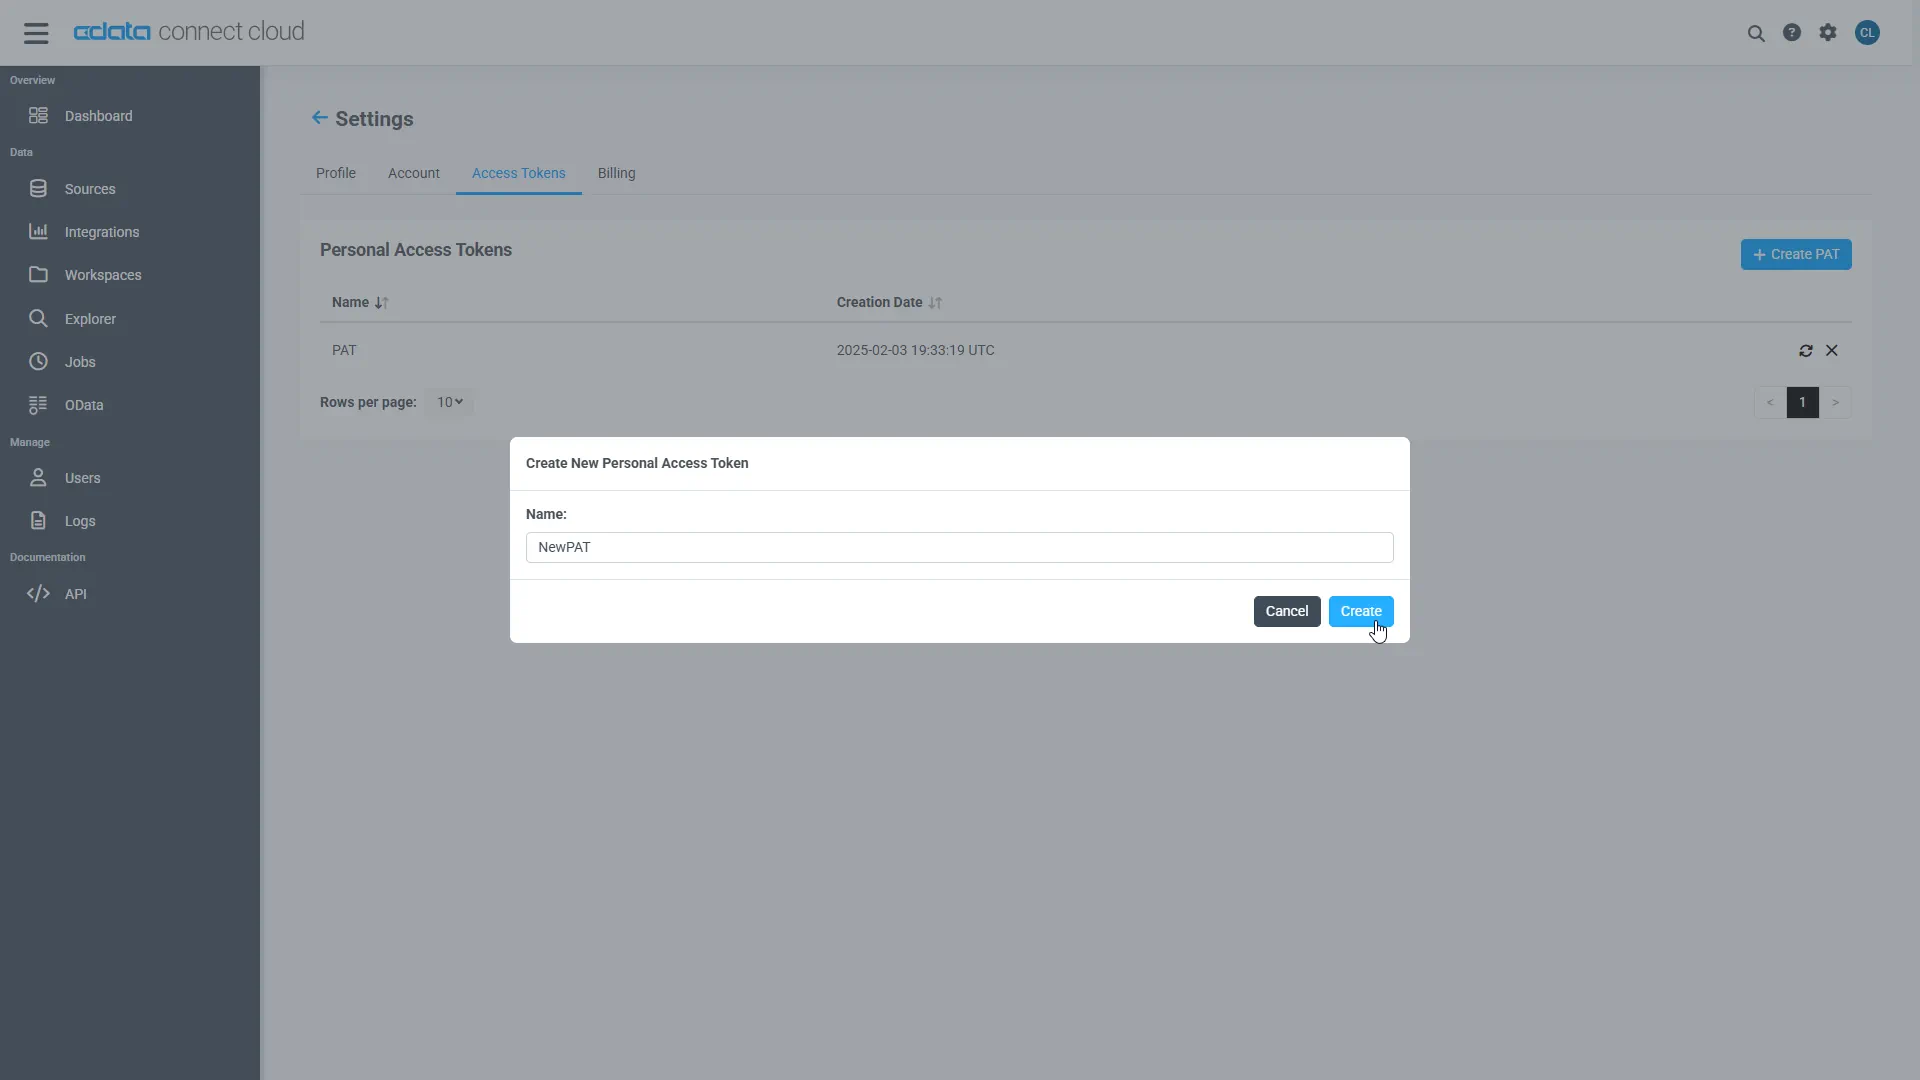
- The PAT is only visible at creation, so copy it and store it securely.
Install Required Modules
Install the SDK (with the pandas extra) and Matplotlib using the pip utility:
pip install "cdata-connect-ai[full]"
pip install matplotlib
Visualize JD Edwards Data in Python
Import the modules, then connect to Connect AI with your account email and PAT. Identifiers are three-part: <Connection>.<Schema>.<Table>, where the connection name defaults to the source name (for example, JDEdwards1).
import pandas
import matplotlib.pyplot as plt
import cdata_connect_ai

conn = cdata_connect_ai.connect(
    username="[email protected]",
    password="<your_pat>",
)
Query JD Edwards with pandas
Use the read_sql function from pandas to execute a SQL statement and store the result set in a DataFrame. Pass the SDK connection directly, no engine required.
df = pandas.read_sql(
    "SELECT DocumentNumber, Amount "
    "FROM [JDEdwards1].[JDEdwards].[AccountsPayable.AccountLedger] "
    "WHERE BusinessUnit = '100'",
    conn,
)
Note: pandas may print a UserWarning stating that it only officially supports SQLAlchemy connectables. This is expected when passing a DB-API connection directly—the query runs correctly and the warning is safe to ignore.
Visualize JD Edwards Data
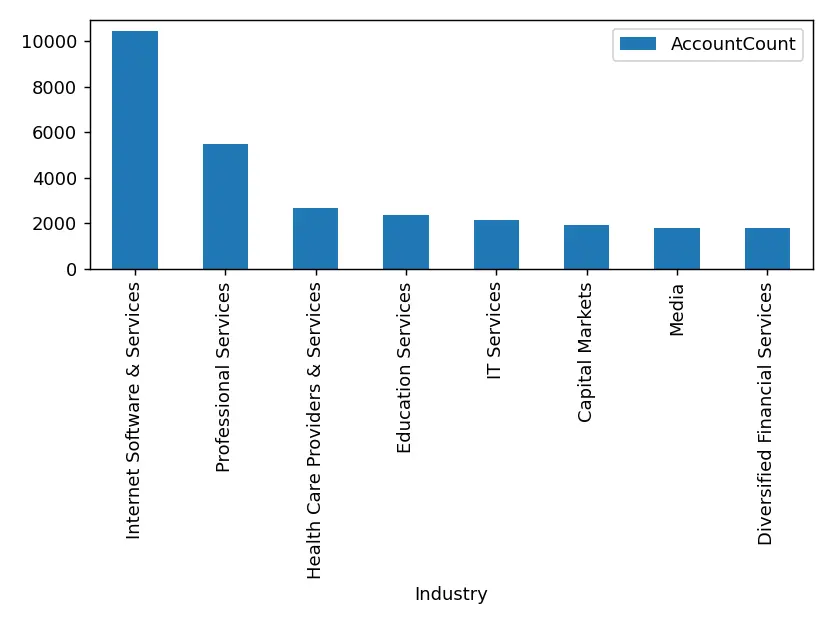
With the query results stored in a DataFrame, use the plot function to build a chart. The show method displays the chart in a new window.
df.plot(kind="bar", x="DocumentNumber", y="Amount")
plt.show()

conn.close()
More Information and Free Trial
Now you can read live JD Edwards data into pandas through the CData Connect AI Python SDK. For more information on connecting to JD Edwards (and hundreds of other data sources), visit the Connect AI page. Sign up for a free trial and start working with live JD Edwards data in Python.
Full Source Code
import pandas
import matplotlib.pyplot as plt
import cdata_connect_ai

conn = cdata_connect_ai.connect(
    username="[email protected]",
    password="<your_pat>",
)

df = pandas.read_sql(
    "SELECT DocumentNumber, Amount "
    "FROM [JDEdwards1].[JDEdwards].[AccountsPayable.AccountLedger] "
    "WHERE BusinessUnit = '100'",
    conn,
)

df.plot(kind="bar", x="DocumentNumber", y="Amount")
plt.show()

conn.close()