




How to Work with JD Edwards Data in ETL Validator JDBC
ETL Validator provides data movement and transformation capabilities for integrating data platforms across your organization. CData's JDBC driver seamlessly integrates with ETL Validator and extends its native connectivity to include JD Edwards data.
This tutorial explains how to build a simple ETL validator data flow to extract data from JD Edwards data and load it into an example data storage solution: SQL Server.
Add a new ETL Validator data source via CData
CData extends ETL Validator's data connectivity capabilities by providing the ability to add data sources that connect via CData's JDBC drivers. Connecting to JD Edwards data simply requires creating a new data source in ETL Validator through CData's connectiviy suite as described below.
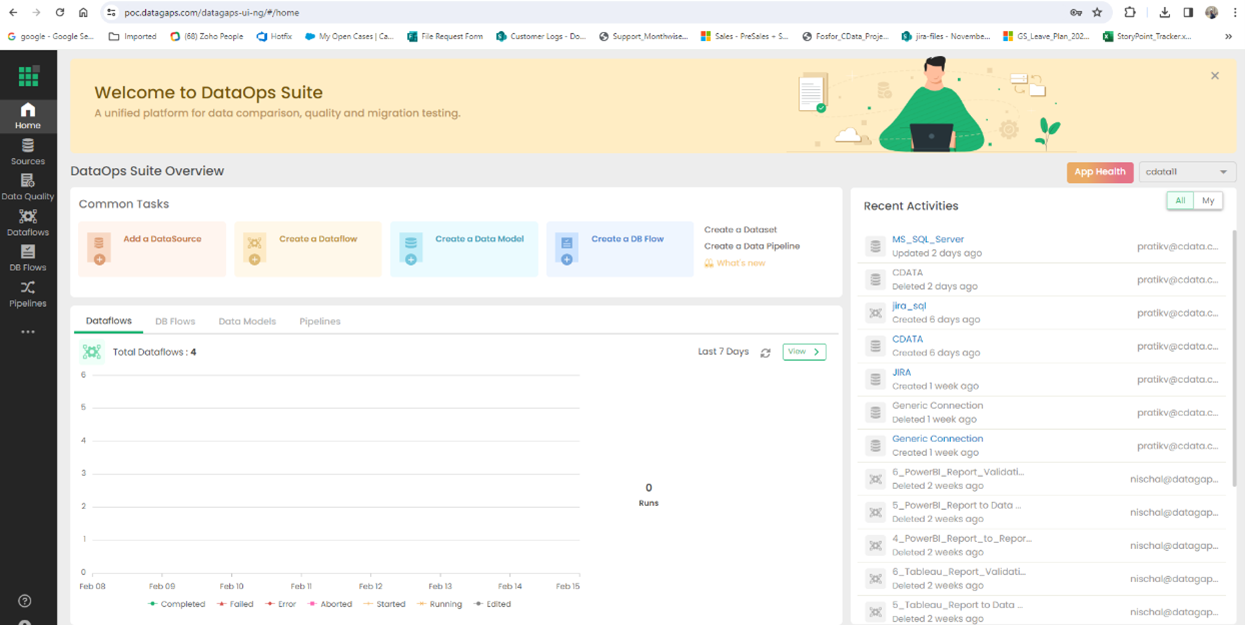
Login to ETL Validator
Begin by logging into ETL Validator to view the application dashboard.
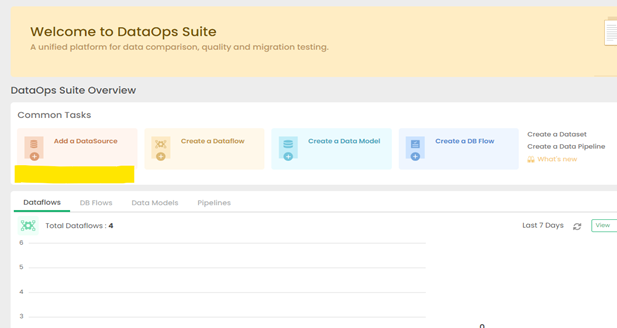
Click on Add a DataSource
CData extends the data source options within ETL Validator.
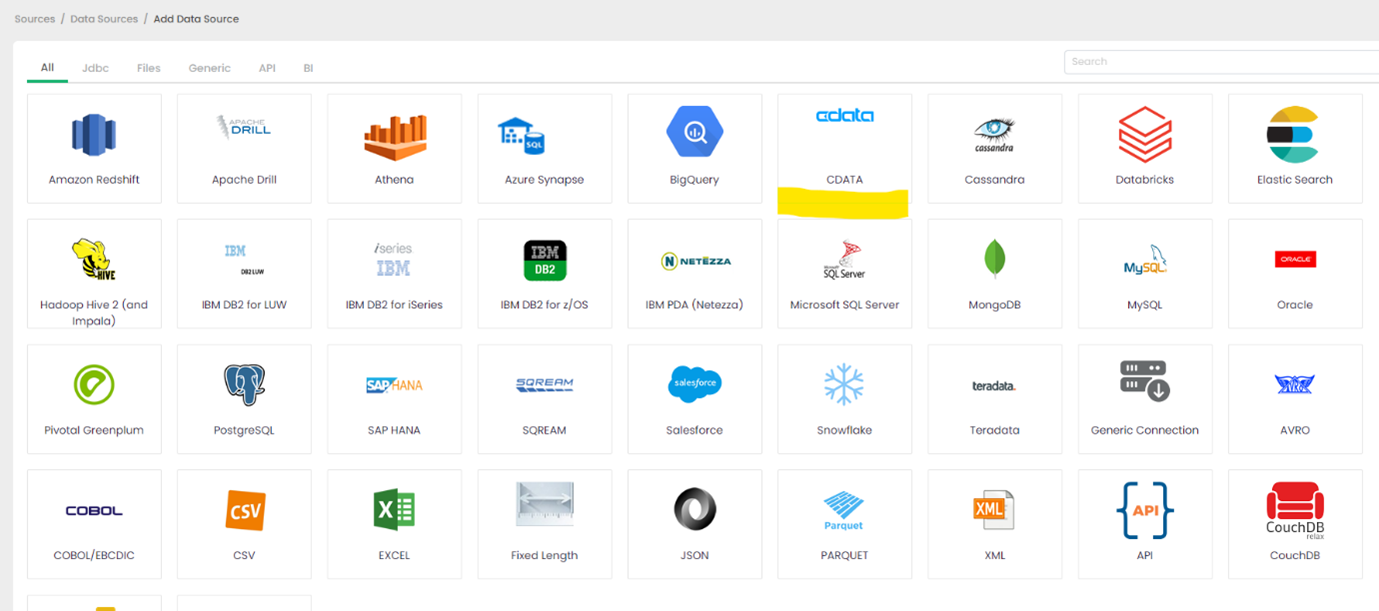
Click on CData
CData's connectivity is embedded within ETL Validator's data source options.
Configure the CData Driver Connection String
You will need a JDBC connection string to establish a connection to JD Edwards in ETL Validator.
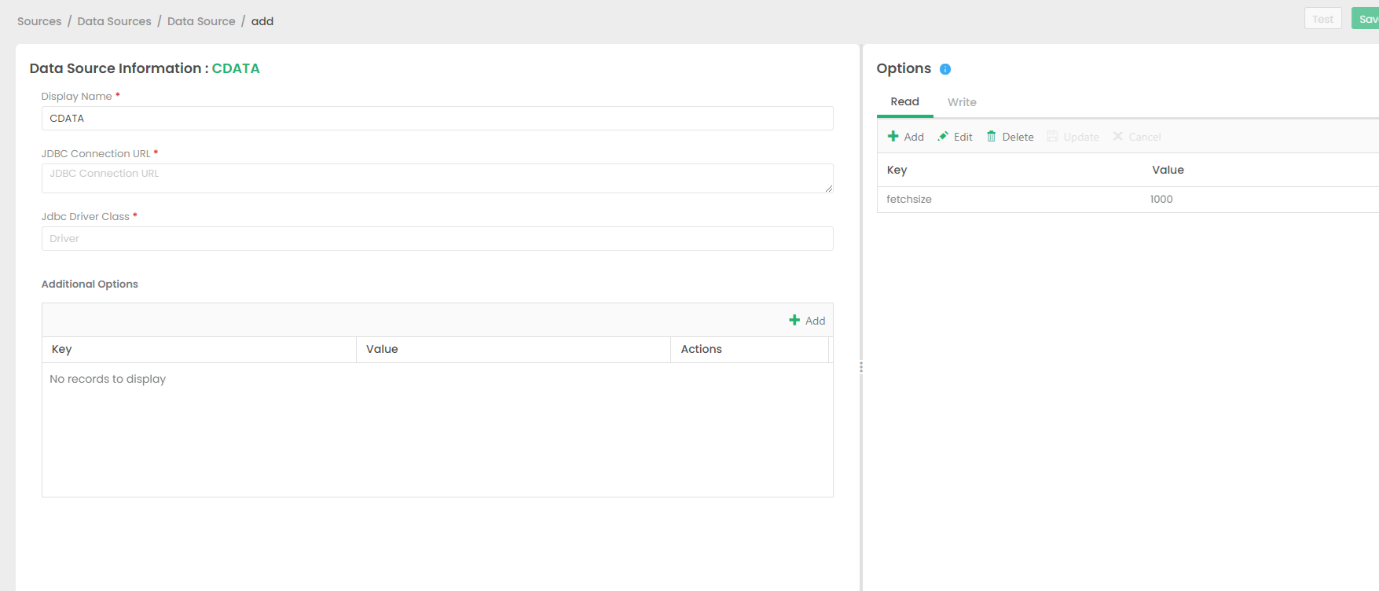
The driver connects to JD Edwards through your Application Interface Services (AIS) Server. Set the following connection properties:
- URL: The base HTTPS URL of your AIS Server (e.g., https://jde-ais.example.com:8300).
- User: Your JD Edwards username.
- Password: Your JD Edwards password.
- Environment (optional): The JD Edwards environment to use (e.g., PD920 for production or DV920 for development). If not specified, the AIS Server's default environment is used.
- Role (optional): The JD Edwards role for the session. If not specified, the AIS Server's default role is used.
- DeviceName (optional): An identifier for the connecting device or application, used for auditing and logging on the AIS Server.
- Jasserver (optional): The specific Java Application Server (JAS) instance to route requests through, useful in clustered environments.
Choosing Which Data Is Exposed
JD Edwards organizes tables and business views by System Code, and the driver exposes each System Code as its own schema. Use these properties to control which schemas are available:
- DataModel: One or more ERP modules (comma-separated) whose System Codes are exposed as schemas, or All to expose every System Code in the connected instance. Defaults to FinancialManagement.
- SystemCodes: A comma-separated list of additional System Codes to expose alongside those from DataModel (e.g., 42,43).
When you connect, the driver sends your credentials to the AIS Server to obtain a session token and caches it. The driver requests a new token automatically before the session expires.
Built-in Connection String Designer
For assistance in constructing the JDBC URL, use the connection string designer built into the JD Edwards JDBC Driver. Either double-click the JAR file or execute the jar file from the command-line.
java -jar cdata.jdbc.jdedwards.jar
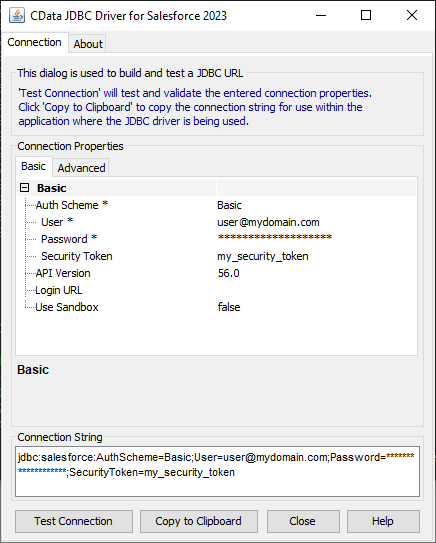
A typical connection string looks like this:
jdbc:jdedwards:URL=https://your-jde-environment-app.example.com;User=admin;Password=myPassword;
Licensing the Driver
To ensure the JDBC driver is licensed appropriately, copy the license file to the appropriate location:
Copy the JDBC Driver for JD Edwards and lic file from "C:\Program Files\CData\CData JDBC Driver for JD Edwards\lib" to "C:\Datagaps\ETLValidator\Server\apache-tomcat\bin".
            cdata.jdbc.jdedwards.jar
            cdata.jdbc.jdedwards.lic
Note: If you do not copy the .lic file with the jar, you will see a licensing error that indicates you do not have a valid license installed. This is true for both the trial and full versions.
Save the connection
Should you encounter any difficulties loading the CData JDBC driver class, please contact DataGap's team, and they will provide you instructions on how to load the jar file for the relevant driver.
Add SQL Server as a Target
This example will use SQL Server as a destination for JD Edwards data data, but any preferred destination can be used instead.
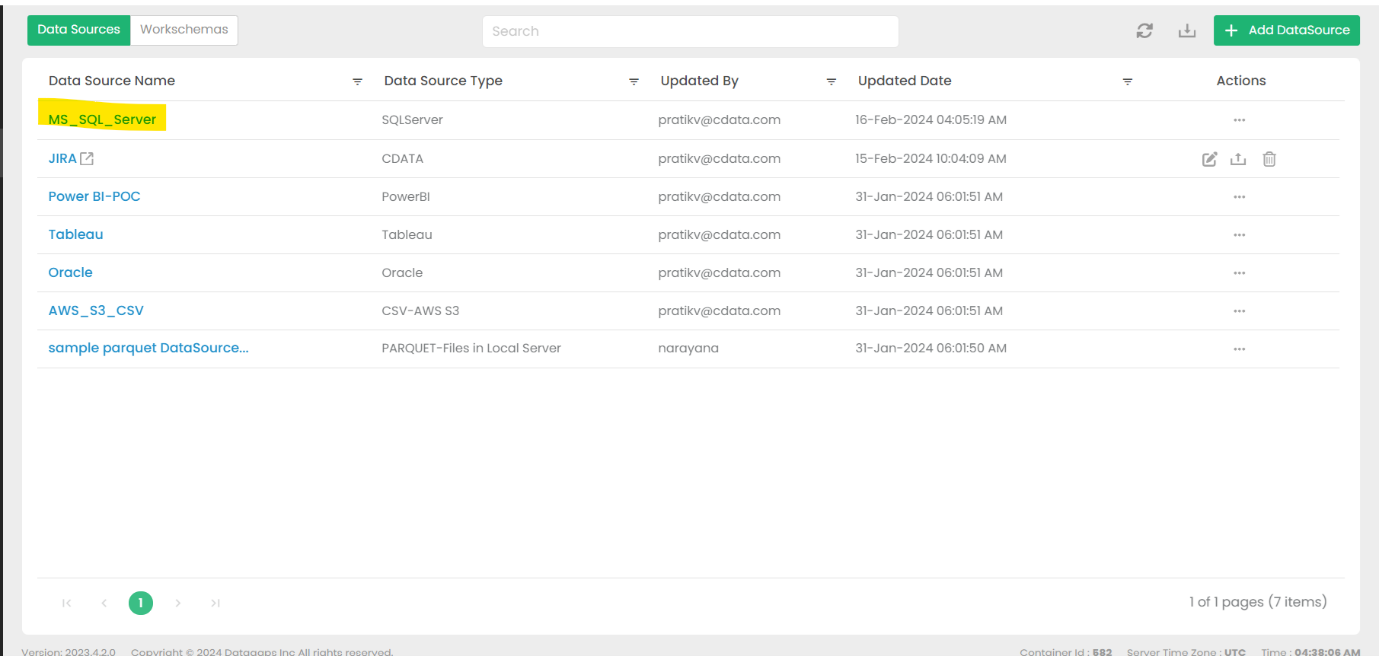
Go to DataSources and select MS_SQL_SERVER
This option is the default.
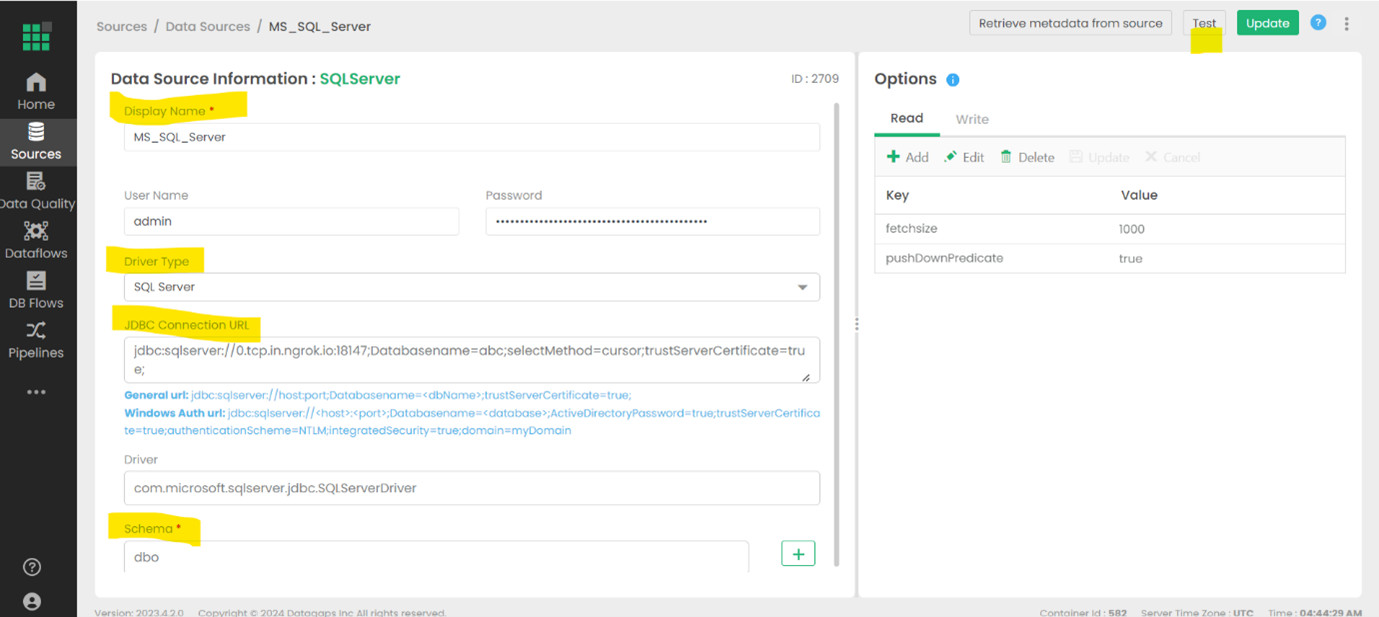
Fill in the necessary connection details and test the connection
The details will depend on the specific target, but these details may include a URL, authentiation credentials, etc.
Create a Dataflow in ETL Validator
Open the Dataflows tab
Configured data flows will appear in this window.
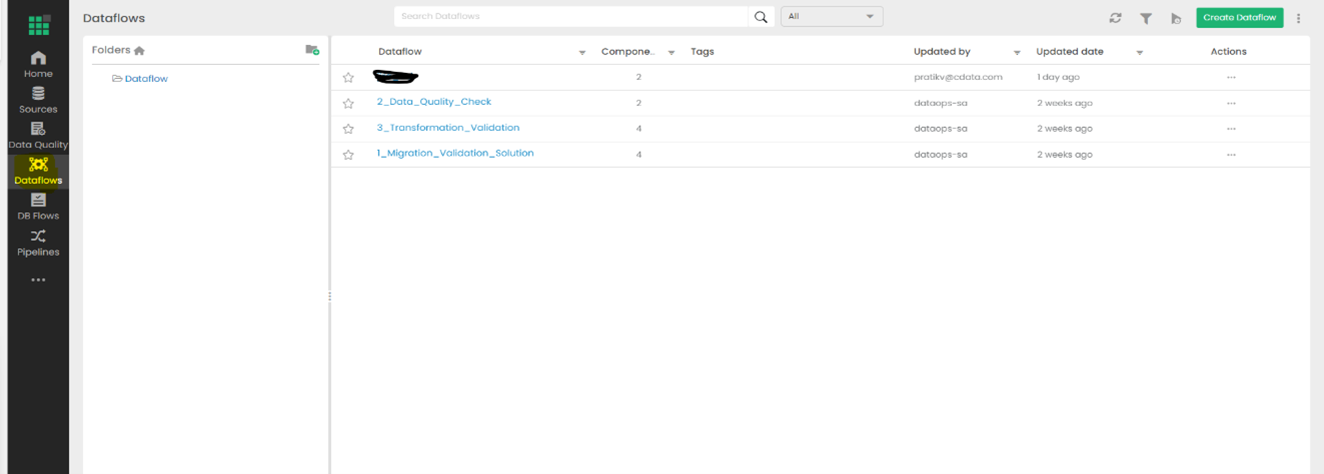
Select Create Dataflow
Name your new dataflow and save it.
Open the Dataflow to view the Dataflow Diagram
The details of the data movement will be configured in this panel.
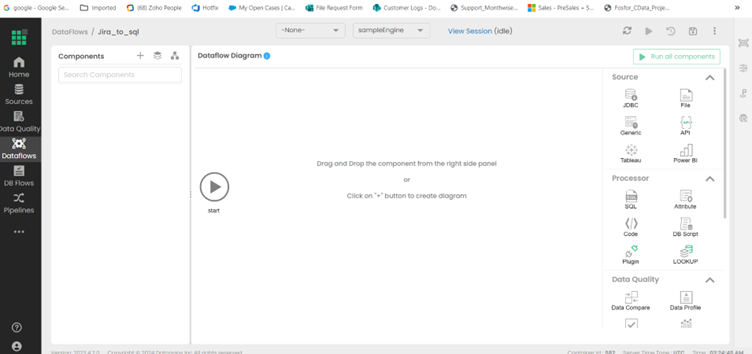
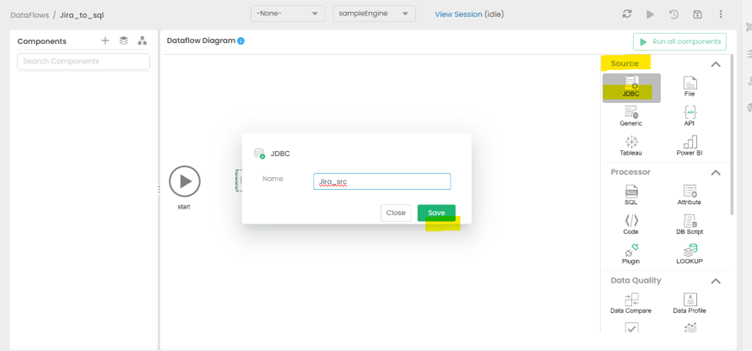
Drag & drop the JDBC as a source from the right side
Give the new source an appropriate name and save it.
Fill in the Query section of the new source
Select the Table from the Schema option that reflects which data should be pulled from JD Edwards data.
View the expected results of your query
The anticipated outcome of the configured query is displayed in the Result tab.
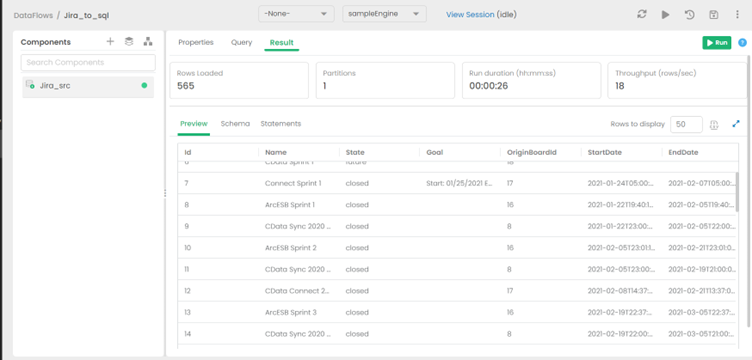
Add the destination to the Dataflow
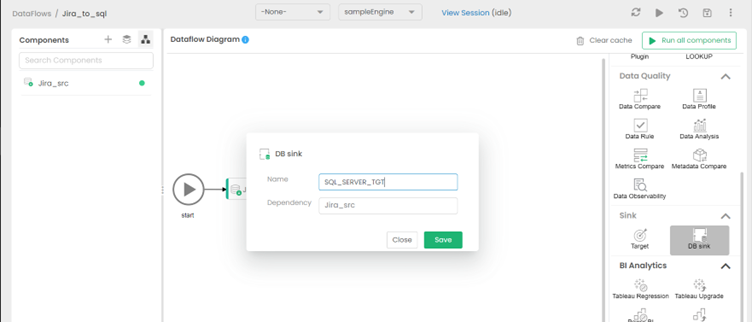
Select Switch to Diagram, then drag & drop the DB Sink as a target from the right side (under Sink options). Give the sink an appropriate name and save it.
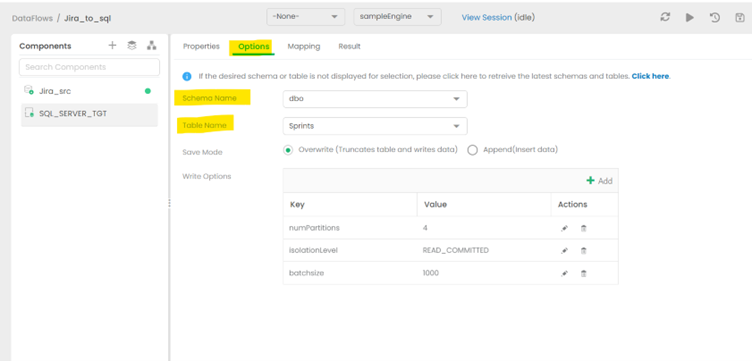
Set the appropriate Schema for the destination
Choose the Schema and table that matches the structure of the source table. For this example, the table on the target side was created to match the Source so that data flow seamlessly. More advanced schema transformation operations are beyond the scope of this article.
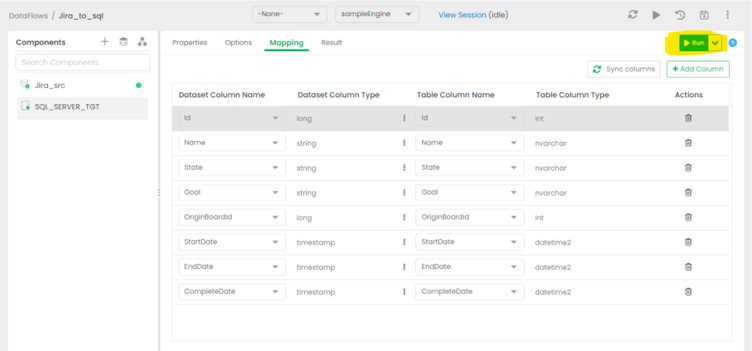
Hit the RUN option to begin replication
Running the job will take some time.
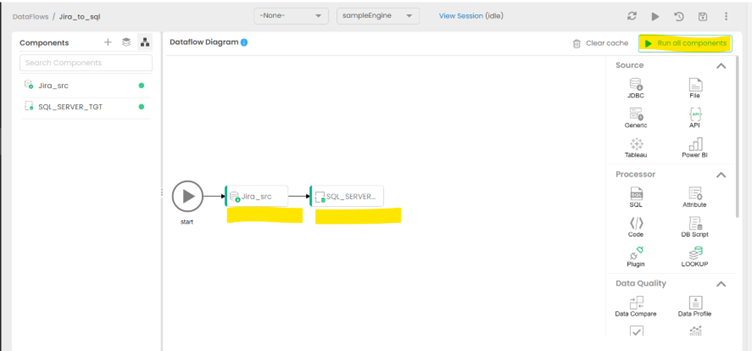
View the finished Dataflow
Return to the diagram to see the finished data replication job from JD Edwards data to SQL Server.
Get Started Today
Download a free, 30-day trial of the CData JDBC Driver for JD Edwards and start building JD Edwards-connected applications with ETL Validator. Reach out to our Support Team if you have any questions.
Ready to get started?
Download a free trial of the JD Edwards Driver to get started:
Download NowLearn more:
 JD Edwards JDBC Driver
Rapidly create and deploy powerful Java applications that integrate with JD Edwards data including AccountLedger, ProposalofPayment, ContractRevenueSummary, EmployeeEnrollment, RentIncreaseAmounts, and more!