




How to Seamlessly Import JD Edwards Data into IBM SPSS Modeler

IBM SPSS Modeler is a powerful data mining and predictive analytics platform that enables organizations to extract valuable insights from their data. By connecting JD Edwards data data to SPSS Modeler via the CData ODBC Driver for JD Edwards, you can leverage real-time access for advanced data mining, predictive modeling, and statistical analysis.
This guide takes you through the steps of connecting IBM SPSS Modeler to JD Edwards data, enabling seamless data import, preparation, and analysis. With the CData ODBC Driver for JD Edwards, you can unlock the full potential of your JD Edwards data data within IBM SPSS Modeler for actionable insights.
Overview
Here is an overview of the steps:
- CONFIGURE THE ODBC DRIVER: Set up a connection to JD Edwards data in the CData ODBC Driver for JD Edwards by entering the required connection properties.
- SET UP ODBC CONNECTION IN SPSS MODELER: Establish the ODBC connection within IBM SPSS Modeler by selecting the configured DSN.
- IMPORT AND PROCESS DATA: Import the JD Edwards data data into SPSS Modeler, then review, filter, transform, and prepare the data for predictive analytics and statistical modeling.
Configure the JD Edwards DSN Using the CData ODBC Driver
To start, configure the DSN (Data Source Name) for JD Edwards data in your system using the CData ODBC Driver. Download and install a 30-day free trial with all the features from here.
Once installed, launch the ODBC Data Source Administrator:
- On Windows: Search for ODBC Data Source Administrator in the Start menu and open the application.
- On Mac: Open Applications, go to Utilities, and select ODBC Manager.
- On Linux: Use the command line to launch ODBC Data Source Administrator or use unixODBC if installed.
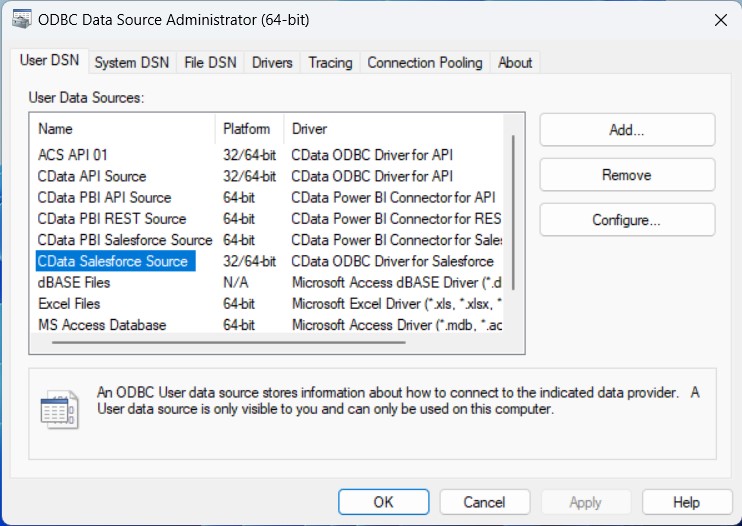
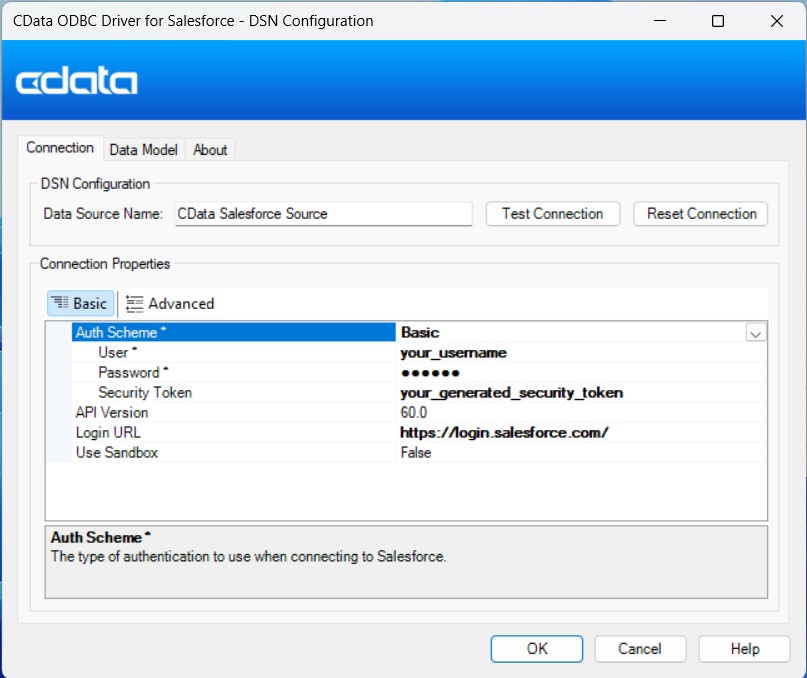
Once launched, double-click on the CData JD Edwards data Source and enter the required values to establish a connection:
The driver connects to JD Edwards through your Application Interface Services (AIS) Server. Set the following connection properties:
- URL: The base HTTPS URL of your AIS Server (e.g., https://jde-ais.example.com:8300).
- User: Your JD Edwards username.
- Password: Your JD Edwards password.
- Environment (optional): The JD Edwards environment to use (e.g., PD920 for production or DV920 for development). If not specified, the AIS Server's default environment is used.
- Role (optional): The JD Edwards role for the session. If not specified, the AIS Server's default role is used.
- DeviceName (optional): An identifier for the connecting device or application, used for auditing and logging on the AIS Server.
- Jasserver (optional): The specific Java Application Server (JAS) instance to route requests through, useful in clustered environments.
Choosing Which Data Is Exposed
JD Edwards organizes tables and business views by System Code, and the driver exposes each System Code as its own schema. Use these properties to control which schemas are available:
- DataModel: One or more ERP modules (comma-separated) whose System Codes are exposed as schemas, or All to expose every System Code in the connected instance. Defaults to FinancialManagement.
- SystemCodes: A comma-separated list of additional System Codes to expose alongside those from DataModel (e.g., 42,43).
When you connect, the driver sends your credentials to the AIS Server to obtain a session token and caches it. The driver requests a new token automatically before the session expires.
Setup an ODBC Connection in IBM SPSS Modeler
After configuring the DSN, it's time to connect to it in IBM SPSS Modeler:
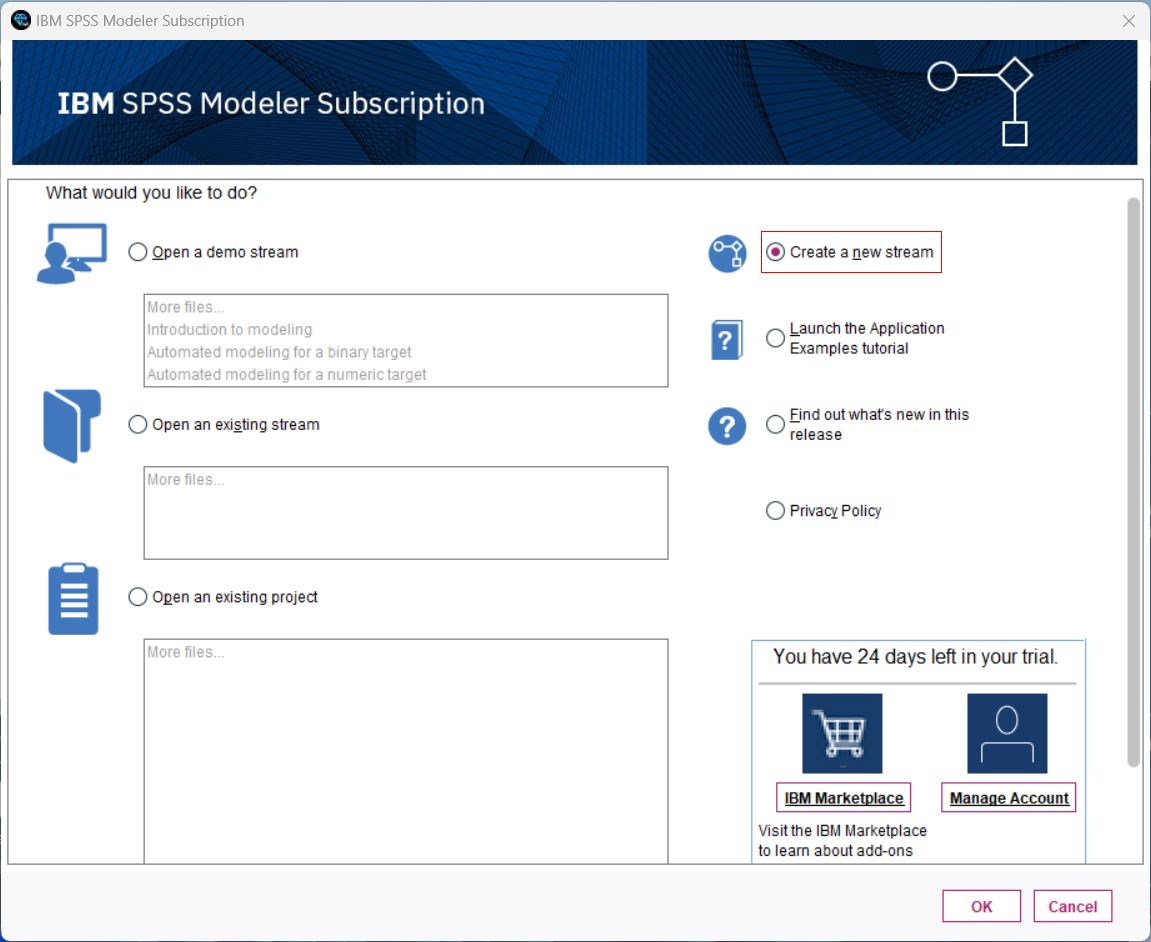
- Launch IBM SPSS Modeler, log in, and create a new stream.
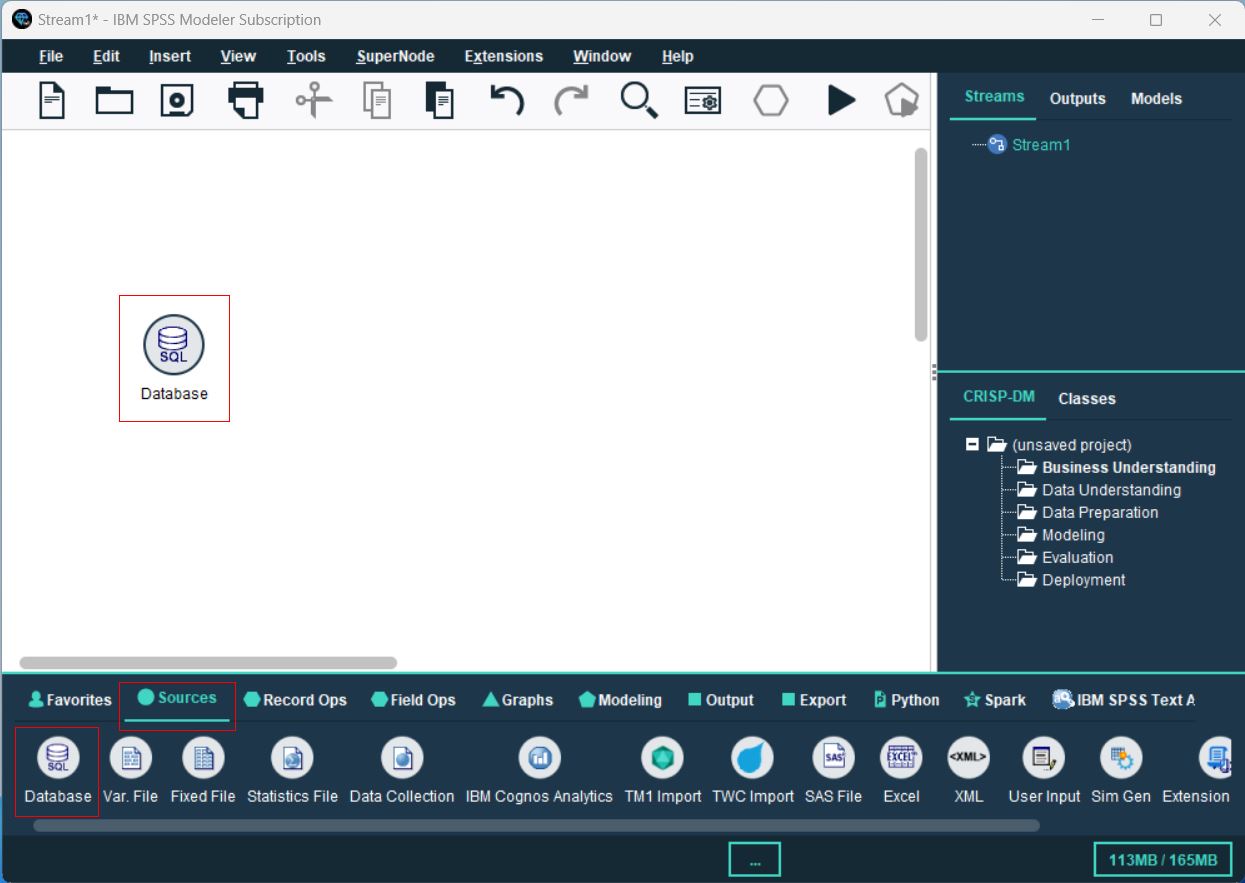
- From the Sources palette, locate the Database node, and drag it onto the canvas.
- Double-click the Database node to open the configuration dialog. Select
, browse to select the configured DSN, then click OK. - In the Database dialog, browse to select the table(s) you’d like to import, preview the data, and click OK to finalize.
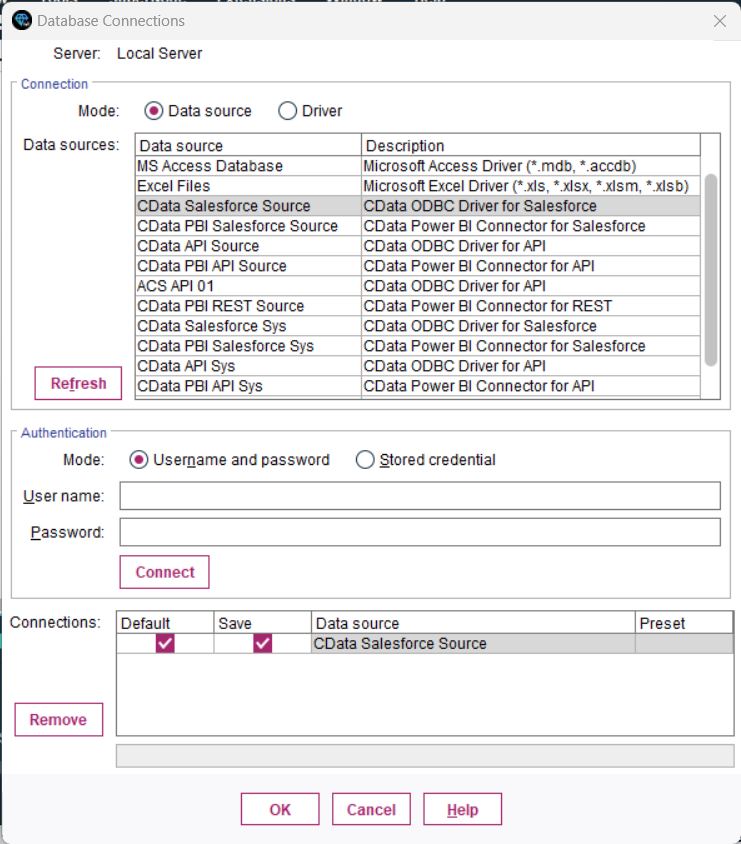
You are now ready to process and analyze the JD Edwards data data in IBM SPSS Modeler.
Process Data: Filter, Categories, and Model
Once the tables are imported, you can refine, filter, categorize, and model your JD Edwards data data in SPSS Modeler:
- Filtering: Double-click your Database connection, go to the Filter section, and select/deselect fields to focus on relevant data. This improves processing speed and model accuracy.
- Set Data Types and Roles: Categorize your fields and assign roles to each data type by navigating to the Types section.
- Perform a Basic Analysis: Drag and drop the Analysis node next to your Database node, connect them, and click the Play button to run the stream and analyze the data.
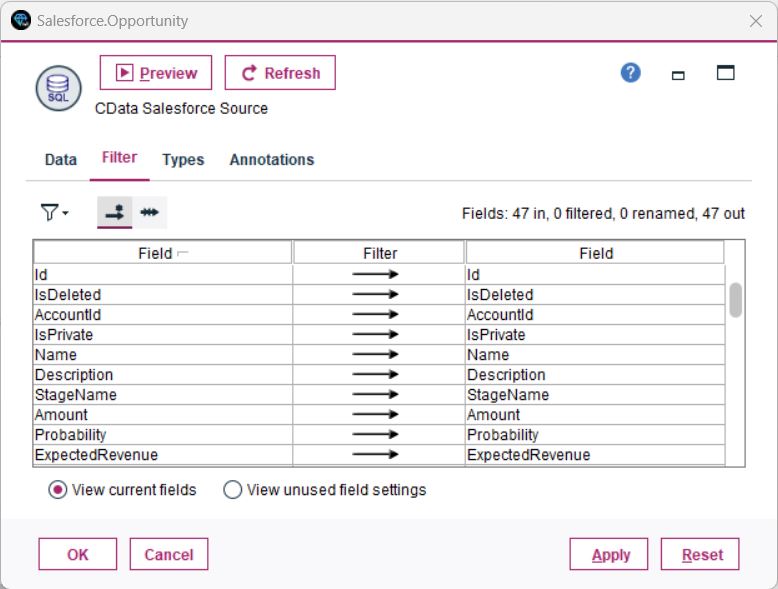
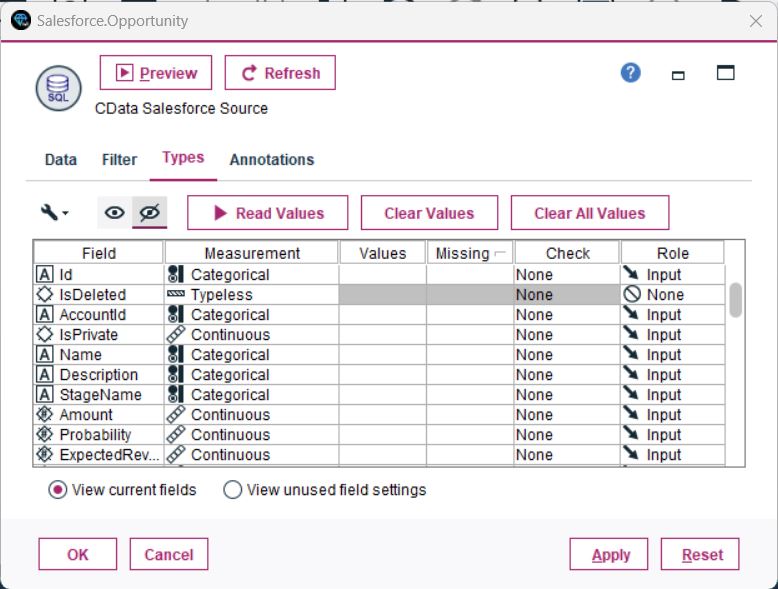
You have now performed a simple analysis, enabling SPSS Modeler to process and display insights from your database.
Unlock the Potential of Your JD Edwards Data with CData
With the CData ODBC Driver for JD Edwards, connecting JD Edwards data data to IBM SPSS Modeler is seamless. Start your free trial today and unlock the full potential of your real-time data for advanced analytics and decision-making.
Ready to get started?
Download a free trial of the JD Edwards ODBC Driver to get started:
Download NowLearn more:
 JD Edwards ODBC Driver
The JD Edwards ODBC Driver is a powerful tool that allows you to connect with live data from JD Edwards, directly from any applications that support ODBC connectivity.
Access JD Edwards data like you would a database - read JD Edwards AccountLedger, ProposalofPayment, ContractRevenueSummary, EmployeeEnrollment, RentIncreaseAmounts, etc. through a standard ODBC Driver interface.