




Migrating data from JD Edwards to Databricks using CData SSIS Components.
Databricks is a unified data analytics platform that allows organizations to easily process, analyze, and visualize large amounts of data. It combines data engineering, data science, and machine learning capabilities in a single platform, making it easier for teams to collaborate and derive insights from their data.
The CData SSIS Components enhance SQL Server Integration Services by enabling users to easily import and export data from various sources and destinations.
In this article, we explore the data type mapping considerations when exporting to Databricks and walk through how to migrate JD Edwards data to Databricks using the CData SSIS Components for JD Edwards and Databricks.
Data Type Mapping
| Databricks Schema | CData Schema |
|---|---|
|
int, integer, int32 |
int |
|
smallint, short, int16 |
smallint |
|
double, float, real |
float |
|
date |
date |
|
datetime, timestamp |
datetime |
|
time, timespan |
time |
|
string, varchar |
If length > 4000: nvarchar(max), Otherwise: nvarchar(length) |
|
long, int64, bigint |
bigint |
|
boolean, bool |
tinyint |
|
decimal, numeric |
decimal |
|
uuid |
nvarchar(length) |
|
binary, varbinary, longvarbinary |
binary(1000) or varbinary(max) after SQL Server 2000 |
Special Considerations
- String/VARCHAR: String columns from Databricks can map to different data types depending on the length of the column. If the column length exceeds 4000, then the column is mapped to nvarchar (max). Otherwise, the column is mapped to nvarchar (length).
- DECIMAL Databricks supports DECIMAL types up to 38 digits of precision, but any source column beyond that can cause load errors.
Prerequisites
- Visual Studio 2022
- SQL Server Integration Services Projects extension for Visual Studio 2022
- CData SSIS Components for Databricks
- CData SSIS Components for JD Edwards
Create the project and add components
-
Open Visual Studio and create a new Integration Services Project.
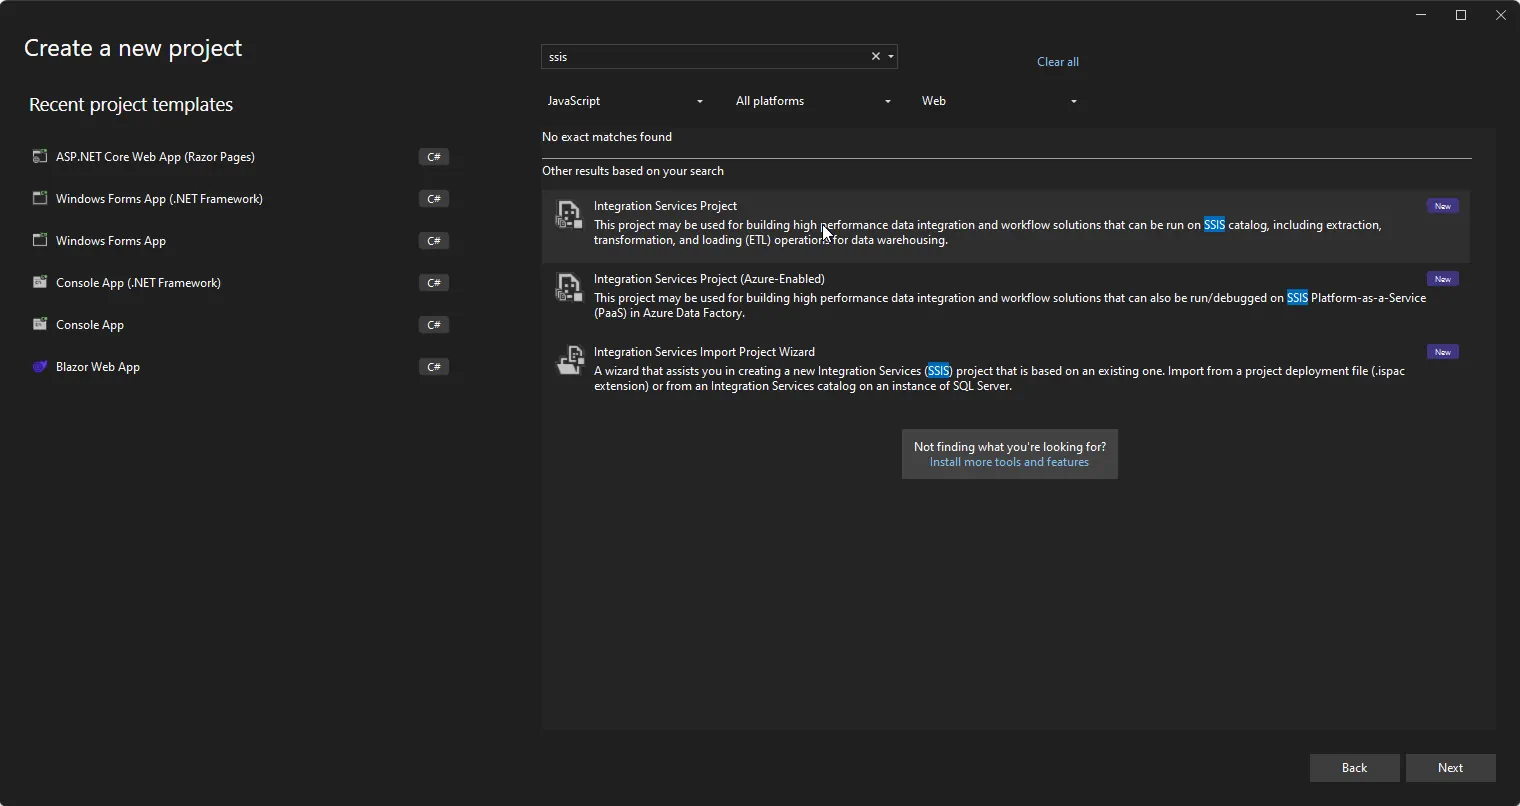
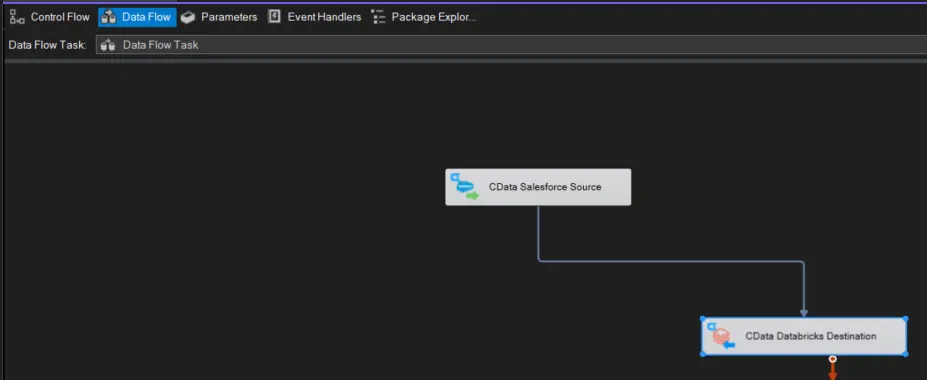
- Add a new Data Flow Task to the Control Flow screen and open the Data Flow Task.
-
Add a CData JD Edwards Source control and a CData Databricks Destination control to the data flow task.
Configure the JD Edwards source
Follow the steps below to specify properties required to connect to JD Edwards.
-
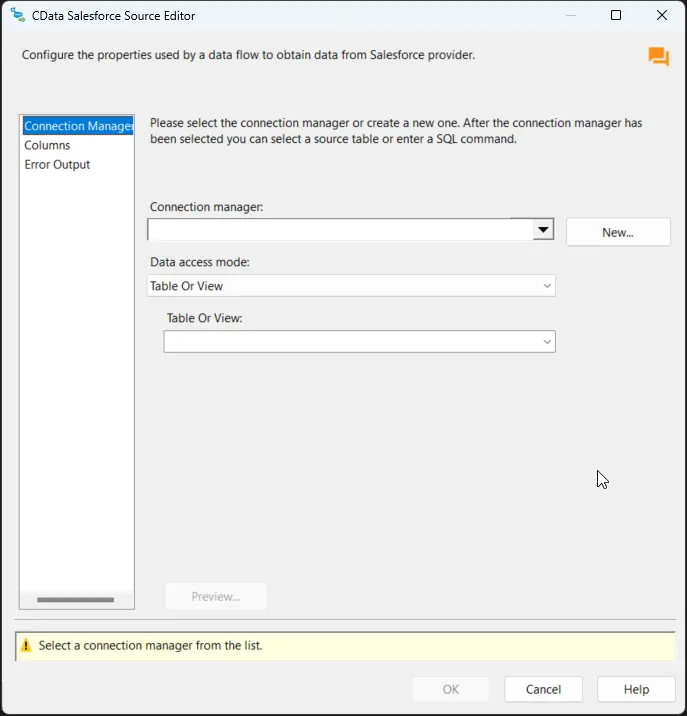
Double-click the CData JD Edwards Source to open the source component editor and add a new connection.
-
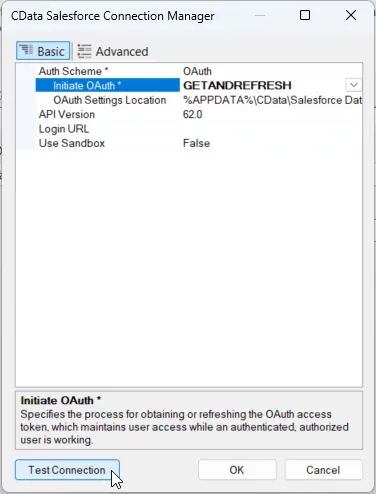
In the CData JD Edwards Connection Manager, configure the connection properties, then test and save the connection.
The driver connects to JD Edwards through your Application Interface Services (AIS) Server. Set the following connection properties:
- URL: The base HTTPS URL of your AIS Server (e.g., https://jde-ais.example.com:8300).
- User: Your JD Edwards username.
- Password: Your JD Edwards password.
- Environment (optional): The JD Edwards environment to use (e.g., PD920 for production or DV920 for development). If not specified, the AIS Server's default environment is used.
- Role (optional): The JD Edwards role for the session. If not specified, the AIS Server's default role is used.
- DeviceName (optional): An identifier for the connecting device or application, used for auditing and logging on the AIS Server.
- Jasserver (optional): The specific Java Application Server (JAS) instance to route requests through, useful in clustered environments.
Choosing Which Data Is Exposed
JD Edwards organizes tables and business views by System Code, and the driver exposes each System Code as its own schema. Use these properties to control which schemas are available:
- DataModel: One or more ERP modules (comma-separated) whose System Codes are exposed as schemas, or All to expose every System Code in the connected instance. Defaults to FinancialManagement.
- SystemCodes: A comma-separated list of additional System Codes to expose alongside those from DataModel (e.g., 42,43).
When you connect, the driver sends your credentials to the AIS Server to obtain a session token and caches it. The driver requests a new token automatically before the session expires.
-
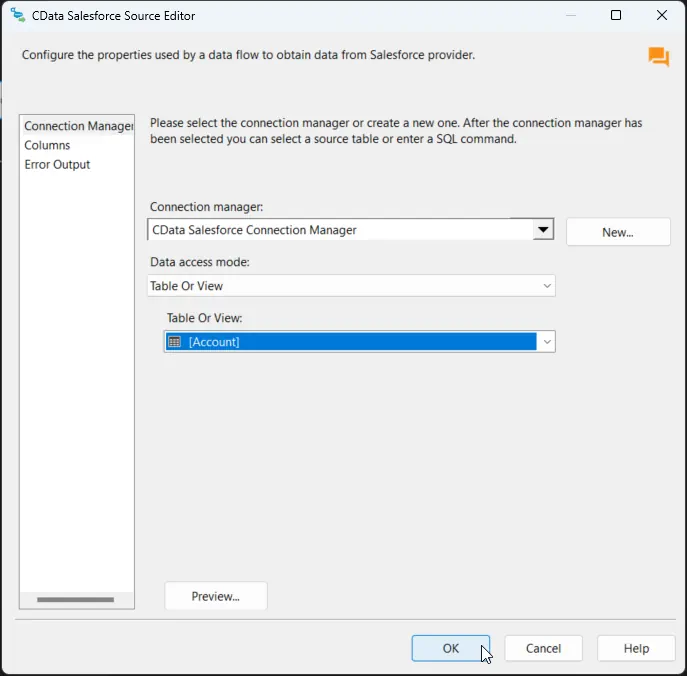
After saving the connection, select "Table or view" and select the table or view to export into Databricks, then close the CData JD Edwards Source Editor.
Configure the Databricks destination
With the JD Edwards Source configured, we can configure the Databricks connection and map the columns.
-
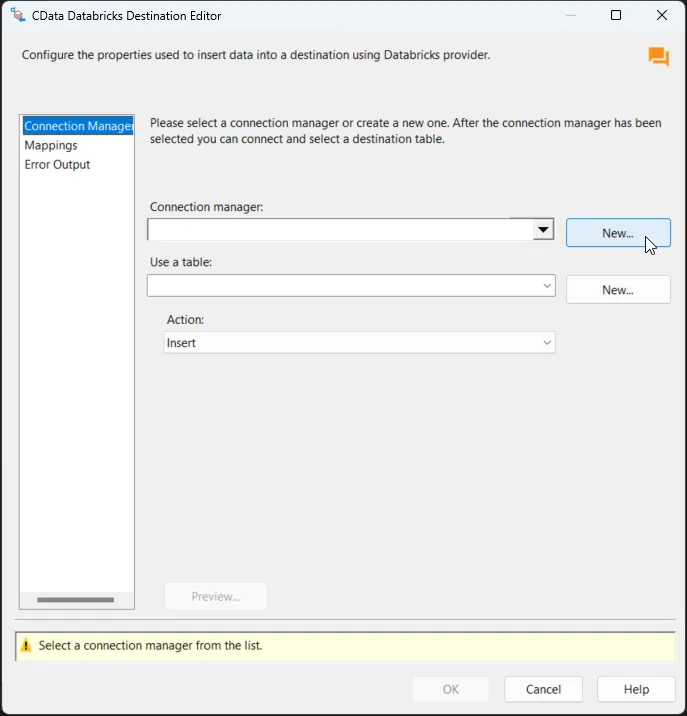
Double-click the CData Databricks Destination to open the destination component editor and add a new connection.
-
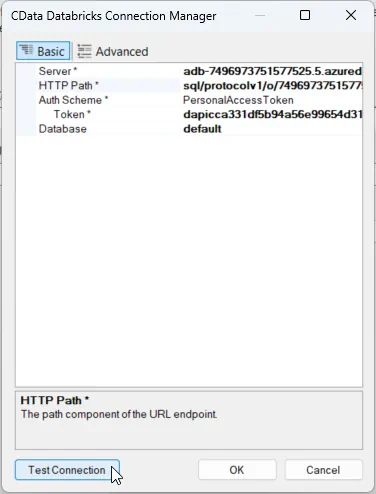
In the CData Databricks Connection Manager, configure the connection properties, then test and save the connection. To connect to a Databricks cluster, set the properties as described below.
Note: The needed values can be found in your Databricks instance by navigating to Clusters, selecting the desired cluster, and selecting the JDBC/ODBC tab under Advanced Options.
- Server: Set to the Server Hostname of your Databricks cluster.
- HTTPPath: Set to the HTTP Path of your Databricks cluster.
- Token: Set to your personal access token (this value can be obtained by navigating to the User Settings page of your Databricks instance and selecting the Access Tokens tab).
Other helpful connection properties
- QueryPassthrough: When this is set to True, queries are passed through directly to Databricks.
- ConvertDateTimetoGMT: When this is set to True, the components will convert date-time values to GMT, instead of the local time of the machine.
- UseUploadApi: Setting this property to true will improve performance if there is a large amount of data in a Bulk INSERT operation.
- UseCloudFetch: This option specifies whether to use CloudFetch to improve query efficiency when the table contains over one million entries.
-
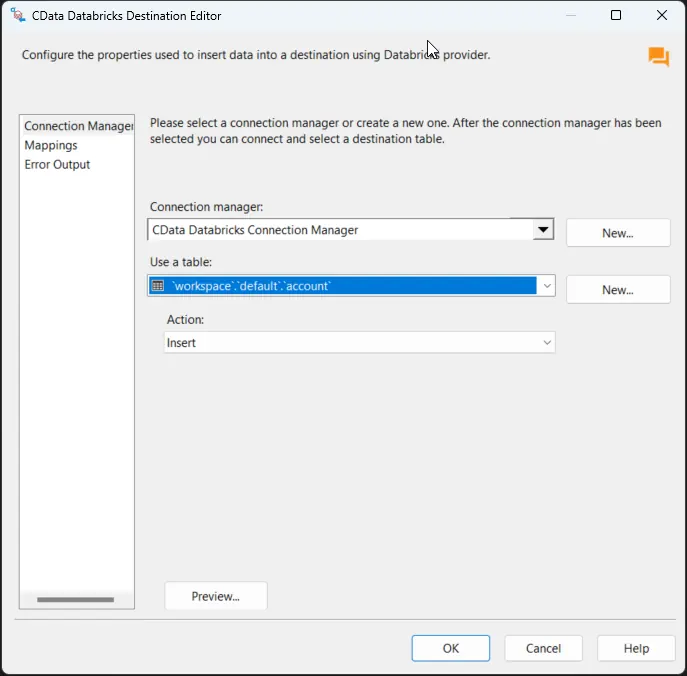
After saving the connection, select a table in the Use a Table menu and in the Action menu, select Insert.
-
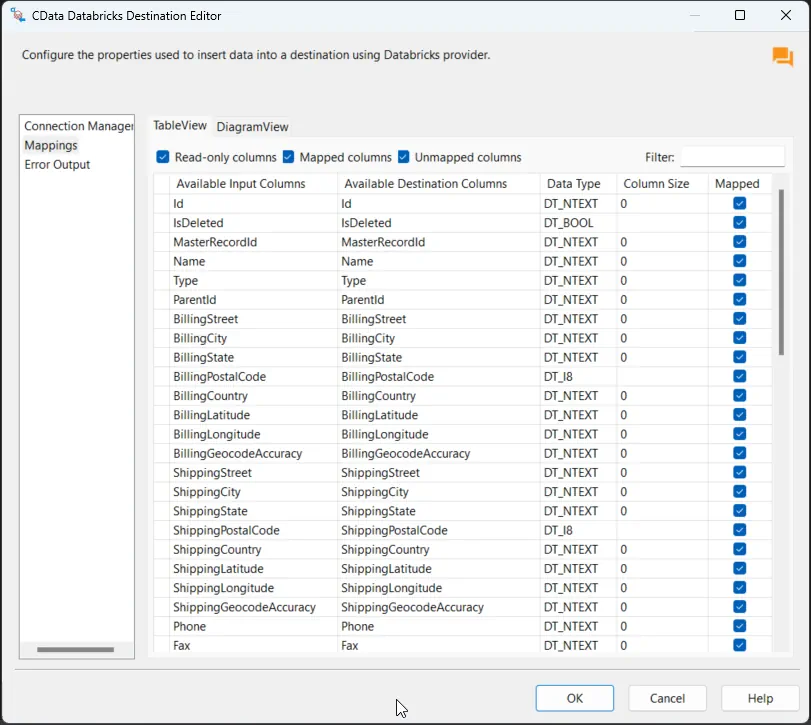
On the Column Mappings tab, configure the mappings from the input columns to the destination columns.
Run the project
You can now run the project. After the SSIS Task has finished executing, data from your SQL table will be exported to the chosen table.
Ready to get started?
Download a free trial of the JD Edwards SSIS Component to get started:
Download NowLearn more:
 JD Edwards SSIS Components
Powerful SSIS Source Components that allow you to easily connect SQL Server with JD Edwards through SSIS Workflows.
Use the JD Edwards Data Flow Components to synchronize with JD Edwards AccountLedger, ProposalofPayment, ContractRevenueSummary, EmployeeEnrollment, RentIncreaseAmounts, and more. Perfect for data synchronization, local back-ups, workflow automation, and more!