

Process & Analyze Respond.io Data in Databricks (AWS)
Databricks is a cloud-based service that provides data processing capabilities through Apache Spark. When paired with the CData JDBC Driver, customers can use Databricks to perform data engineering and data science on live Respond.io data. This article explains how to host the CData JDBC Driver in AWS, as well as connect to and process live Respond.io data in Databricks.
With built-in optimized data processing, the CData JDBC Driver offers unmatched performance for interacting with live Respond.io data. When you issue complex SQL queries to Respond.io, the driver pushes supported SQL operations, like filters and aggregations, directly to Respond.io and utilizes the embedded SQL engine to process unsupported operations client-side (often SQL functions and JOIN operations). Its built-in dynamic metadata querying allows you to work with and analyze Respond.io data using native data types.
Install the CData JDBC Driver in Databricks
To work with live Respond.io data in Databricks, install the driver on your Databricks cluster.
- Navigate to your Databricks administration screen and select the target cluster.
- On the Libraries tab, click "Install New."
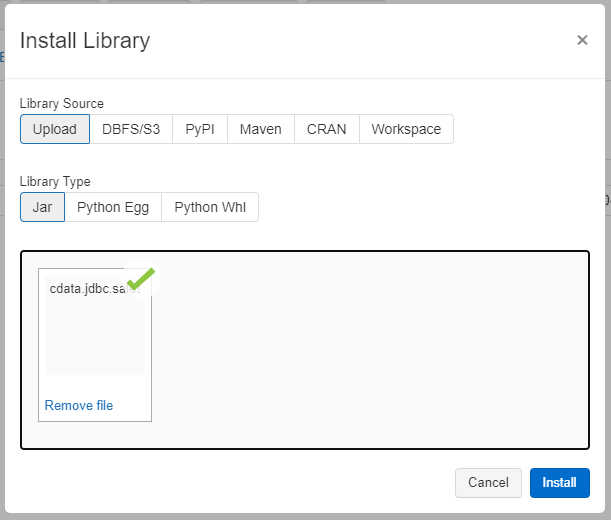
- Select "Upload" as the Library Source and "Jar" as the Library Type.
- Upload the JDBC JAR file (cdata.jdbc.api.jar) from the installation location (typically C:\Program Files\CData\CData API Driver for JDBC\lib).
Access Respond.io Data in your Notebook: Python
With the JAR file installed, we are ready to work with live Respond.io data in Databricks. Start by creating a new notebook in your workspace. Name the notebook, select Python as the language (though Scala is available as well), and choose the cluster where you installed the JDBC driver. When the notebook launches, we can configure the connection, query Respond.io, and create a basic report.
Configure the Connection to Respond.io
Connect to Respond.io by referencing the JDBC Driver class and constructing a connection string to use in the JDBC URL. Additionally, you will need to set the RTK property in the JDBC URL (unless you are using a Beta driver). You can view the licensing file included in the installation for information on how to set this property.
Step 1: Connection Information
driver = "cdata.jdbc.api.APIDriver"
url = "jdbc:api:RTK=5246...;Profile=C:\profiles\Respondio.apip;AuthScheme=APIKey;ProfileSettings='APIKey=your_api_key';"
Built-in Connection String Designer
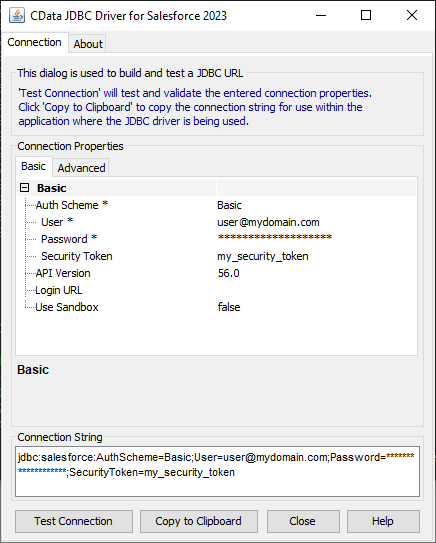
For assistance in constructing the JDBC URL, use the connection string designer built into the Respond.io JDBC Driver. Either double-click the JAR file or execute the jar file from the command-line.
java -jar cdata.jdbc.api.jar
Fill in the connection properties and copy the connection string to the clipboard.
Start by setting the Profile connection property to the location of the Respondio Profile on disk (e.g. C:\profiles\Respondio.apip). Next, set the ProfileSettings connection property to the connection string for Respondio (see below).
Respondio API Profile Settings
Respond.io uses API key authentication. To obtain an API key:
- Log in to your Respond.io account.
- Navigate to Settings in your workspace.
- Select Developer under the Integrations section.
- Copy the API key displayed on the page.
After obtaining your API key, set the following connection properties:
- AuthScheme: Set this to APIKey.
Set the following in the ProfileSettings connection property:
- APIKey: Set this to your Respond.io API key.
Load Respond.io Data
Once you configure the connection, you can load Respond.io data as a dataframe using the CData JDBC Driver and the connection information.
Step 2: Reading the data
remote_table = spark.read.format ( "jdbc" ) \
	.option ( "driver" , driver) \
	.option ( "url" , url) \
	.option ( "dbtable" , "Contacts") \
	.load ()
Display Respond.io Data
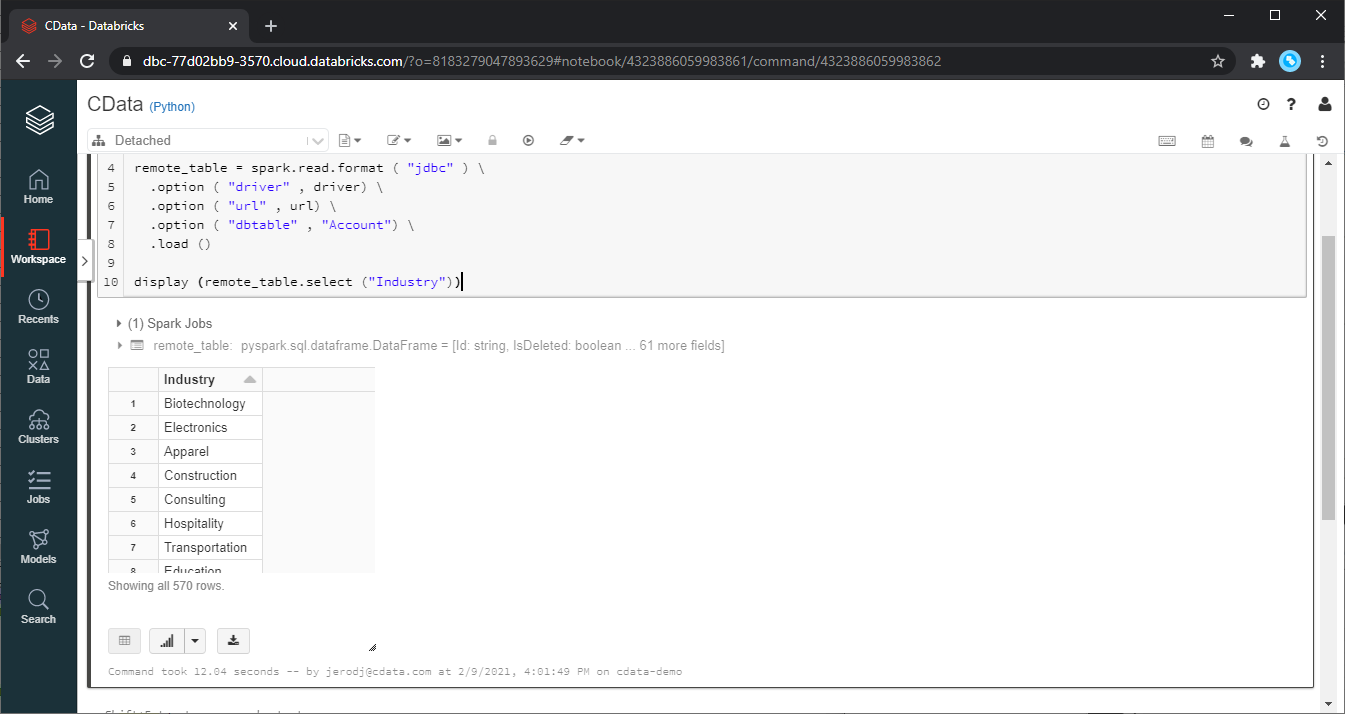
Check the loaded Respond.io data by calling the display function.
Step 3: Checking the result
display (remote_table.select ("Id"))
Analyze Respond.io Data in Databricks
If you want to process data with Databricks SparkSQL, register the loaded data as a Temp View.
Step 4: Create a view or table
remote_table.createOrReplaceTempView ( "SAMPLE_VIEW" )
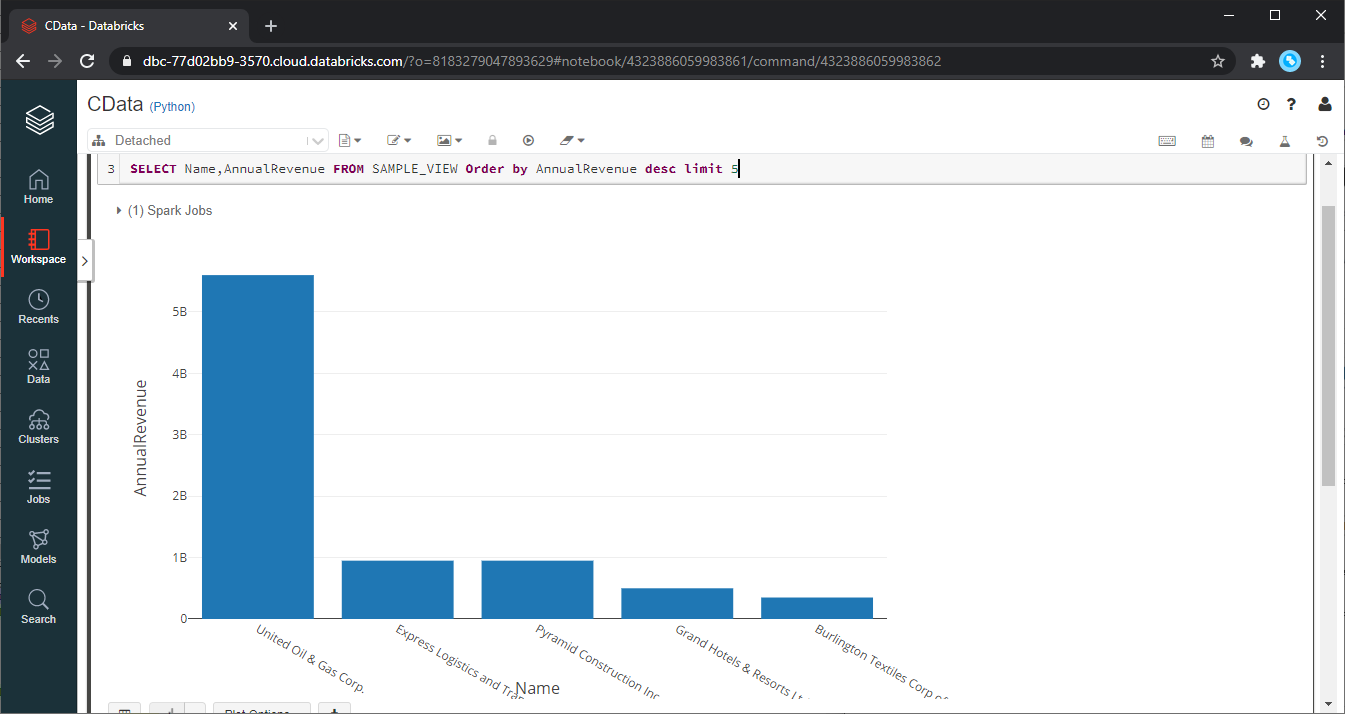
With the Temp View created, you can use SparkSQL to retrieve the Respond.io data for reporting, visualization, and analysis.
% sql

SELECT Id, Email FROM SAMPLE_VIEW ORDER BY Email DESC LIMIT 5
The data from Respond.io is only available in the target notebook. If you want to use it with other users, save it as a table.
remote_table.write.format ( "parquet" ) .saveAsTable ( "SAMPLE_TABLE" )
Download a free, 30-day trial of the CData API Driver for JDBC and start working with your live Respond.io data in Databricks. Reach out to our Support Team if you have any questions.