




Build Sage X3 Cloud-Connected ETL Processes in Google Data Fusion
Google Data Fusion allows users to perform self-service data integration to consolidate disparate data. Uploading the CData JDBC Driver for Sage X3 Cloud enables users to access live Sage X3 Cloud data from within their Google Data Fusion pipelines. While the CData JDBC Driver enables piping Sage X3 Cloud data to any data source natively supported in Google Data Fusion, this article explains how to pipe data from Sage X3 Cloud to Google BigQuery,
Upload the CData JDBC Driver for Sage X3 Cloud to Google Data Fusion
Upload the CData JDBC Driver for Sage X3 Cloud to your Google Data Fusion instance to work with live Sage X3 Cloud data. Due to the naming restrictions for JDBC drivers in Google Data Fusion, create a copy or rename the JAR file to match the following format driver-version.jar. For example: cdatasagex3cloud-2020.jar
- Open your Google Data Fusion instance
- Click the to add an entity and upload a driver
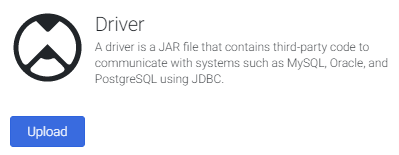
- On the "Upload driver" tab, drag or browse to the renamed JAR file.
- On the "Driver configuration" tab:
- Name: Create a name for the driver (cdata.jdbc.sagex3cloud) and make note of the name
- Class name: Set the JDBC class name: (cdata.jdbc.sagex3cloud.SageX3CloudDriver)
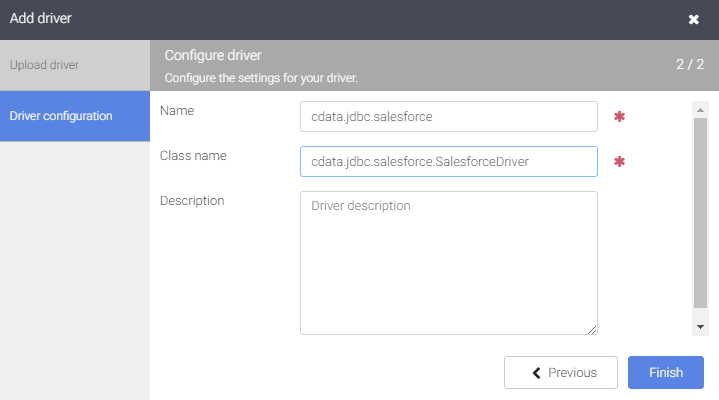
- Click "Finish"
Connect to Sage X3 Cloud Data in Google Data Fusion
With the JDBC Driver uploaded, you are ready to work with live Sage X3 Cloud data in Google Data Fusion Pipelines.
- Navigate to the Pipeline Studio to create a new Pipeline
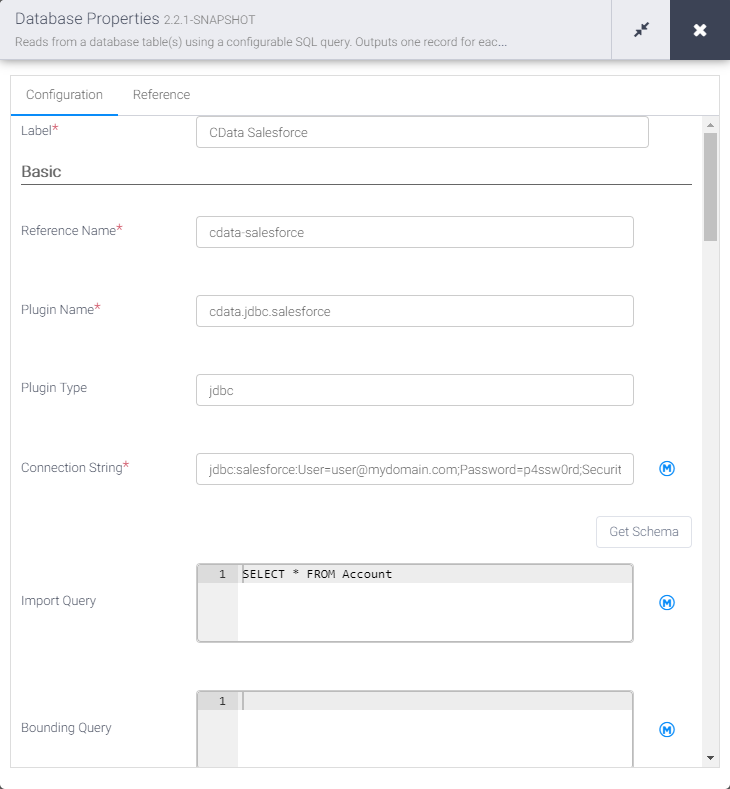
- From the "Source" options, click "Database" to add a source for the JDBC Driver
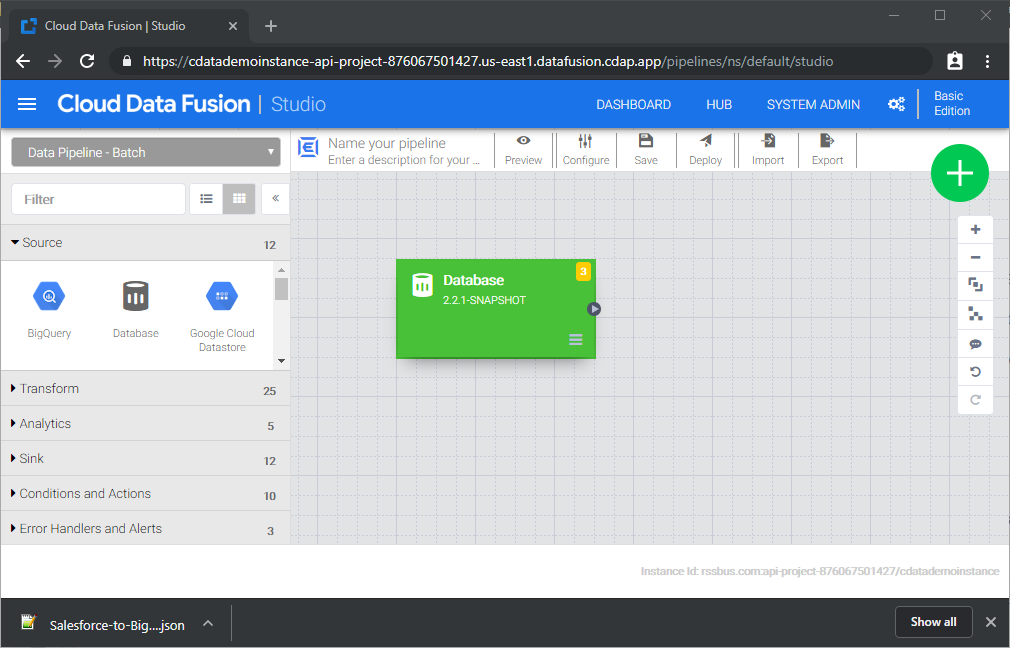
- Click "Properties" on the Database source to edit the properties
NOTE: To use the JDBC Driver in Google Data Fusion, you will need a license (full or trial) and a Runtime Key (RTK). For more information on obtaining this license (or a trial), contact our sales team.
- Set the Label
- Set Reference Name to a value for any future references (i.e.: cdata-sagex3cloud)
- Set Plugin Type to "jdbc"
- Set Connection String to the JDBC URL for Sage X3 Cloud. For example:
jdbc:sagex3cloud:RTK=5246...;AuthScheme=OAuth;URL=https://x3server/;OAuthAccessTokenUrl=https://auth-domain/oauth/token;OAuthClientId=your_client_id;OAuthClientSecret=your_client_secret;Audience=https://api-audience;XAPIKey=your_api_key;Folder=SEED;Sage X3 Cloud uses the OAuth 2.0 Client Credentials flow, and an X-API-Key is also required for API access. Set AuthScheme to OAuth and specify the following connection properties:
- URL: The base URL of your Sage X3 Cloud instance.
- OAuthAccessTokenUrl: The OAuth token endpoint (e.g., https://your-auth-domain/oauth/token).
- OAuthClientId: Your OAuth application client ID.
- OAuthClientSecret: Your OAuth application client secret.
- Audience: The API audience value for the token request.
- XAPIKey: The X-API-Key provided by your Sage X3 Cloud administrator.
- Folder: The Sage X3 folder name (e.g., SEED). This folder is used as the default schema.
- Folders (optional): A comma-separated list of Sage X3 folders (e.g., SEED,PERF). Each folder is exposed as a separate schema, so you can query across folders with the Schema.Table syntax.
The driver obtains an access token with the Client Credentials flow and sends it with the X-API-Key on every API request. With InitiateOAuth set to GETANDREFRESH (the default), the driver acquires and refreshes the token automatically.
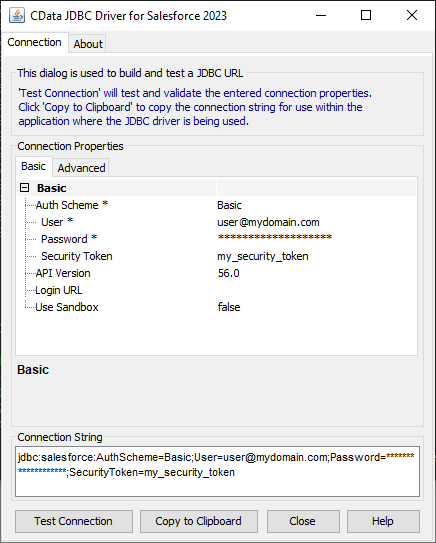
Built-in Connection String Designer
For assistance in constructing the JDBC URL, use the connection string designer built into the Sage X3 Cloud JDBC Driver. Either double-click the JAR file or execute the jar file from the command-line.
java -jar cdata.jdbc.sagex3cloud.jarFill in the connection properties and copy the connection string to the clipboard.
- Set Import Query to a SQL query that will extract the data you want from Sage X3 Cloud, i.e.:
SELECT * FROM BPCUSTOMER
- From the "Sink" tab, click to add a destination sink (we use Google BigQuery in this example)
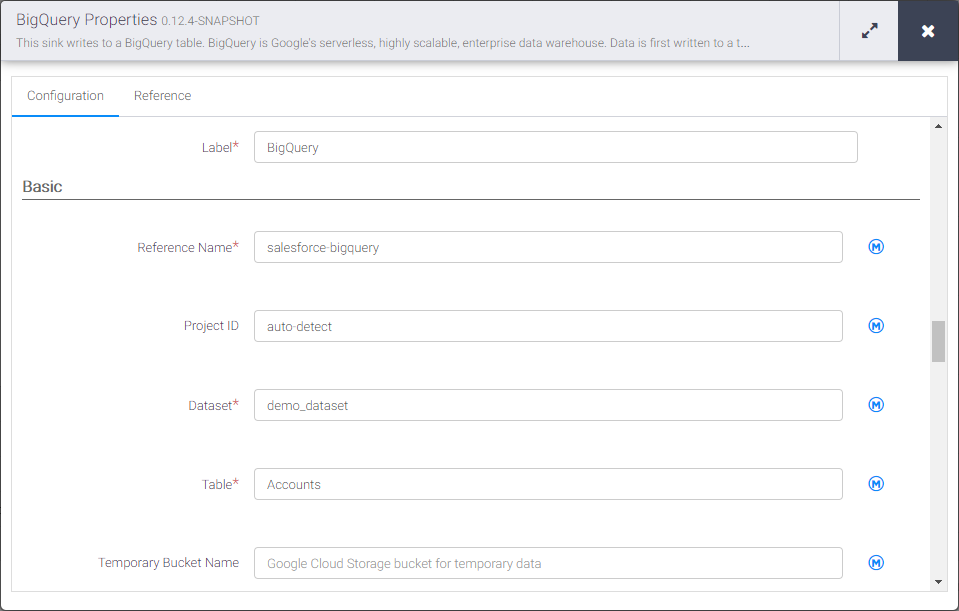
- Click "Properties" on the BigQuery sink to edit the properties
- Set the Label
- Set Reference Name to a value like sagex3cloud-bigquery
- Set Project ID to a specific Google BigQuery Project ID (or leave as the default, "auto-detect")
- Set Dataset to a specific Google BigQuery dataset
- Set Table to the name of the table you wish to insert Sage X3 Cloud data into
With the Source and Sink configured, you are ready to pipe Sage X3 Cloud data into Google BigQuery. Save and deploy the pipeline. When you run the pipeline, Google Data Fusion will request live data from Sage X3 Cloud and import it into Google BigQuery.
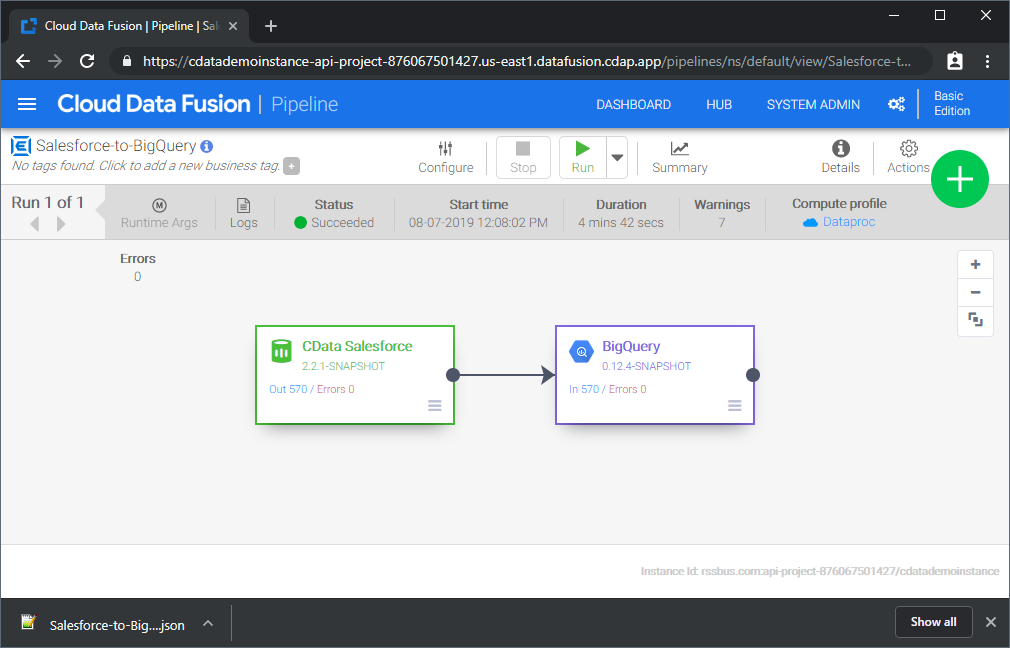
While this is a simple pipeline, you can create more complex Sage X3 Cloud pipelines with transforms, analytics, conditions, and more. Download a free, 30-day trial of the CData JDBC Driver for Sage X3 Cloud and start working with your live Sage X3 Cloud data in Google Data Fusion today.
Ready to get started?
Download a free trial of the Sage X3 Cloud Driver to get started:
Download NowLearn more:
 Sage X3 Cloud JDBC Driver
Rapidly create and deploy powerful Java applications that integrate with Sage X3 Cloud.