




Stream BugHerd Data into Apache Kafka Topics
Apache Kafka is an open-source stream processing platform that is primarily used for building real-time data pipelines and event-driven applications. When paired with the CData API Driver for JDBC, Kafka can work with live BugHerd data. This article describes how to connect, access and stream BugHerd data into Apache Kafka Topics and to start Confluent Control Center to help users secure, manage, and monitor the BugHerd data received using Kafka infrastructure in the Confluent Platform.
With built-in optimized data processing, the CData JDBC Driver offers unmatched performance for interacting with live BugHerd data. When you issue complex SQL queries to BugHerd, the driver pushes supported SQL operations, like filters and aggregations, directly to BugHerd and utilizes the embedded SQL engine to process unsupported operations client-side (often SQL functions and JOIN operations). Its built-in dynamic metadata querying allows you to work with and analyze BugHerd data using native data types.
Prerequisites
Before connecting the CData JDBC Driver for streaming BugHerd data in Apache Kafka Topics, install and configure the following in the client Linux-based system.
- Confluent Platform for Apache Kafka
- Confluent Hub CLI Installation
- Self-Managed Kafka JDBC Source Connector for Confluent Platform
Define a New JDBC Connection to BugHerd data
- Download CData API Driver for JDBC on a Linux-based system
- Follow the given instructions to create a new directory extract all the driver contents into it:
- Create a new directory named BugHerd
mkdir API - Move the downloaded driver file (.zip) into this new directory
mv APIJDBCDriver.zip API/ - Unzip the CData APIJDBCDriver contents into this new directory
unzip APIJDBCDriver.zip
- Create a new directory named BugHerd
- Open the BugHerd directory and navigate to the lib folder
ls cd lib/ - Copy the contents of the lib folder of the CData API Driver for JDBC into the lib folder of Kafka Connect JDBC. Check the Kafka Connect JDBC folder contents to confirm that the cdata.jdbc.api.jar file is successfully copied into the lib folder
cp -r /path/to/CData API Driver for JDBC/lib/* /usr/share/confluent-hub-components/confluentinc-kafka-connect-jdbc/lib/ cd /usr/share/confluent-hub-components/confluentinc-kafka-connect-jdbc/lib/ - Install the CData BugHerd JDBC driver license using the given command, followed by your Name and Email ID
java -jar cdata.jdbc.api.jar -l - Enter the product key or "TRIAL" (In the scenarios of license expiry, please contact our CData Support team)
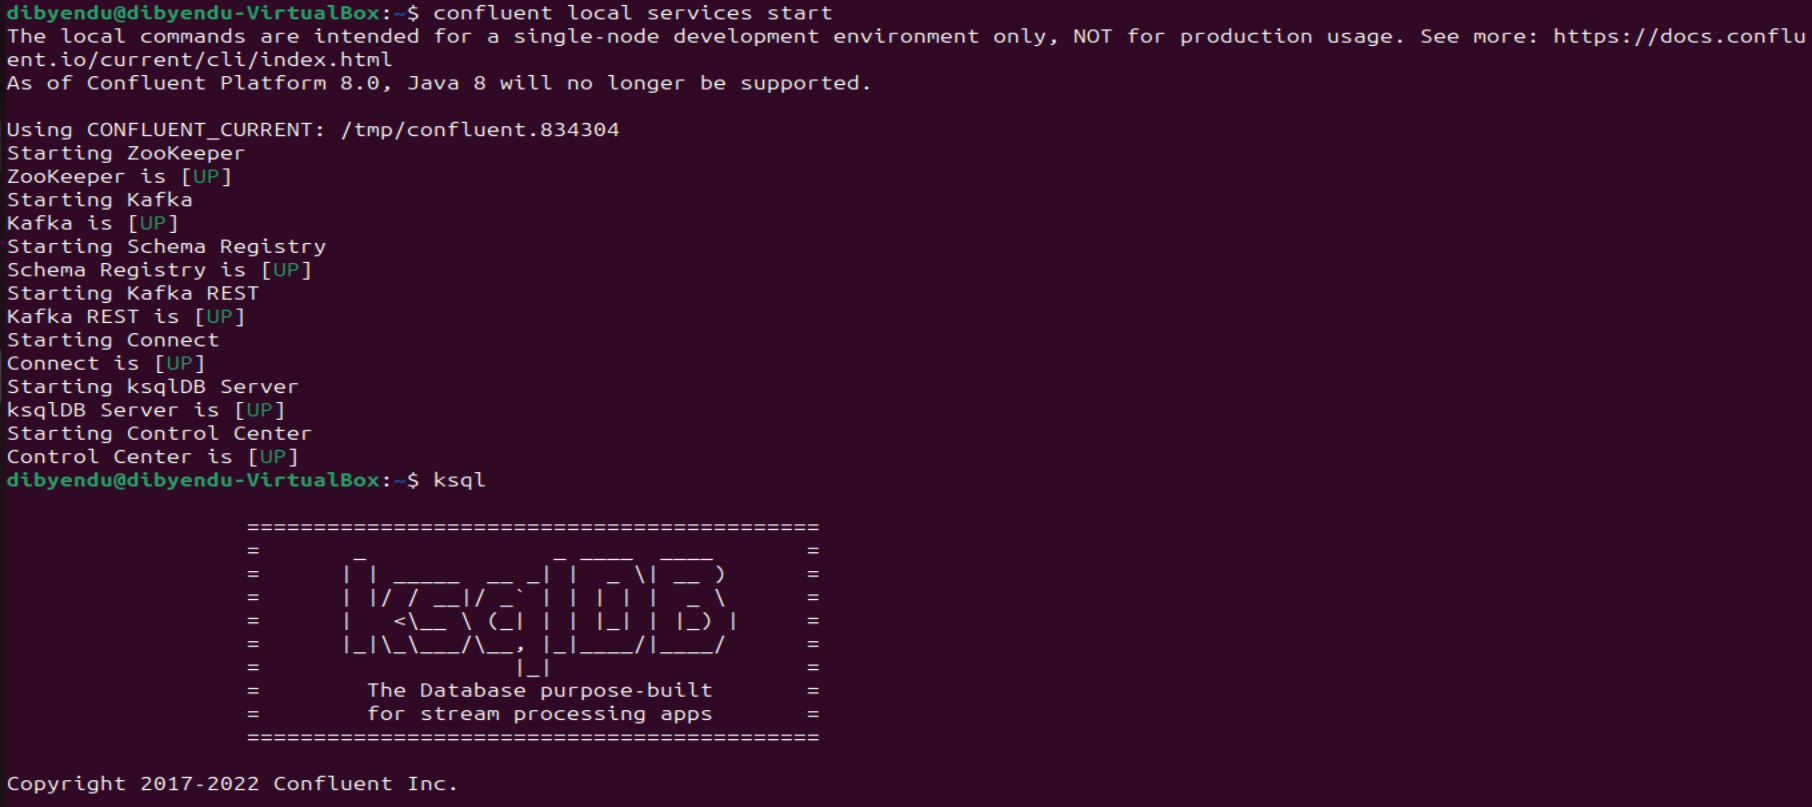
- Start the Confluent local services using the command:
confluent local services startThis starts all the Confluent Services like Zookeeper, Kafka, Schema Registry, Kafka REST, Kafka CONNECT, ksqlDB and Control Center. You are now ready to use the CData JDBC driver for BugHerd to stream messages using Kafka Connect Driver into Kafka Topics on ksqlDB.
- Create the Kafka topics manually using a POST HTTP API Request:
 curl --location 'server_address:8083/connectors'
	--header 'Content-Type: application/json'
	--data '{
		"name": "jdbc_source_cdata_api_01",
		"config": {
			"connector.class": "io.confluent.connect.jdbc.JdbcSourceConnector",
			"connection.url": "jdbc:api:Profile=C:\profiles\BugHerd.apip;AuthScheme=APIKey;ProfileSettings='APIKey=your_api_key';",
		"topic.prefix": "api-01-",
		"mode": "bulk"
		}
	}'
Let us understand the fields used in the HTTP POST body (shown above):
- connector.class: Specifies the Java class of the Kafka Connect connector to be used.
- connection.url: The JDBC connection URL to connect with BugHerd data.
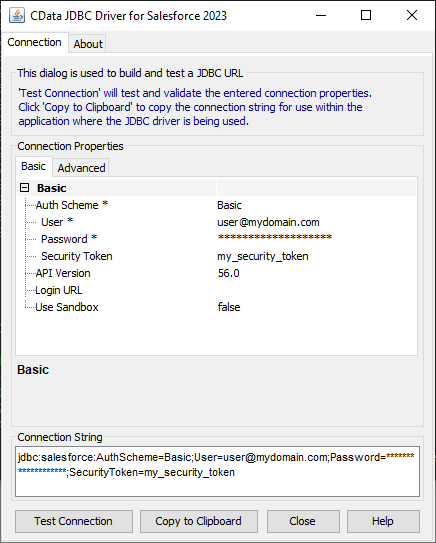
Built-in Connection String Designer
For assistance in constructing the JDBC URL, use the connection string designer built into the CData API Driver for JDBC. Either double-click the JAR file or execute the jar file from the command-line.
java -jar cdata.jdbc.api.jarFill in the connection properties and copy the connection string to the clipboard.
Start by setting the Profile connection property to the location of the BugHerd Profile on disk (e.g. C:\profiles\BugHerd.apip). Next, set the ProfileSettings connection property to the connection string for BugHerd (see below).
BugHerd API Profile Settings
BugHerd uses HTTP Basic authentication with an API key as the username. To obtain an API key:
- Sign in to your BugHerd account at https://www.bugherd.com
- Navigate to Settings > General Settings
- Locate the API Key section and copy the generated key
After obtaining your API key, set the following connection properties:
- AuthScheme: Set this to APIKey.
Set the following in the ProfileSettings connection property:
- APIKey: Set this to your BugHerd API key. The driver uses the key as the Basic auth username and sets the password internally to the literal value 'x' as required by BugHerd.
- topic.prefix: A prefix that will be added to the Kafka topics created by the connector. It's set to "api-01-".
- mode: Specifies the mode in which the connector operates. In this case, it's set to "bulk", which suggests that the connector is configured to perform bulk data transfer.
This request adds all the tables/contents from BugHerd as Kafka Topics.
Note: The IP Address (server) to POST the request (shown above) is the Linux Network IP Address.
- Run ksqlDB and list the topics. Use the commands:
ksql
list topics;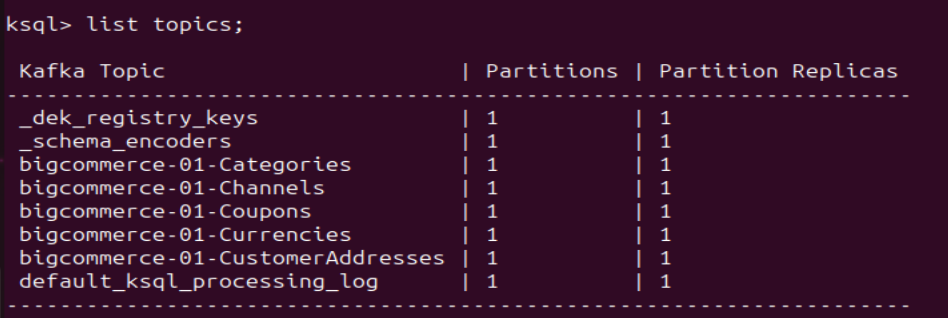
- To view the data inside the topics, type the SQL Statement:
PRINT topic FROM BEGINNING;
Connecting with the Confluent Control Center
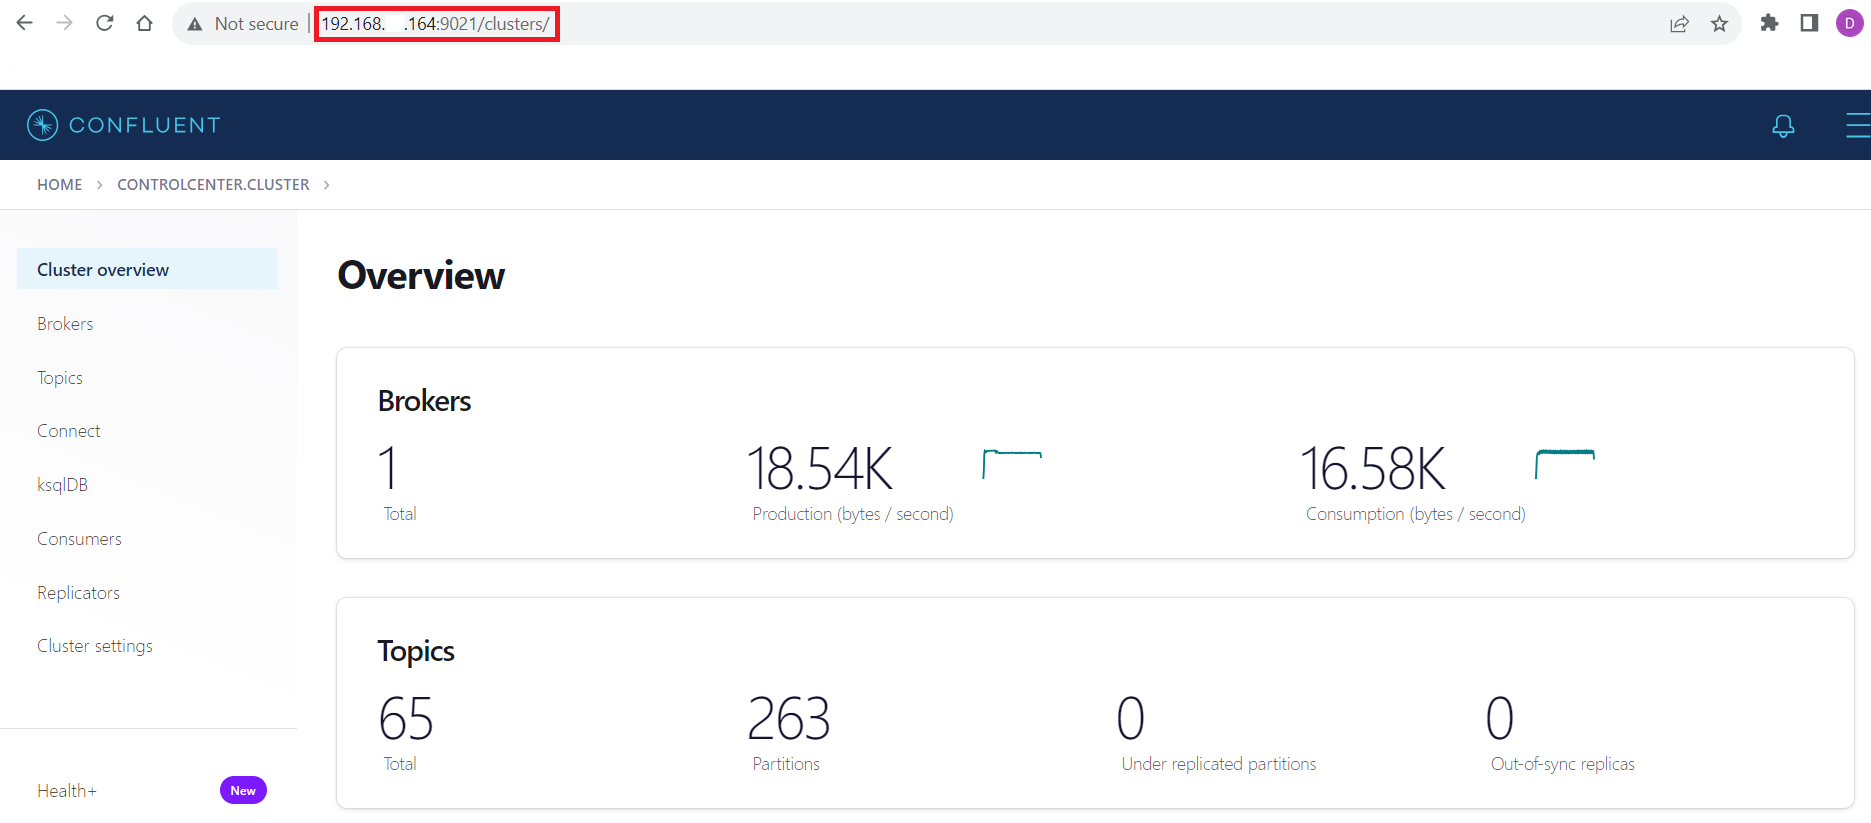
To access the Confluent Control Center user interface, ensure to run the "confluent local services" as described in the above section and type http://<server address>:9021/clusters/ on your local browser.
Get Started Today
Download a free, 30-day trial of the CData API Driver for JDBC and start streaming BugHerd data into Apache Kafka. Reach out to our Support Team if you have any questions.