

How to work with Buildkite Data in Apache Spark using SQL
Apache Spark is a fast and general engine for large-scale data processing. When paired with the CData JDBC Driver for Buildkite, Spark can work with live Buildkite data. This article describes how to connect to and query Buildkite data from a Spark shell.
The CData JDBC Driver offers unmatched performance for interacting with live Buildkite data due to optimized data processing built into the driver. When you issue complex SQL queries to Buildkite, the driver pushes supported SQL operations, like filters and aggregations, directly to Buildkite and utilizes the embedded SQL engine to process unsupported operations (often SQL functions and JOIN operations) client-side. With built-in dynamic metadata querying, you can work with and analyze Buildkite data using native data types.
Install the CData JDBC Driver for Buildkite
Download the CData JDBC Driver for Buildkite installer, unzip the package, and run the JAR file to install the driver.
Start a Spark Shell and Connect to Buildkite Data
- Open a terminal and start the Spark shell with the CData JDBC Driver for Buildkite JAR file as the jars parameter:
$ spark-shell --jars /CData/CData JDBC Driver for Buildkite/lib/cdata.jdbc.api.jar - With the shell running, you can connect to Buildkite with a JDBC URL and use the SQL Context load() function to read a table.
Start by setting the Profile connection property to the location of the Buildkite Profile on disk (e.g. C:\profiles\Buildkite.apip). Next, set the ProfileSettings connection property to the connection string for Buildkite (see below).
Buildkite API Profile Settings
Buildkite uses HTTP API key authentication. Your Buildkite API access token is used to authenticate requests as a Bearer token. You can generate or view your tokens at https://buildkite.com/user/api-access-tokens.
After setting the following connection properties, you are ready to connect:
- AuthScheme: Set this to APIKey.
- APIKey: Set this to your Buildkite API access token.
- Organization: Set this to your Buildkite organization slug (e.g. acme-inc).
Built-in Connection String Designer
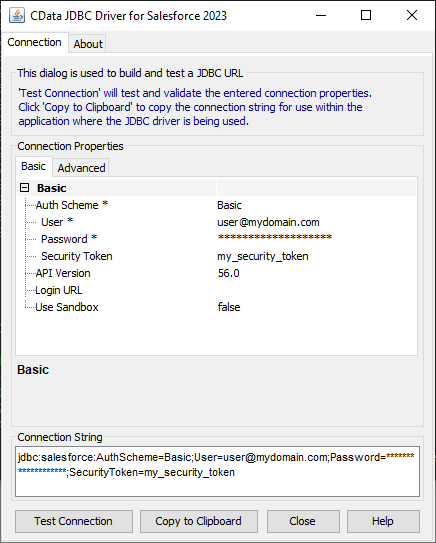
For assistance in constructing the JDBC URL, use the connection string designer built into the Buildkite JDBC Driver. Either double-click the JAR file or execute the jar file from the command-line.
java -jar cdata.jdbc.api.jarFill in the connection properties and copy the connection string to the clipboard.
Configure the connection to Buildkite, using the connection string generated above.
scala> val api_df = spark.sqlContext.read.format("jdbc").option("url", "jdbc:api:Profile=C:\profiles\Buildkite.apip;AuthScheme=APIKey;ProfileSettings='APIKey=your_api_key;Organization=your_organization_slug';").option("dbtable","Builds").option("driver","cdata.jdbc.api.APIDriver").load() - Once you connect and the data is loaded you will see the table schema displayed.
Register the Buildkite data as a temporary table:
scala> api_df.registerTable("builds")-
Perform custom SQL queries against the Data using commands like the one below:
scala> api_df.sqlContext.sql("SELECT Id, BuildNumber FROM Builds WHERE State = passed").collect.foreach(println)You will see the results displayed in the console, similar to the following:

Using the CData JDBC Driver for Buildkite in Apache Spark, you are able to perform fast and complex analytics on Buildkite data, combining the power and utility of Spark with your data. Download a free, 30 day trial of any of the hundreds of CData JDBC Drivers and get started today.