




Connect to Carbone Data in HULFT Integrate
HULFT Integrate is a modern data integration platform that provides a drag-and-drop user interface to create cooperation flows, data conversion, and processing so that complex data connections are easier than ever to execute. When paired with the CData API Driver for JDBC, HULFT Integrate can work with live Carbone data. This article explains how to connect to Carbone and move the data into a CSV file.
With built-in optimized data processing, the CData JDBC driver offers unmatched performance for interacting with live Carbone data. When you issue complex SQL queries to Carbone, the driver pushes supported SQL operations, like filters and aggregations, directly to Carbone and utilizes the embedded SQL engine to process unsupported operations client-side (often SQL functions and JOIN operations). Its built-in dynamic metadata querying allows you to work with and analyze Carbone data using native data types.
Enable Access to Carbone
To enable access to Carbone data from HULFT Integrate projects:
- Copy the CData JDBC Driver JAR file (and license file if it exists), cdata.jdbc.api.jar (and cdata.jdbc.api.lic), to the jdbc_adapter subfolder for the Integrate Server
- Restart the HULFT Integrate Server and launch HULFT Integrate Studio
Build a Project with Access to Carbone Data
Once you copy the JAR files, you can create a project with access to Carbone data. Start by opening Integrate Studio and creating a new project.
- Name the project
- Ensure the "Create script" checkbox is checked
- Click Next
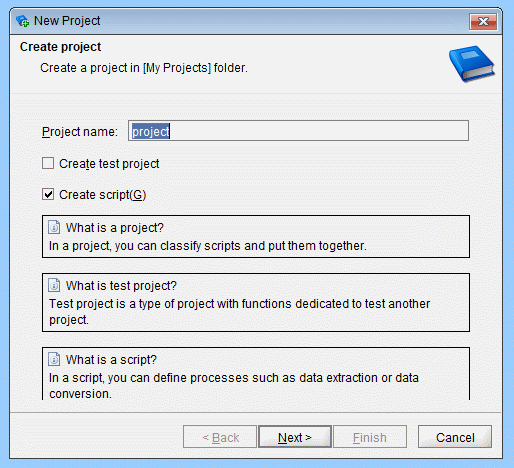
- Name the script (e.g.: APItoCSV)
Once you create the project, add components to the script to copy Carbone data to a CSV file.
Configure an Execute Select SQL Component
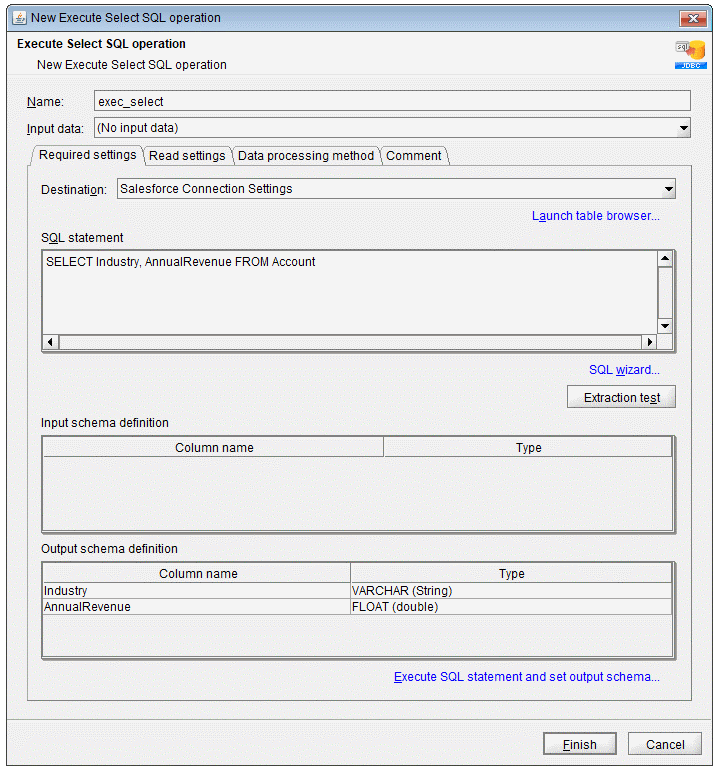
Drag an "Execute Select SQL" component from the Tool Palette (Database -> JDBC) into the Script workspace.
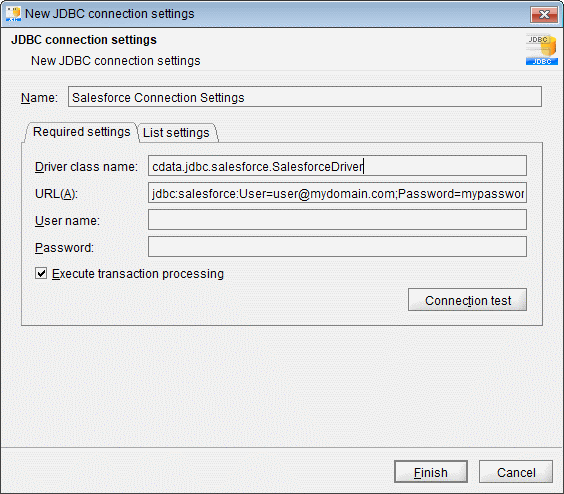
- In the "Required settings" tab for the Destination, click "Add" to create a new connection for Carbone. Set the following properties:
- Name: Carbone Connection Settings
- Driver class name: cdata.jdbc.api.APIDriver
- URL: jdbc:api:Profile=C:\profiles\Carbone.apip;AuthScheme=APIKey;APIKey=your_api_key;
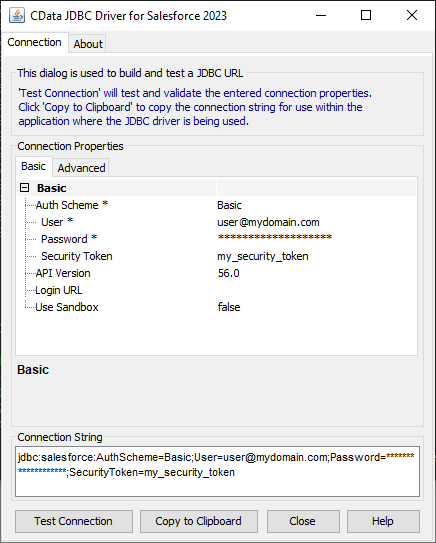
Built-in Connection String Designer
For assistance constructing the JDBC URL, use the connection string designer built into the Carbone JDBC Driver. Either double-click the JAR file or execute the JAR file from the command-line.
java -jar cdata.jdbc.api.jarFill in the connection properties and copy the connection string to the clipboard.
Start by setting the Profile connection property to the location of the Carbone Profile on disk (e.g. C:\profiles\Carbone.apip). Next, set the ProfileSettings connection property to the connection string for Carbone (see below).
Carbone API Profile Settings
Carbone uses API key authentication via a Bearer token in the Authorization header. To obtain an API key:
- Log in to your Carbone account at https://account.carbone.io
- Copy the API key shown on the account home page
After obtaining your API key, set the following connection properties:
- AuthScheme: Set this to APIKey.
- APIKey: Set this to your Carbone API key (Bearer token).
- CarboneVersion: (Optional) The major version of the Carbone API to target via the carbone-version request header. Defaults to 5. Accepted values: 5, 4, 3, staging.
- Write your SQL statement. For example:
SELECT Id, Name FROM Templates
- Click "Extraction test" to ensure the connection and query are configured properly
- Click "Execute SQL statement and set output schema"
- Click "Finish"
Configure a Write CSV File Component
Drag a "Write CSV File" component from the Tool Palette (File -> CSV) onto the workspace.
- Set a file to write the query results to (e.g. Templates.csv)
- Set "Input data" to the "Select SQL" component
- Add columns for each field selected in the SQL query
- In the "Write settings" tab, check the checkbox to "Insert column names into first row"
- Click "Finish"
Map Carbone Fields to the CSV Columns
Map each column from the "Select" component to the corresponding column for the "CSV" component.
Finish the Script
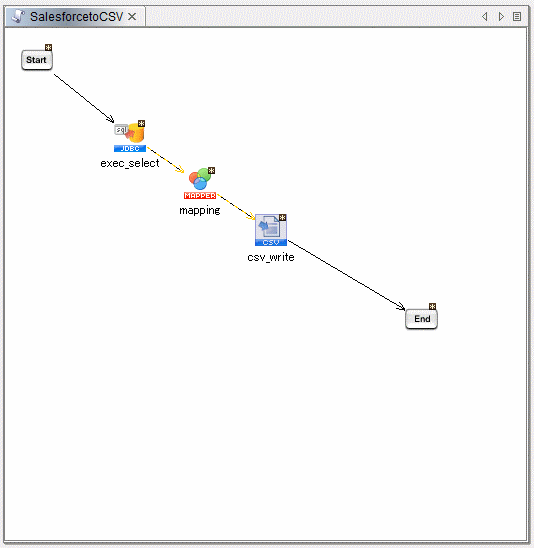
Drag the "Start" component onto the "Select" component and the "CSV" component onto the "End" component. Build the script and run the script to move Carbone data into a CSV file.
Download a free, 30-day trial of the CData API Driver for JDBC and start working with your live Carbone data in HULFT Integrate. Reach out to our Support Team if you have any questions.