


Build Pipelines with Live Bitbucket Data in Google Cloud Data Fusion (via CData Connect AI)

Google Cloud Data Fusion simplifies building and managing data pipelines by offering a visual interface to connect, transform, and move data across various sources and destinations, streamlining data integration processes. When combined with CData Connect AI, it provides access to Bitbucket data for building and managing ELT/ETL data pipelines. This article explains how to use CData Connect AI to create a live connection to Bitbucket and how to connect and access live Bitbucket data from the Cloud Data Fusion platform.
Configure Bitbucket Connectivity for Cloud Data Fusion
Connectivity to Bitbucket from Cloud Data Fusion is made possible through CData Connect AI. To work with Bitbucket data from Cloud Data Fusion, we start by creating and configuring a Bitbucket connection.
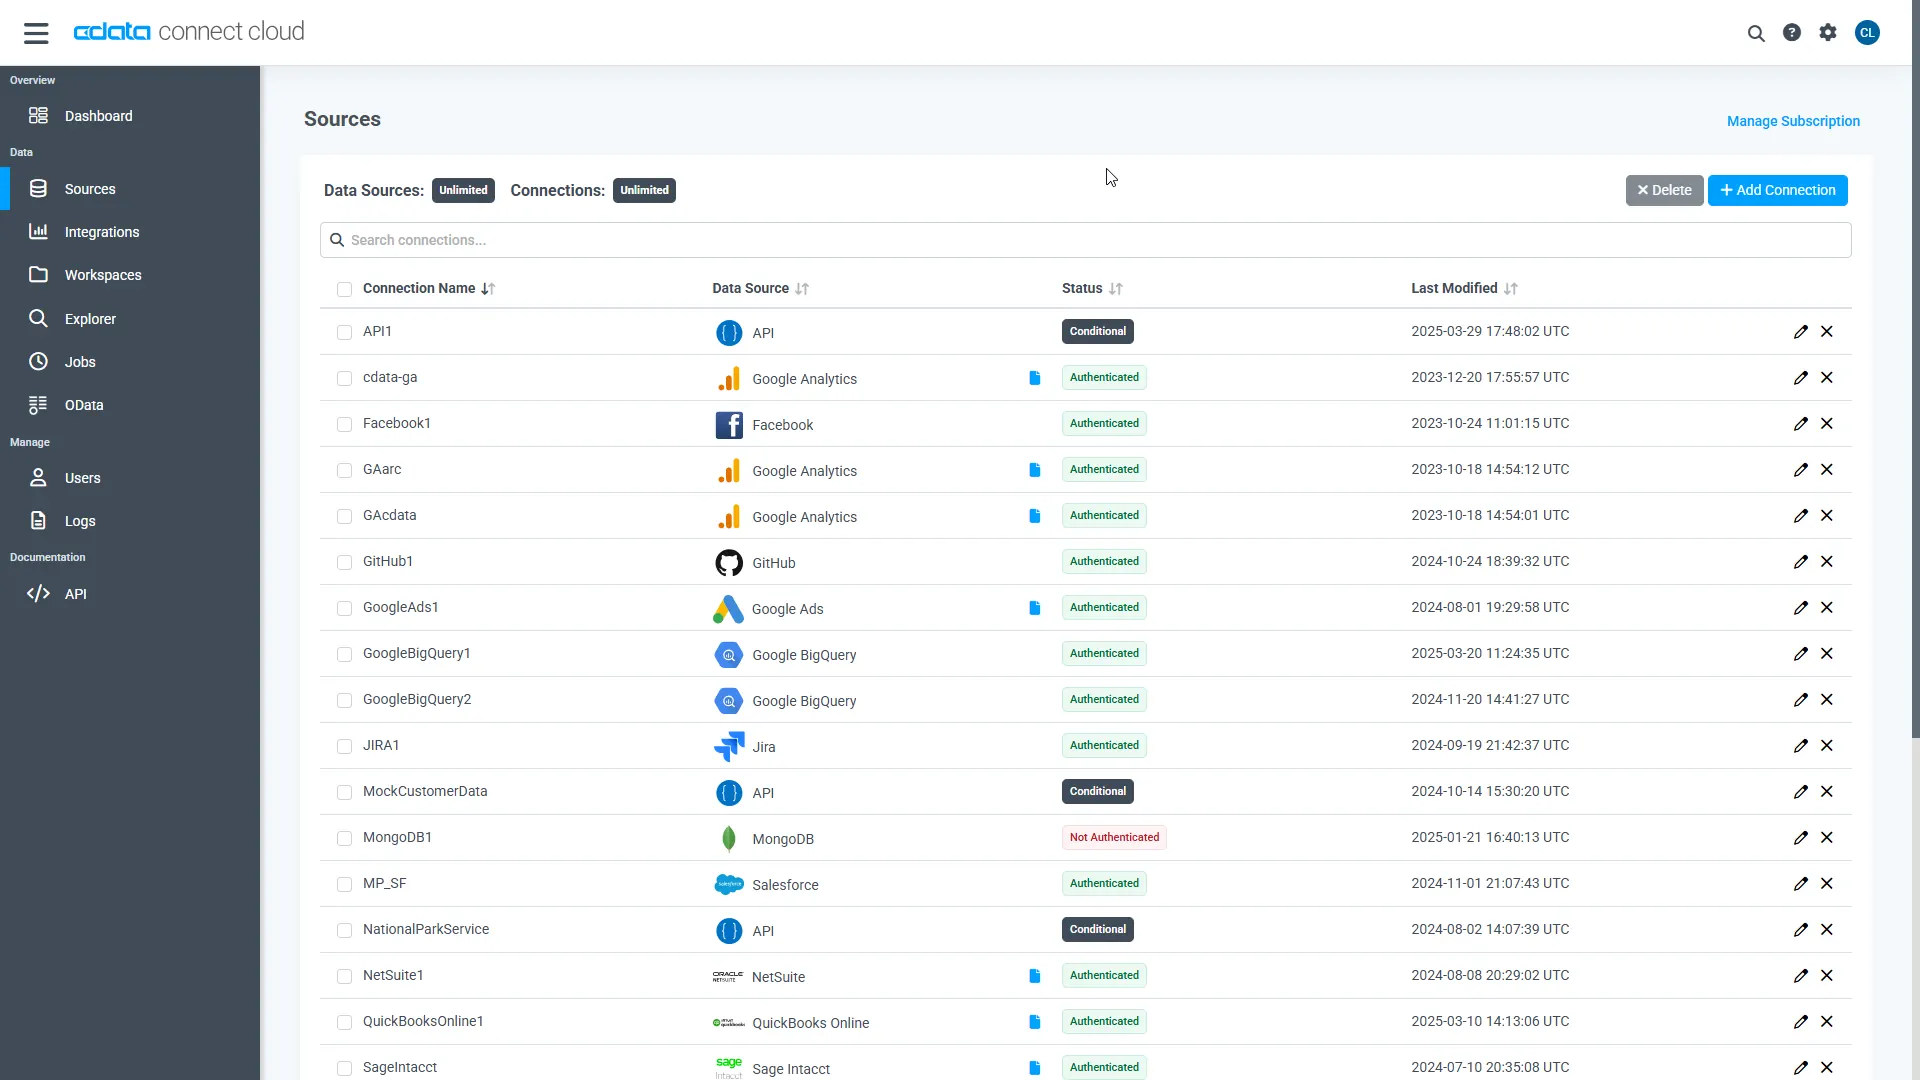
- Log into Connect AI, click Sources, and then click Add Connection
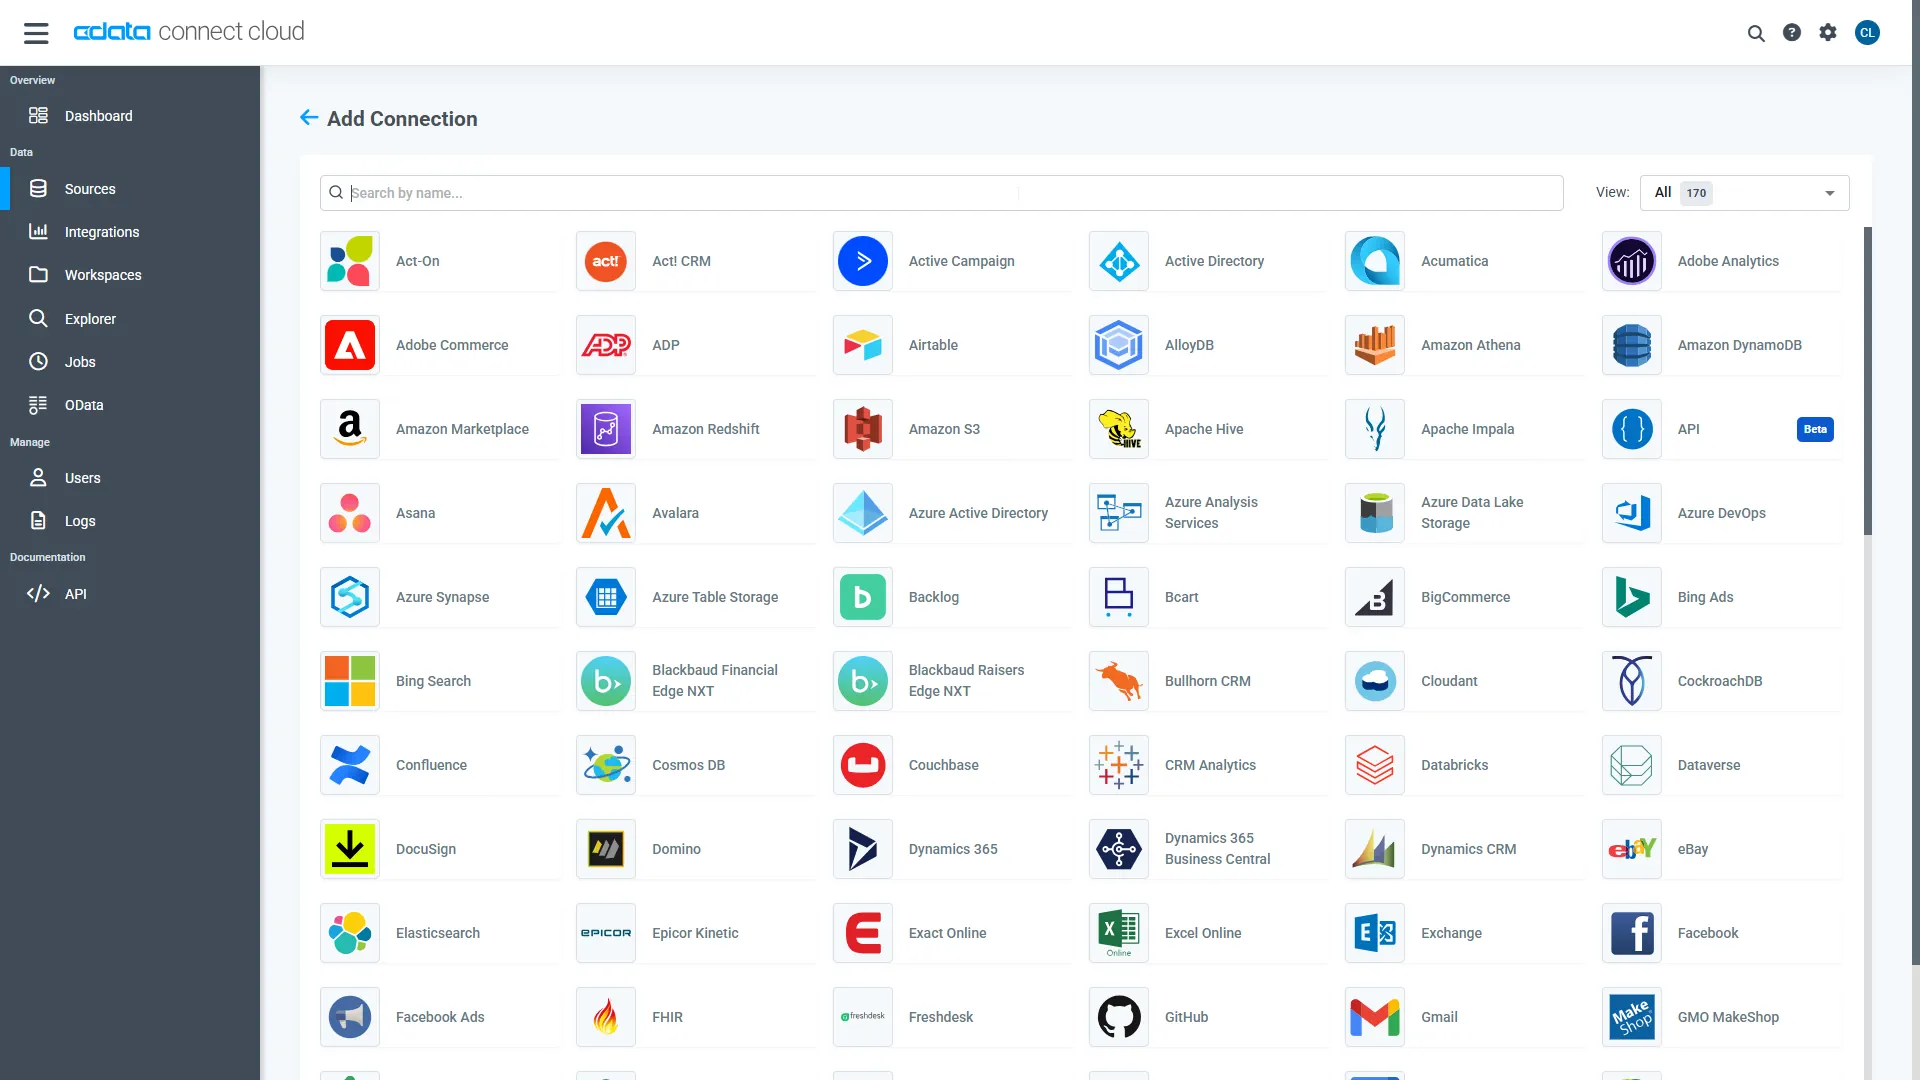
- Select "Bitbucket" from the Add Connection panel
-
Enter the necessary authentication properties to connect to Bitbucket.
For most queries, you must set the Workspace. The only exception to this is the Workspaces table, which does not require this property to be set, as querying it provides a list of workspace slugs that can be used to set Workspace. To query this table, you must set Schema to 'Information' and execute the query SELECT * FROM Workspaces>.
Setting Schema to 'Information' displays general information. To connect to Bitbucket, set these parameters:
- Schema: To show general information about a workspace, such as its users, repositories, and projects, set this to Information. Otherwise, set this to the schema of the repository or project you are querying. To get a full set of available schemas, query the sys_schemas table.
- Workspace: Required if you are not querying the Workspaces table. This property is not required for querying the Workspaces table, as that query only returns a list of workspace slugs that can be used to set Workspace.
Authenticating to Bitbucket
Bitbucket supports OAuth authentication only. To enable this authentication from all OAuth flows, you must create a custom OAuth application, and set AuthScheme to OAuth.
Be sure to review the Help documentation for the required connection properties for you specific authentication needs (desktop applications, web applications, and headless machines).
Creating a custom OAuth application
From your Bitbucket account:
- Go to Settings (the gear icon) and select Workspace Settings.
- In the Apps and Features section, select OAuth Consumers.
- Click Add Consumer.
- Enter a name and description for your custom application.
- Set the callback URL:
- For desktop applications and headless machines, use http://localhost:33333 or another port number of your choice. The URI you set here becomes the CallbackURL property.
- For web applications, set the callback URL to a trusted redirect URL. This URL is the web location the user returns to with the token that verifies that your application has been granted access.
- If you plan to use client credentials to authenticate, you must select This is a private consumer. In the driver, you must set AuthScheme to client.
- Select which permissions to give your OAuth application. These determine what data you can read and write with it.
- To save the new custom application, click Save.
- After the application has been saved, you can select it to view its settings. The application's Key and Secret are displayed. Record these for future use. You will use the Key to set the OAuthClientId and the Secret to set the OAuthClientSecret.
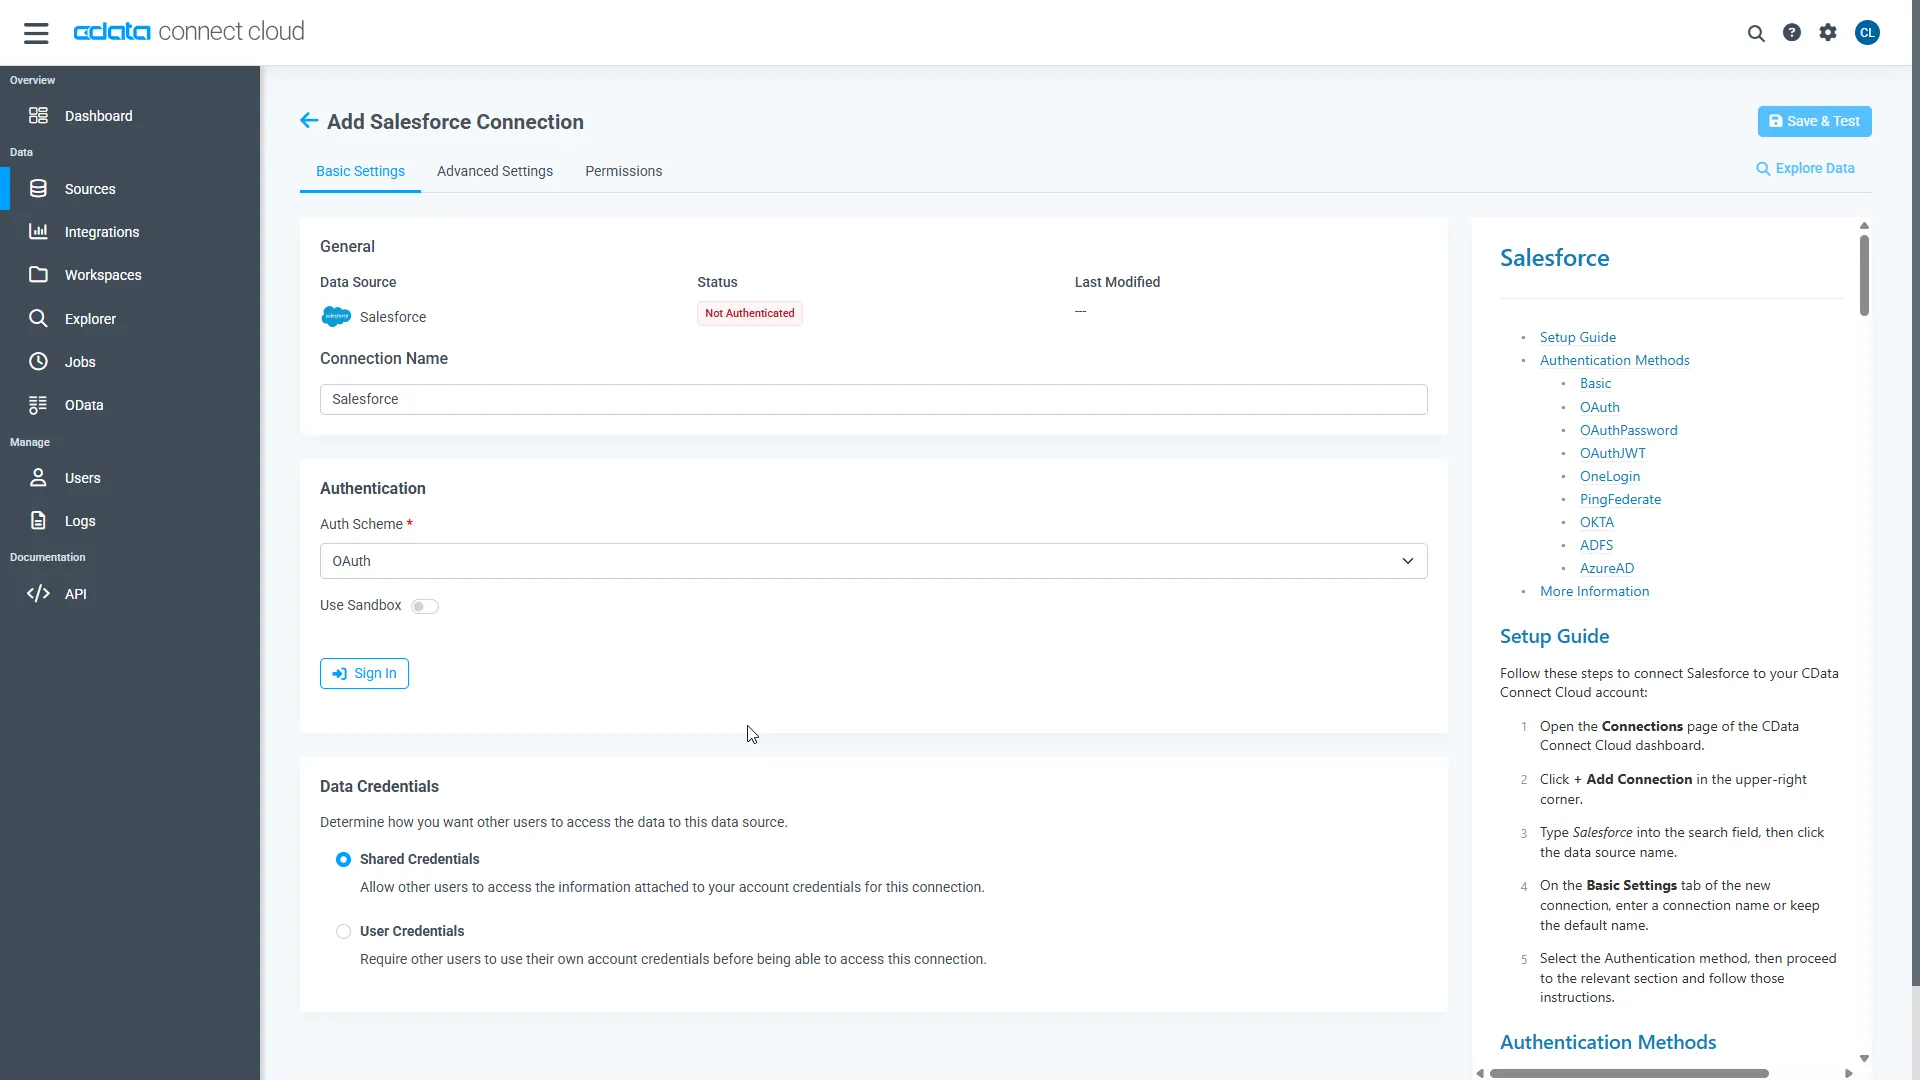
- Click Save & Test
-
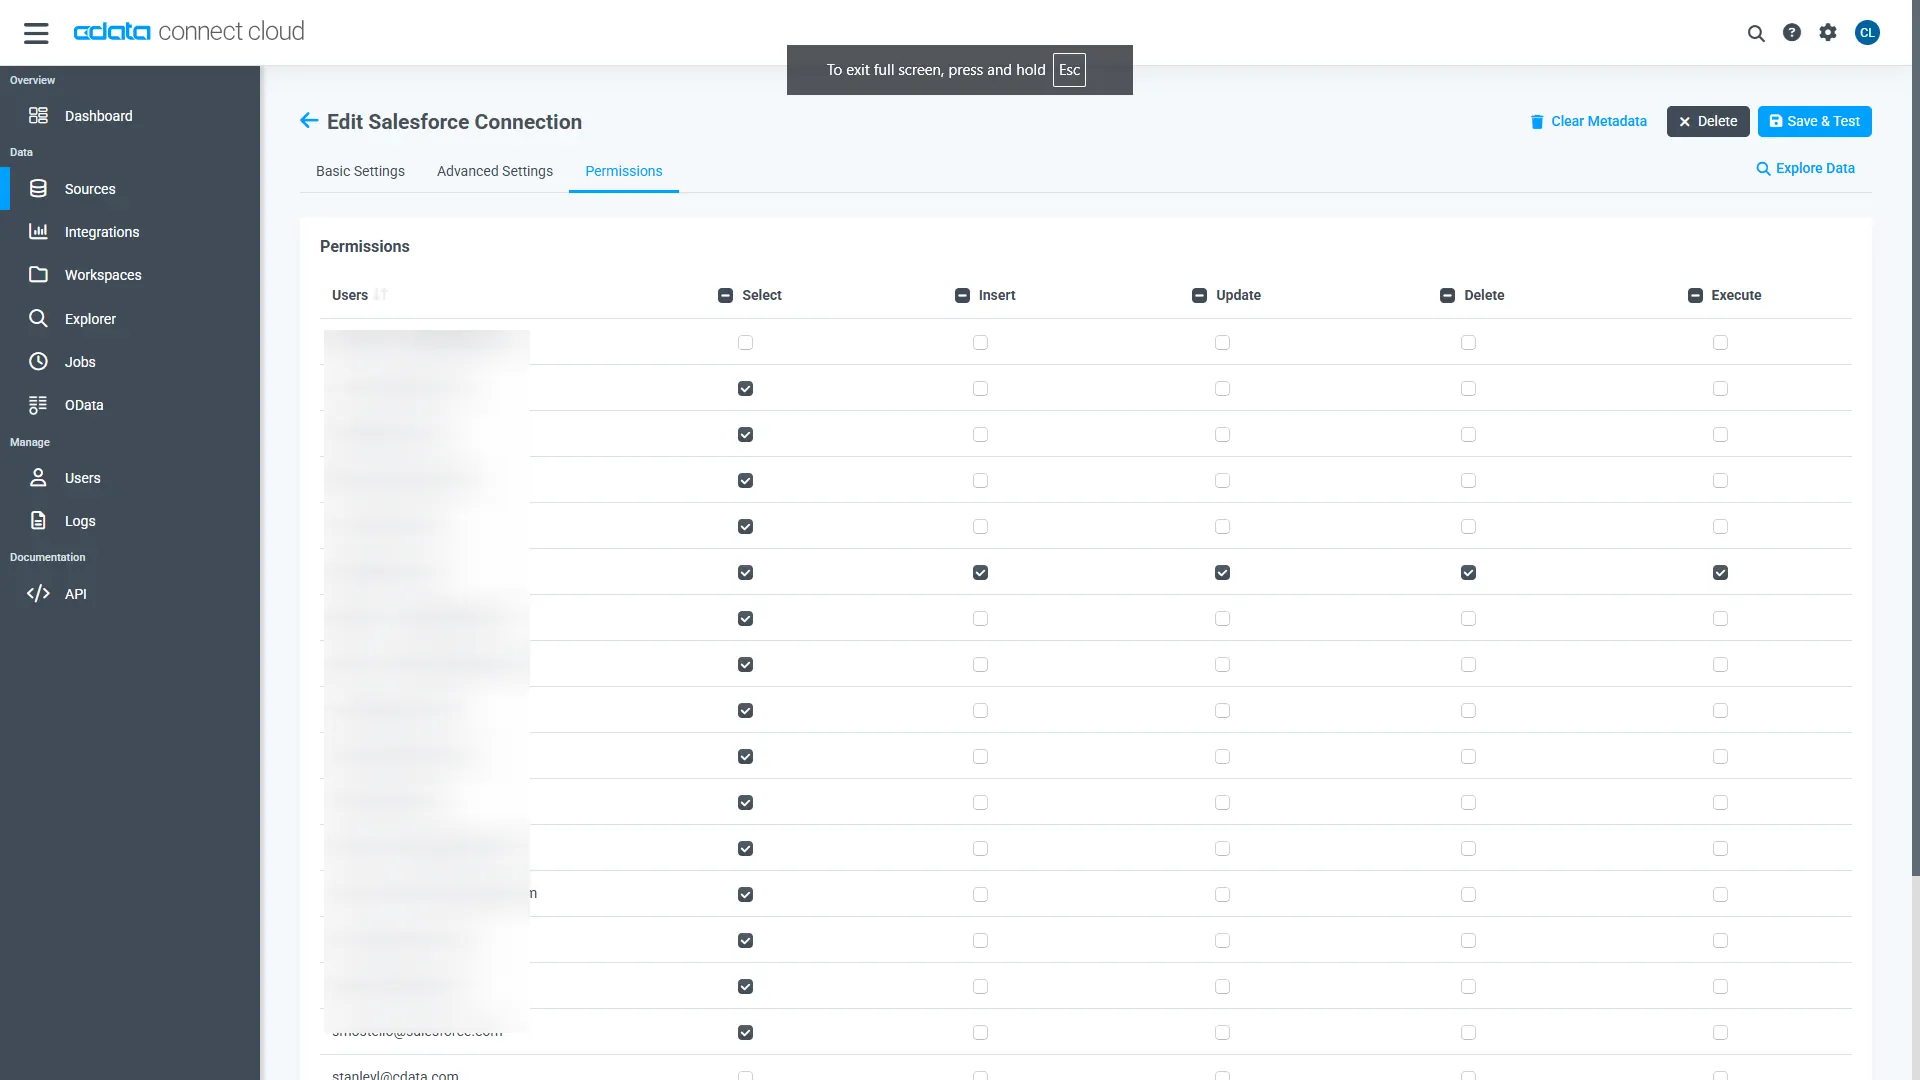
Navigate to the Permissions tab in the Add Bitbucket Connection page and update the User-based permissions.
Add a Personal Access Token
When connecting to Connect AI through the REST API, the OData API, or the Virtual SQL Server, a Personal Access Token (PAT) is used to authenticate the connection to Connect AI. It is best practice to create a separate PAT for each service to maintain granularity of access.
- Click on the Gear icon () at the top right of the Connect AI app to open the settings page.
- On the Settings page, go to the Access Tokens section and click Create PAT.
-
Give the PAT a name and click Create.
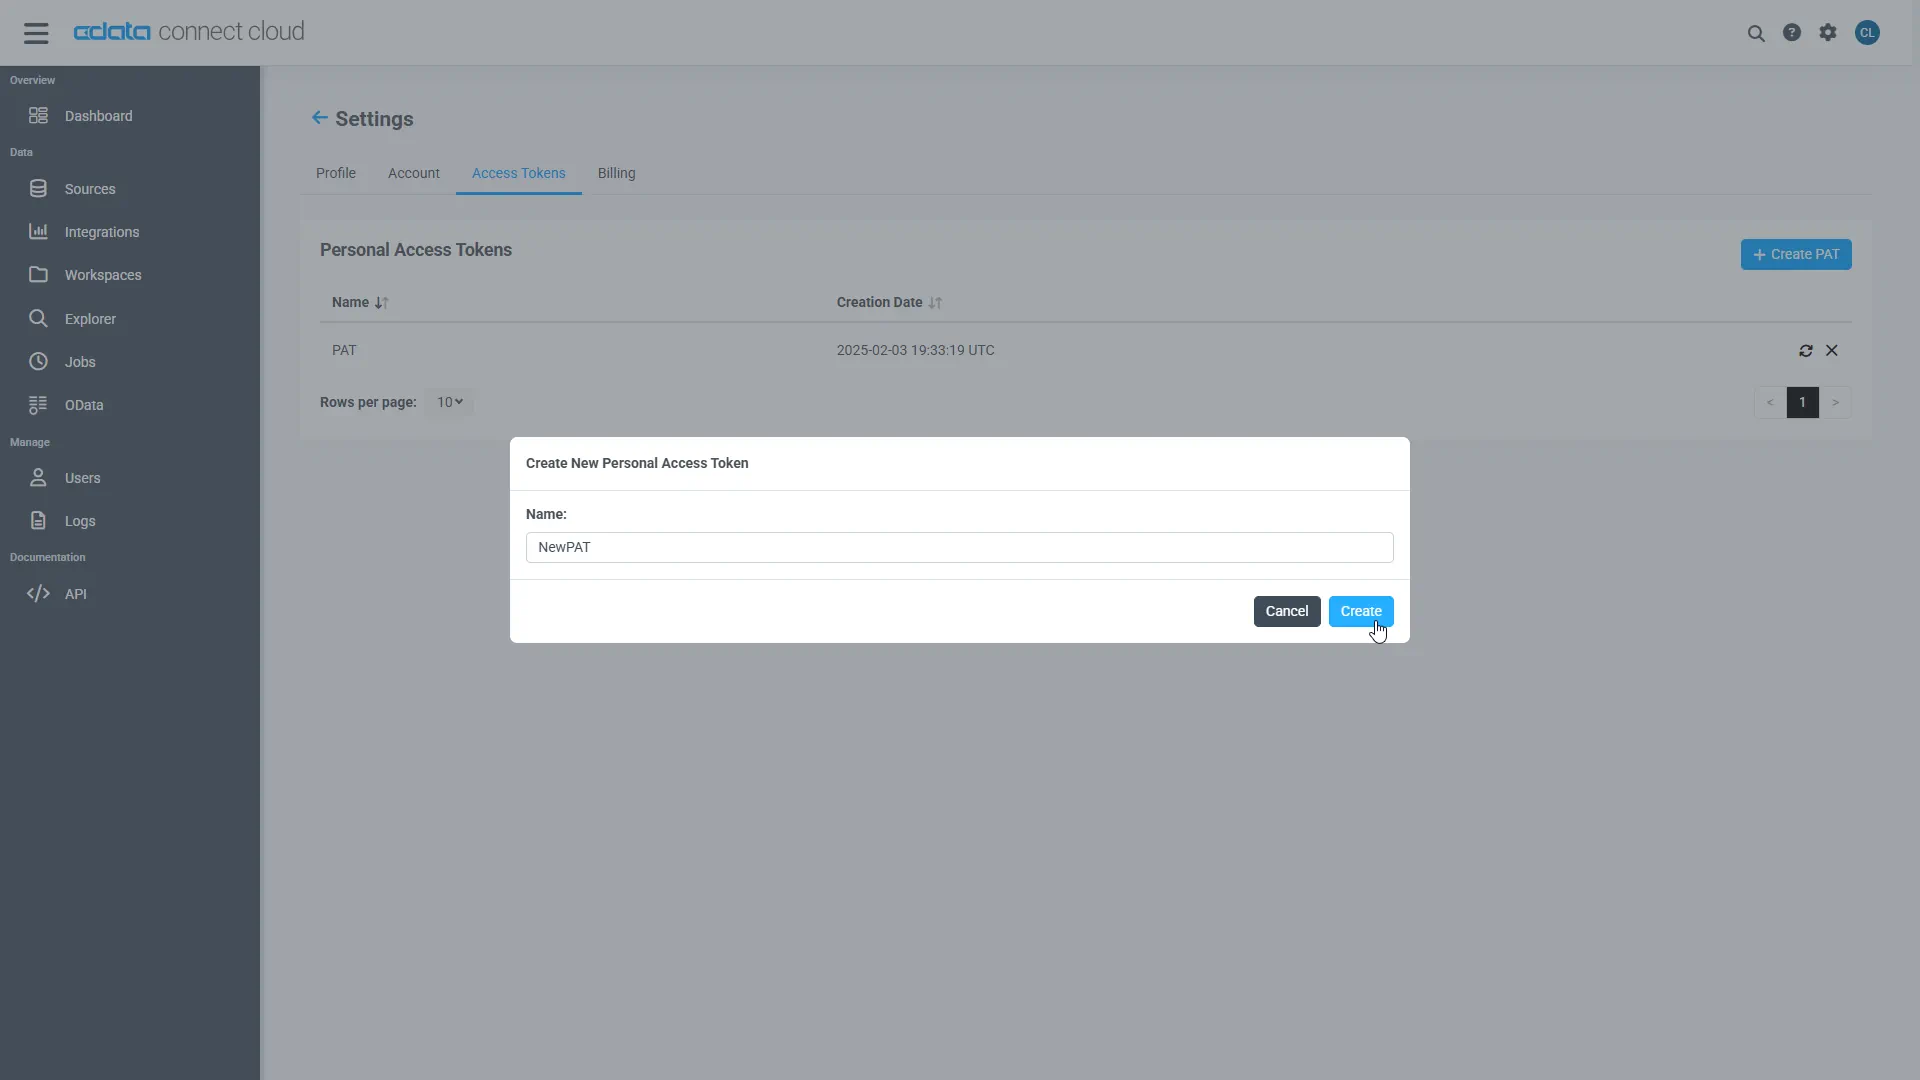
- The personal access token is only visible at creation, so be sure to copy it and store it securely for future use.
With the connection configured and a PAT generated, you are ready to connect to Bitbucket data from Cloud Data Fusion.
Connecting to Bitbucket from Cloud Data Fusion
Follow these steps to establish a connection from Cloud Data Fusion to Bitbucket through the CData Connect AI JDBC driver:
- Download and install the CData Connect AI JDBC driver:
- Open the Integrations page of CData Connect AI.
- Search for and select JDBC.
- Download and run the setup file.
- When the installation is complete, copy the JAR file(cdata.jdbc.connect.jar) from the installation directory (e.g., C:\Program Files\CData\JDBC Driver for CData Connect\lib).
- Log into Cloud Data Fusion.
- Click the green "+" button at the top right to add an entity.
- Under Driver, click Upload.
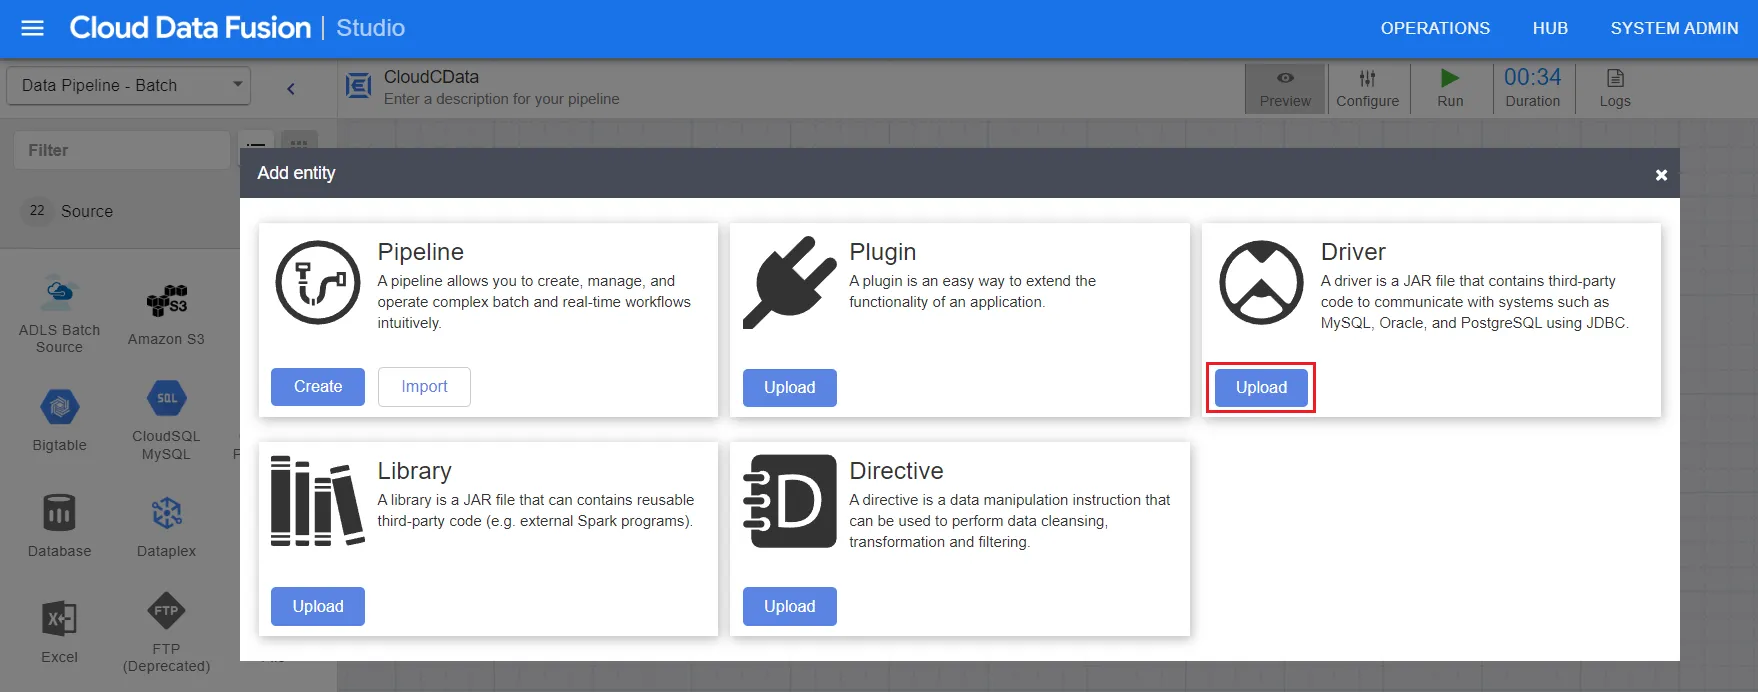
- Now, upload the CData Connect AI JDBC driver (JAR file).
- Enter the driver settings:
- Name: Enter the name of the driver
- Class name: Enter "cdata.jdbc.connect.ConnectDriver"
- Version: Enter the driver version
- Description (optional): Enter a description for the driver
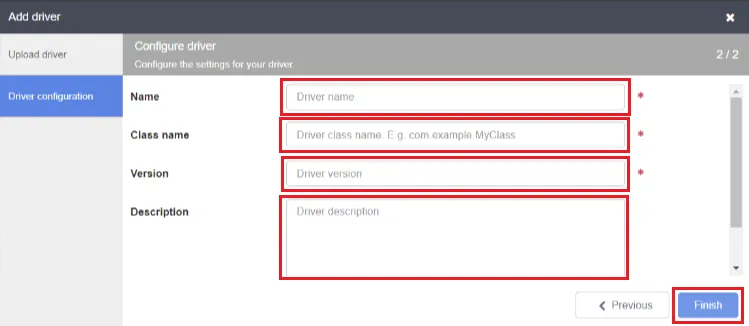
- Click on Finish.
- Enter source configuration settings:
- Label: Helps to identify the connection
- JDBC driver name: Enter the JDBC driver name to identify the driver configured in Step 6.
- Connection string: Enter the JDBC connection string, for example:
jdbc:connect:AuthScheme=Basic;user=username;password=PAT; - User: Enter your CData Connect AI username, displayed in the top-right corner of the CData Connect AI interface. For example, "[email protected]"
- Password: Enter the PAT you generated on the Settings page.
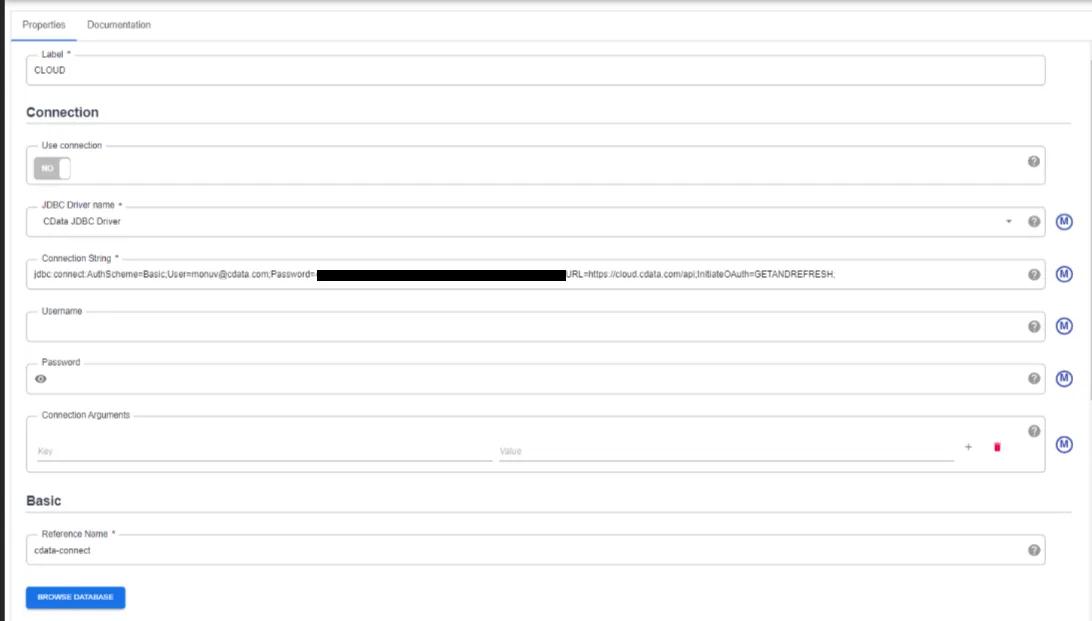
- Click Validate in the top right corner.
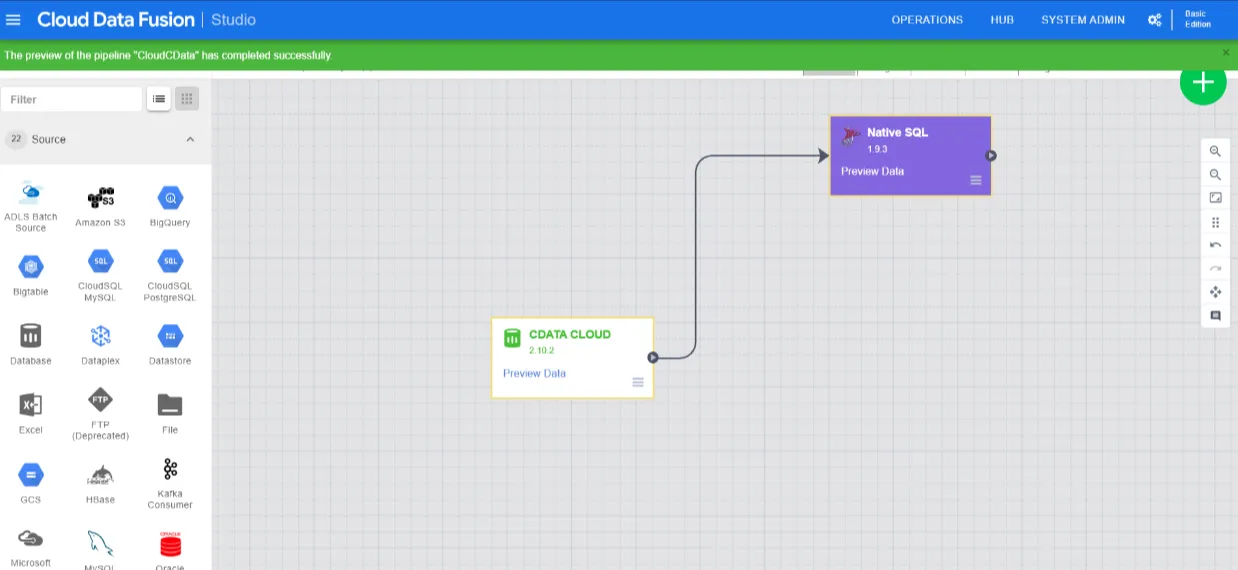
- If the connection is successful, you can manage the pipeline by editing it through the UI.
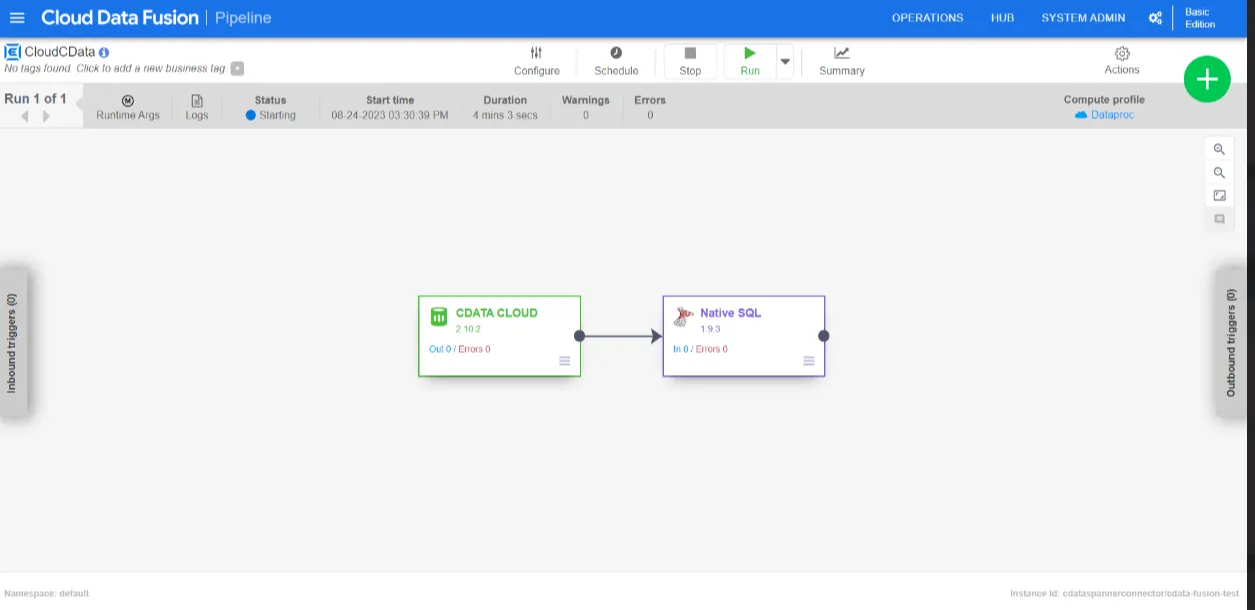
- Run the pipepline created.
Troubleshooting
Please be aware that there is a known issue in Cloud Data Fusion where "int" types from source data are automatically cast as "long".
Live Access to Bitbucket Data from Cloud Applications
Now you have a direct connection to live Bitbucket data from from Google Cloud Data Fusion. You can create more connections to ensure a smooth movement of data across various sources and destinations, thereby streamlining data integration processes - all without replicating Bitbucket data.
To get real-time data access to hundreds of SaaS, Big Data, and NoSQL sources (including Bitbucket) directly from your cloud applications, explore the CData Connect AI.