


Integrating LlamaIndex with Bitbucket Data via CData Connect AI
LlamaIndex is a data framework for building LLM applications — agents, RAG pipelines, and structured workflows that reason over external data. By integrating LlamaIndex with CData Connect AI through the built-in MCP Server, your agents can discover and query live Bitbucket data as native tools without writing custom connectors.
CData Connect AI offers a secure, low-code environment to connect Bitbucket and other data sources, removing the need for complex ETL and enabling seamless automation across business applications with live data.
This article outlines how to configure Bitbucket connectivity in CData Connect AI, register the MCP server with LlamaIndex, and build a ReAct agent that queries Bitbucket data in real time.
Prerequisites
- An account in CData Connect AI
- Python version 3.10 or higher, to install the LlamaIndex packages
- Generate and save an OpenAI API key
- Install Visual Studio Code in your system
Step 1: Configure Bitbucket Connectivity for LlamaIndex
Before LlamaIndex can access Bitbucket, a Bitbucket connection must be created in CData Connect AI. This connection is then exposed to LlamaIndex through the remote MCP server.
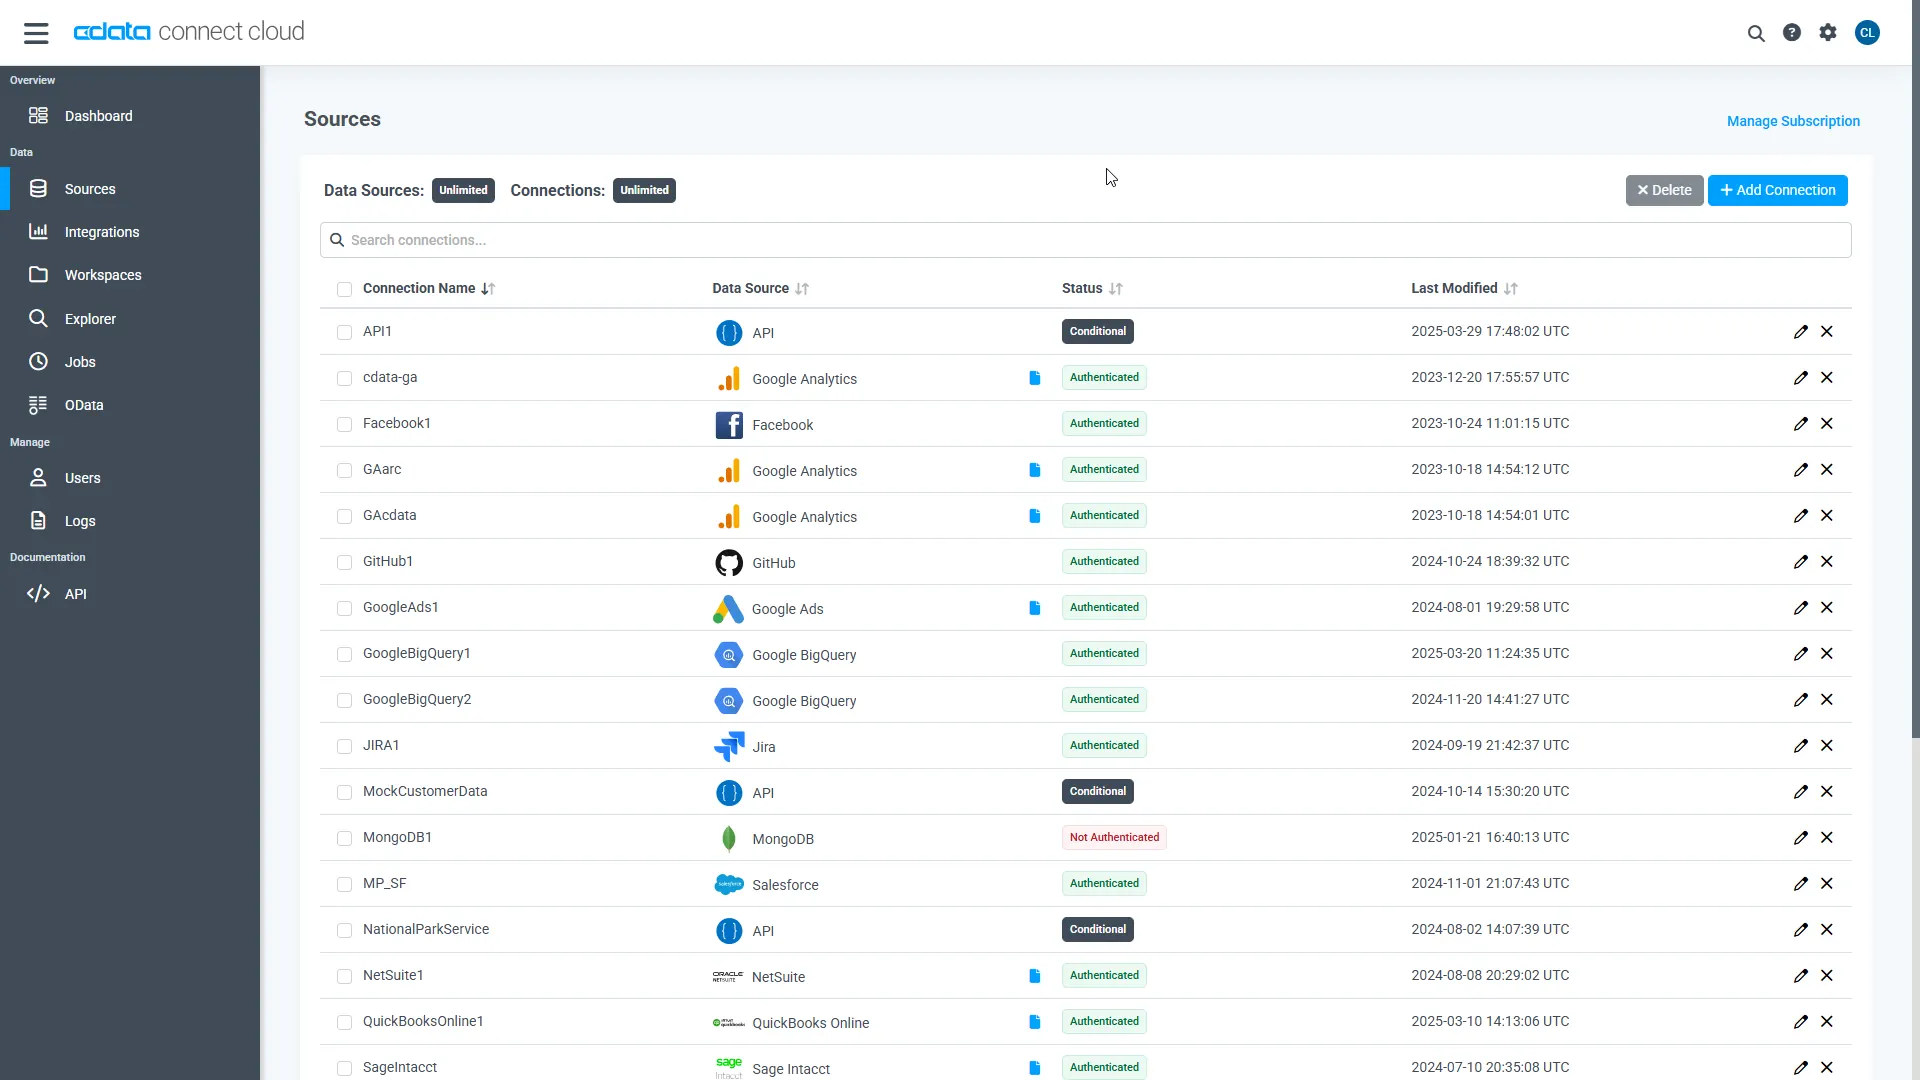
- Log in to Connect AI, click Sources, and then click + Add Connection
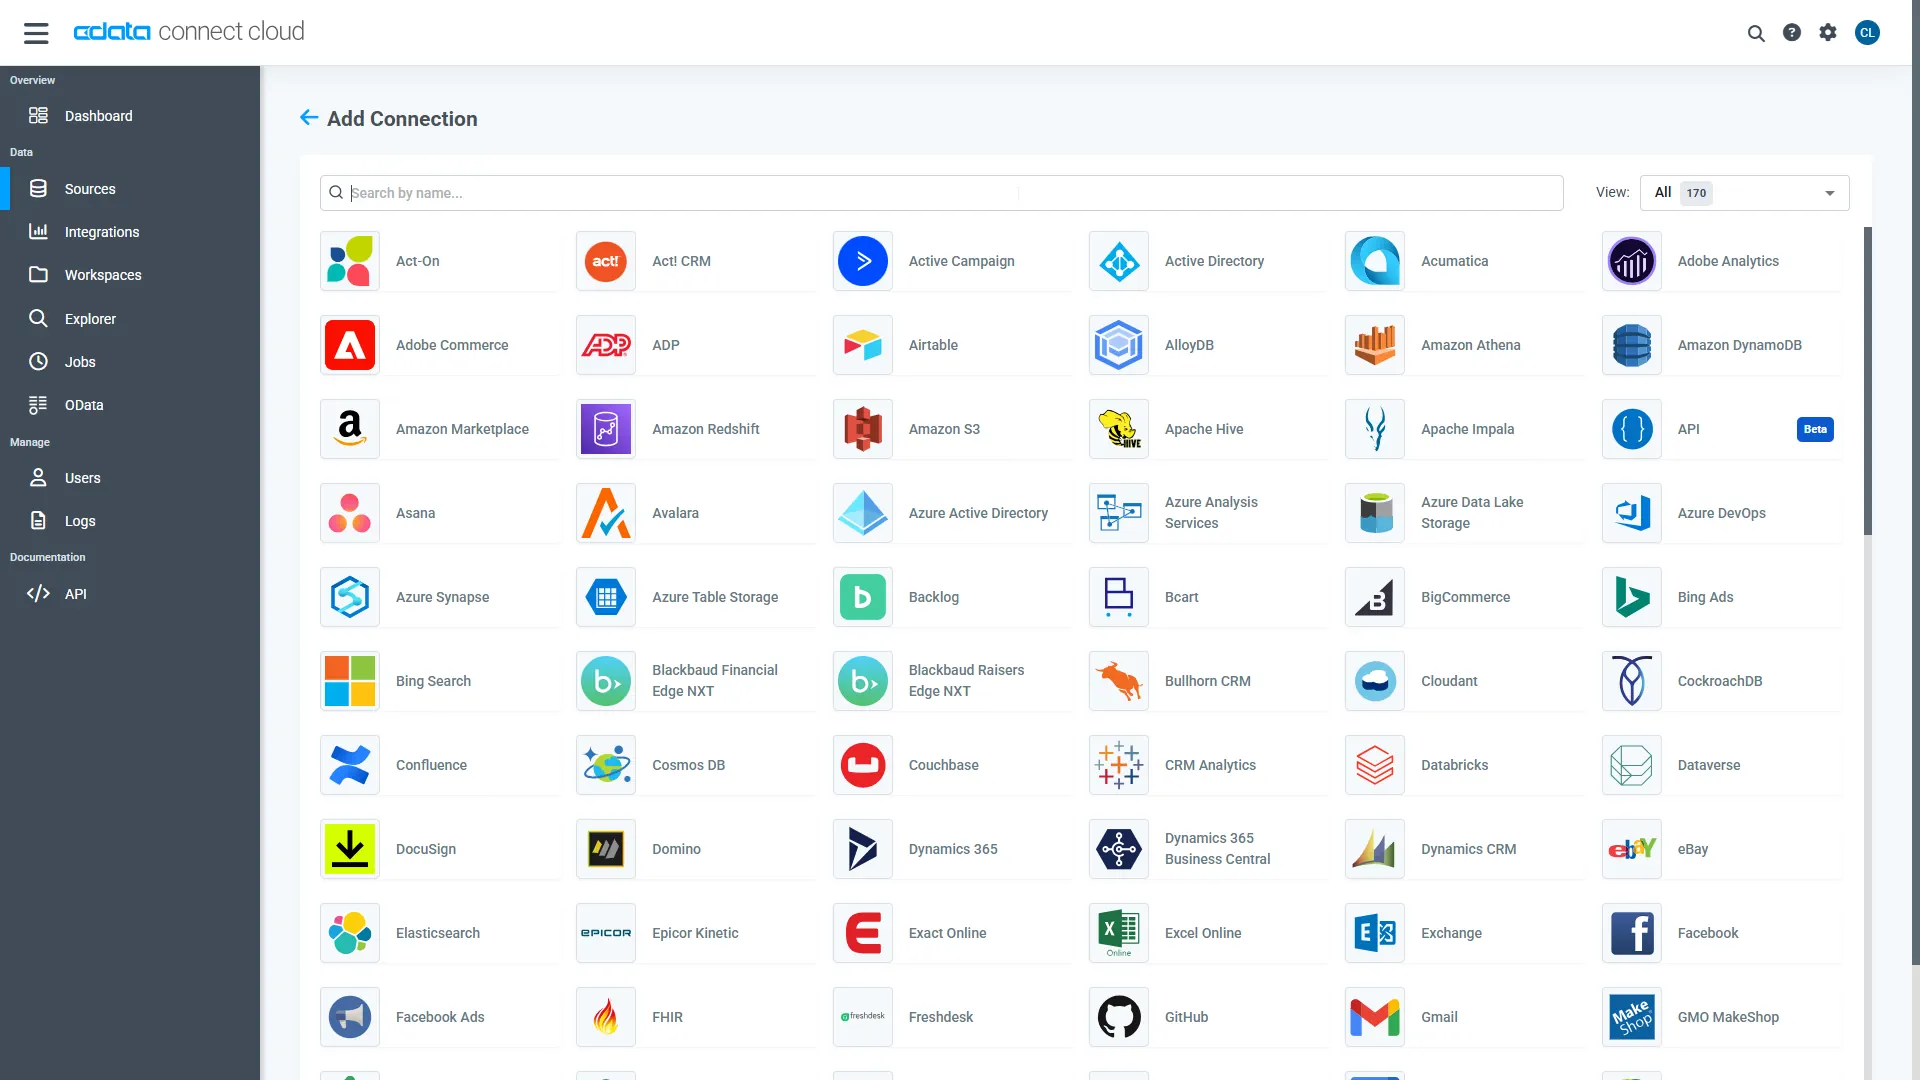
- From the available data sources, choose Bitbucket
-
Enter the necessary authentication properties to connect to Bitbucket
For most queries, you must set the Workspace. The only exception to this is the Workspaces table, which does not require this property to be set, as querying it provides a list of workspace slugs that can be used to set Workspace. To query this table, you must set Schema to 'Information' and execute the query SELECT * FROM Workspaces>.
Setting Schema to 'Information' displays general information. To connect to Bitbucket, set these parameters:
- Schema: To show general information about a workspace, such as its users, repositories, and projects, set this to Information. Otherwise, set this to the schema of the repository or project you are querying. To get a full set of available schemas, query the sys_schemas table.
- Workspace: Required if you are not querying the Workspaces table. This property is not required for querying the Workspaces table, as that query only returns a list of workspace slugs that can be used to set Workspace.
Authenticating to Bitbucket
Bitbucket supports OAuth authentication only. To enable this authentication from all OAuth flows, you must create a custom OAuth application, and set AuthScheme to OAuth.
Be sure to review the Help documentation for the required connection properties for you specific authentication needs (desktop applications, web applications, and headless machines).
Creating a custom OAuth application
From your Bitbucket account:
- Go to Settings (the gear icon) and select Workspace Settings.
- In the Apps and Features section, select OAuth Consumers.
- Click Add Consumer.
- Enter a name and description for your custom application.
- Set the callback URL:
- For desktop applications and headless machines, use http://localhost:33333 or another port number of your choice. The URI you set here becomes the CallbackURL property.
- For web applications, set the callback URL to a trusted redirect URL. This URL is the web location the user returns to with the token that verifies that your application has been granted access.
- If you plan to use client credentials to authenticate, you must select This is a private consumer. In the driver, you must set AuthScheme to client.
- Select which permissions to give your OAuth application. These determine what data you can read and write with it.
- To save the new custom application, click Save.
- After the application has been saved, you can select it to view its settings. The application's Key and Secret are displayed. Record these for future use. You will use the Key to set the OAuthClientId and the Secret to set the OAuthClientSecret.
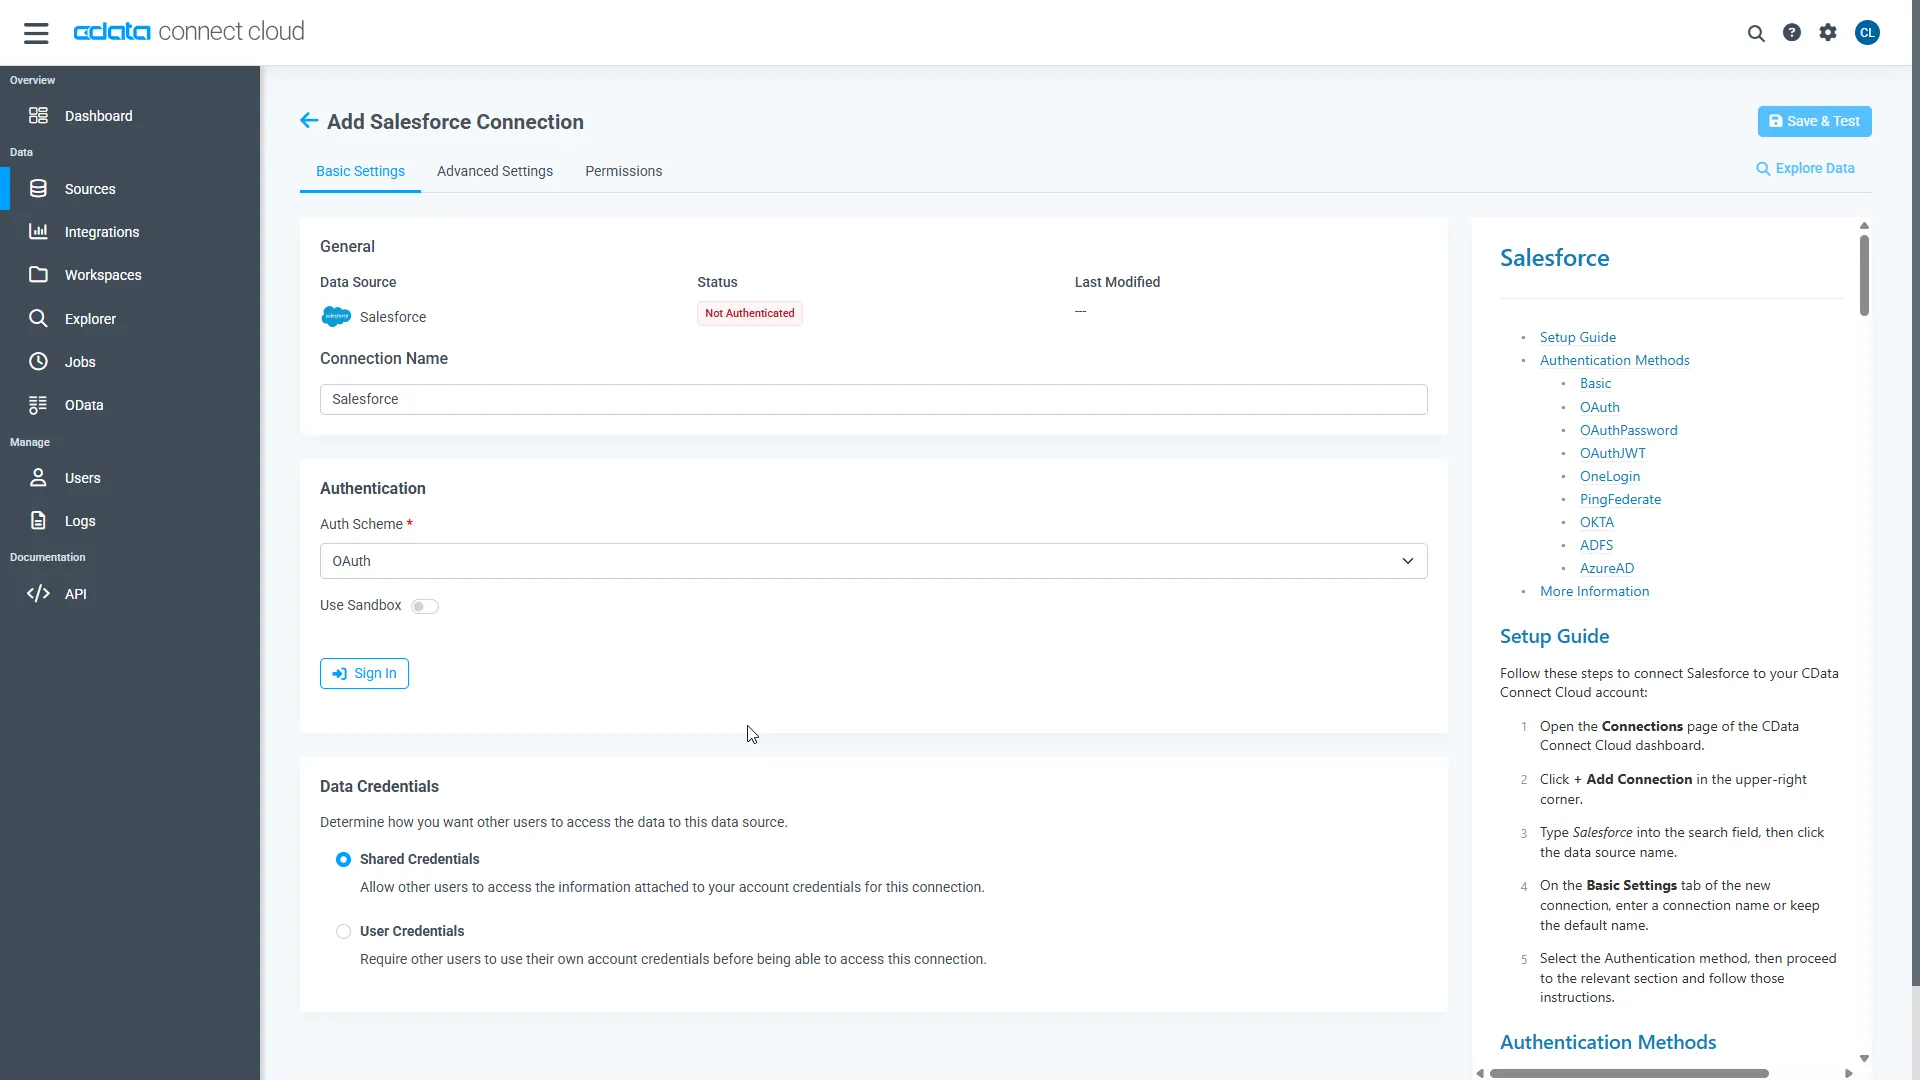
- Click Save & Test
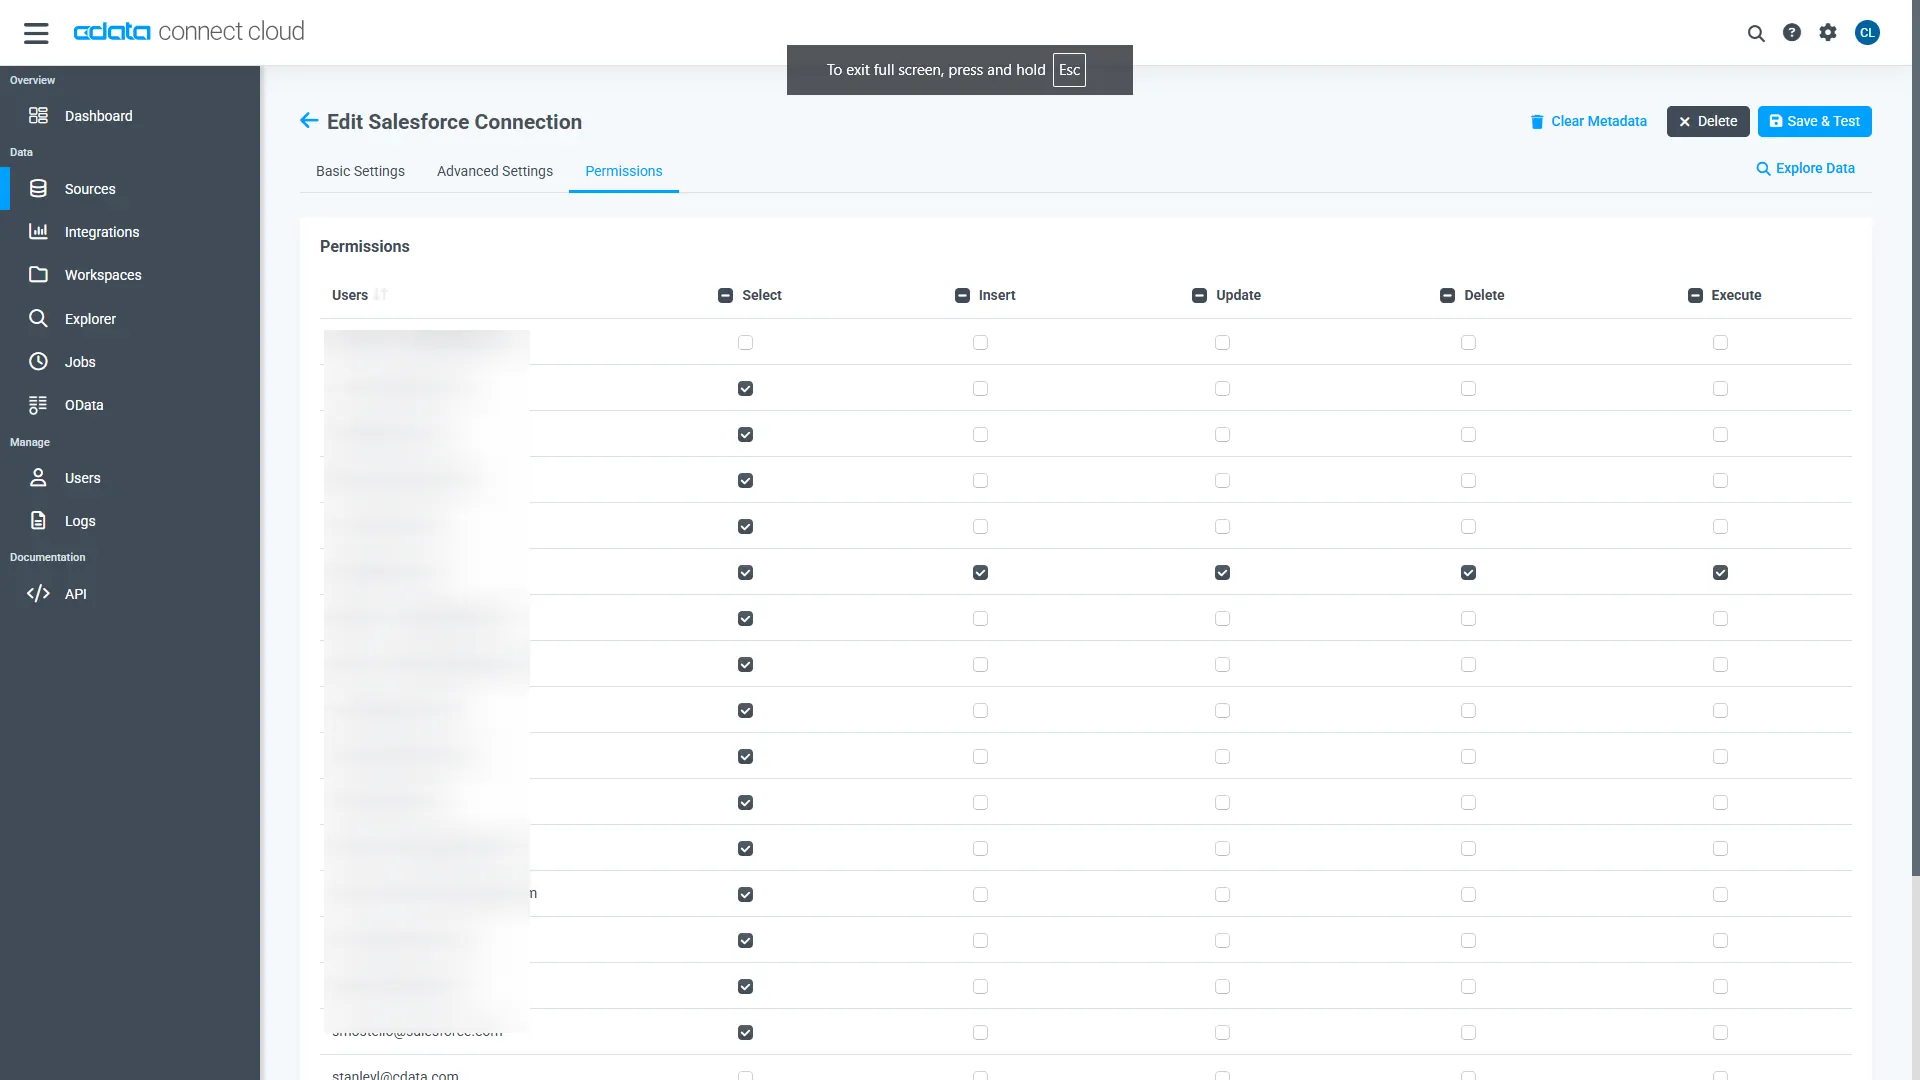
- Once authenticated, open the Permissions tab in the Bitbucket connection and configure user-based permissions as required
Generate a Personal Access Token (PAT)
LlamaIndex authenticates to Connect AI using an account email and a Personal Access Token (PAT). Creating separate PATs for each integration is recommended to maintain access control granularity.
- In Connect AI, select the Gear icon in the top-right to open Settings
- Under Access Tokens, select Create PAT
- Provide a descriptive name for the token and select Create
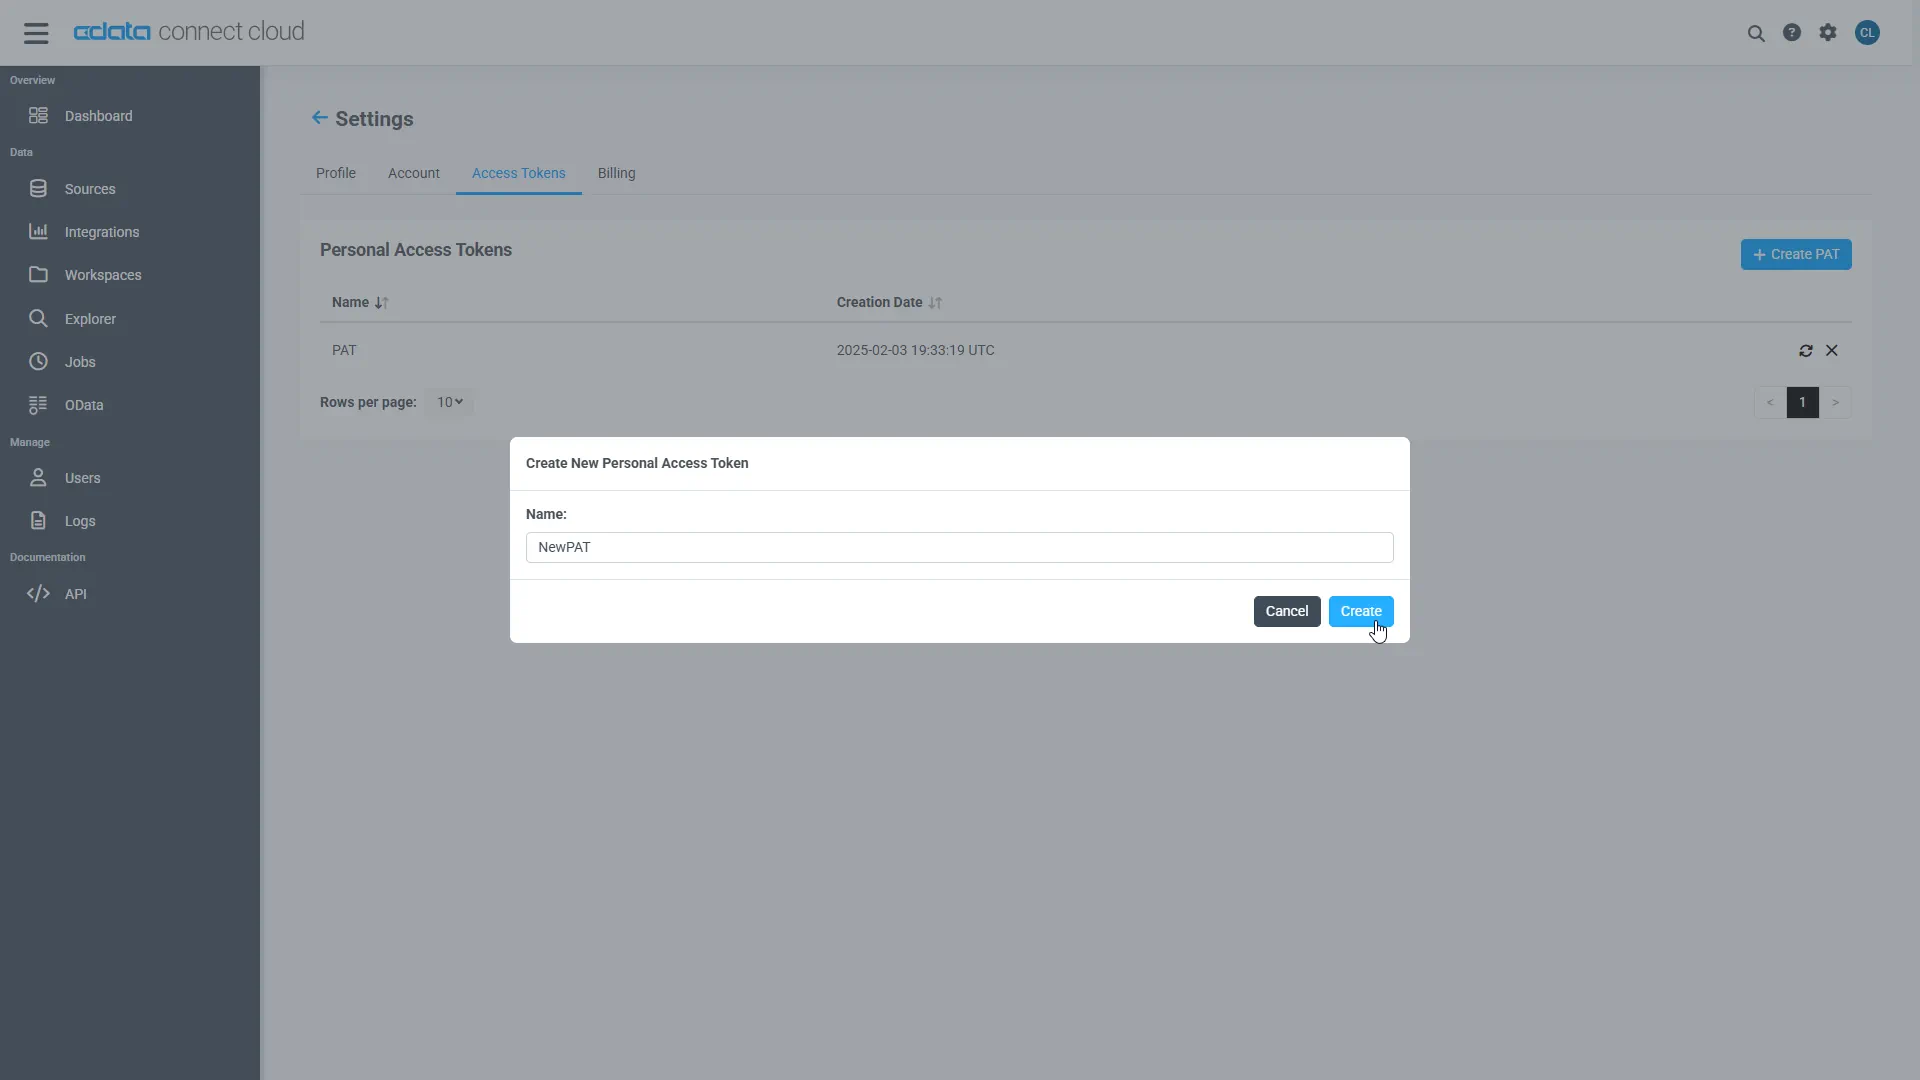
- Copy the token and store it securely. The PAT will only be visible during creation
With the Bitbucket connection configured and a PAT generated, LlamaIndex is prepared to connect to Bitbucket data through the CData MCP server.
Step 2: Connect to the MCP server in LlamaIndex
To connect LlamaIndex with CData Connect AI Remote MCP Server and use OpenAI for reasoning, configure your MCP server endpoint and authentication in a
config.py- Create a folder for the LlamaIndex MCP project
- Create two Python files within the folder:
andconfig.pyllamaindex_agent.py - In
, define your MCP server URL and your Base64-encoded CData Connect AI email and PAT (obtained in the prerequisites):config.pyclass Config: MCP_BASE_URL = "https://mcp.cloud.cdata.com/mcp" # MCP Server URL MCP_AUTH = "base64encoded(EMAIL:PAT)" # Base64 encoded Connect AI Email:PATNote: You can create the base64 encoded version of MCP_AUTH using any Base64 encoding tool.
- In
, wire up the MCP tool spec and a ReAct agent:llamaindex_agent.py""" Integrates a LlamaIndex ReAct agent with the CData Connect AI MCP server. The script discovers MCP tools, wraps them as LlamaIndex tools, and runs an agent loop driven by OpenAI for reasoning. """ import asyncio from llama_index.tools.mcp import BasicMCPClient, McpToolSpec from llama_index.core.agent.workflow import ReActAgent from llama_index.llms.openai import OpenAI from config import Config async def main(): # Initialize the MCP client pointed at Connect AI mcp_client = BasicMCPClient( Config.MCP_BASE_URL, headers={"Authorization": f"Basic {Config.MCP_AUTH}"}, ) # Discover tools the MCP server exposes (getCatalogs, queryData, etc.) tool_spec = McpToolSpec(client=mcp_client) tools = await tool_spec.to_tool_list_async() print("Discovered MCP tools:", [t.metadata.name for t in tools]) # Configure the LLM that drives the ReAct loop llm = OpenAI( model="gpt-4o", temperature=0.2, api_key="YOUR_OPENAI_API_KEY", # https://platform.openai.com/ ) # Build the agent with the MCP-backed tools agent = ReActAgent(tools=tools, llm=llm) user_prompt = "How many tables are available in Bitbucket1?" # Change as needed print(f" User prompt: {user_prompt}") response = await agent.run(user_prompt) print("Agent final response:", response) if __name__ == "__main__": asyncio.run(main())
Step 3: Install the LlamaIndex packages
Since this workflow uses LlamaIndex together with the CData Connect AI MCP server and OpenAI for reasoning, install the required Python packages.
Run the following command in your project terminal:
pip install llama-index llama-index-tools-mcp llama-index-llms-openai
Step 4: Prompt Bitbucket using LlamaIndex (via the MCP server)
- When the installation finishes, run
to execute the scriptpython llamaindex_agent.py - The script connects to the MCP server and discovers the CData Connect AI MCP tools available for querying your connected data
- Supply a prompt (e.g., "How many tables are available in Bitbucket?")
- The agent reasons over the available tools, calls
against Bitbucket, and responds with the resultqueryData
Get CData Connect AI
To get live data access to hundreds of SaaS, Big Data, and NoSQL sources directly from your cloud applications, try CData Connect AI today!