


Integrating Dataiku with HubDB Data via CData Connect AI
Dataiku is a collaborative data science and AI platform that enables teams to design, deploy, and manage machine learning and generative AI projects within a governed environment. It's Agent and GenAI framework allows users to build intelligent agents that can analyze, generate, and act on data through custom workflows and model orchestration.
By integrating Dataiku with CData Connect AI through the built-in MCP (Model Context Protocol) Server, these agents gain secure, real-time access to live HubDB data. The integration bridges Dataiku's agent execution environment with CData's governed enterprise connectivity layer, allowing every query or instruction to run safely against authorized data sources without manual exports or staging.
This article demonstrates how to configure HubDB connectivity in Connect AI, prepare a Python code environment in Dataiku with MCP support, and create an agent that queries and interacts with live HubDB data directly from within Dataiku.
Step 1: Configure HubDB Connectivity for Dataiku
Connectivity to HubDB from Dataiku is made possible through CData Connect AI's Remote MCP Server. To interact with HubDB data from Dataiku, you start by creating and configuring a HubDB connection in CData Connect AI.
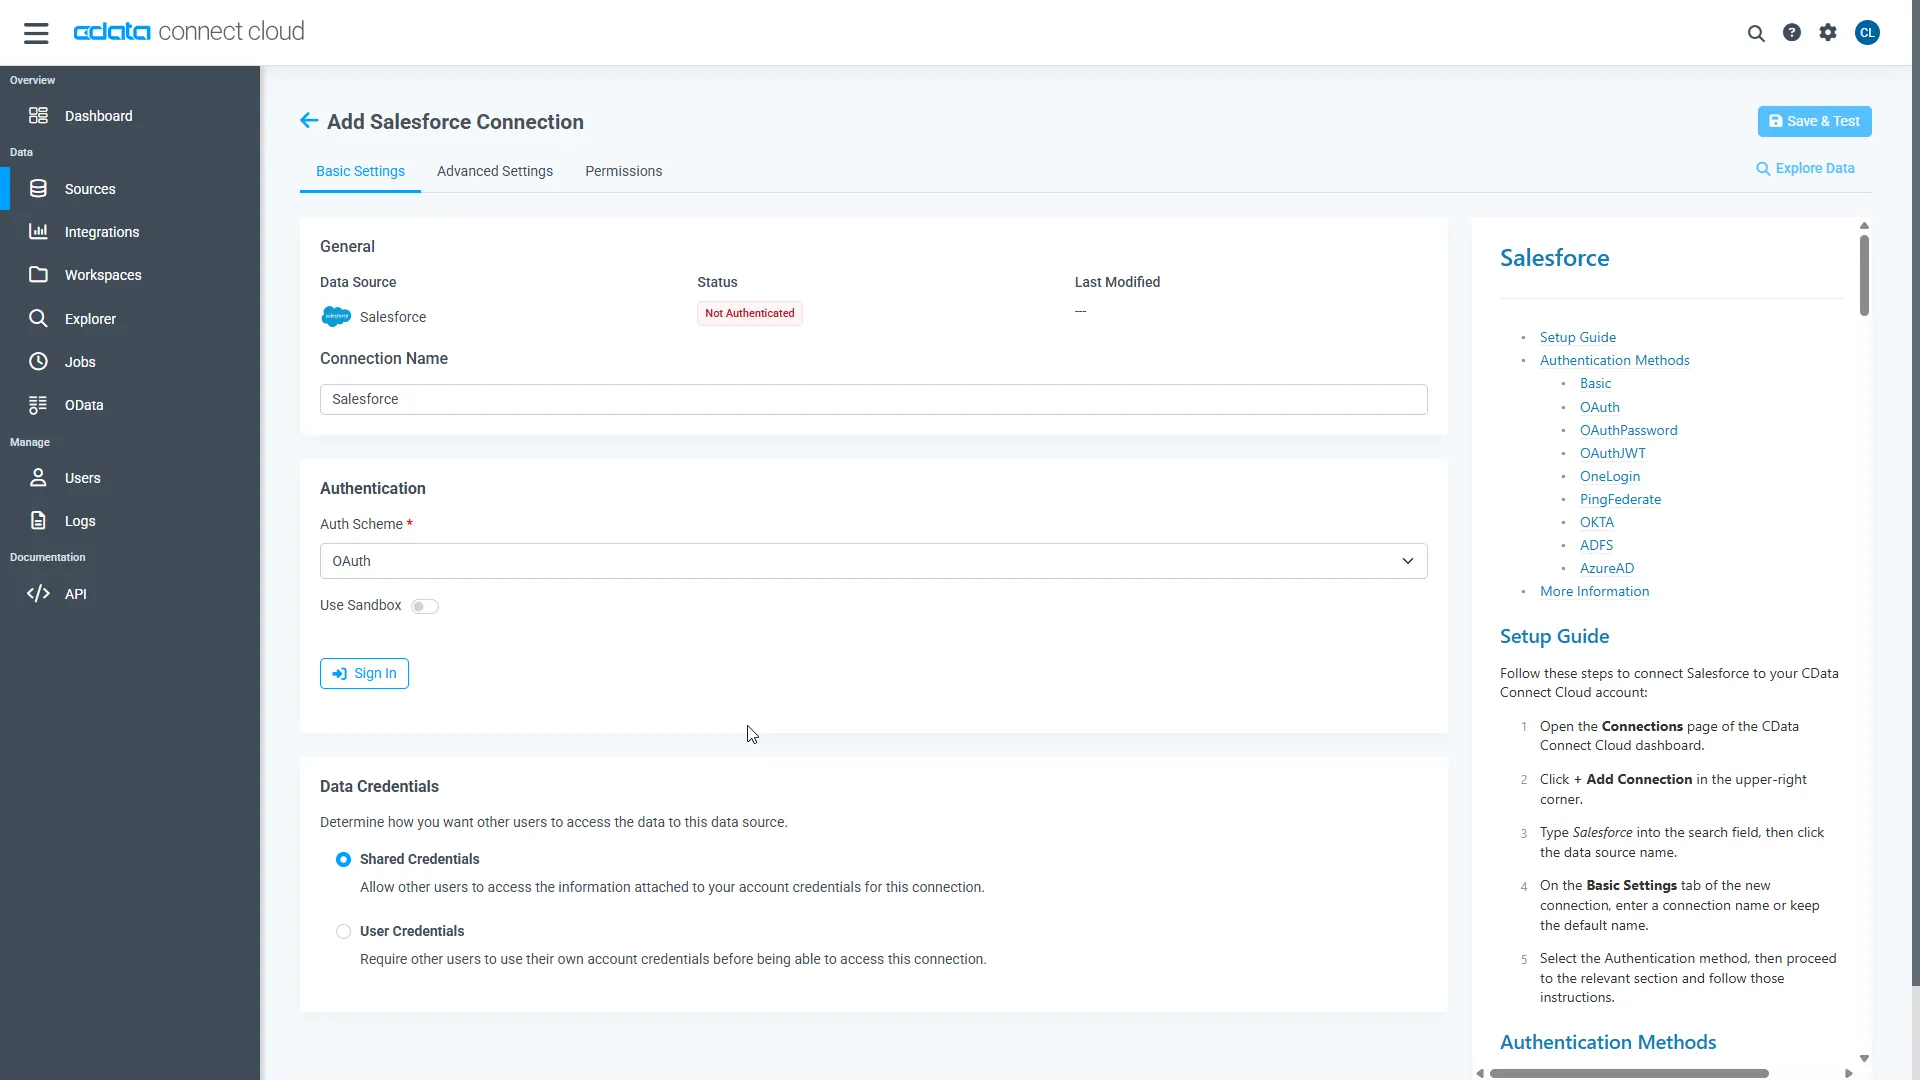
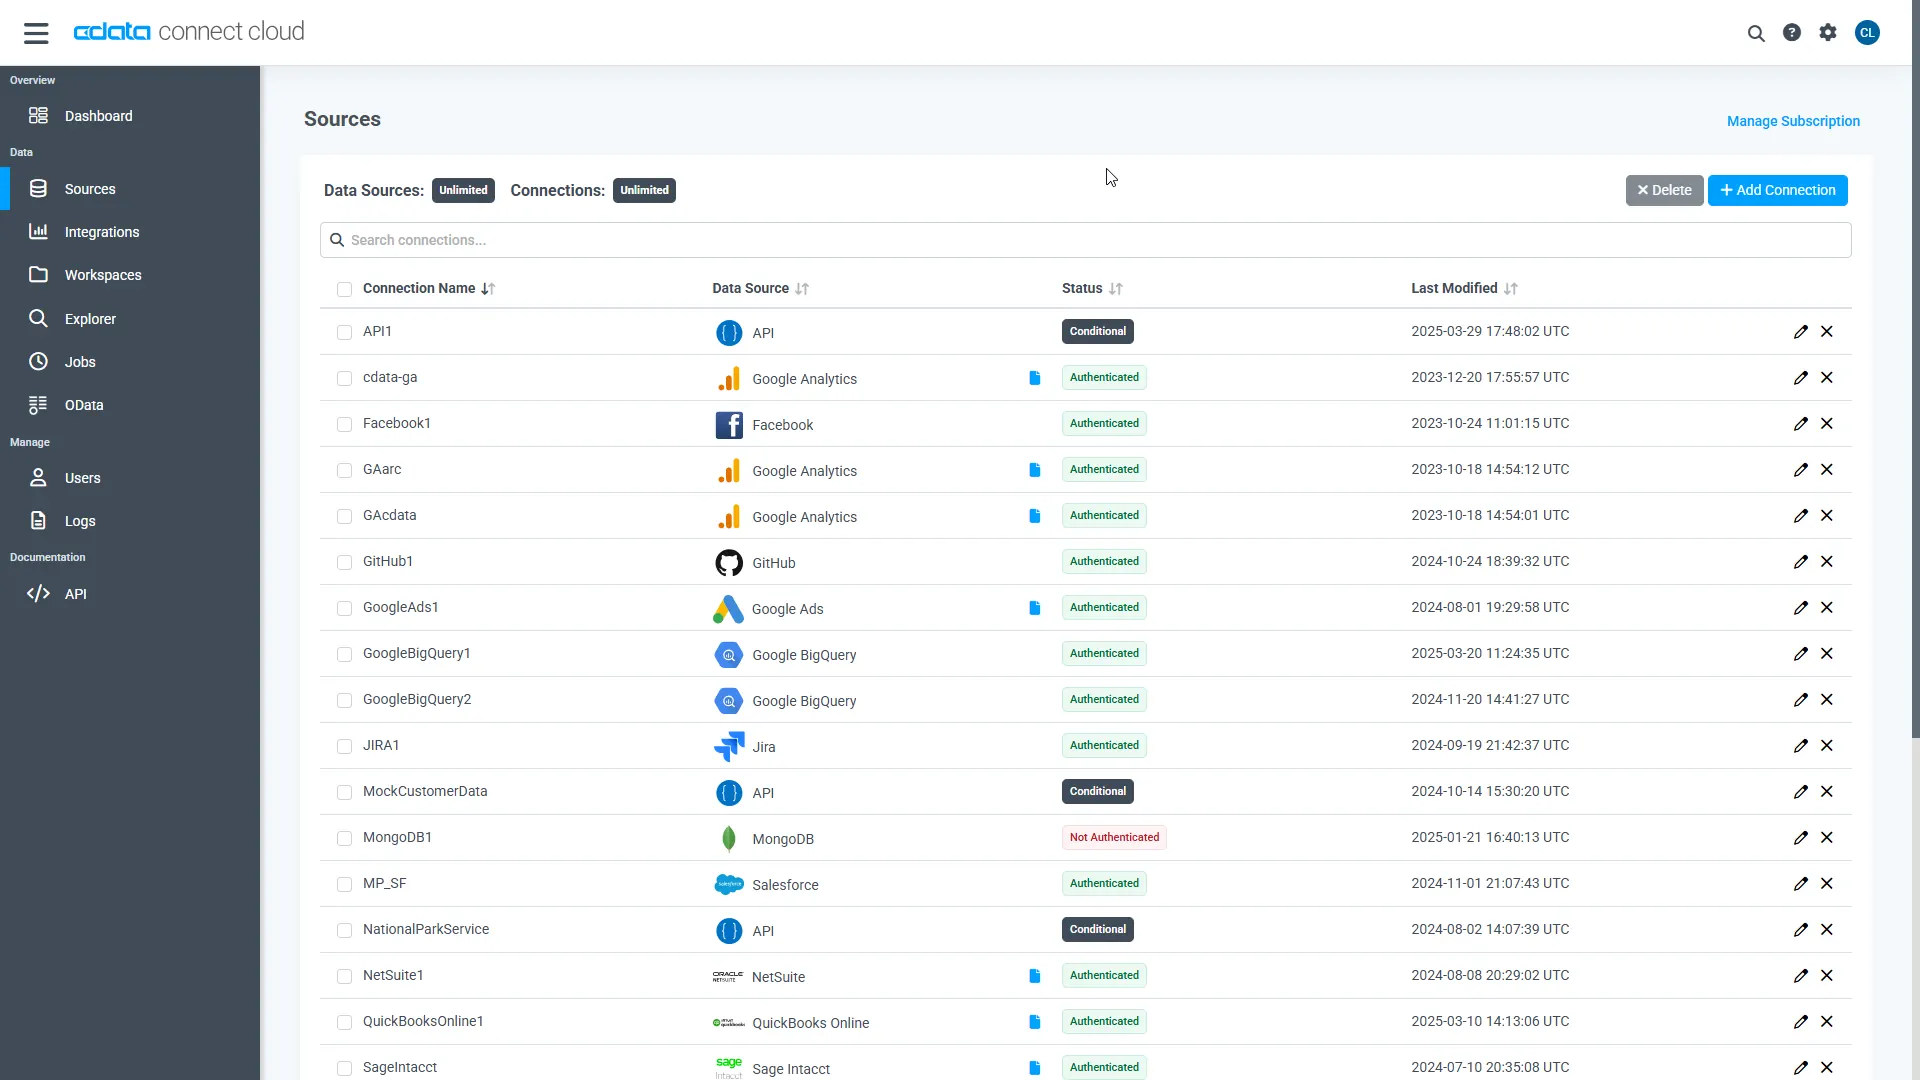
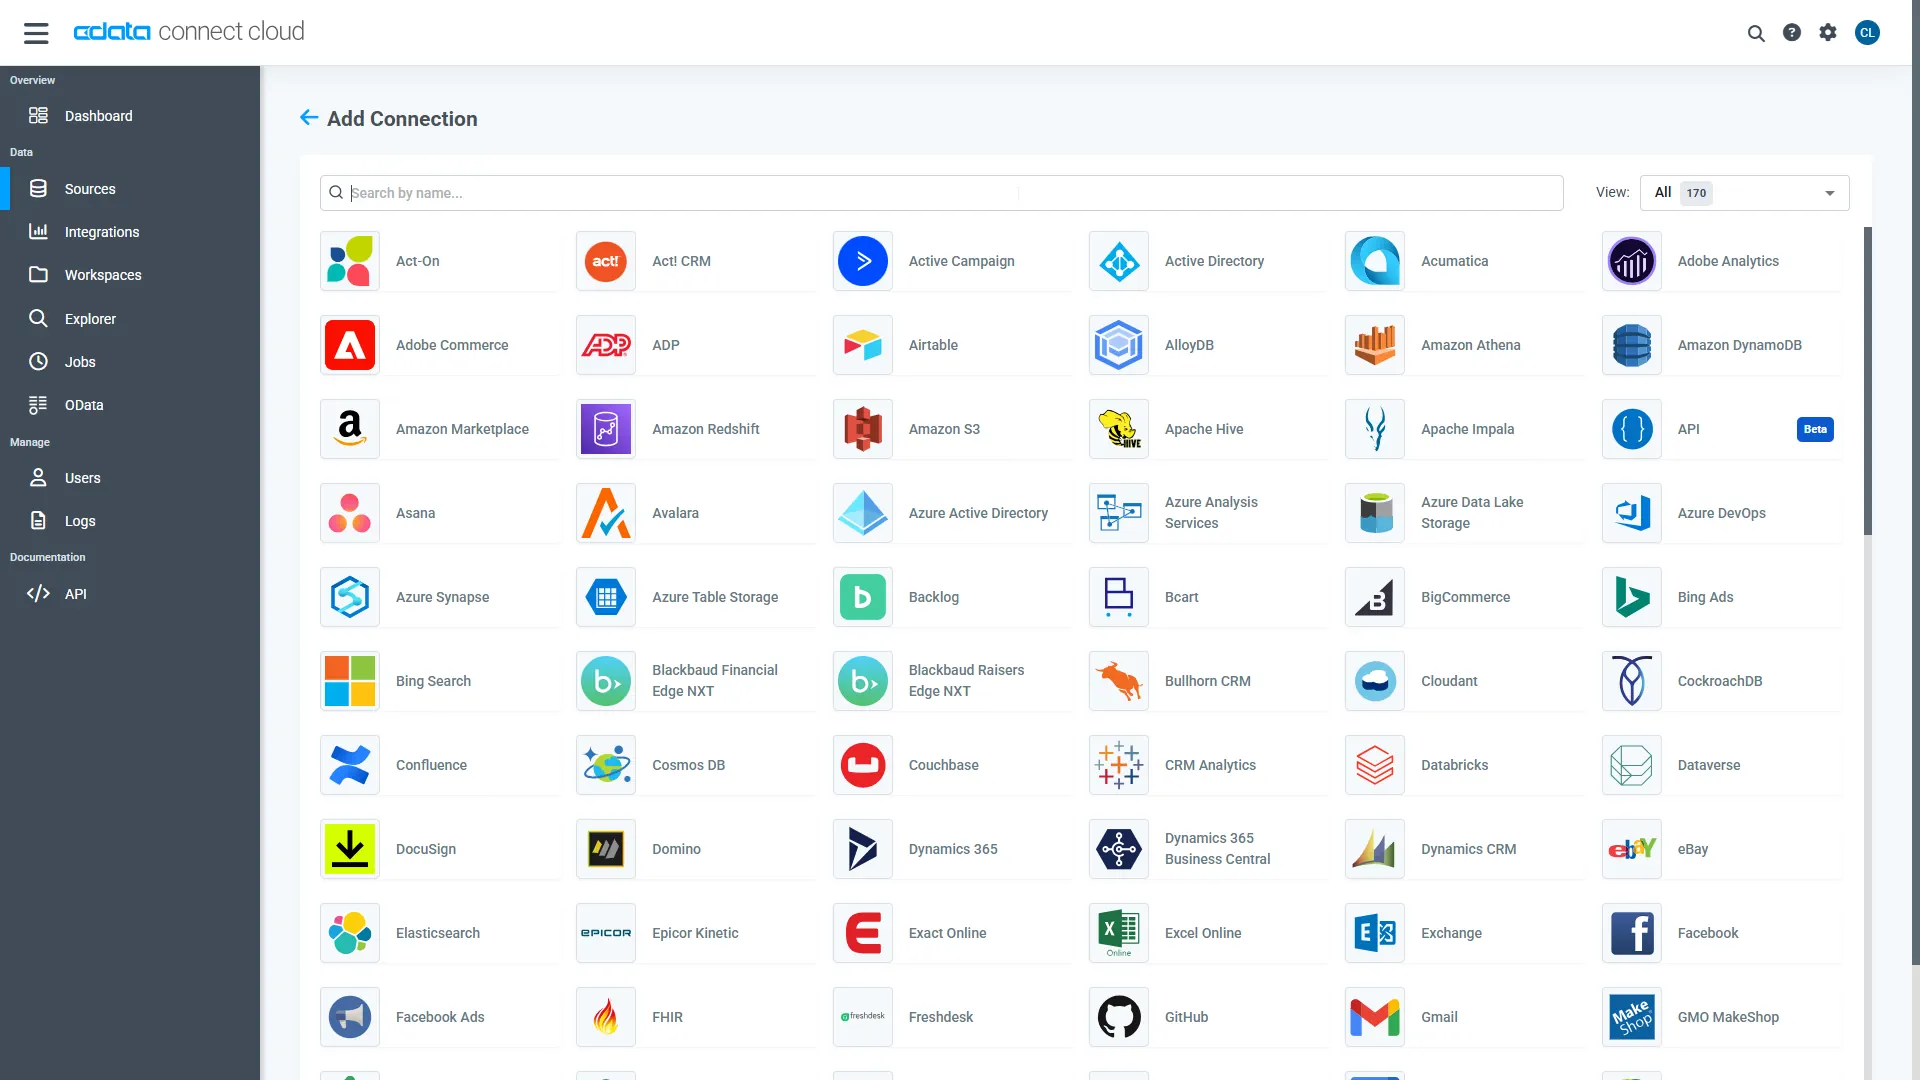
- Log into Connect AI, click Sources, then click Add Connection
- Select "HubDB" from the Add Connection panel
-
Enter the necessary authentication properties to connect to HubDB.
There are two authentication methods available for connecting to HubDB data source: OAuth Authentication with a public HubSpot application and authentication with a Private application token.
Using a Custom OAuth App
AuthScheme must be set to "OAuth" in all OAuth flows. Be sure to review the Help documentation for the required connection properties for you specific authentication needs (desktop applications, web applications, and headless machines).
Follow the steps below to register an application and obtain the OAuth client credentials:
- Log into your HubSpot app developer account.
- Note that it must be an app developer account. Standard HubSpot accounts cannot create public apps.
- On the developer account home page, click the Apps tab.
- Click Create app.
- On the App info tab, enter and optionally modify values that are displayed to users when they connect. These values include the public application name, application logo, and a description of the application.
- On the Auth tab, supply a callback URL in the "Redirect URLs" box.
- If you're creating a desktop application, set this to a locally accessible URL like http://localhost:33333.
- If you are creating a Web application, set this to a trusted URL where you want users to be redirected to when they authorize your application.
- Click Create App. HubSpot then generates the application, along with its associated credentials.
- On the Auth tab, note the Client ID and Client secret. You will use these later to configure the driver.
Under Scopes, select any scopes you need for your application's intended functionality.
A minimum of the following scopes is required to access tables:
- hubdb
- oauth
- crm.objects.owners.read
- Click Save changes.
- Install the application into a production portal with access to the features that are required by the integration.
- Under "Install URL (OAuth)", click Copy full URL to copy the installation URL for your application.
- Navigate to the copied link in your browser. Select a standard account in which to install the application.
- Click Connect app. You can close the resulting tab.
Using a Private App
To connect using a HubSpot private application token, set the AuthScheme property to "PrivateApp."
You can generate a private application token by following the steps below:
- In your HubDB account, click the settings icon (the gear) in the main navigation bar.
- In the left sidebar menu, navigate to Integrations > Private Apps.
- Click Create private app.
- On the Basic Info tab, configure the details of your application (name, logo, and description).
- On the Scopes tab, select Read or Write for each scope you want your private application to be able to access.
- A minimum of hubdb and crm.objects.owners.read is required to access tables.
- After you are done configuring your application, click Create app in the top right.
- Review the info about your application's access token, click Continue creating, and then Show token.
- Click Copy to copy the private application token.
To connect, set PrivateAppToken to the private application token you retrieved.
- Log into your HubSpot app developer account.
- Click Save & Test
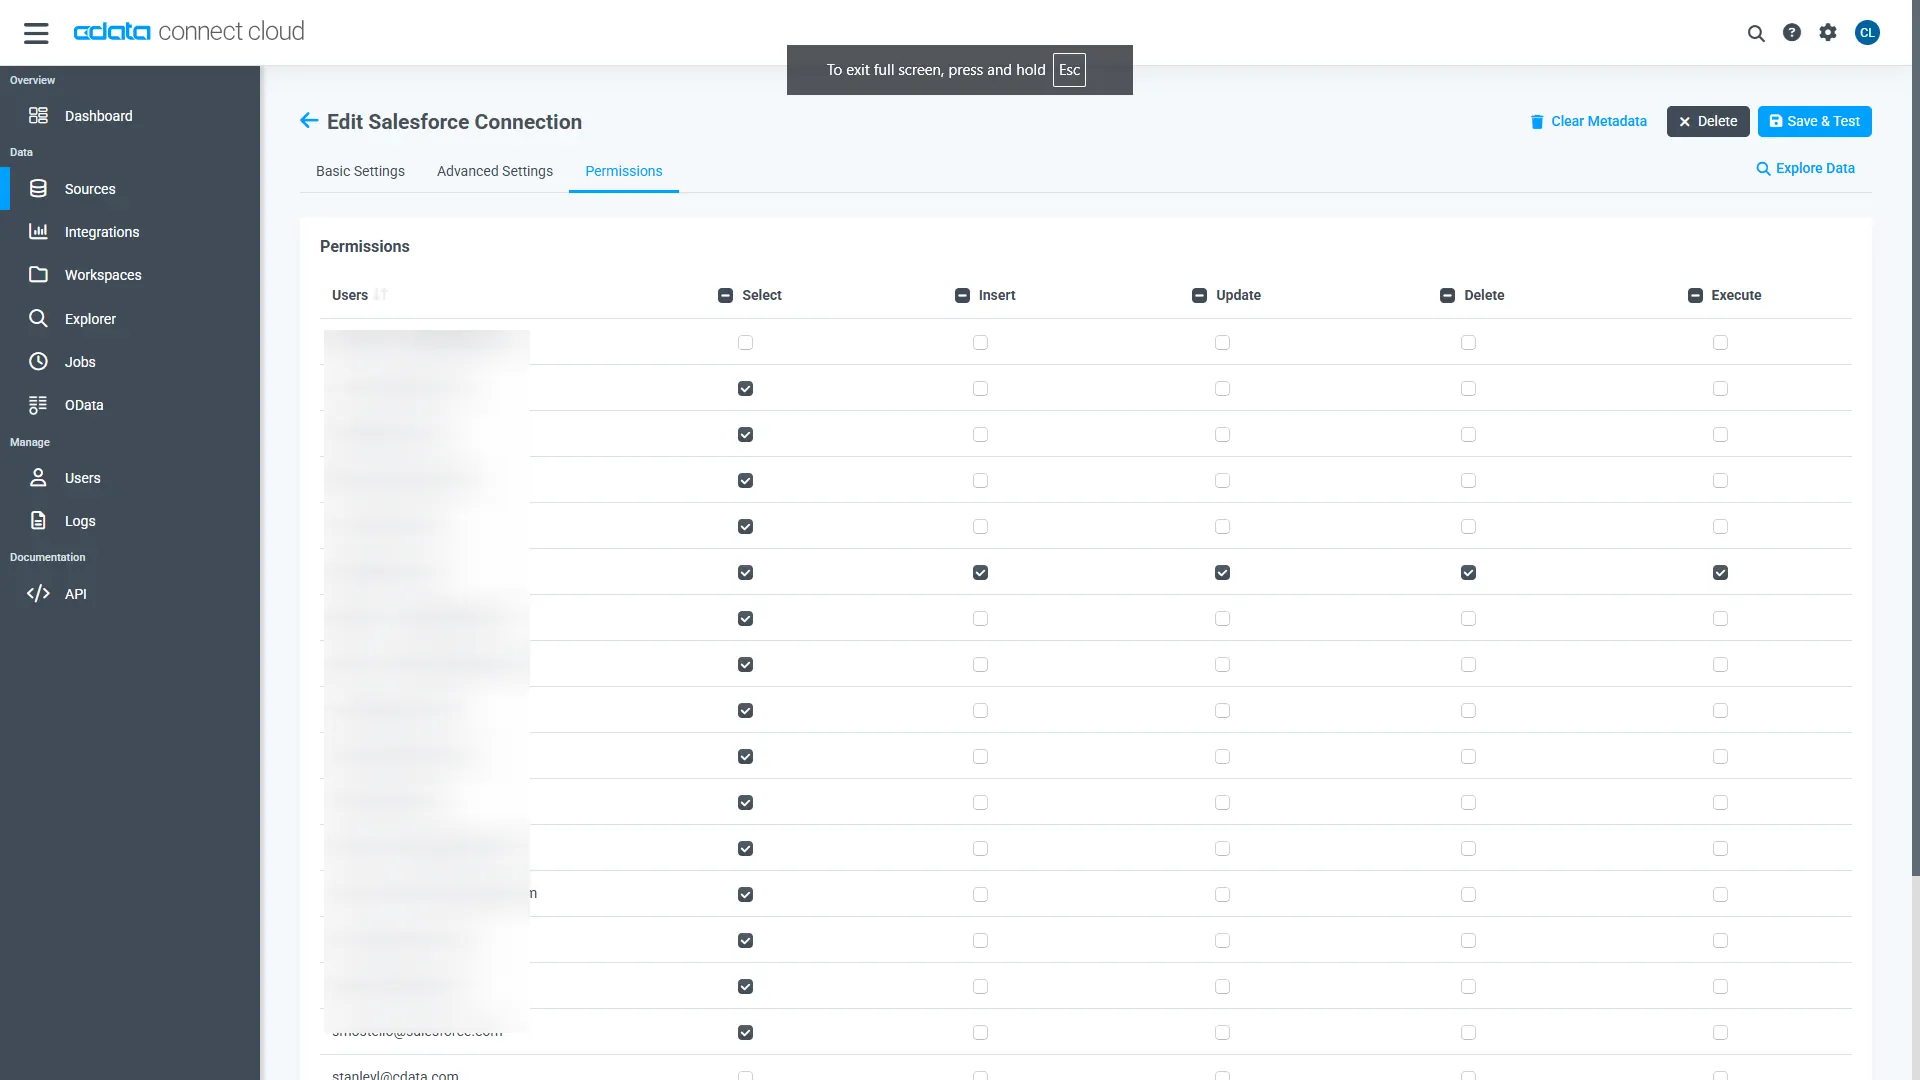
- Open the Permissions tab and set user-based permissions
Add a Personal Access Token
A Personal Access Token (PAT) is used to authenticate the connection to Connect AI from Dataiku. It is best practice to create a separate PAT for each integration to maintain granular access control
- Click the gear icon () at the top right of the Connect AI app to open Settings
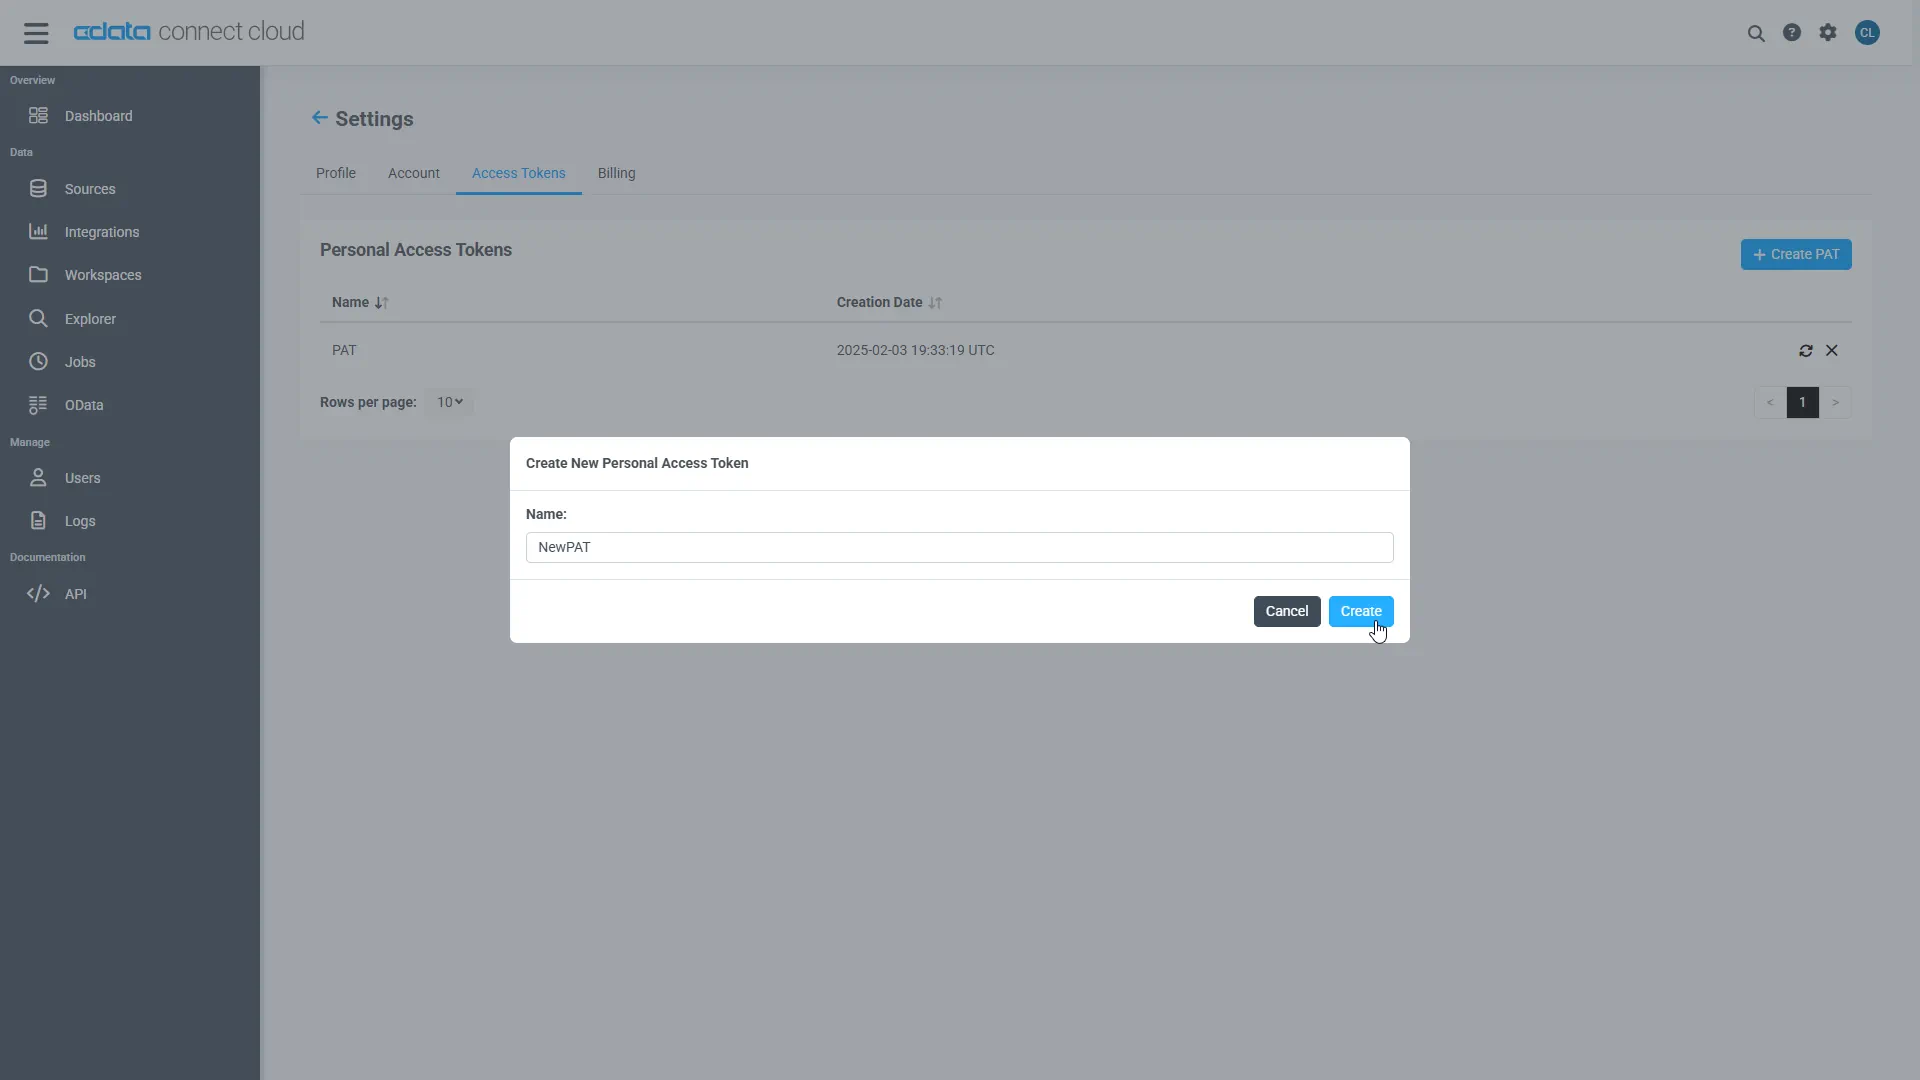
- On the Settings page, go to the Access Tokens section and click Create PAT
- Give the PAT a descriptive name and click Create
- Copy the token when displayed and store it securely. It will not be shown again
With the HubDB connection configured and a PAT generated, Dataiku can now connect to HubDB data through the Connect AI.
Step 2: Prepare Dataiku and the Code Environment
A dedicated python code environment in Dataiku provides the runtime support needed for MCP-based communication. To enable Dataiku Agents to connect to CData Connect AI, create a Python environment and install the MCP client dependencies required for agent-to-server interaction.
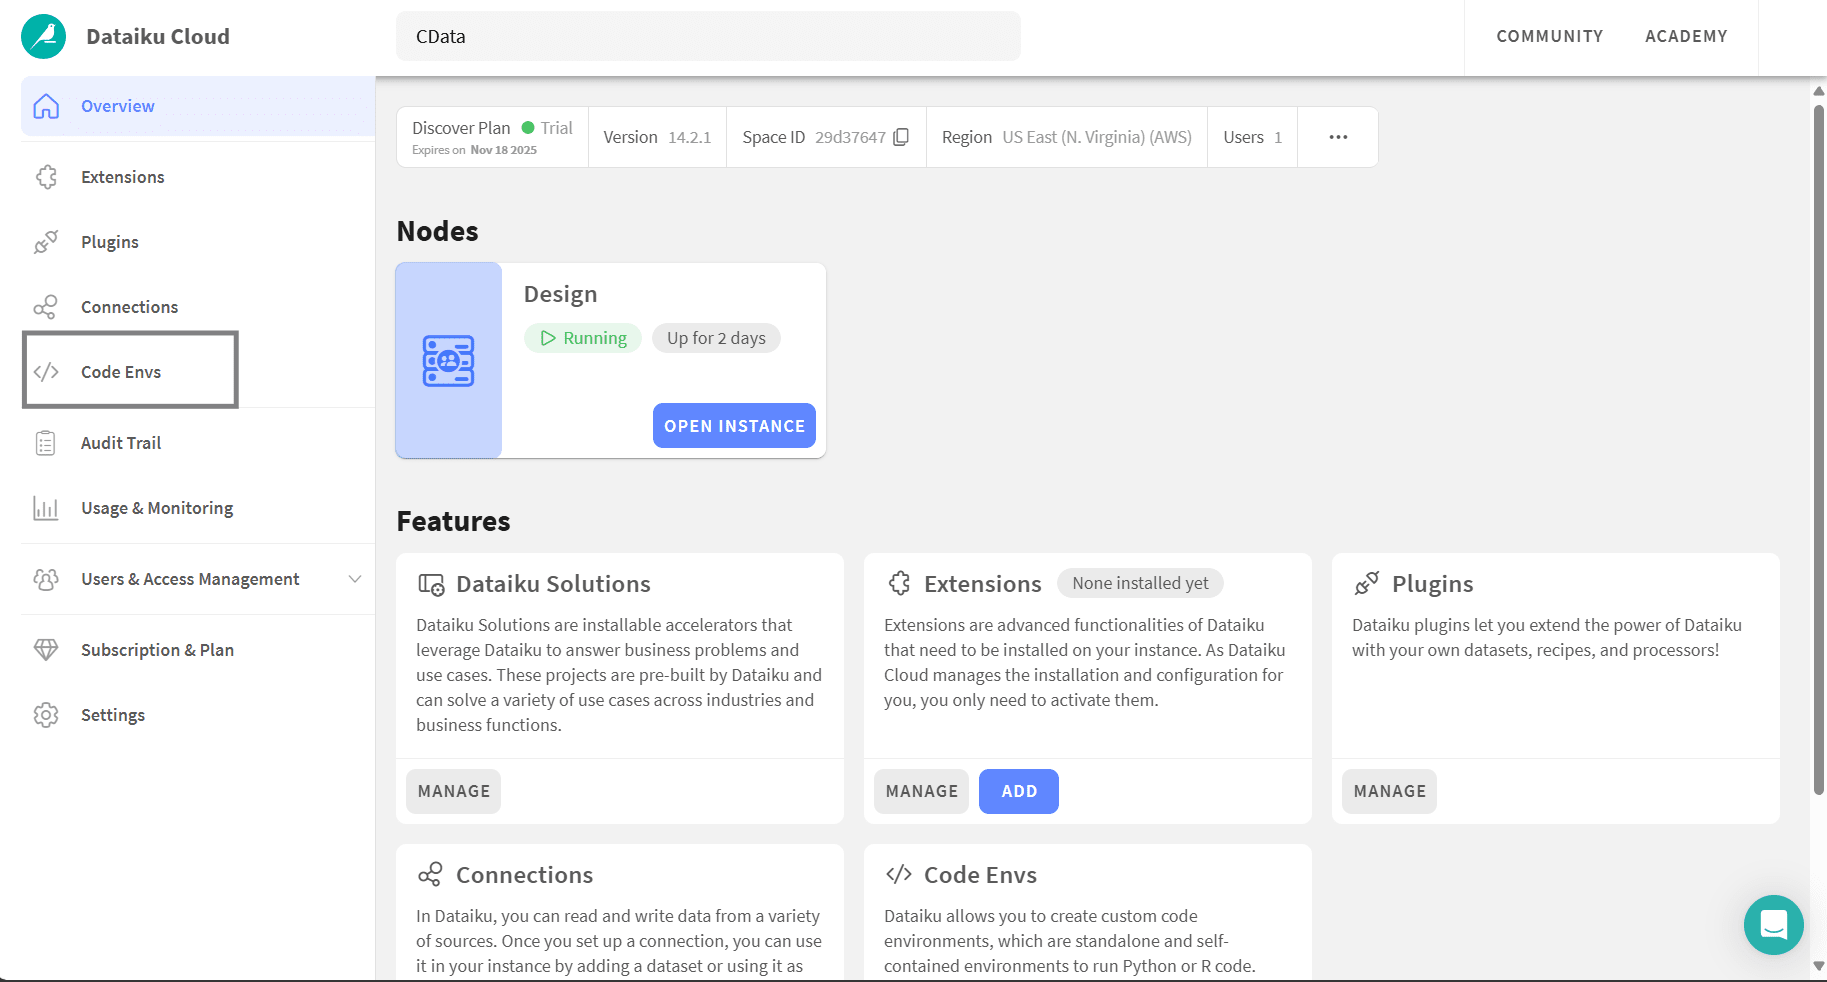
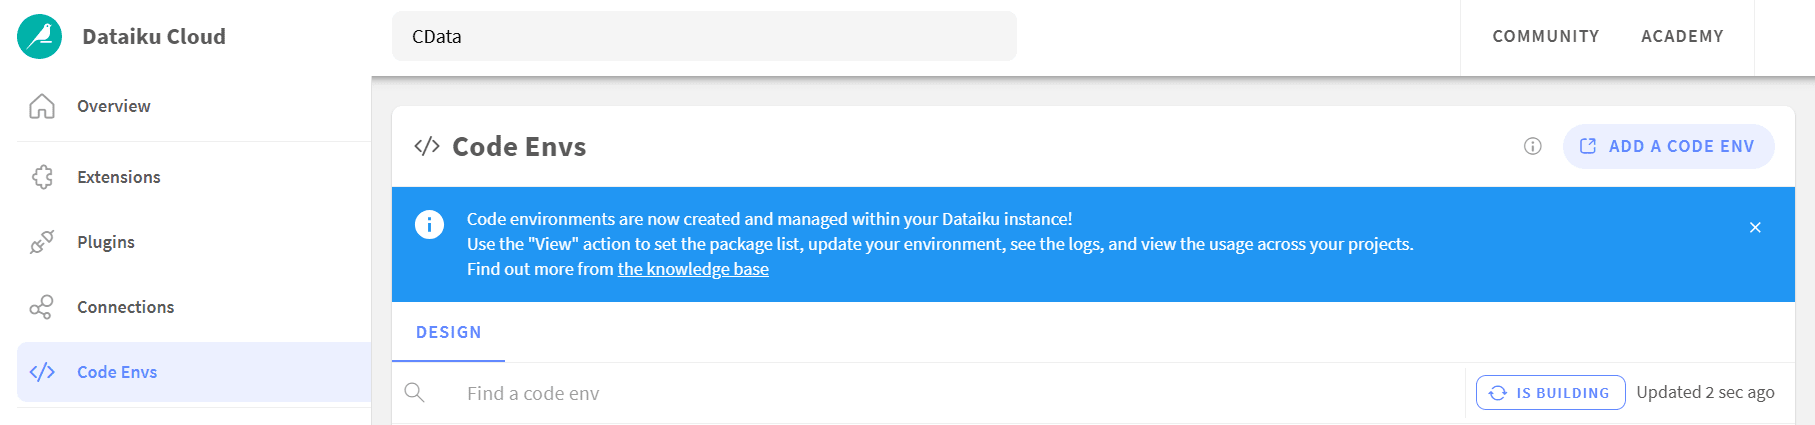
- In Dataiku Cloud, open Code Envs
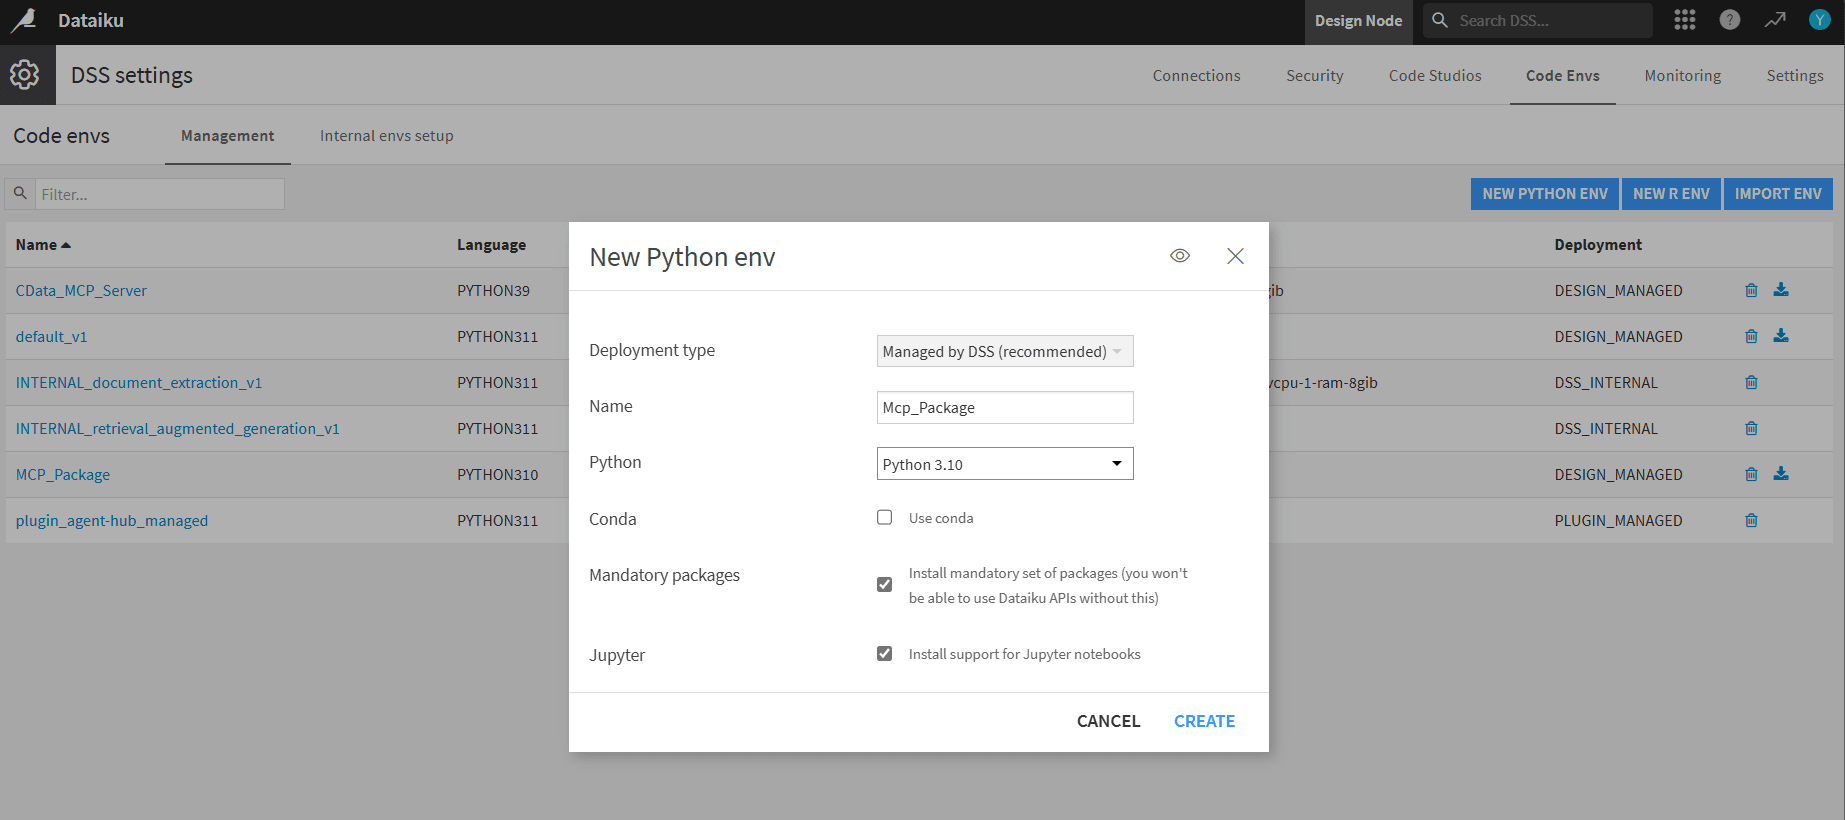
- Click Add a code env to open the DSS settings window
- In DSS, click New Python env. Name it (for example, MCP_Package) and choose Python 3.10 (3.10 to 3.13 supported)
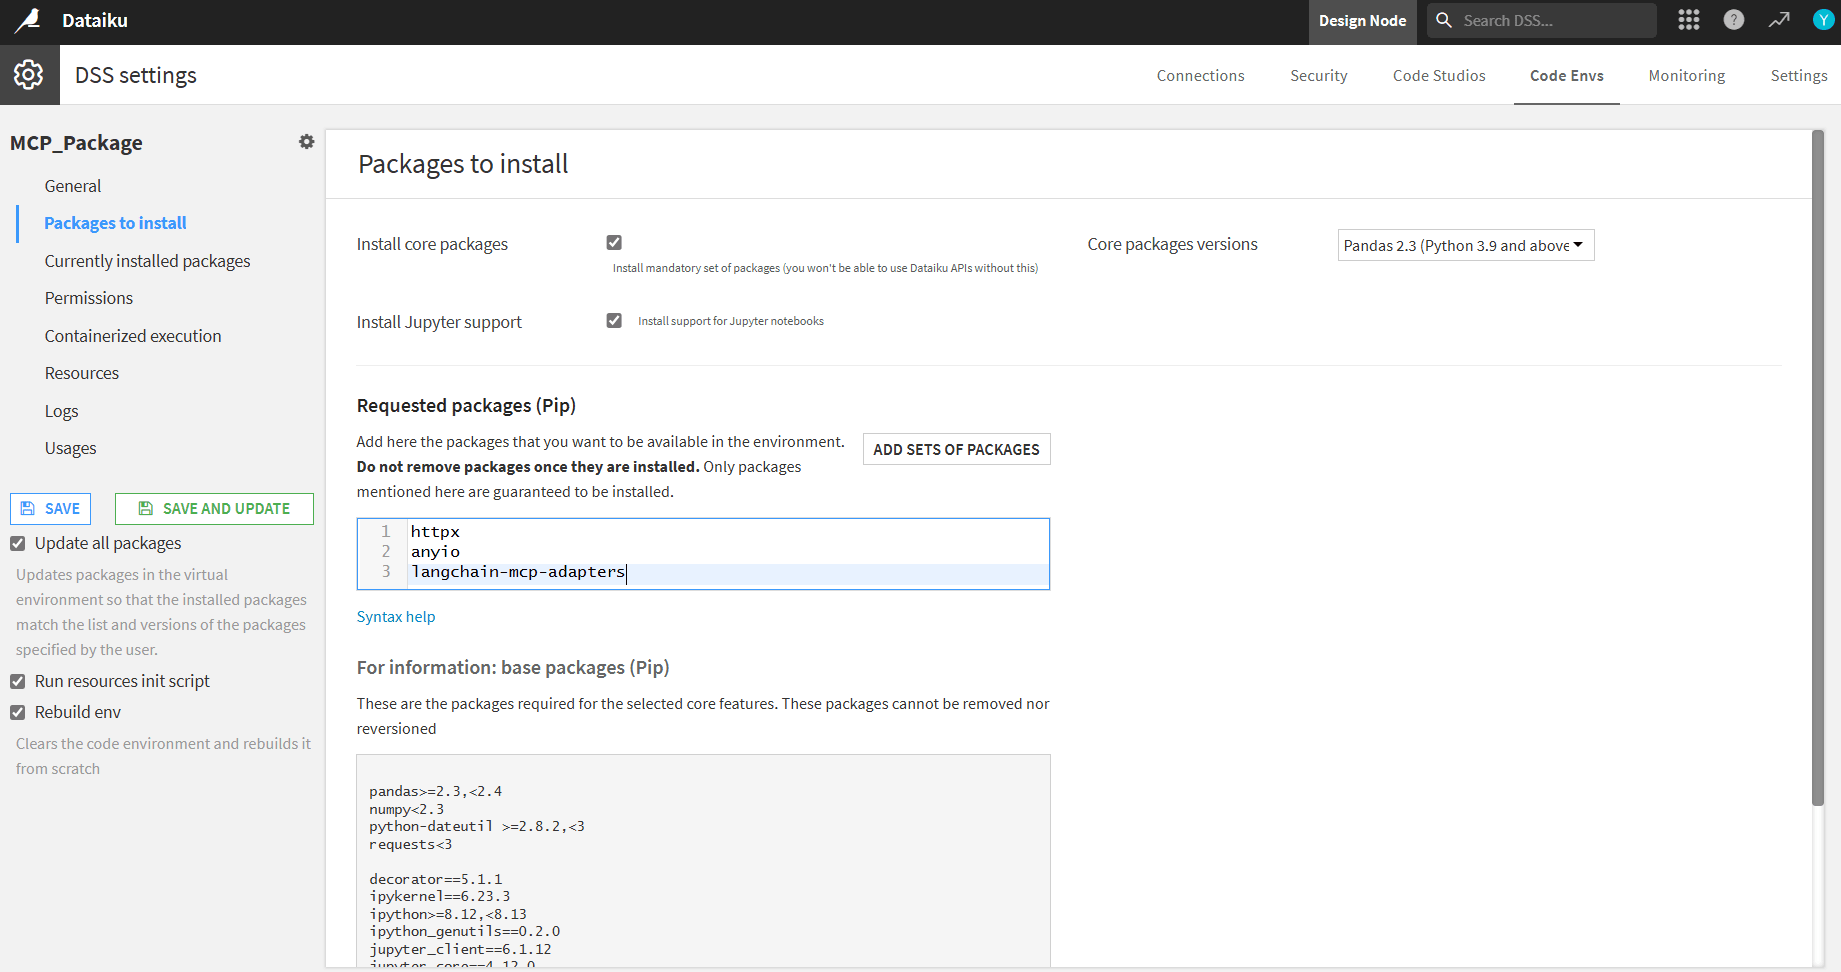
- Open Packages to install and add the following pip packages:
- httpx
- anyio
- langchain-mcp-adapters
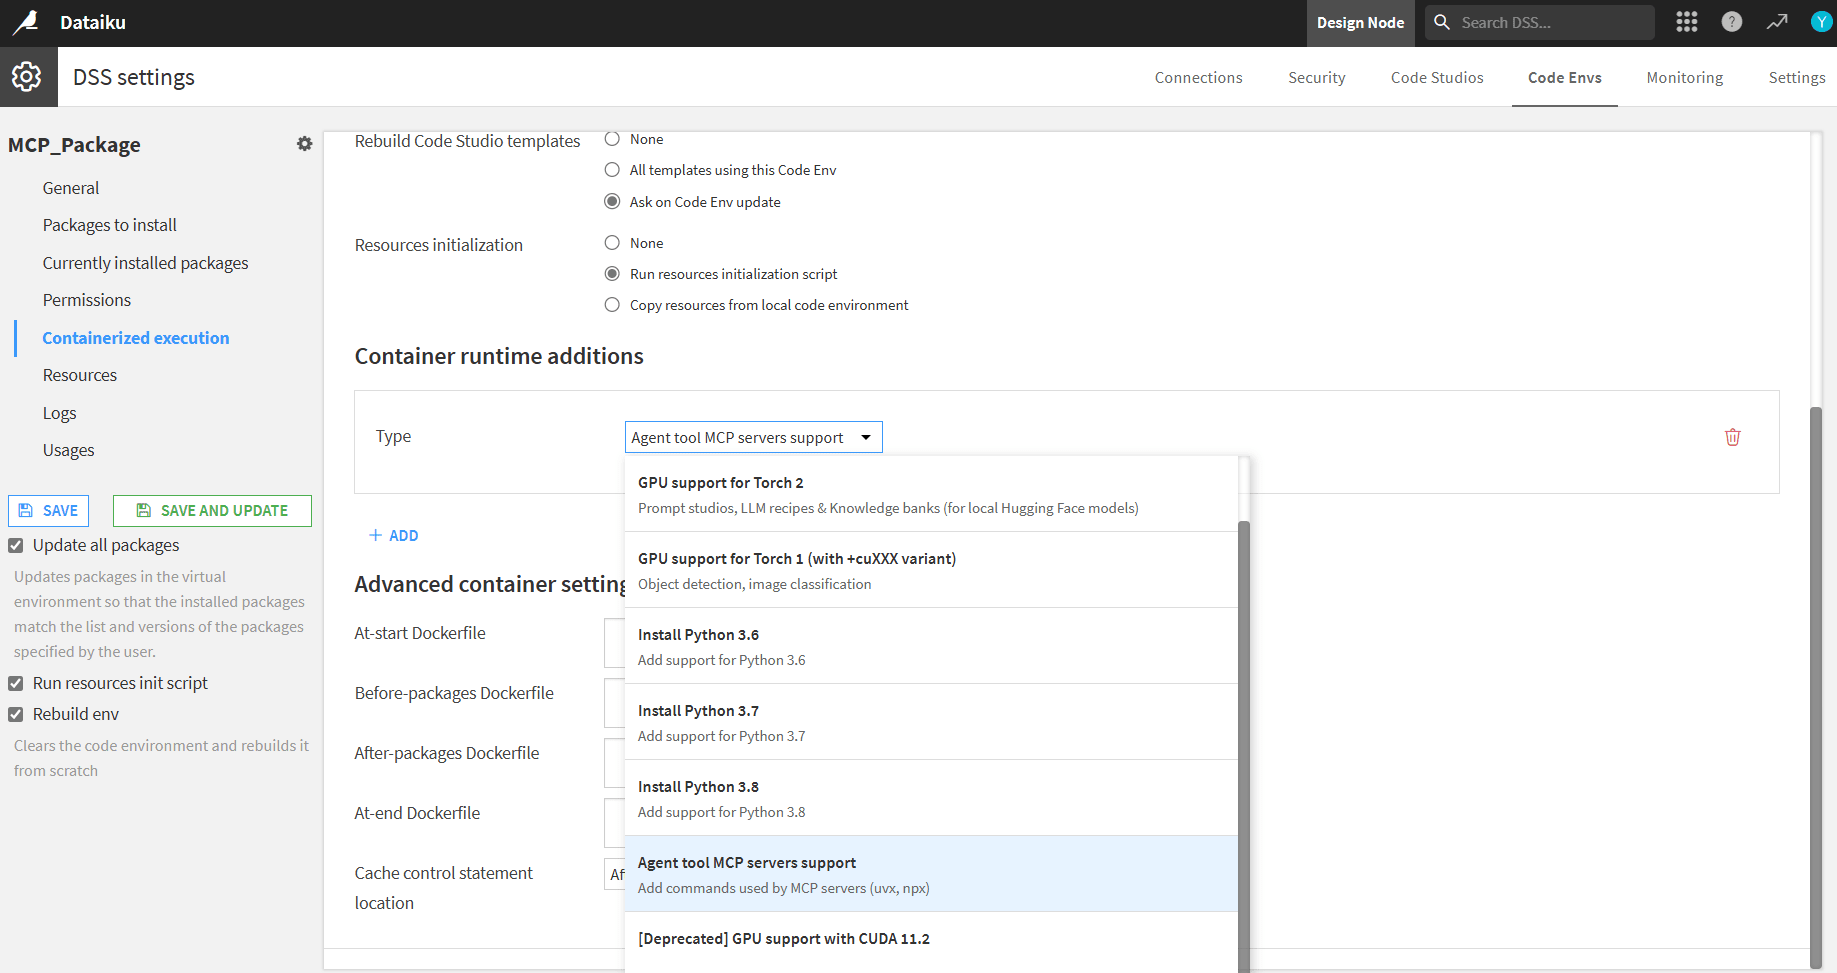
- Open Containerized execution and under Container runtime additions select Agent tool MCP servers support
- Check Rebuild env and click Save and update to install packages
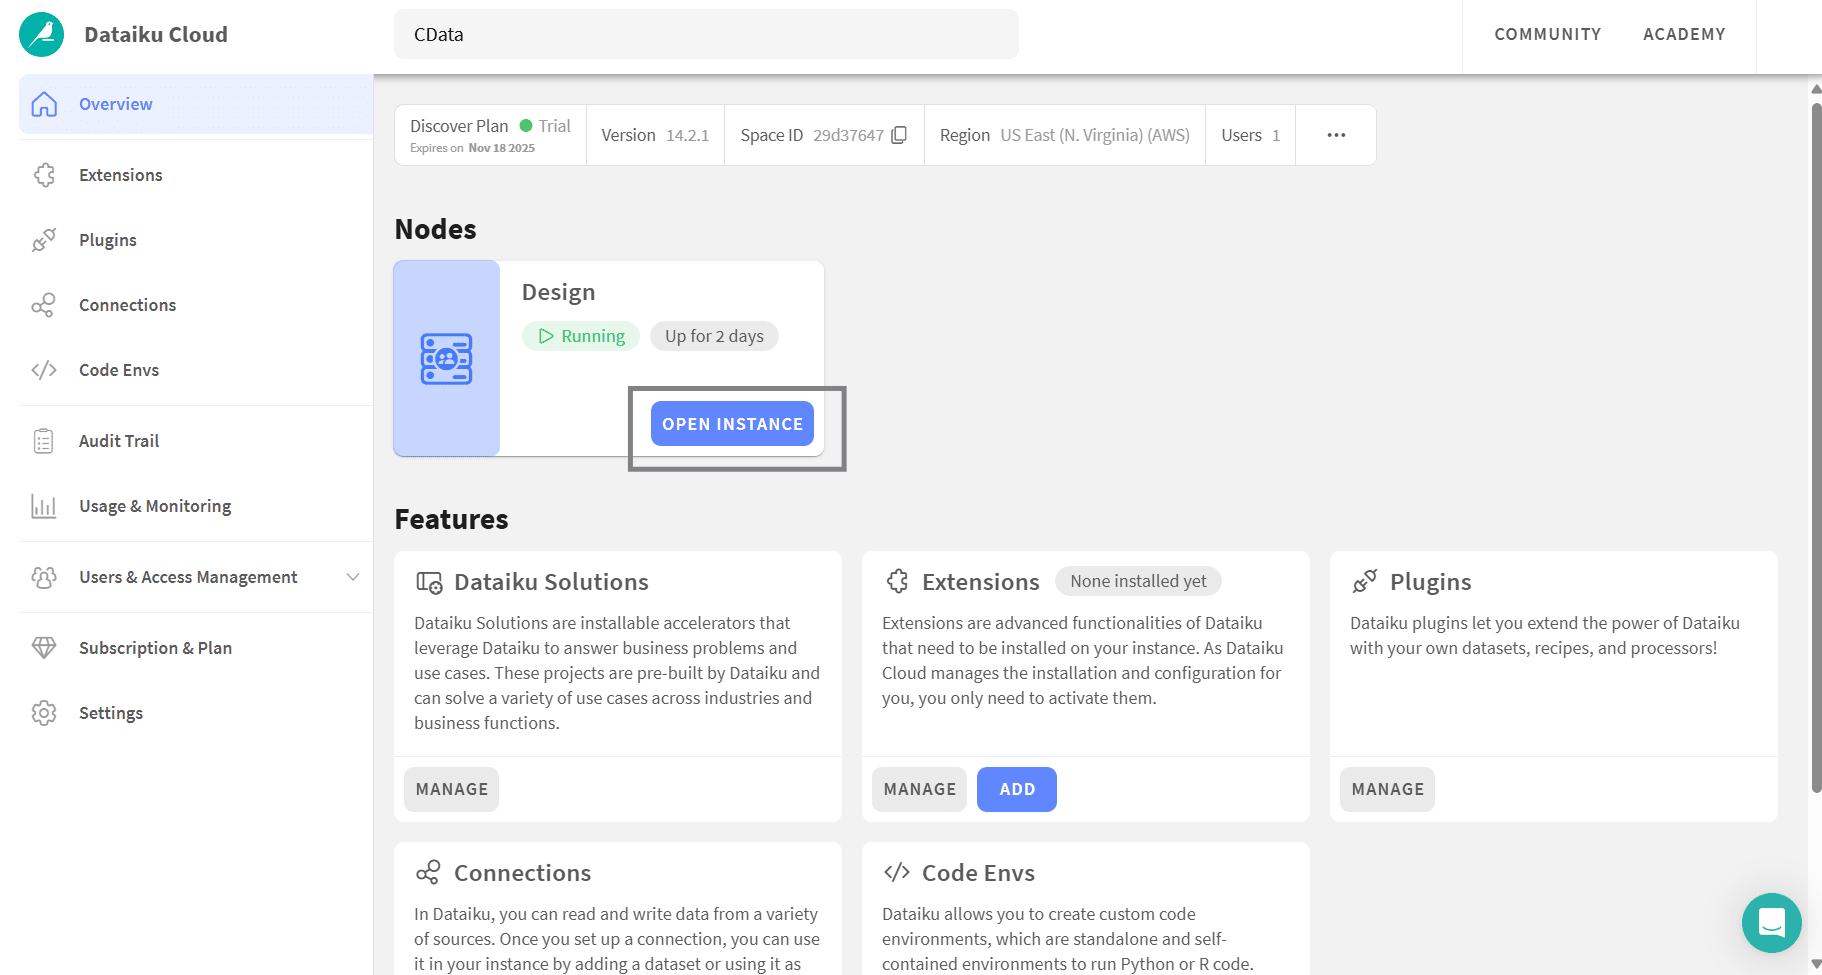
- Back in Dataiku Cloud, open Overview and click Open instance
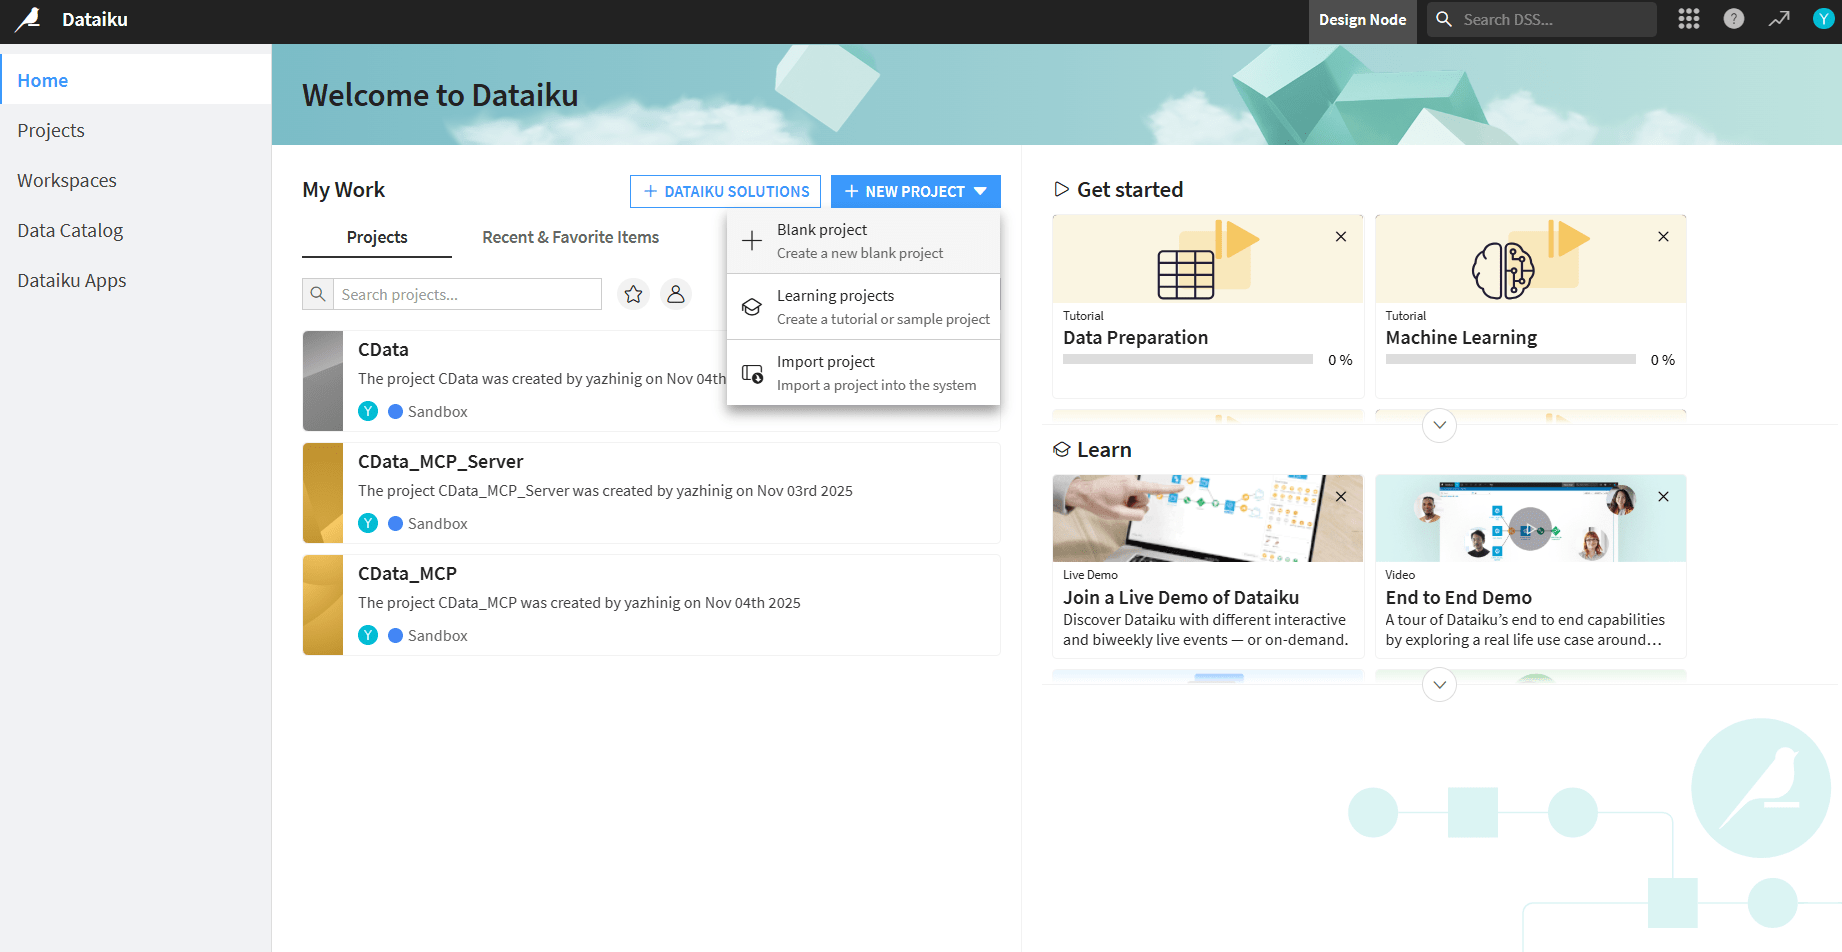
- Click + New project and select Blank project. Name the project
Step 3: Create a Dataiku Agent and connect to the MCP server
The Dataiku Agent serves as the bridge between the Dataiku workspace and Connect AI. To enable this connection, create a custom code-based agent, assign it the configured Python environment, and embed your Connect AI credentials to allow the agent to query and interact with live HubDB data.
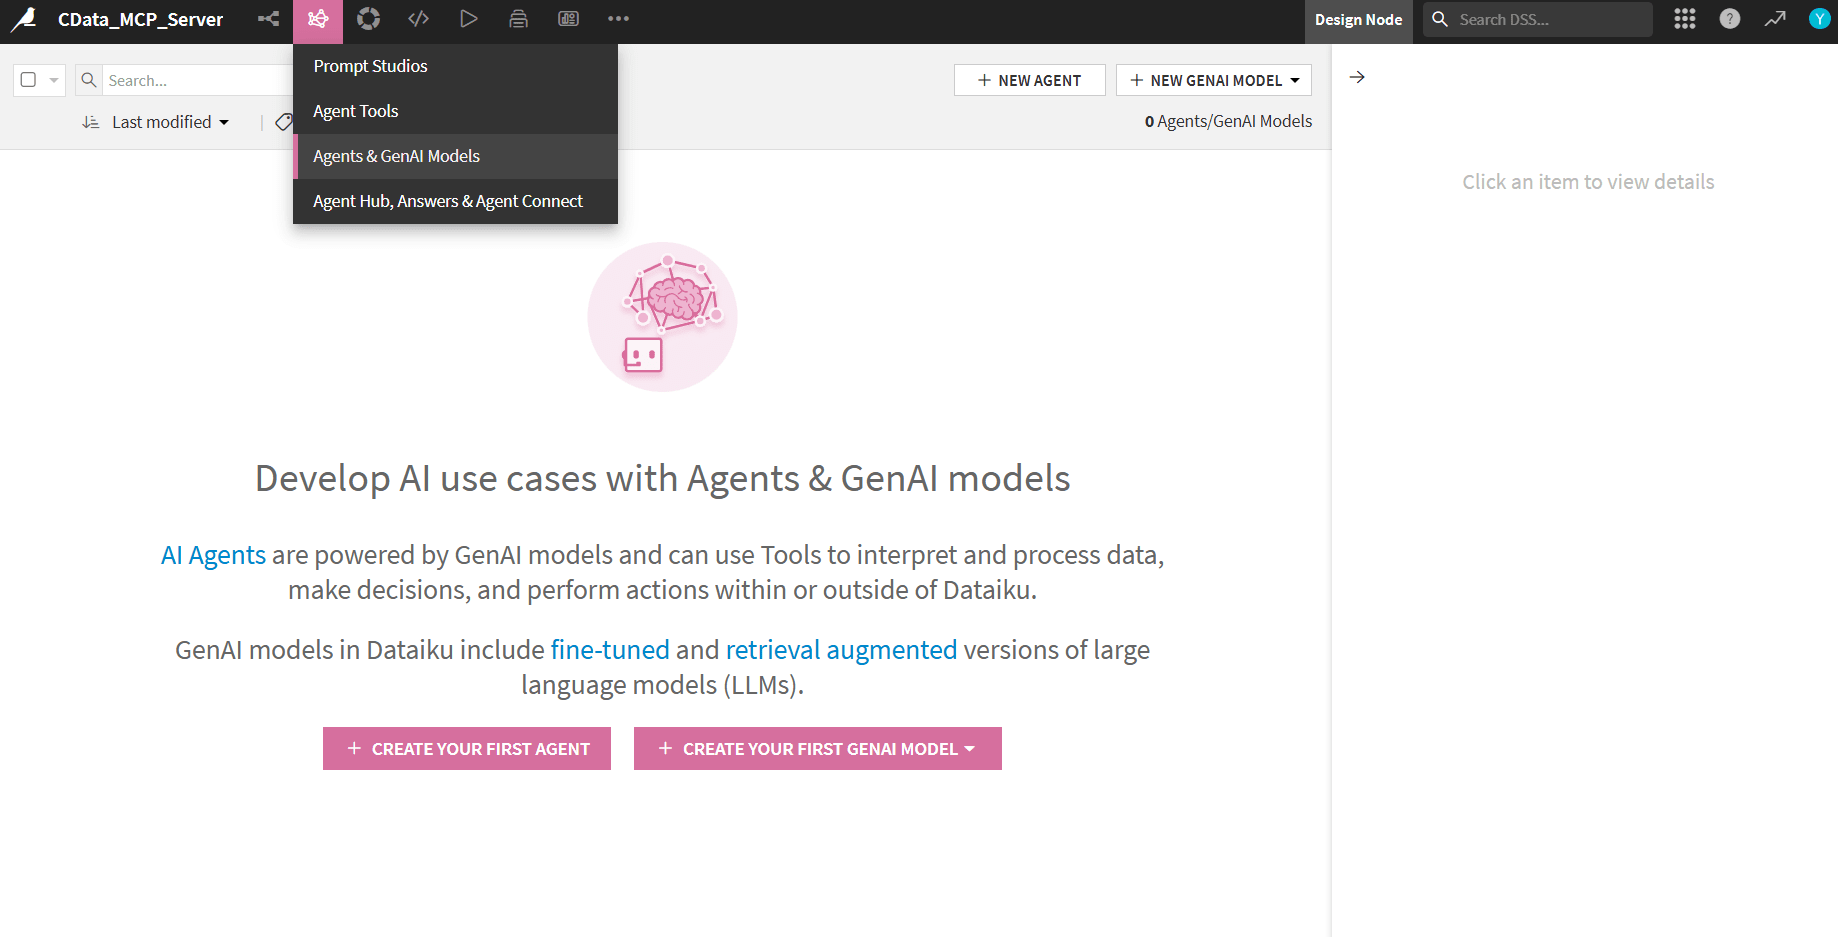
- Go to Agents & GenAI Models and click Create your first agent
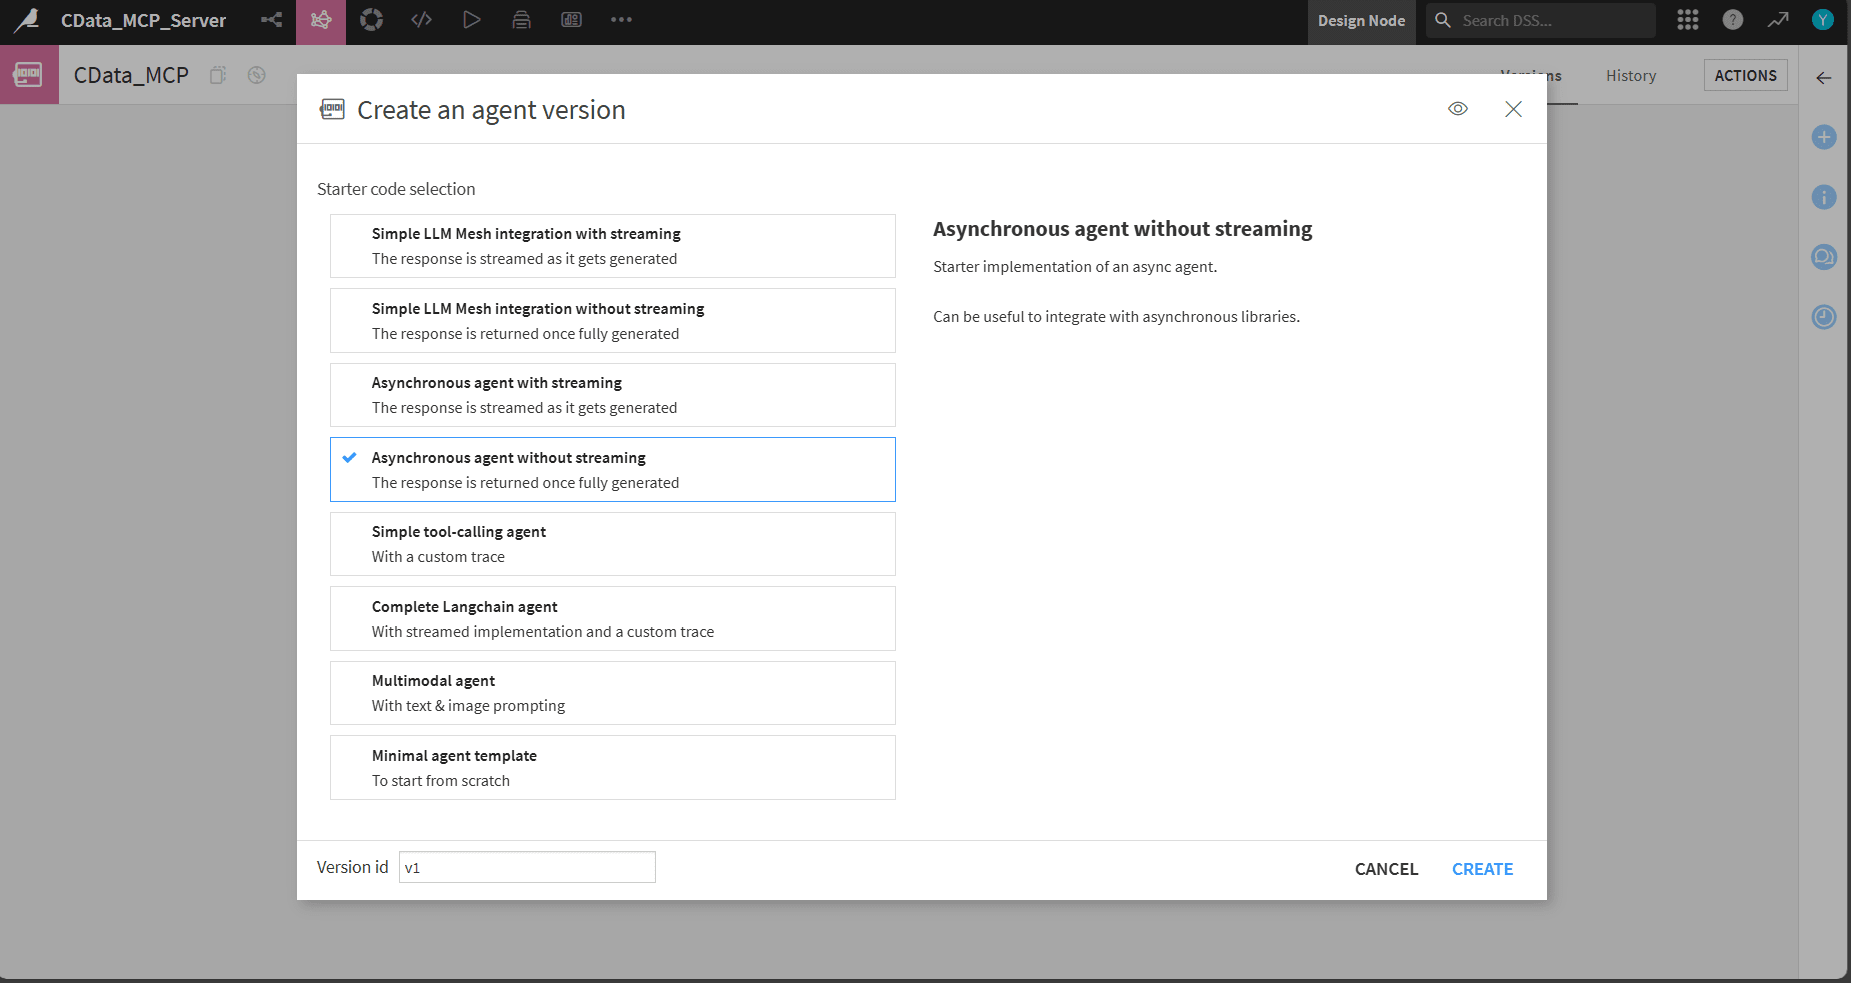
- Choose Code agent, name it, and for Agent version select Asynchronous agent without streaming
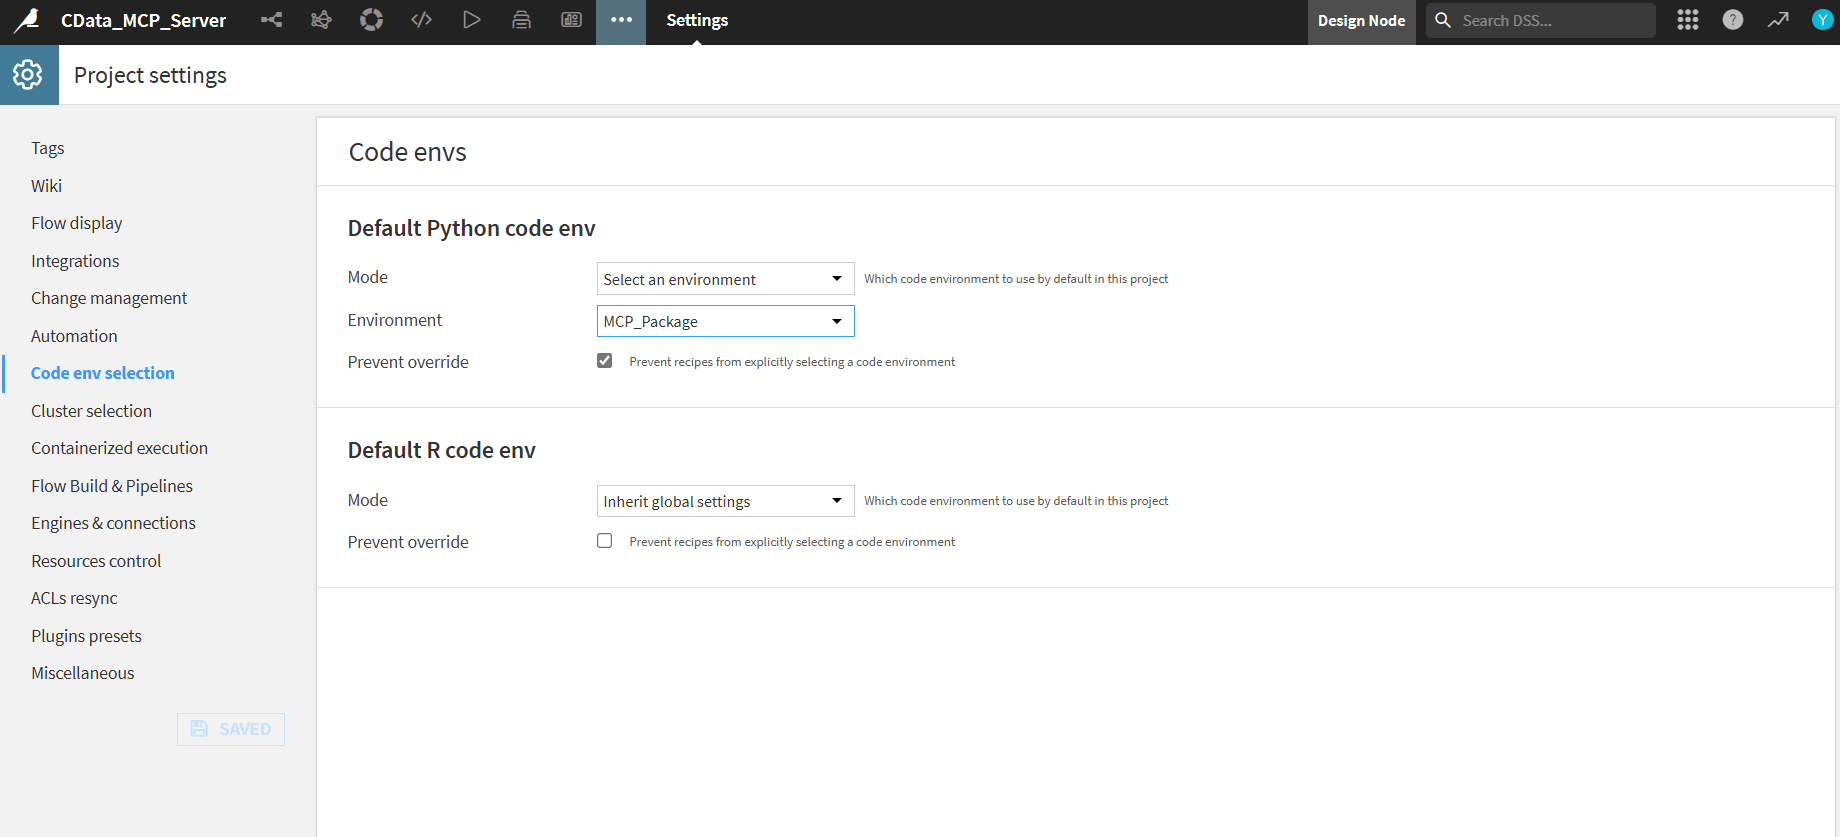
- From the tab above select Settings. In Code env selection set Default Python code env to the environment you created (for example, MCP_Package)
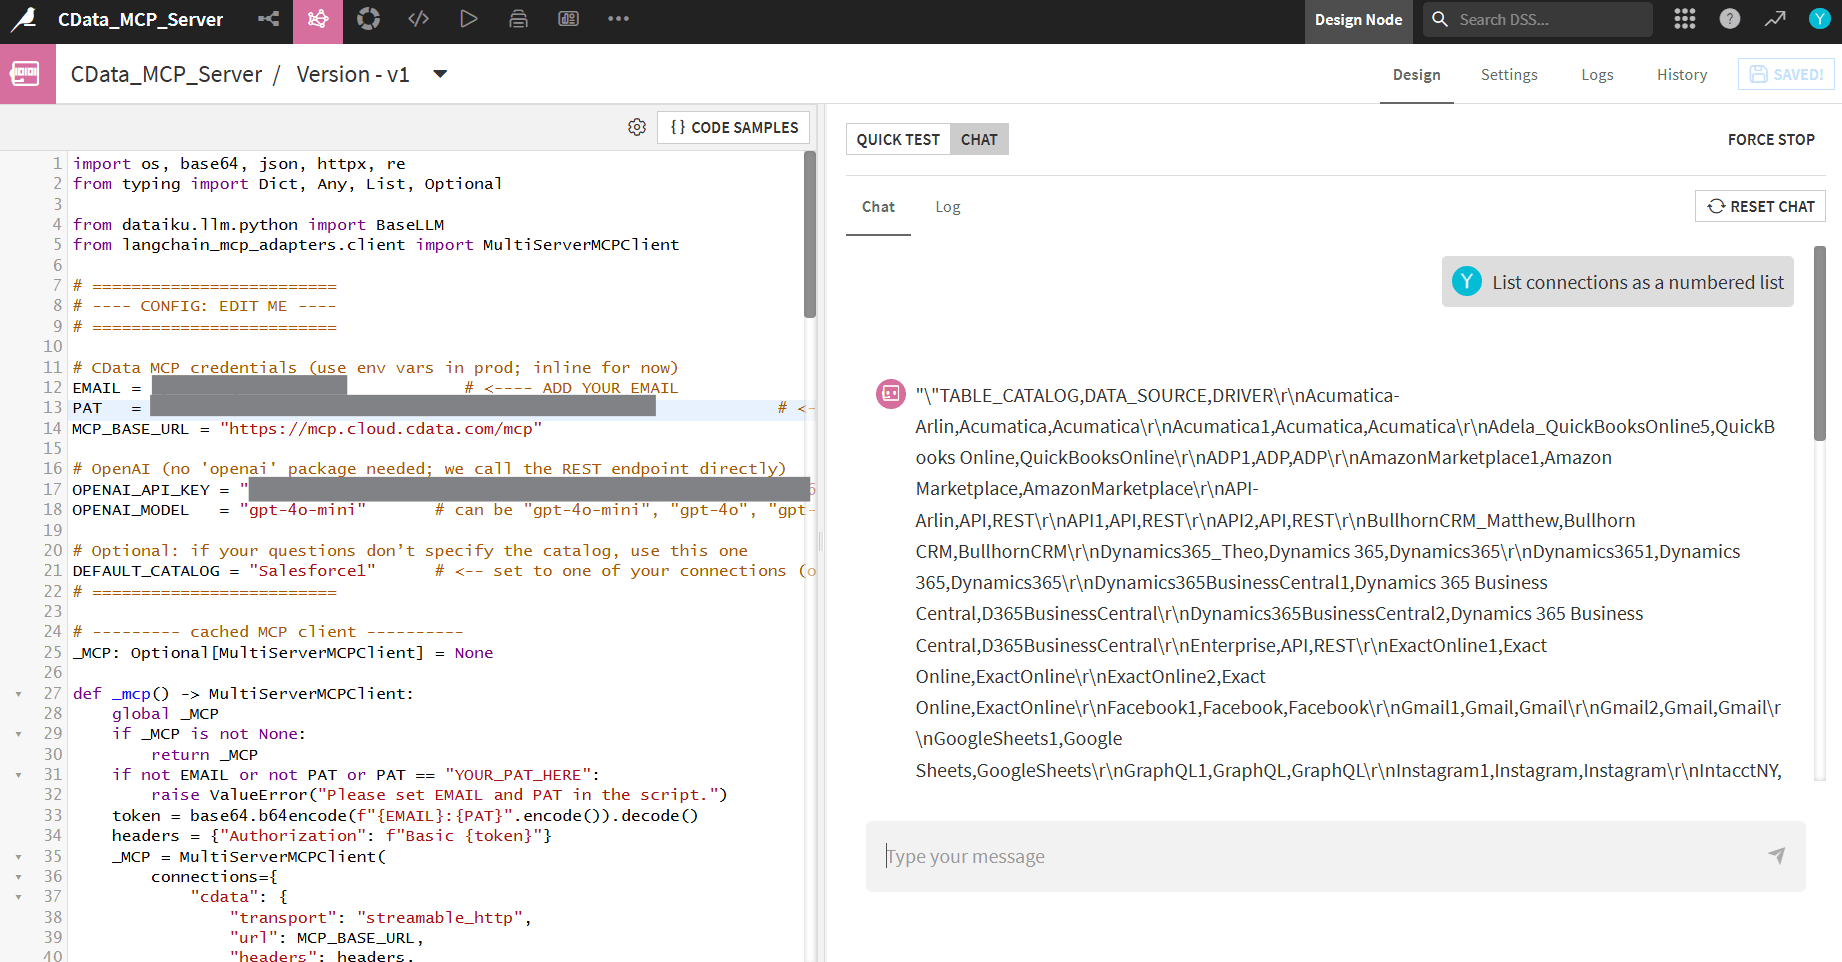
- Return to the Agent Design tab and paste the following code. Replace EMAIL, and PAT with your values
- Open Quick Test on the right side panel
- Paste the JSON code and click Run test
import os
import base64
from typing import Dict, Any, List

from dataiku.llm.python import BaseLLM
from langchain_mcp_adapters.client import MultiServerMCPClient

# ---------- Persistent MCP client (cached between calls) ----------
_MCP_CLIENT = None

def _get_mcp_client() -> MultiServerMCPClient:
    """Create (or reuse) a MultiServerMCPClient to CData Cloud MCP."""
    global _MCP_CLIENT
    if _MCP_CLIENT is not None:
        return _MCP_CLIENT

    # Set creds via env/project variables ideally
    EMAIL = os.getenv("CDATA_EMAIL", "YOUR_EMAIL")
    PAT   = os.getenv("CDATA_PAT",   "YOUR_PAT")
    BASE_URL = "https://mcp.cloud.cdata.com/mcp"

    if not EMAIL or PAT == "YOUR_PAT":
        raise ValueError("Set CDATA_EMAIL and CDATA_PAT as env variables or inline in the code.")

    token = base64.b64encode(f"{EMAIL}:{PAT}".encode()).decode()
    headers = {"Authorization": f"Basic {token}"}

    _MCP_CLIENT = MultiServerMCPClient(
        connections={
            "cdata": {
                "transport": "streamable_http",
                "url": BASE_URL,
                "headers": headers,
            }
        }
    )
    return _MCP_CLIENT


def _pick_tool(tools, names: List[str]):
    L = [n.lower() for n in names]
    return next((t for t in tools if t.name.lower() in L), None)


async def _route(prompt: str) -> str:
    """
    Simple intent router:
      - 'list connections' / 'list catalogs' -> getCatalogs
      - 'sql: ...' or 'query: ...' -> queryData
      - otherwise -> help text
    """
    client = _get_mcp_client()
    tools = await client.get_tools()

    p = prompt.strip()
    low = p.lower()

    # 1) List connections (catalogs)
    if "list connections" in low or "list catalogs" in low:
        t = _pick_tool(tools, ["getCatalogs", "listCatalogs"])
        if not t:
            return "No 'getCatalogs' tool found on the MCP server."
        res = await t.ainvoke({})
        return str(res)[:4000]

    # 2) Run SQL
    if low.startswith("sql:") or low.startswith("query:"):
        sql = p.split(":", 1)[1].strip()
        t = _pick_tool(tools, ["queryData", "sqlQuery", "runQuery", "query"])
        if not t:
            return "No query-capable tool (queryData/sqlQuery) found on the MCP server."
        try:
            res = await t.ainvoke({"query": sql})
            return str(res)[:4000]
        except Exception as e:
            return f"Query failed: {e}"

    # 3) Help
    return (
        "Connected to CData MCP

"
        "Say **'list connections'** to view available sources, or run a SQL like:
"
        "  sql: SELECT * FROM [Salesforce1].[SYS].[Connections] LIMIT 5

"
        "Remember to use bracket quoting for catalog/schema/table names."
    )


class MyLLM(BaseLLM):
    async def aprocess(self, query: Dict[str, Any], settings: Dict[str, Any], trace: Any):
        # Extract last user message from the Quick Test payload
        prompt = ""
        try:
            prompt = (query.get("messages") or [])[-1].get("content", "")
        except Exception:
            prompt = ""

        try:
            reply = await _route(prompt)
        except Exception as e:
            reply = f"Error: {e}"

        # The template expects a dict with a 'text' key
        return {"text": reply}
Run a Quick Test
{
   "messages": [
      {
         "role": "user",
         "content": "list connections"
      }
   ],
   "context": {}
}
Chat with your Agent
Switch to the Chat tab and try prompting like, "List all connections". The chat output will show a list of connection catalogs.
Get CData Connect AI
To access hundreds of SaaS, Big Data, and NoSQL sources from your AI agents, try CData Connect AI today.