


Connect to PingOne Data from AWS Glue
Amazon AWS Glue is an ETL service designed to simplify the preparation and loading of data for storage and analytics purposes. By employing Glue Studio and CData Connect AI, you have the capability to construct ETL jobs without the need for coding or with minimal coding. These jobs can interact with data through the CData Glue Connector. This article provides a step-by-step guide on connecting to PingOne via CData Connect AI and utilizing the CData Glue Connector to establish and execute an AWS Glue job that operates with real-time PingOne data.
CData Connect AI offers a seamless cloud-to-cloud interface tailored for PingOne, simplifying the direct access to live PingOne data within AWS Glue jobs. All you need to do is employ the AWS Glue Connector and choose a table (or craft your custom SQL query). With its inherent optimized data processing capabilities, CData Connect AI efficiently channels all supported query operations, including filters, JOINs, and more, straight to PingOne. This harnesses server-side processing to promptly retrieve PingOne data for your ETL jobs.
This setup requires a CData Connect AI instance and the CData AWS Glue Connector. To get started, sign up a free trial of Connect AI and subscribe to the free Glue Connector for Connect AI.
Configure PingOne Connectivity for AWS Glue
Connectivity to PingOne from AWS Glue is made possible through CData Connect AI. To work with PingOne data from AWS Glue, we start by creating and configuring a PingOne connection.
- Log into Connect AI, click Sources, and then click Add Connection
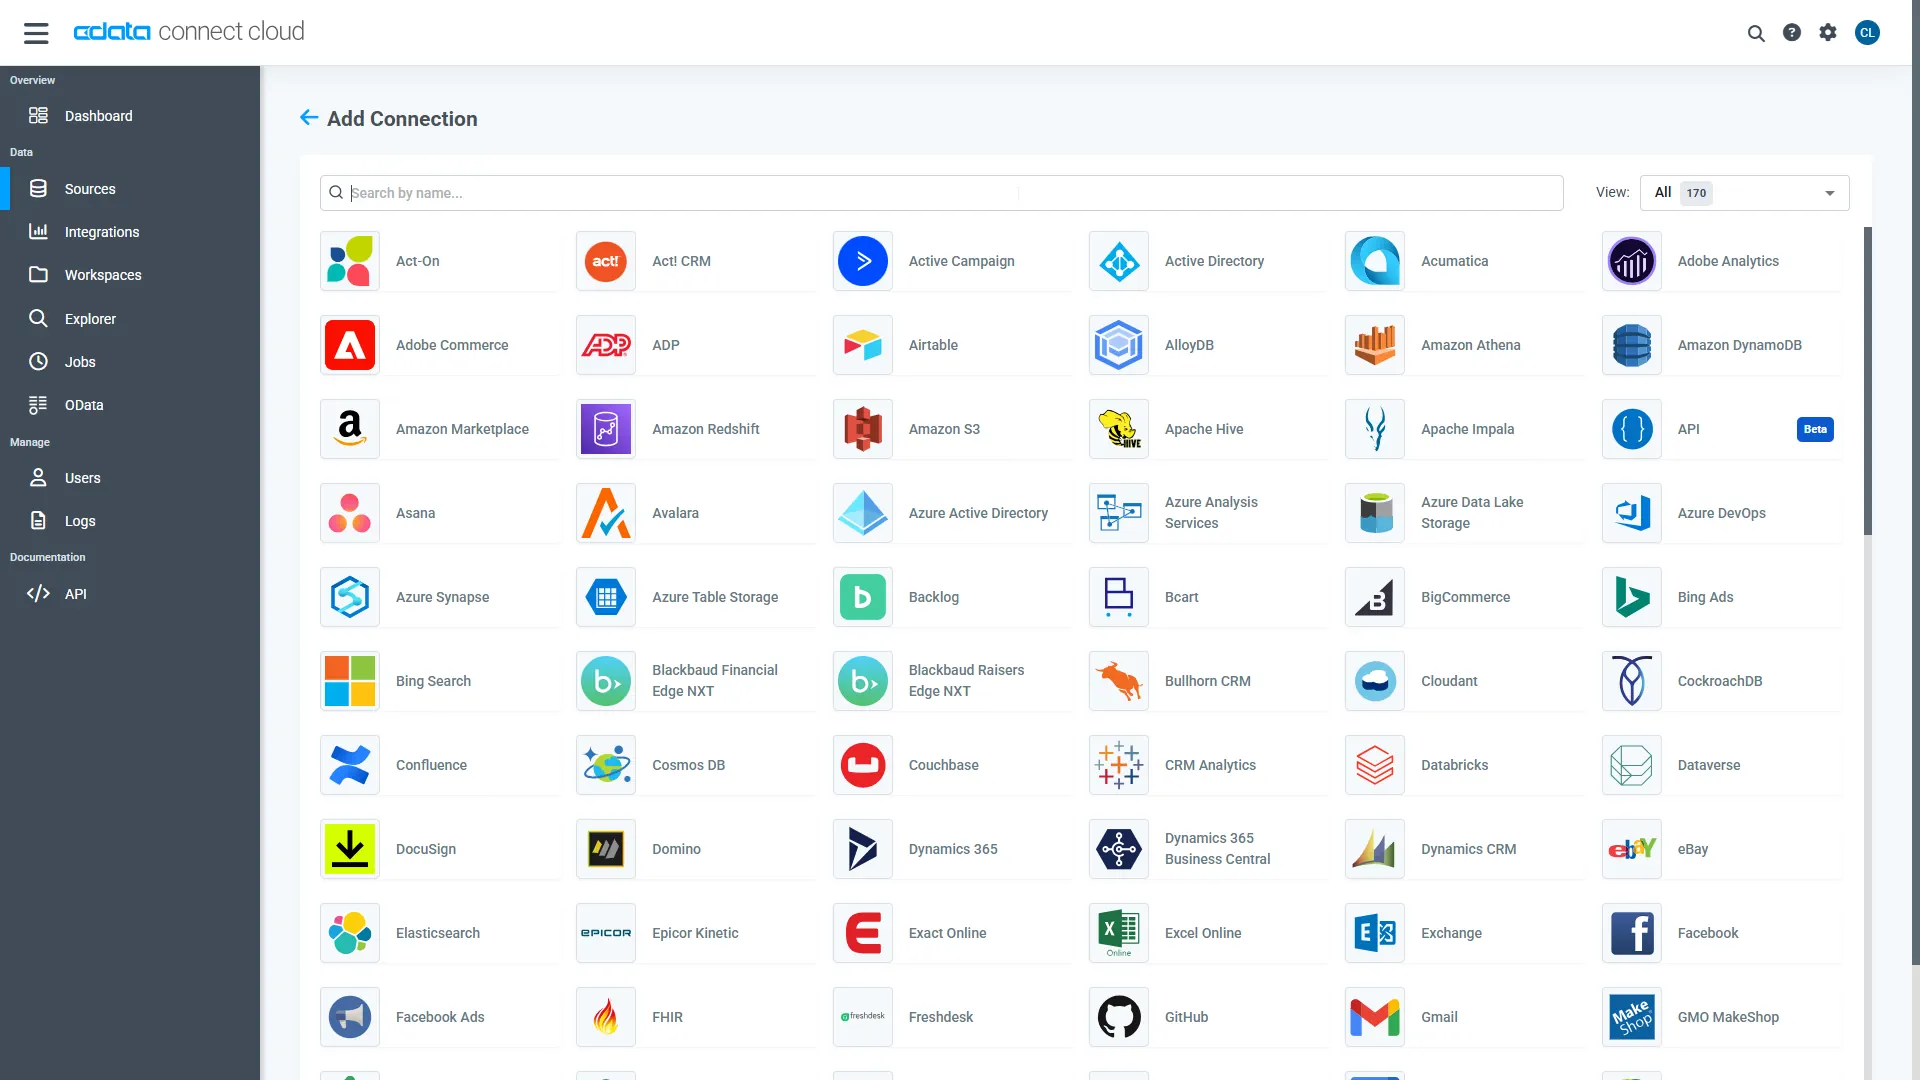
- Select "PingOne" from the Add Connection panel
-
Enter the necessary authentication properties to connect to PingOne.
To connect to PingOne, configure these properties:
- Region: The region where the data for your PingOne organization is being hosted.
- AuthScheme: The type of authentication to use when connecting to PingOne.
- Either WorkerAppEnvironmentId (required when using the default PingOne domain) or AuthorizationServerURL, configured as described below.
Configuring WorkerAppEnvironmentId
WorkerAppEnvironmentId is the ID of the PingOne environment in which your Worker application resides. This parameter is used only when the environment is using the default PingOne domain (auth.pingone). It is configured after you have created the custom OAuth application you will use to authenticate to PingOne, as described in Creating a Custom OAuth Application in the Help documentation.
First, find the value for this property:
- From the home page of your PingOne organization, move to the navigation sidebar and click Environments.
- Find the environment in which you have created your custom OAuth/Worker application (usually Administrators), and click Manage Environment. The environment's home page displays.
- In the environment's home page navigation sidebar, click Applications.
- Find your OAuth or Worker application details in the list.
-
Copy the value in the Environment ID field.
It should look similar to:
WorkerAppEnvironmentId='11e96fc7-aa4d-4a60-8196-9acf91424eca'
Now set WorkerAppEnvironmentId to the value of the Environment ID field.
Configuring AuthorizationServerURL
AuthorizationServerURL is the base URL of the PingOne authorization server for the environment where your application is located. This property is only used when you have set up a custom domain for the environment, as described in the PingOne platform API documentation. See Custom Domains.
Authenticating to PingOne with OAuth
PingOne supports both OAuth and OAuthClient authentication. In addition to performing the configuration steps described above, there are two more steps to complete to support OAuth or OAuthCliet authentication:
- Create and configure a custom OAuth application, as described in Creating a Custom OAuth Application in the Help documentation.
- To ensure that the driver can access the entities in Data Model, confirm that you have configured the correct roles for the admin user/worker application you will be using, as described in Administrator Roles in the Help documentation.
- Set the appropriate properties for the authscheme and authflow of your choice, as described in the following subsections.
OAuth (Authorization Code grant)
Set AuthScheme to OAuth.
Desktop Applications
Get and Refresh the OAuth Access Token
After setting the following, you are ready to connect:
- InitiateOAuth: GETANDREFRESH. To avoid the need to repeat the OAuth exchange and manually setting the OAuthAccessToken each time you connect, use InitiateOAuth.
- OAuthClientId: The Client ID you obtained when you created your custom OAuth application.
- OAuthClientSecret: The Client Secret you obtained when you created your custom OAuth application.
- CallbackURL: The redirect URI you defined when you registered your custom OAuth application. For example: https://localhost:3333
When you connect, the driver opens PingOne's OAuth endpoint in your default browser. Log in and grant permissions to the application. The driver then completes the OAuth process:
- The driver obtains an access token from PingOne and uses it to request data.
- The OAuth values are saved in the location specified in OAuthSettingsLocation, to be persisted across connections.
The driver refreshes the access token automatically when it expires.
For other OAuth methods, including Web Applications, Headless Machines, or Client Credentials Grant, refer to the Help documentation.
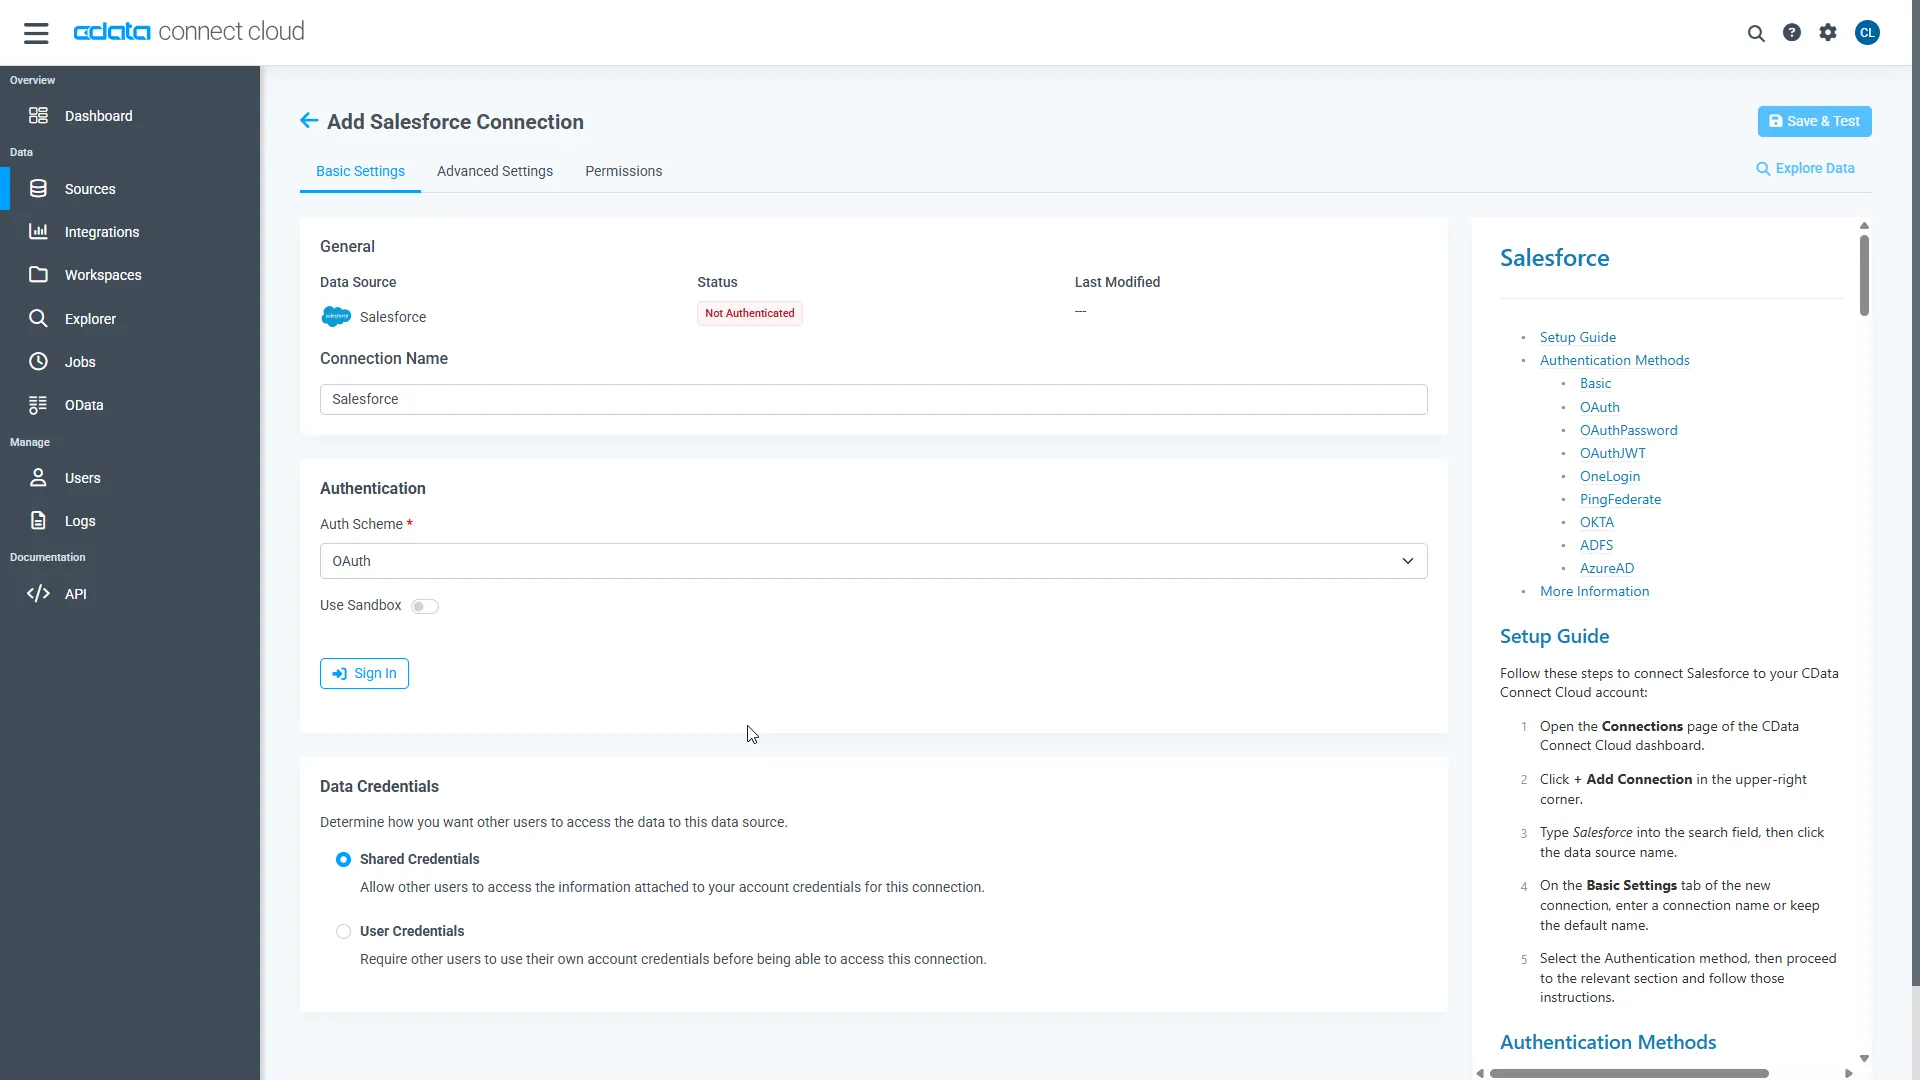
- Click Save & Test
-
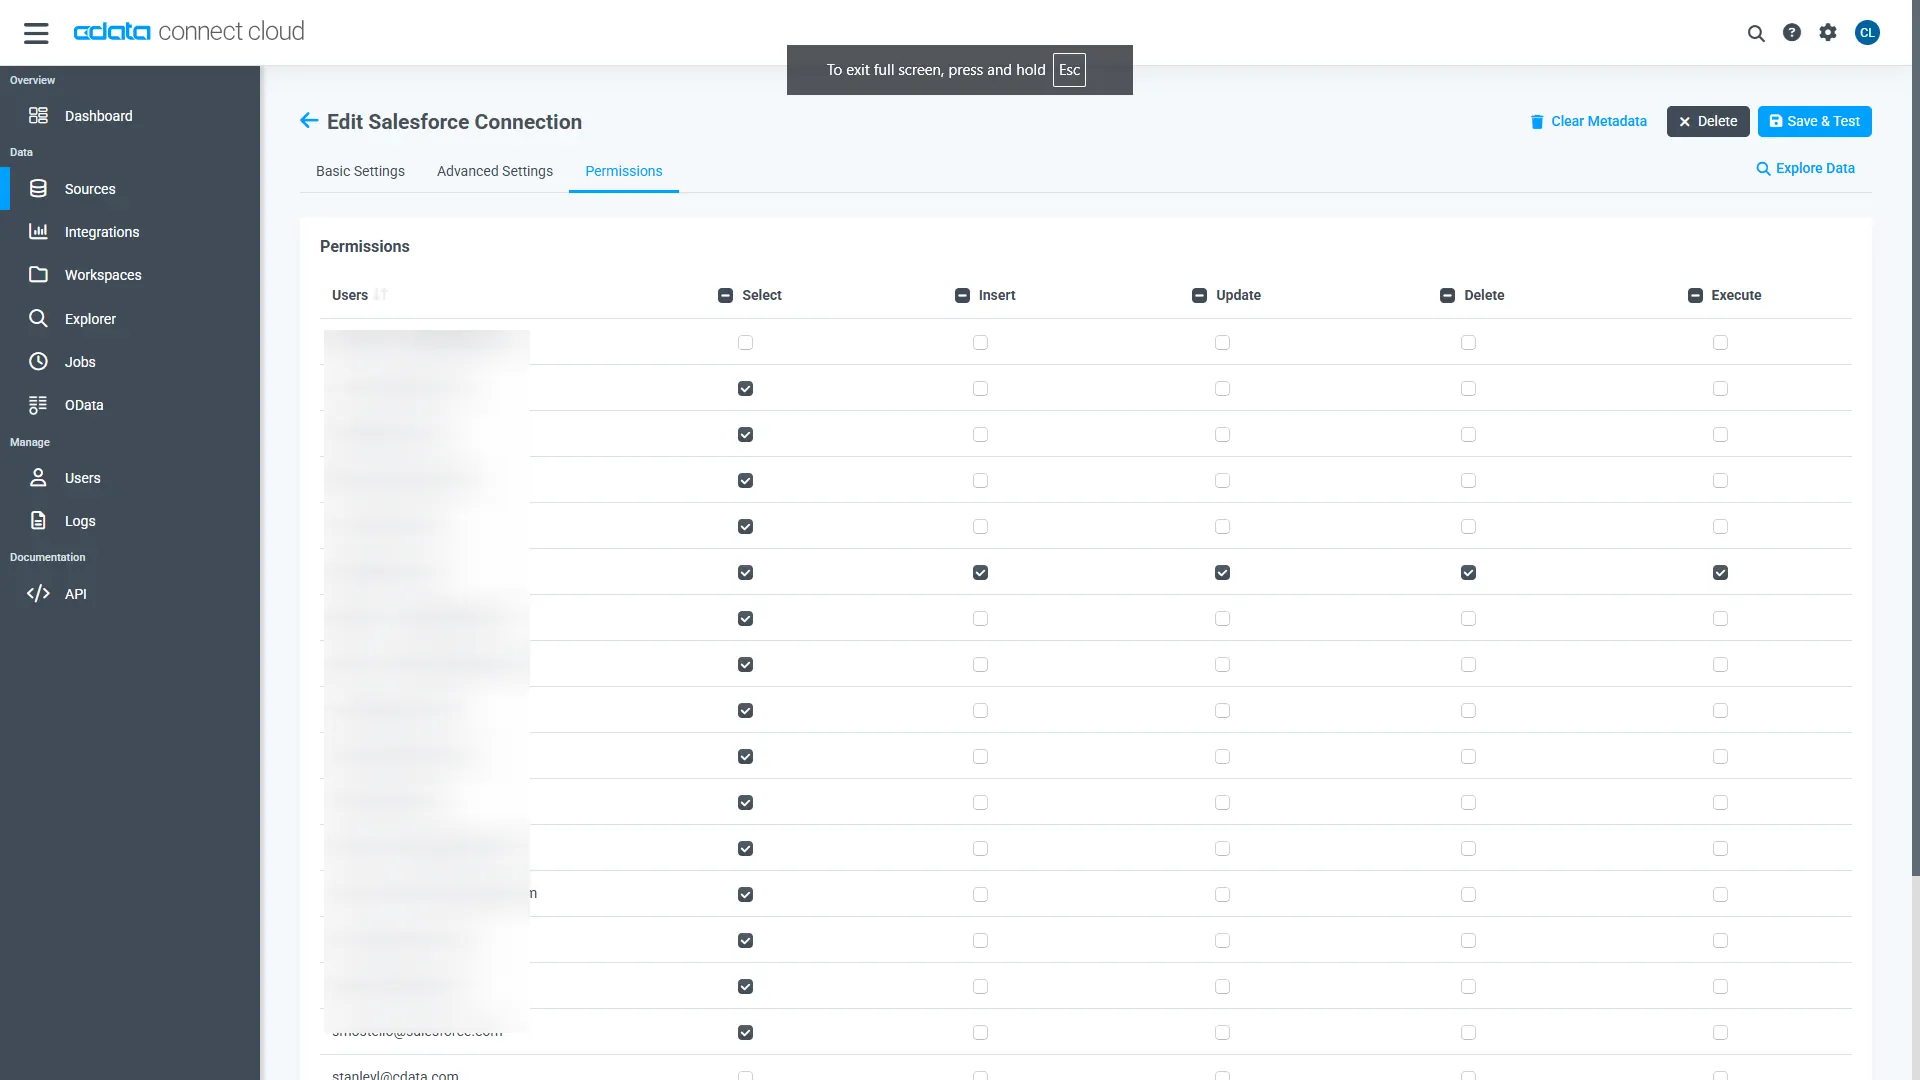
Navigate to the Permissions tab in the Add PingOne Connection page and update the User-based permissions.
Add a Personal Access Token
When connecting to Connect AI through the REST API, the OData API, or the Virtual SQL Server, a Personal Access Token (PAT) is used to authenticate the connection to Connect AI. It is best practice to create a separate PAT for each service to maintain granularity of access.
- Click on the Gear icon () at the top right of the Connect AI app to open the settings page.
- On the Settings page, go to the Access Tokens section and click Create PAT.
-
Give the PAT a name and click Create.
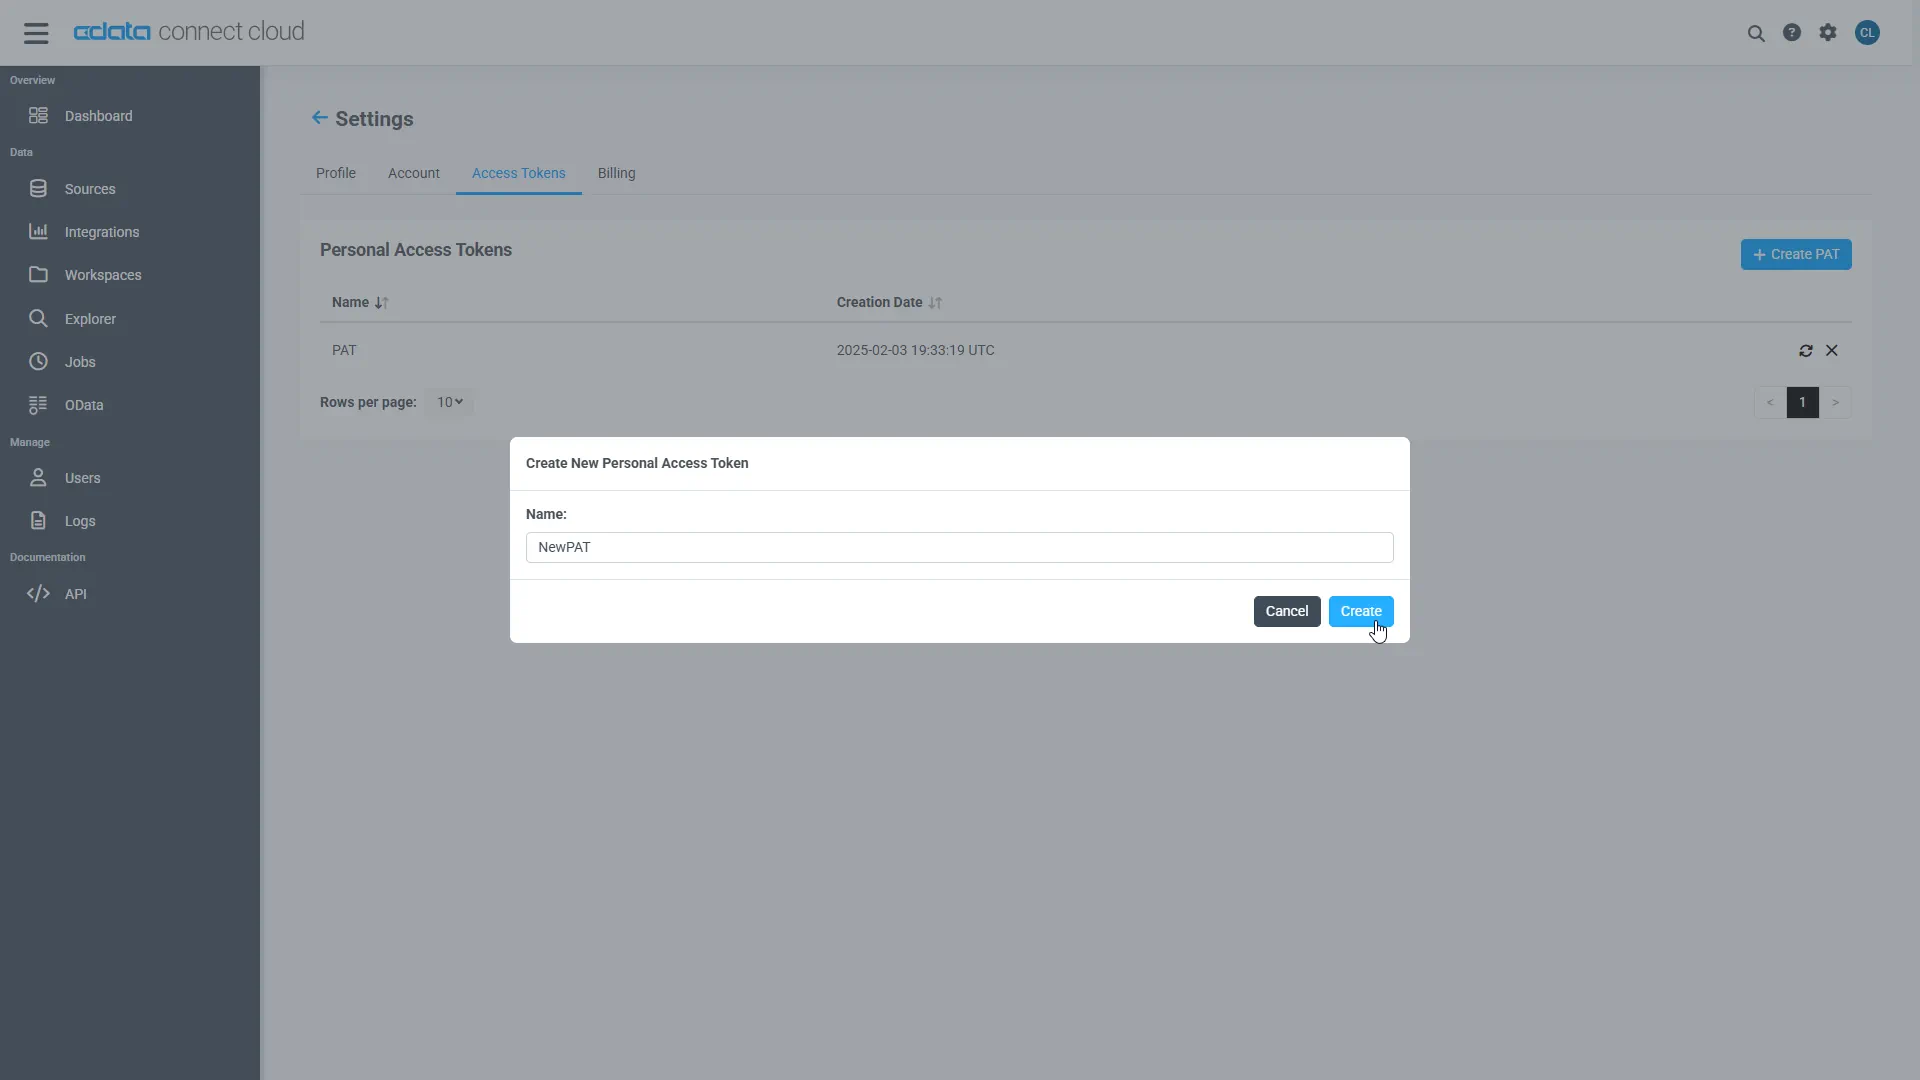
- The personal access token is only visible at creation, so be sure to copy it and store it securely for future use.
With the connection configured and a PAT generated, you are ready to connect to PingOne data from AWS Glue.
Update Permissions for your IAM Role
When you create the AWS Glue job, you specify an AWS Identity and Access Management (IAM) role for the job to use. The role must grant access to all resources used by the job, including Amazon S3 for any sources, targets, scripts, temporary directories, and AWS Glue Data Catalog objects. The role must also grant access to the CData Glue Connector for PingOne from the AWS Glue Marketplace.
The following policies should be added to the IAM role for the AWS Glue job, at a minimum:
- AWSGlueServiceRole (For accessing Glue Studio and Glue Jobs)
- AmazonEC2ContainerRegistryReadOnly (For accessing the CData AWS Glue Connector for PingOne)
If you will be accessing data found in Amazon S3, add:
- AmazonS3FullAccess (For reading from and writing to Amazon S3)
And lastly, if you will be using AWS Secrets Manager to store confidential connection properties (see more below), you will need to add an inline policy similar to the following, granting access to the specific secrets needed for the Glue Job:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "secretsmanager:GetResourcePolicy",
                "secretsmanager:GetSecretValue",
                "secretsmanager:DescribeSecret",
                "secretsmanager:ListSecretVersionIds"
            ],
            "Resource": [
                "arn:aws:secretsmanager:us-west-2:111122223333:secret:aes128-1a2b3c",
                "arn:aws:secretsmanager:us-west-2:111122223333:secret:aes192-4D5e6F",
                "arn:aws:secretsmanager:us-west-2:111122223333:secret:aes256-7g8H9i"
            ]
        }
    ]
}
For more information about granting access to AWS Glue Studio and Glue Jobs, see Setting up IAM Permissions for AWS Glue in the AWS Glue documentation.
For more information about granting access to the Amazon S3 buckets, see Identity and access management in the Amazon Simple Storage Service Developer Guide.
For more information on setting up access control for your secrets, see Authentication and Access Control for AWS Secrets Manager in the AWS Secrets Manager documentation and Limiting Access to Specific Secrets in the AWS Secrets Manager User Guide. The credential retrieved from AWS Secrets Manager (a string of key-value pairs) is used in the JDBC URL used by the CData Glue Connector when connecting to the data source, as shown above.
(Optional) Store PingOne Connection Properties Credentials in AWS Secrets Manager
To safely store and use your connection properties, you can save them in AWS Secrets Manager.
Note: You must host your AWS Glue ETL job and secret in the same region. Cross-region secret retrieval is not supported currently.
- Sign in to the AWS Secrets Manager console.
- On either the service introduction page or the Secrets list page, choose Store a new secret.
- On the Store a new secret page, choose Other type of secret. This option means you must supply the structure and details of your secret.
- You can read more about the required properties to connect to PingOne in the "Activate" section below. Once you know which properties you wish to store, create a key-value pair for each property. For example:
- Username: CData Connect AI user (for example, [email protected])
- Password: CData Connect AI user PAT
For more information about creating secrets, see Creating and Managing Secrets with AWS Secrets Manager in the AWS Secrets Manager User Guide.
- Record the secret name, which is used when configuring the connection in AWS Glue Studio.
Subscribe to the CData Glue Connector for PingOne
To work with the CData Glue Connector for PingOne in AWS Glue Studio, you need to subscribe to the Connector from the AWS Marketplace. If you have already subscribed to the CData Glue Connector for PingOne, you can jump to the next section.
- Navigate to the CData AWS Glue Connector for Connect AI AWS Marketplace listing
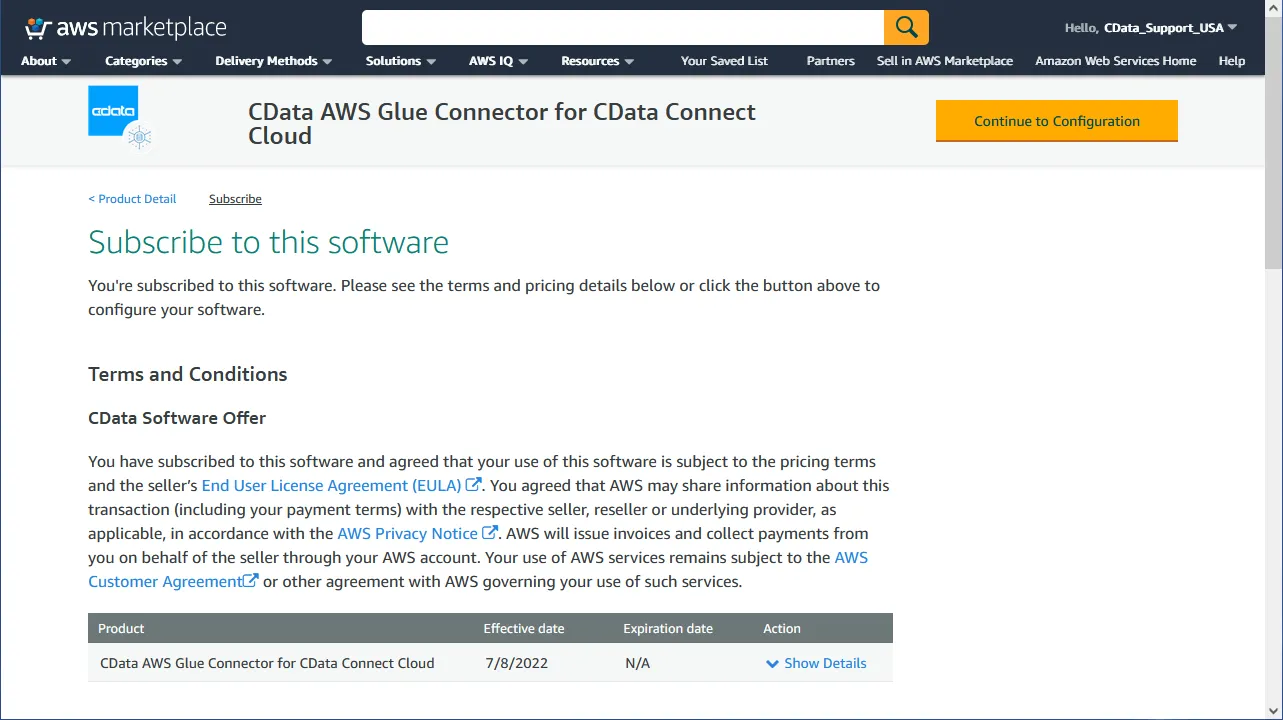
- Click "Continue to Subscribe"
- Accept the terms for the Connector and wait for the request to be processed
- Click "Continue to Configuration"
Activate the CData Glue Connector for Connect AI in Glue Studio
To use the CData Glue Connector for PingOne in AWS Glue, you need to activate the subscribed connector in AWS Glue Studio. The activation process creates a connector object and connection in your AWS account.
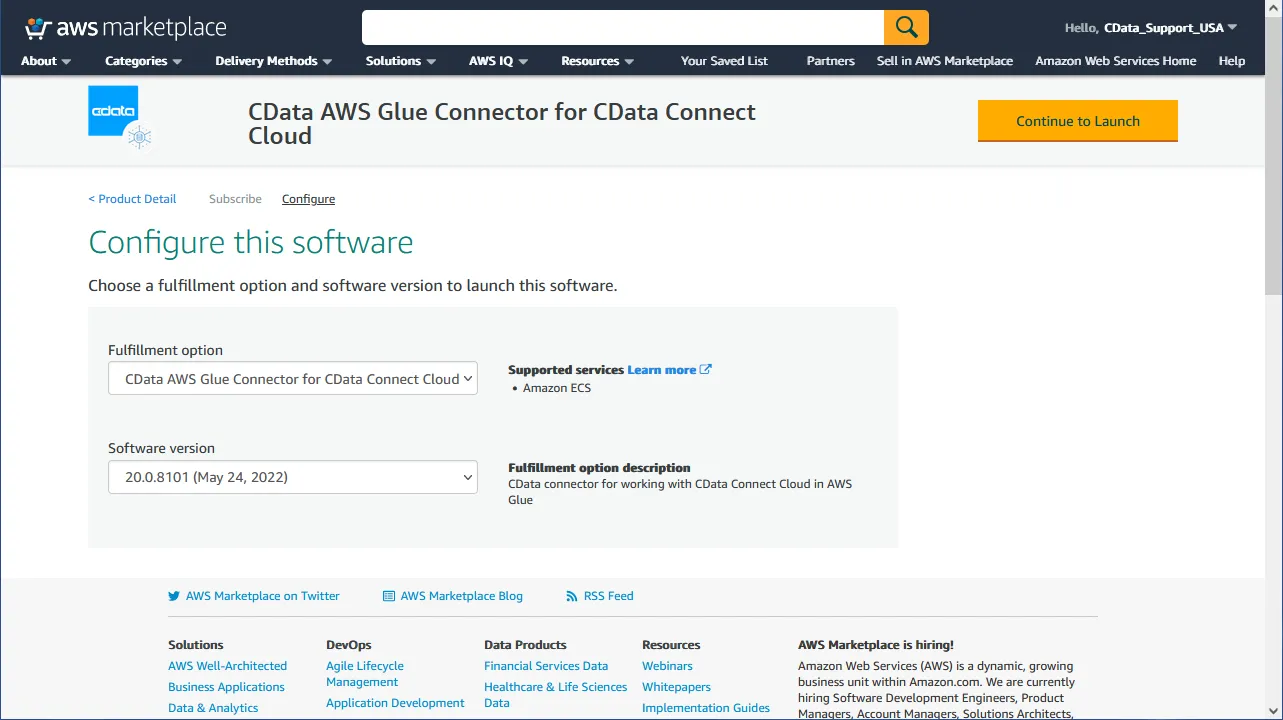
- Once you subscribe to the connector, a new Configure tab shows up in the AWS Marketplace connector page.
- Choose the delivery options and click the "Continue to Launch" button.
- On the launch tab, click "Usage Instructions" and follow the link that appears to create and configure the connection.
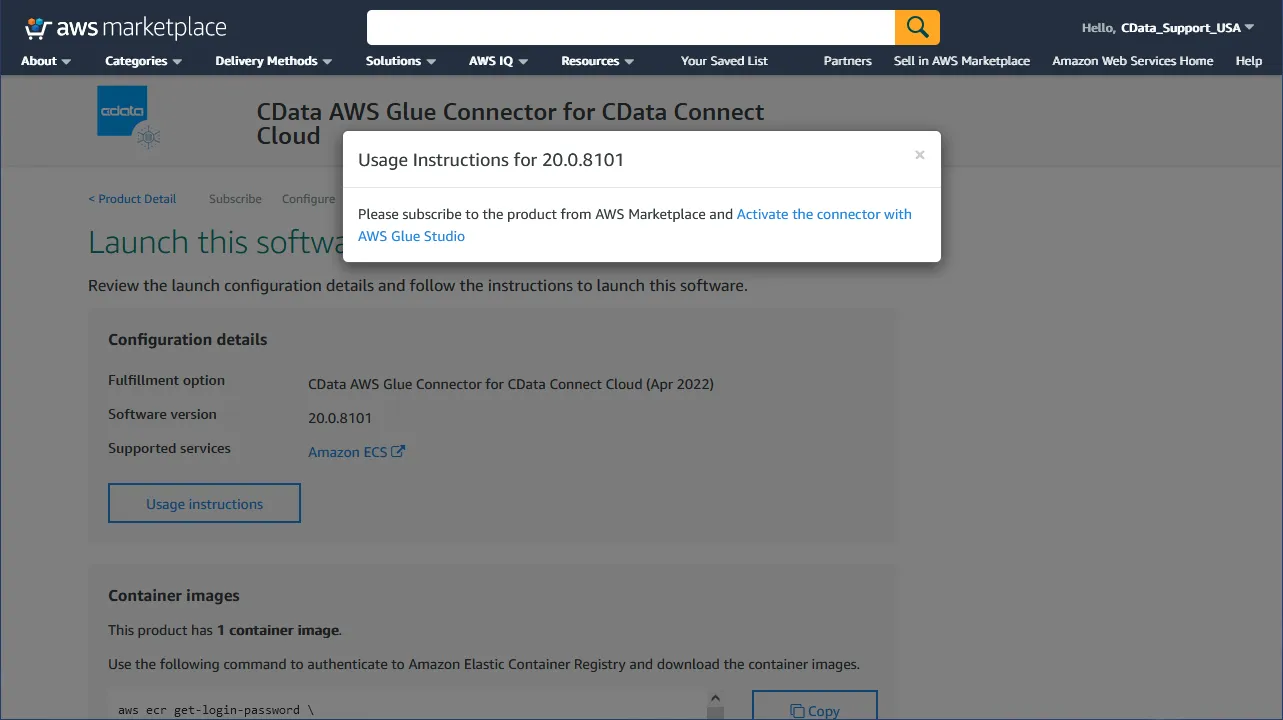
Under Connection access, select the JDBC URL format and configure the connection. Below you will find sample connection string(s) for the JDBC URL format(s) available for PingOne. You can read more about authenticating with PingOne in the Help documentation for the Connector.
If you opted to store properties in the AWS Secrets Manager, leave the placeholder values (e.g. ${Property1}), otherwise, the values you enter in the AWS Glue Connection interface will appear in the (read-only) JDBC URL below the properties.
Connect AI
jdbc:cdata:Connect:AuthScheme=Basic;User=${Username};Password=${Password};defaultCatalog=${defaultCatalog}- ${Username}: set this to your Connect AI user
- ${Password}: set this to your Connect AI PAT
- ${defaultCatalog}: set this to the name of the connection you configured (e.g. PingOne1)
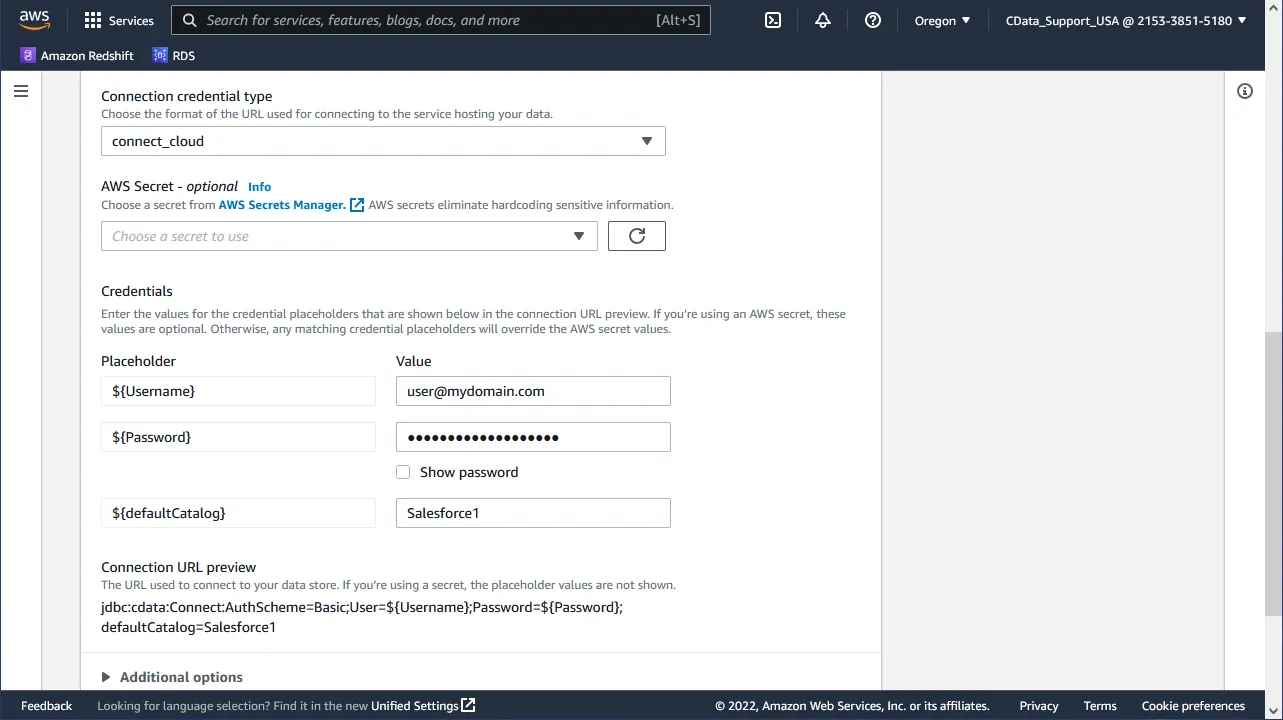
- (Optional): Enable logging for the Connector.
If you want to log the functionality from the CData Glue Connector for PingOne you will need to append two properties to the JDBC URL:
- Logfile: Set this to "STDOUT://"
- Verbosity: Set this to an integer (1-5) for varying depths of logging. 1 is the default, 3 is recommended for most debugging scenarios.
- Configure the Network options and click "Create Connection."
Configure the Amazon Glue Job
Once you have configured a Connection, you can build a Glue Job.
Create a Job that Uses the Connection
- In Glue Studio, under "Your connections," select the connection you created
- Click "Create job"
The visual job editor appears. A new Source node, derived from the connection, is displayed on the Job graph. In the node details panel on the right, the Source Properties tab is selected for user input.
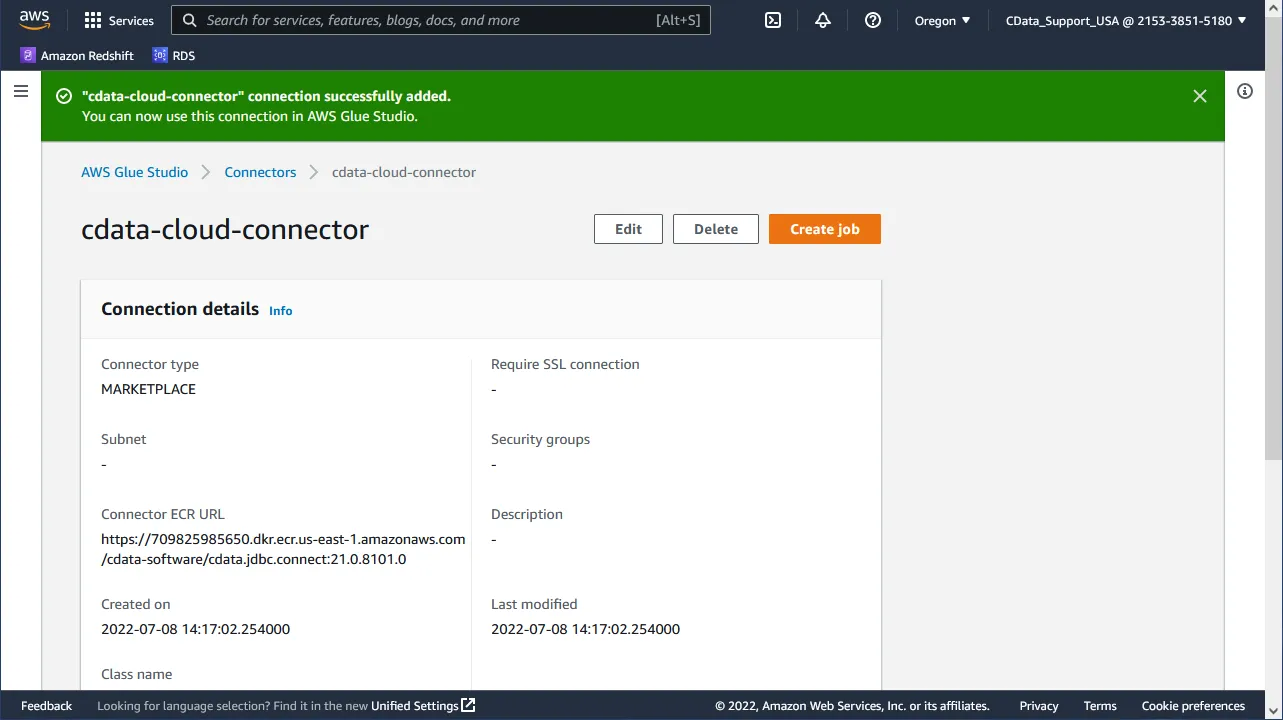
Configure the Source Node properties:
You can configure the access options for your connection to the data source in the Source properties tab. Refer to the AWS Glue Studio documentation for more information. Here we provide a simple walk-through.
- In the visual job editor, make sure the Source node for your connector is selected. Choose the Source properties tab in the node details panel on the right, if it is not already selected.
- The Connection field is populated automatically with the name of the connection associated with the marketplace connector.
- Enter information about the data location in the data source. Provide either a source table name or a query to use to retrieve data from the data source. For example:
SELECT Id, Username FROM PingOne1.PingOne.[CData].[Administrators].Users WHERE EmployeeType = ContractorNOTE: Use the fully qualified domain for the source table, where the name of the connection in CData Connect AI is the catalog name and the name of the data source is the schema. For example: PingOne1.PingOne.[CData].[Administrators].Users.
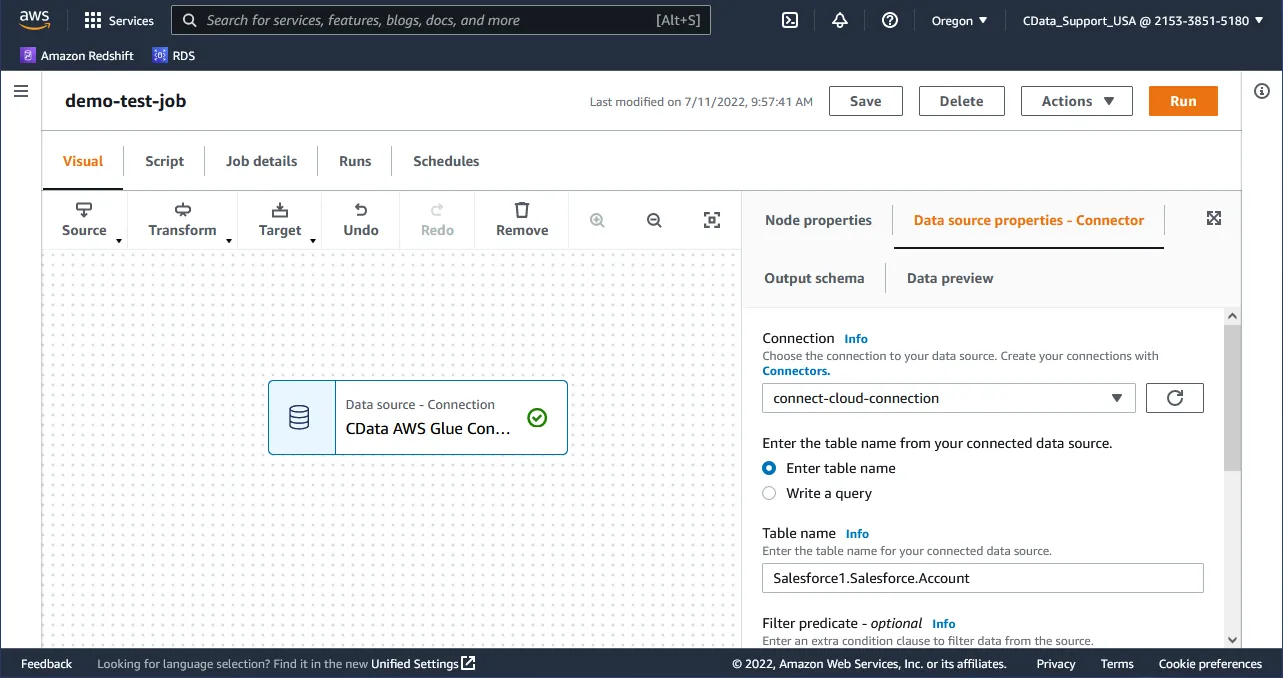
- To pass information from the data source to the transformation nodes, AWS Glue Studio must know the schema of the data. Select "Use Schema Builder" to specify the schema interactively.
- Configure the remaining optional fields as needed. You can configure the following:
- Partitioning information - for parallelizing the read operations from the data source
- Data type mappings - to convert data types used in the source data to the data types supported by AWS Glue
- Filter predicate - to select a subset of the data from the data source
See "Use the Connection in a Glue job using Glue Studio" for more information about these options.
- You can view the schema generated by this node by choosing the Output schema tab in the node properties panel.
Edit, Save, & Run the Job
Edit the job by adding and editing the nodes in the job graph. See Editing ETL jobs in AWS Glue Studio for more information.
After you complete editing the job, enter the job properties.
- Select the Job properties tab above the visual graph editor.
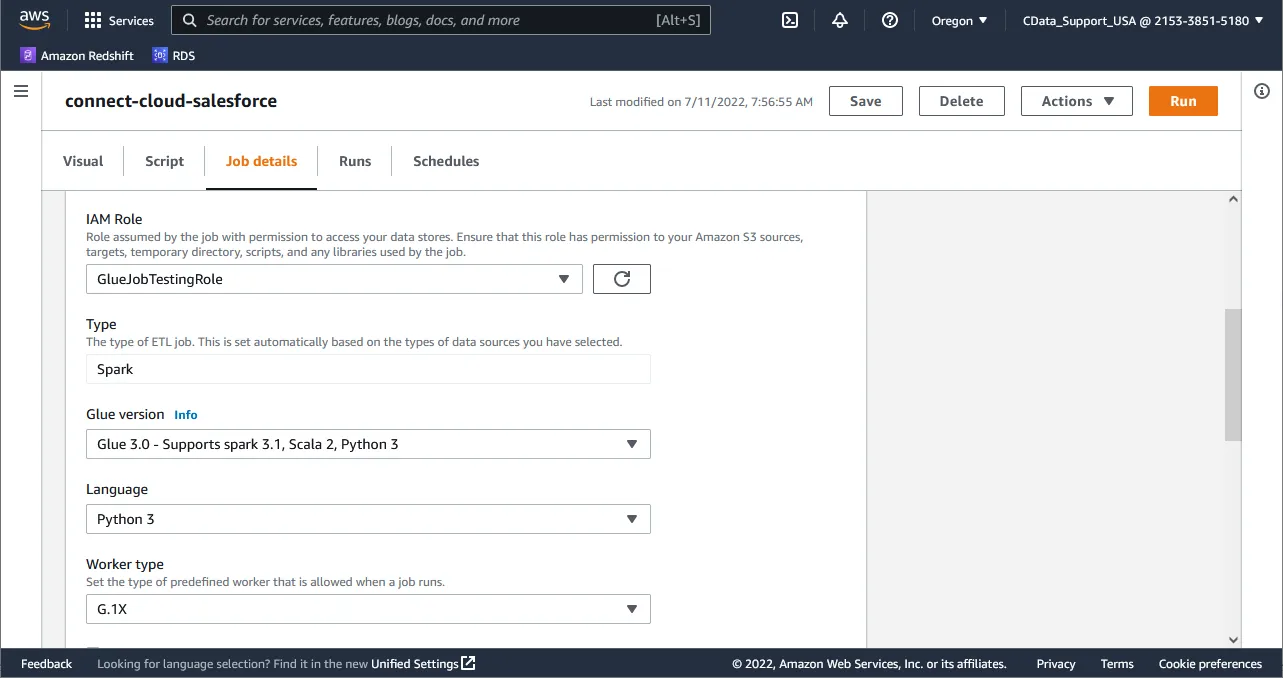
- Configure the following job properties when using custom connectors:
- Name: Provide a job name.
- IAM Role: Choose (or create) an IAM role with the necessary permissions, as described previously.
- Type: Choose "Spark."
- Glue version: Choose "Glue 3.0 - Supports spark 3.1, Scala 2, Python 3."
- Language: Choose "Python 3."
- Use the default values for the other parameters. For more information about job parameters, see "Defining Job Properties" in the AWS Glue Developer Guide.
- At the top of the page, choose "Save."
- A green top banner appears with the message "Successfully created Job."
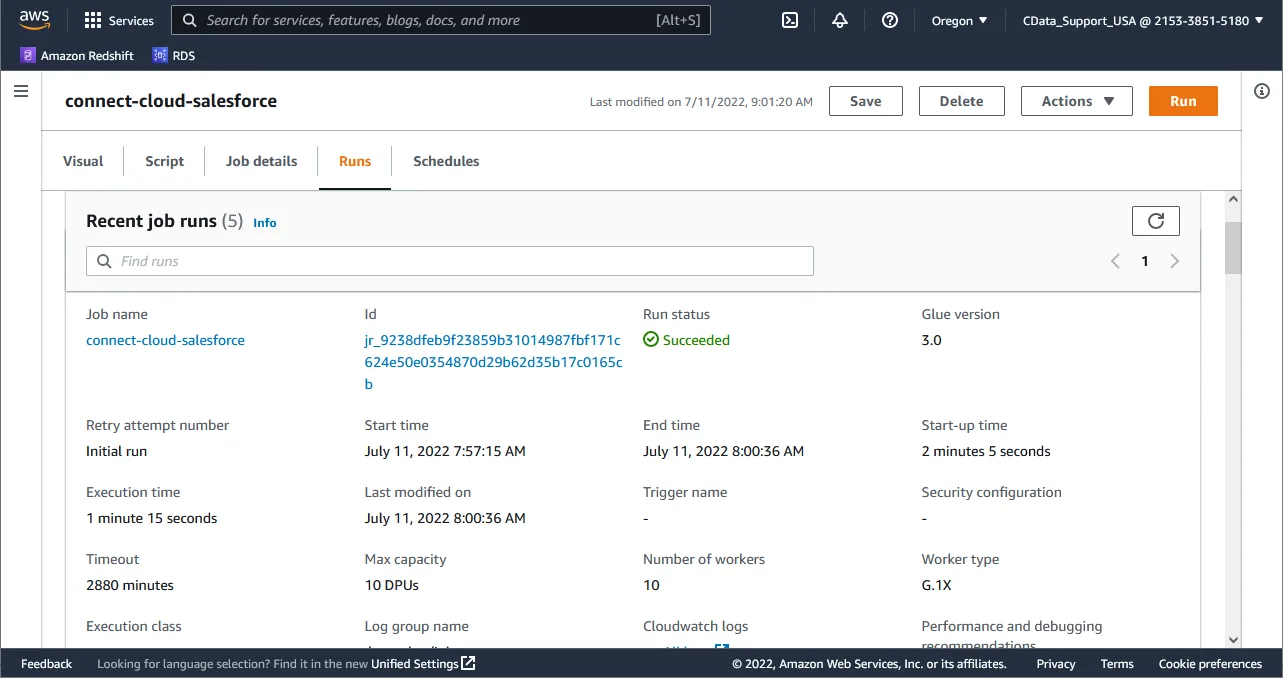
- After you successfully save the job, you can choose "Run" to run the job.
- To view the generated script for the job, choose the "Script" tab at the top of the visual editor. The "Job runs" tab shows the job run history for the job. For more information about job run details, see "View information for recent job runs."
Review the Generated Script
At any point in the job creation, you can click on the Script tab to review the script being created by Glue Studio. If you create a simple job to write PingOne data to an Amazon S3 bucket, your script will look similar to the following:
Sample Script
import sys
from awsglue.transforms import *
from awsglue.utils import getResolvedOptions
from pyspark.context import SparkContext
from awsglue.context import GlueContext
from awsglue.job import Job

args = getResolvedOptions(sys.argv, ["JOB_NAME"])
sc = SparkContext()
glueContext = GlueContext(sc)
spark = glueContext.spark_session
job = Job(glueContext)
job.init(args["JOB_NAME"], args)

# Script generated for node CData AWS Glue Connector for CData Connect
CDataAWSGlueConnectorforCDataConnect_node1 = (
    glueContext.create_dynamic_frame.from_options(
        connection_type="marketplace.jdbc",
        connection_options={
            "tableName": "PingOne1.PingOne.[CData].[Administrators].Users",
            "dbTable": "PingOne1.PingOne.[CData].[Administrators].Users",
            "connectionName": "cdata-cloud-connector",
        },
        transformation_ctx="CDataAWSGlueConnectorforCDataConnect_node1",
    )
)

job.commit()
Using CData Connect AI and AWS Glue Connector for Connect AI in AWS Glue Studio, you can easily create ETL jobs to load PingOne data into an S3 bucket or any other destination.
To get live data access to hundreds of SaaS, Big Data, and NoSQL sources directly from your cloud applications, try CData Connect AI today!