


How to Build an ETL App for Supabase Data in Python with CData Connect AI
The rich ecosystem of Python modules lets you get to work quickly and integrate your systems more effectively. With the CData Connect AI Python SDK and the petl framework, you can build Supabase-connected applications and pipelines for extracting, transforming, and loading Supabase data. This article shows how to connect to Connect AI and use petl to extract, transform, and load Supabase data.
The Connect AI Python SDK (cdata-connect-ai) is a DB-API 2.0 (PEP 249) compliant client, so petl can read directly from the SDK connection with etl.fromdb. There is no driver to install per source: connect with a Personal Access Token and build your pipeline.
Connect to Supabase in Connect AI
CData Connect AI uses a straightforward, point-and-click interface to connect to data sources.
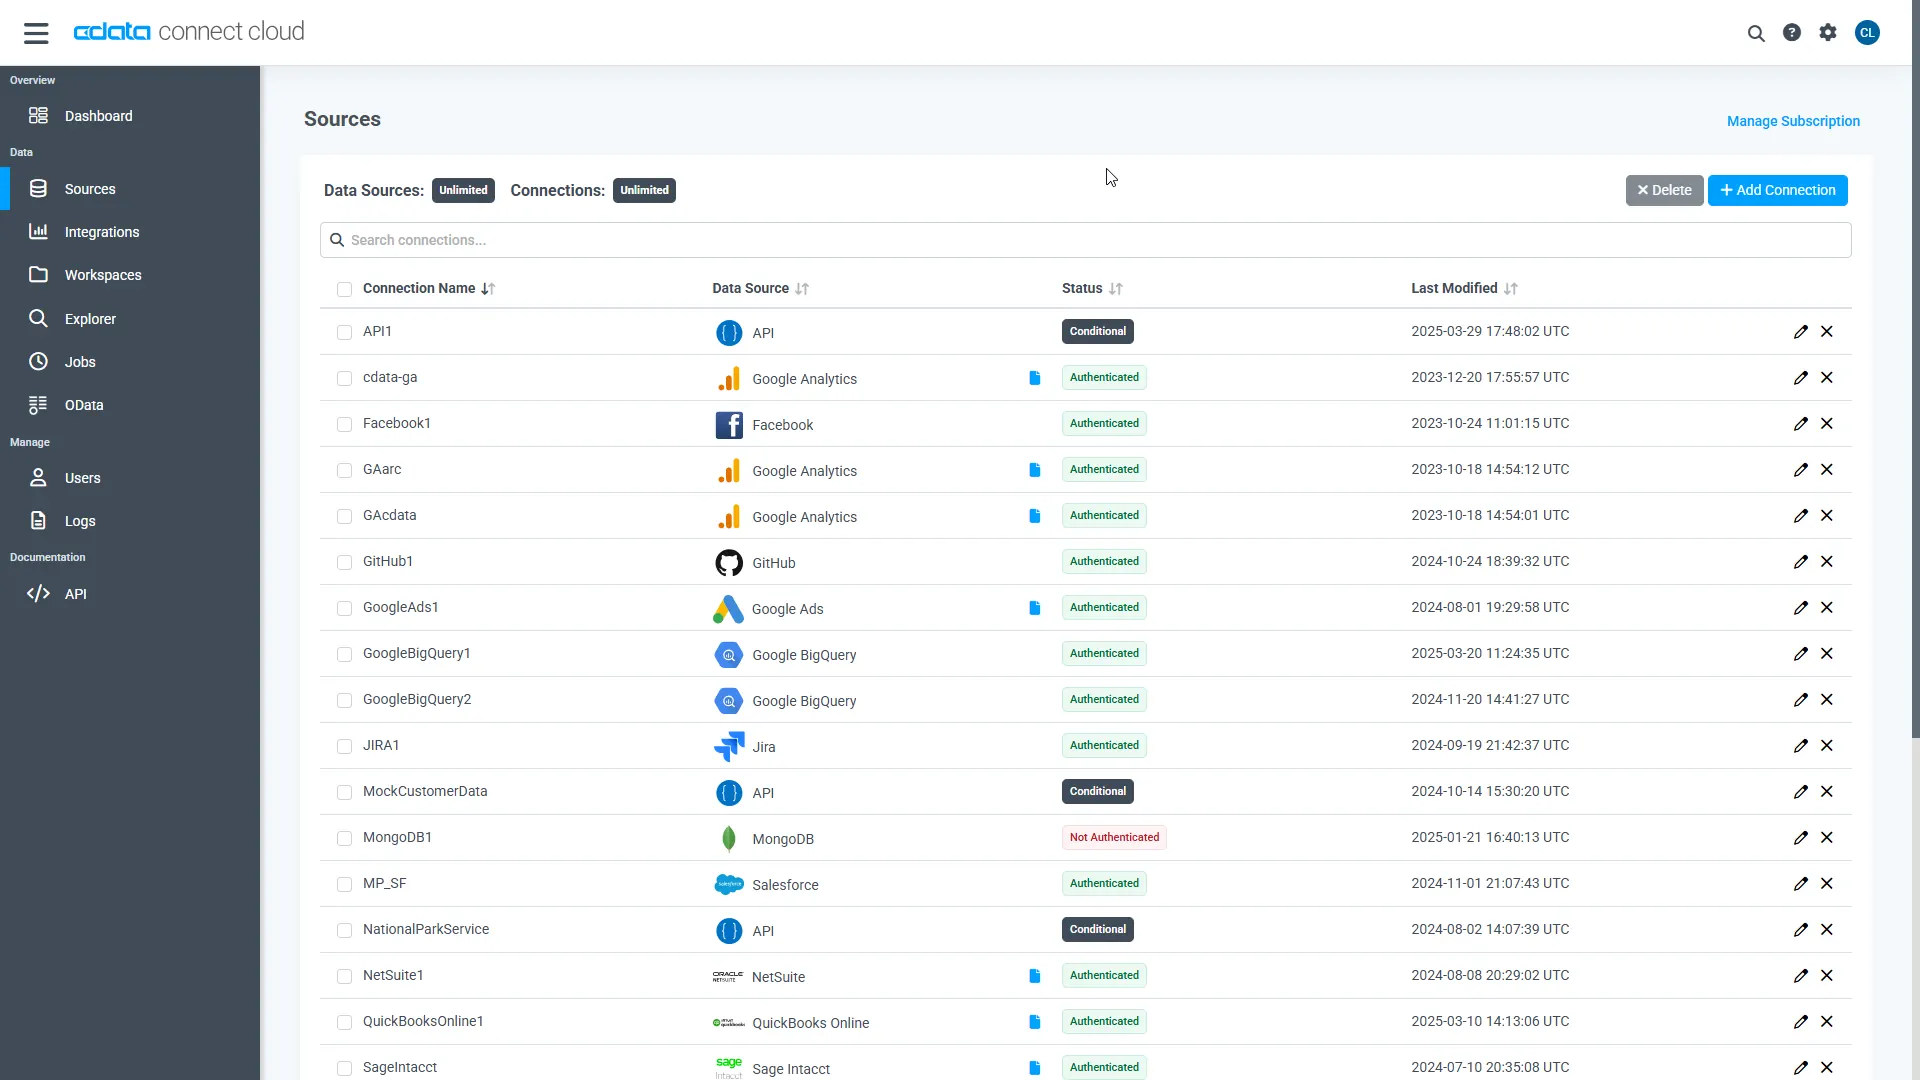
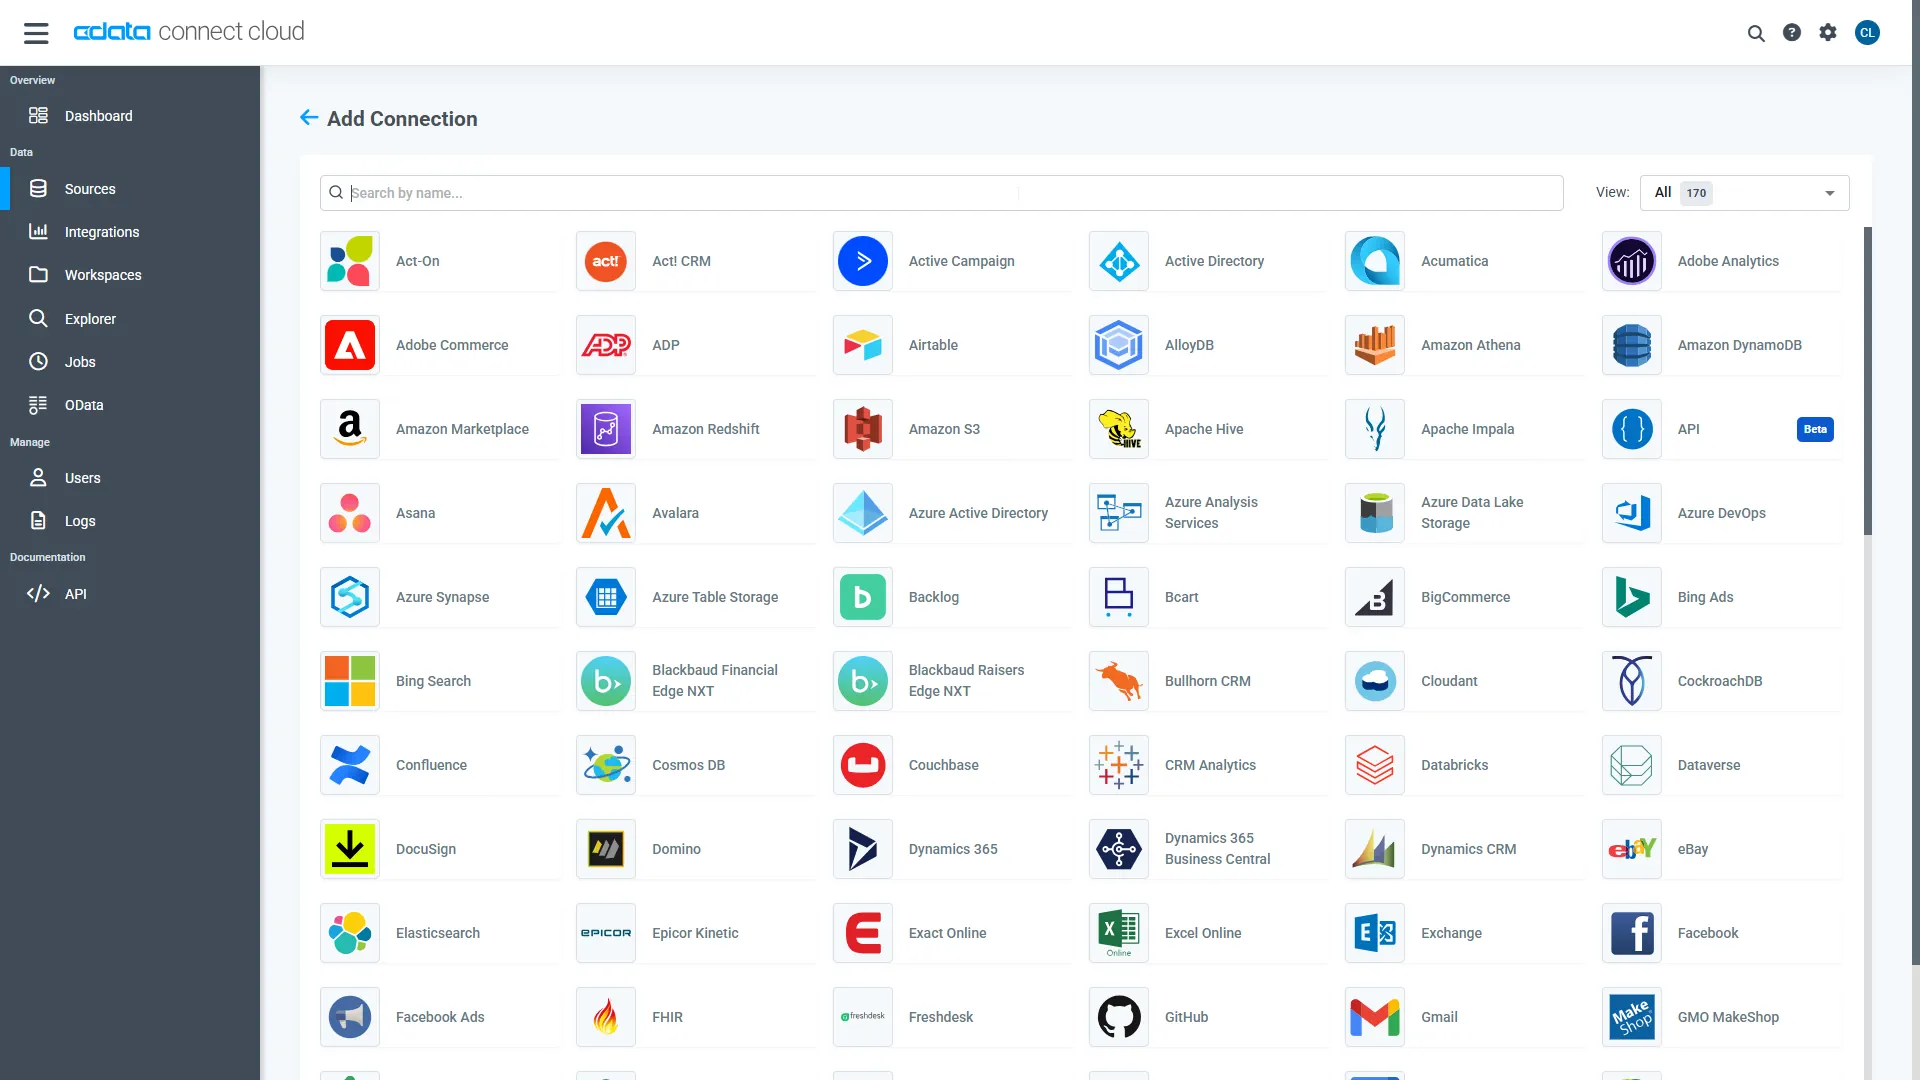
- Log into Connect AI, click Sources, and then click Add Connection
- Select "Supabase" from the Add Connection panel
-
Enter the necessary authentication properties to connect to Supabase.
Start by setting the Profile connection property to the location of the Supabase Profile on disk (e.g. C:\profiles\Supabase.apip). Next, set the ProfileSettings connection property to the connection string for Supabase (see below).
Supabase API Profile Settings
Log into your Supabase account and navigate to Account Settings > Access Tokens to generate a new personal access token.
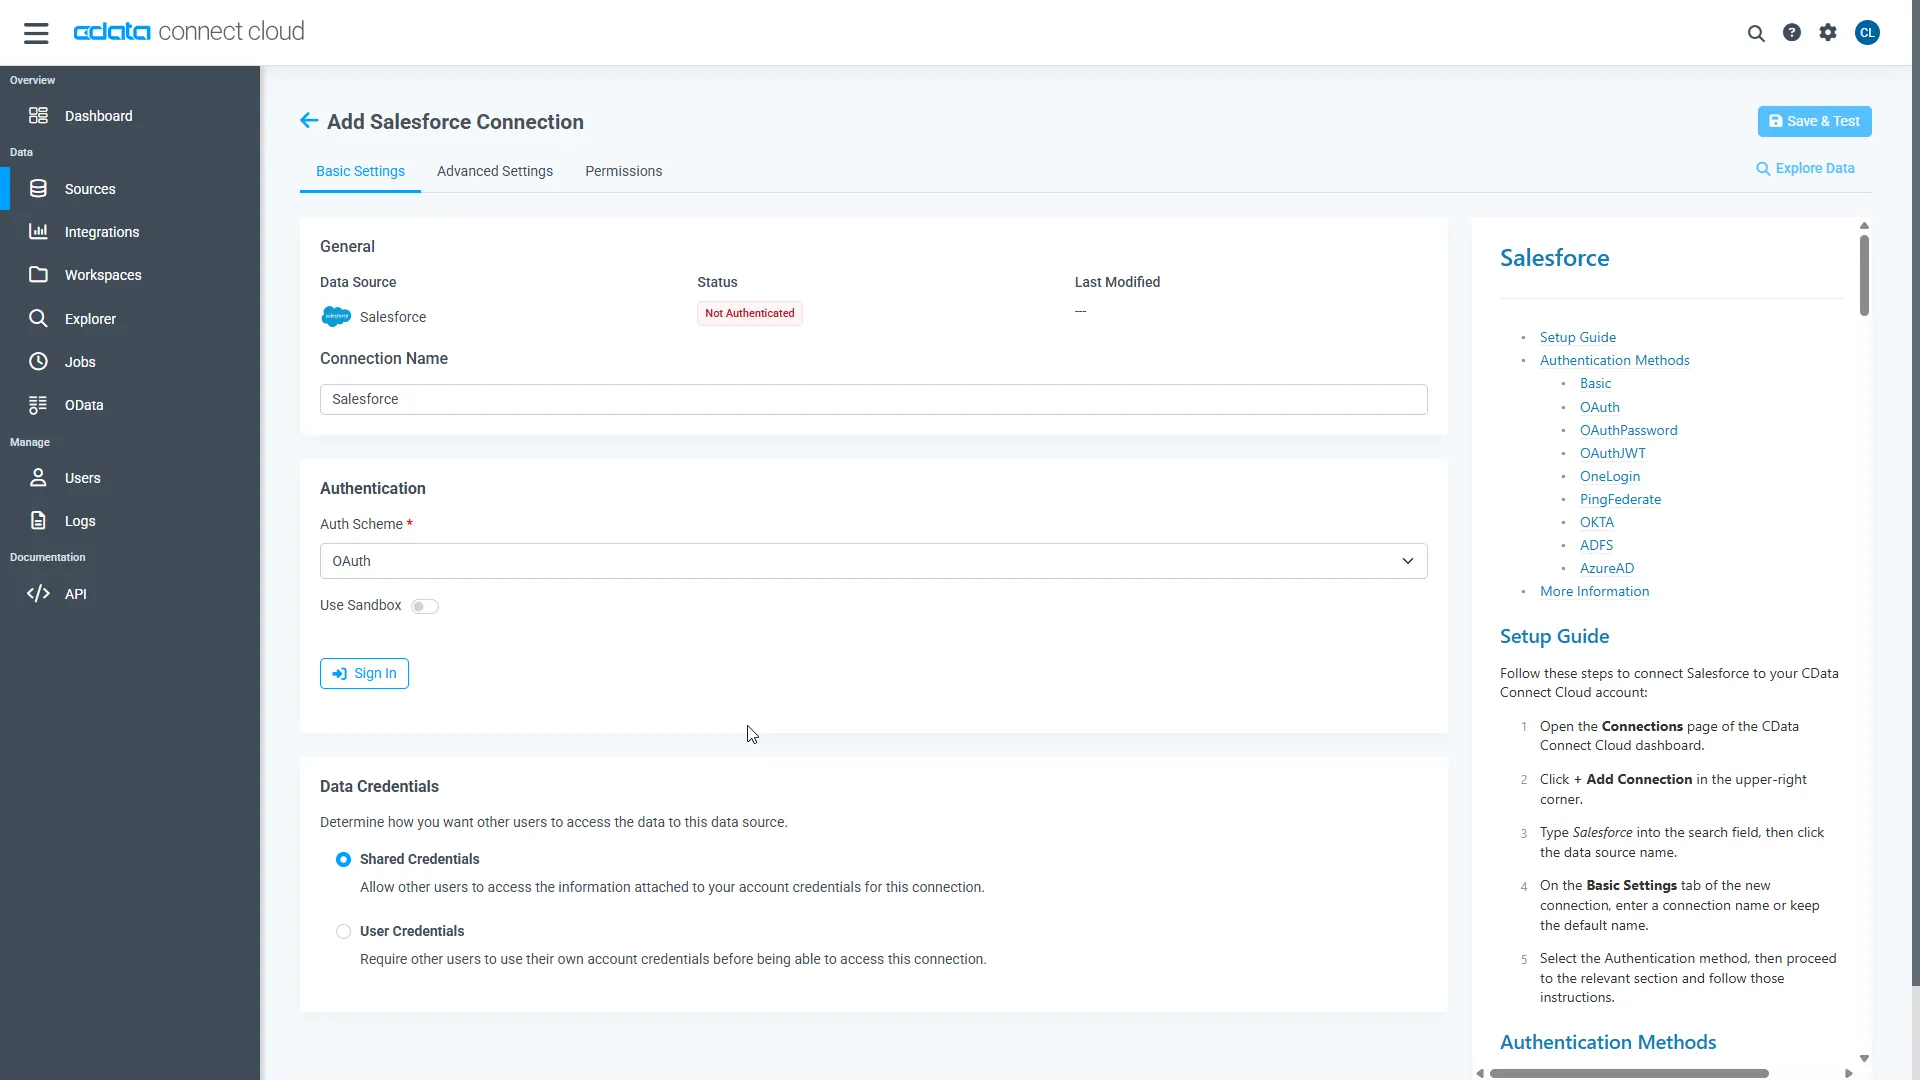
- Click Save & Test
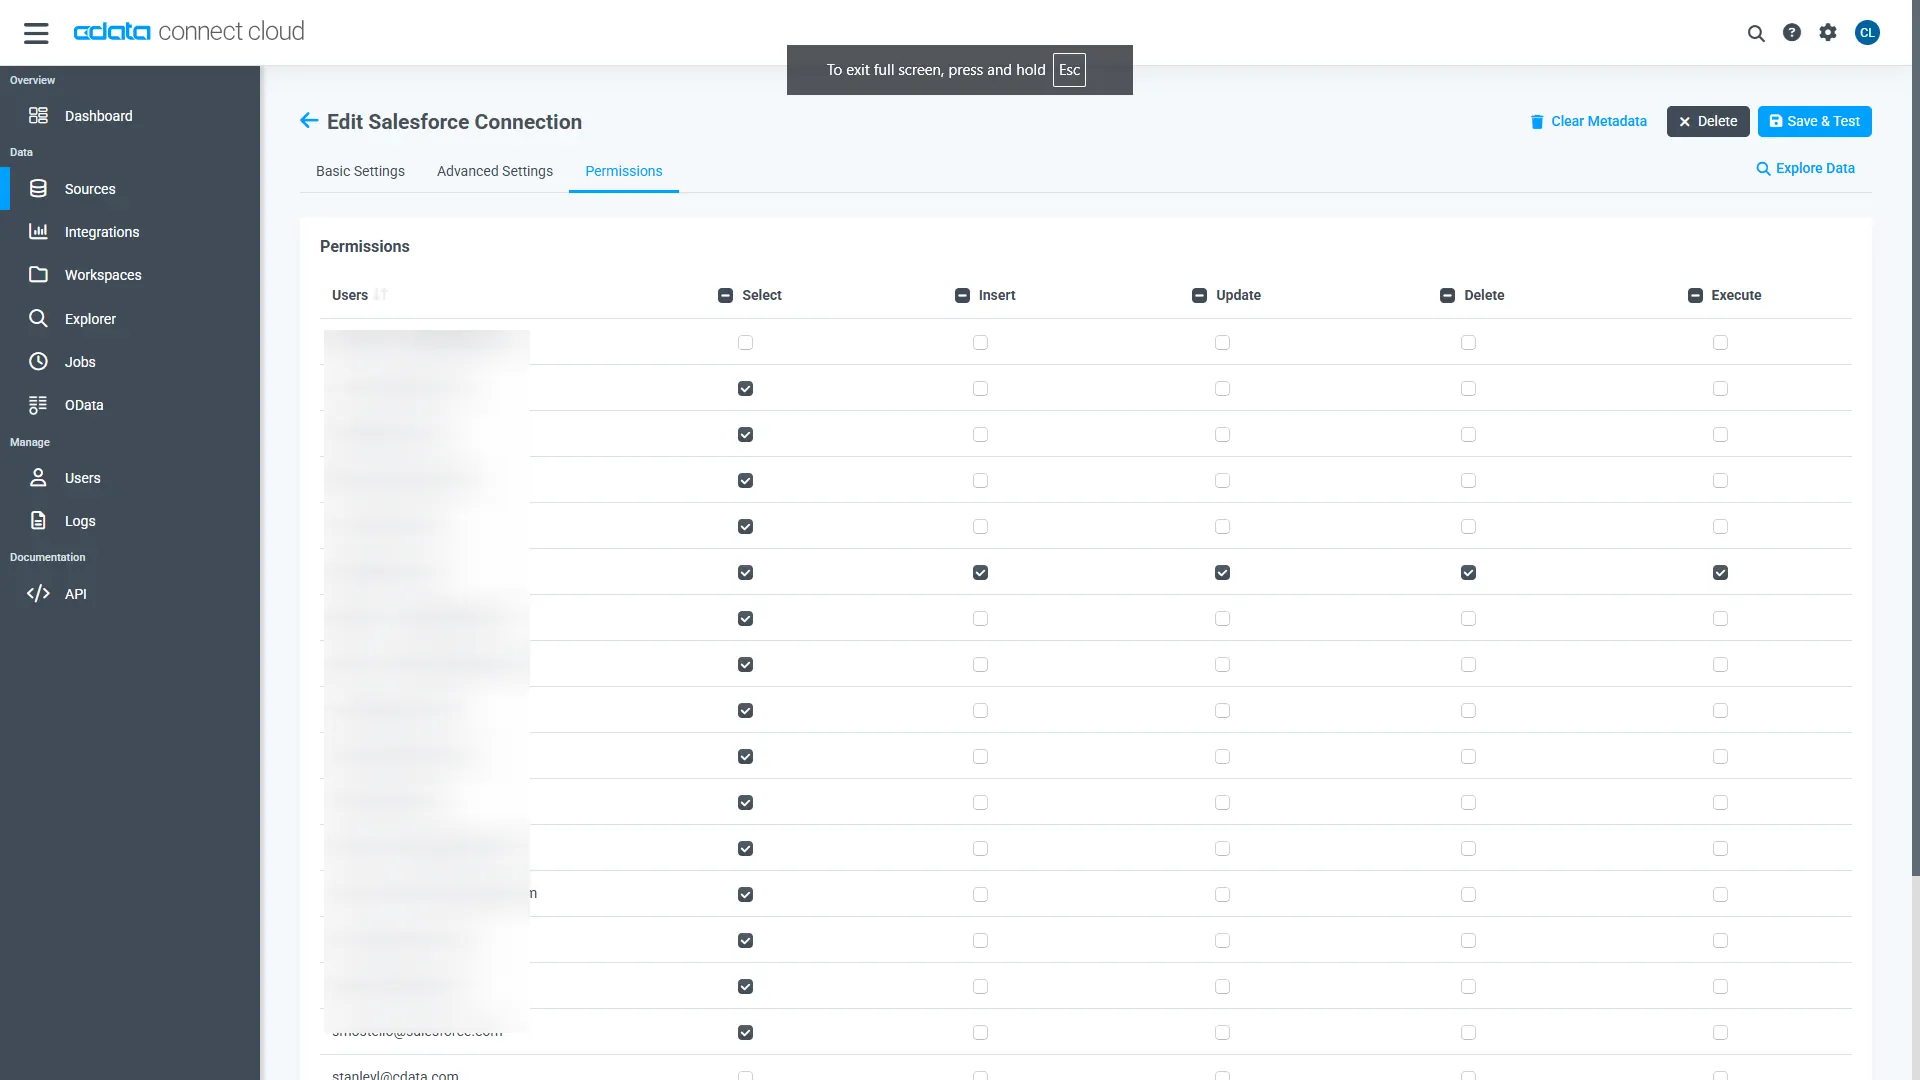
- Navigate to the Permissions tab and update the user-based permissions.
Generate a Personal Access Token (PAT)
The Python SDK authenticates to Connect AI with your account email and a Personal Access Token (PAT). It is best practice to create a separate PAT for each application to maintain granularity of access.
- Click the Gear icon () at the top right of the Connect AI app to open the Settings page.
- On the Settings page, go to the Access Tokens section and click Create PAT.
- Give the PAT a name and click Create.
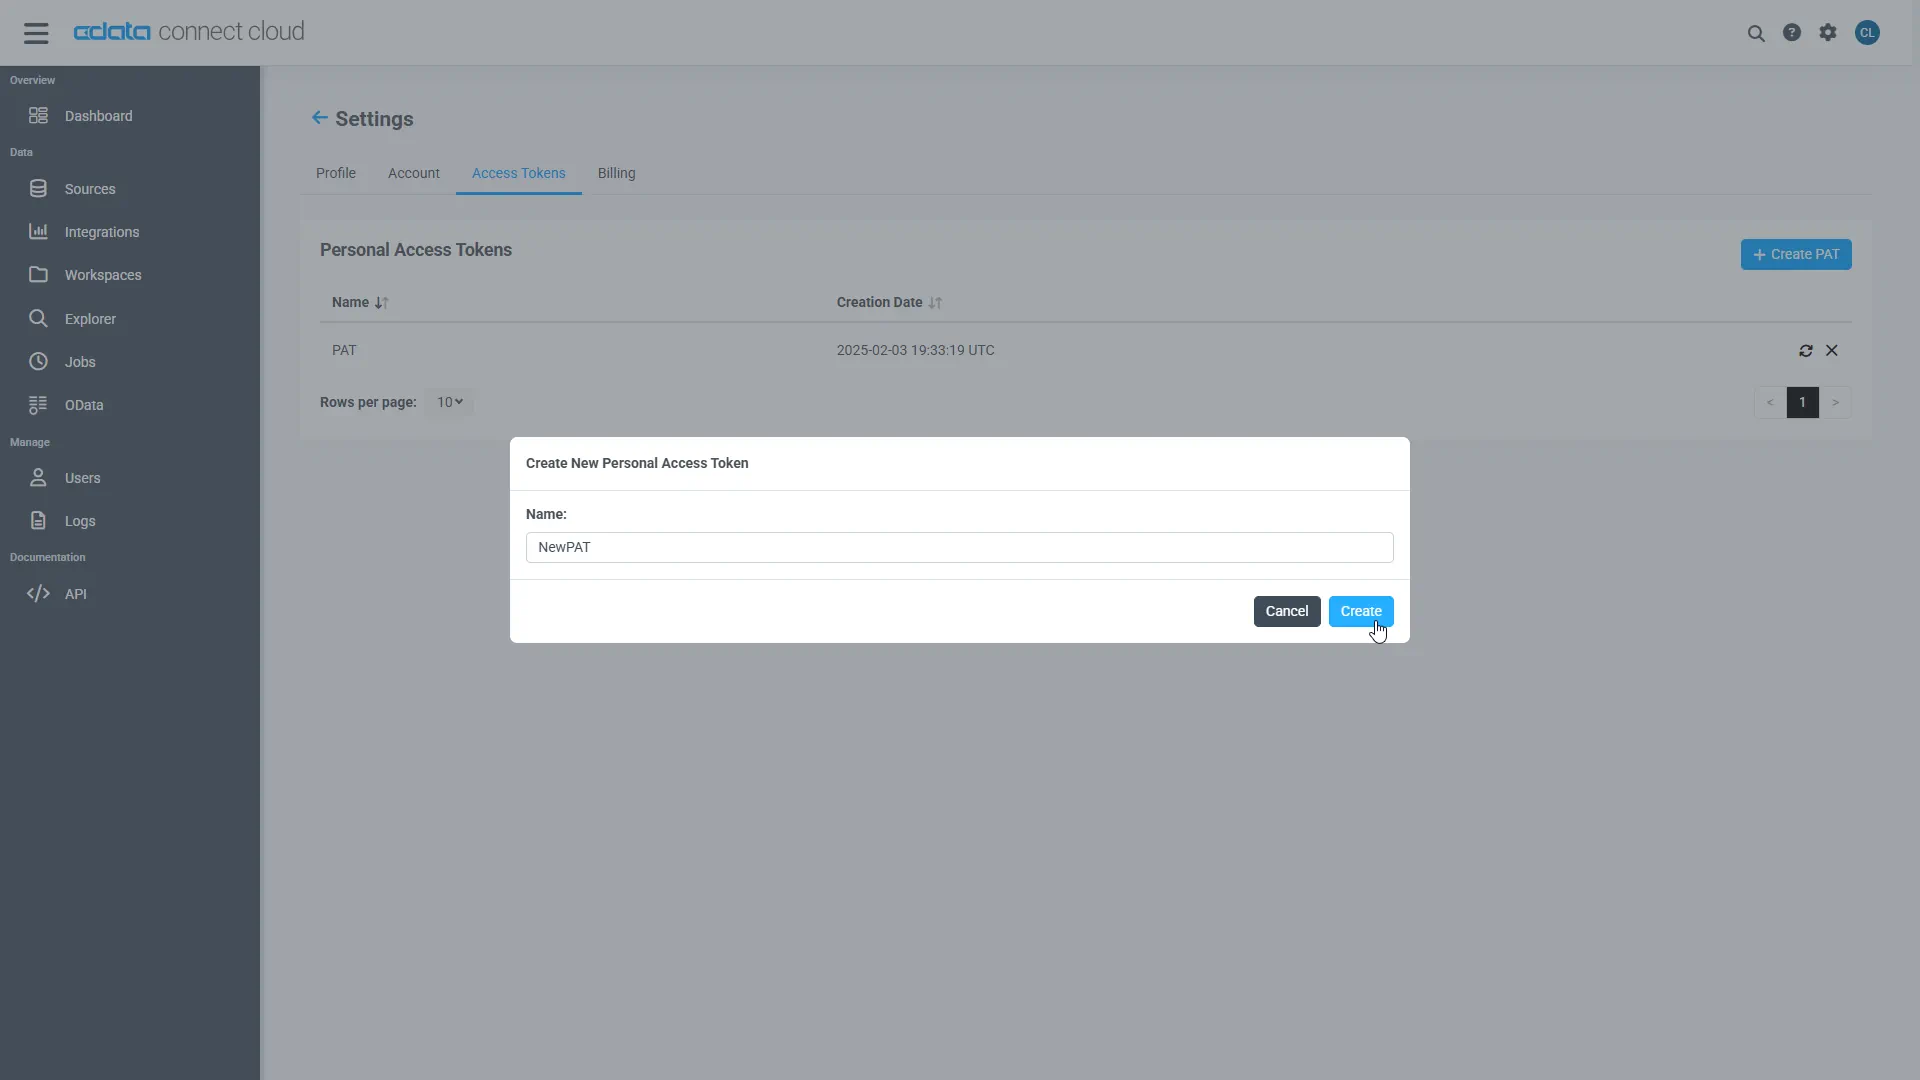
- The PAT is only visible at creation, so copy it and store it securely.
Install Required Modules
Install the SDK and the petl framework using the pip utility:
pip install cdata-connect-ai
pip install petl
Build an ETL App for Supabase Data in Python
Once the required modules are installed, you are ready to build the ETL app. Code snippets follow, but the full source code is available at the end of the article.
First, import the modules and connect to Connect AI with your account email and PAT:
import petl as etl
import cdata_connect_ai

conn = cdata_connect_ai.connect(
    username="[email protected]",
    password="<your_pat>",
)
Create a SQL Statement to Query Supabase
Use SQL to create a statement for querying Supabase. In this article, we read data from the Branch entity. Identifiers are three-part: <Connection>.<Schema>.<Table>, where the connection name defaults to the source name (for example, API1).
sql = (
    "SELECT Ref, PostgresVersion "
    "FROM [API1].[API].[Branch] "
    "WHERE Status = 'active'"
)
Extract, Transform, and Load the Supabase Data
With a connection and query in hand, use petl to extract, transform, and load the Supabase data. In this example, we extract Supabase data, sort the data by the PostgresVersion column, and load the data into a CSV file.
table1 = etl.fromdb(conn, sql)

table2 = etl.sort(table1, 'PostgresVersion')

etl.tocsv(table2, 'branch_data.csv')
Supabase is a read-only source in Connect AI, so this pipeline can extract and transform Supabase data but not load rows back. Close the connection when the extract is complete:
conn.close()
With the CData Connect AI Python SDK, you can work with Supabase data just like you would with any database, including direct access to data in ETL packages like petl.
More Information and Free Trial
Now you can pipe live Supabase data through petl using the CData Connect AI Python SDK. For more information on connecting to Supabase (and hundreds of other data sources), visit the Connect AI page. Sign up for a free trial and start building data pipelines for live Supabase data in Python.
Full Source Code
import petl as etl
import cdata_connect_ai

conn = cdata_connect_ai.connect(
    username="[email protected]",
    password="<your_pat>",
)

sql = (
    "SELECT Ref, PostgresVersion "
    "FROM [API1].[API].[Branch] "
    "WHERE Status = 'active'"
)

table1 = etl.fromdb(conn, sql)

table2 = etl.sort(table1, 'PostgresVersion')

etl.tocsv(table2, 'branch_data.csv')
conn.close()