


Connect and Visualize Live XML Data in Databricks Lakehouse Federation with CData Connect AI
Databricks Lakehouse Federation enables organizations to query and integrate data from multiple sources without requiring data movement. It allows federated queries across databases, data warehouses, and lakehouses, providing a unified interface for data analysis and management within Databricks. When combined with CData Connect AI, it enables seamless access to XML data for data virtualization, while also supporting data lineage and fine-grained access control.
This article explains how to use CData Connect AI to establish a live connection to XML and how to access live XML data from the Databricks platform.
CData Connect AI offers a seamless SQL Server, cloud-to-cloud interface for XML, enabling you to effortlessly create dashboards and visualizations using live XML data in Databricks. While building visualizations, Databricks requires SQL queries to retrieve the necessary data. With built-in optimized data processing, CData Connect AI pushes all supported SQL operations (such as filters and JOINs) directly to XML, utilizing server-side processing for fast and efficient data retrieval of XML data.
Configure XML connectivity for Databricks in CData Connect AI
To work with XML data in Databricks - Lakehouse Federation, you need to connect to XML from Connect AI and provide user access to the connection.
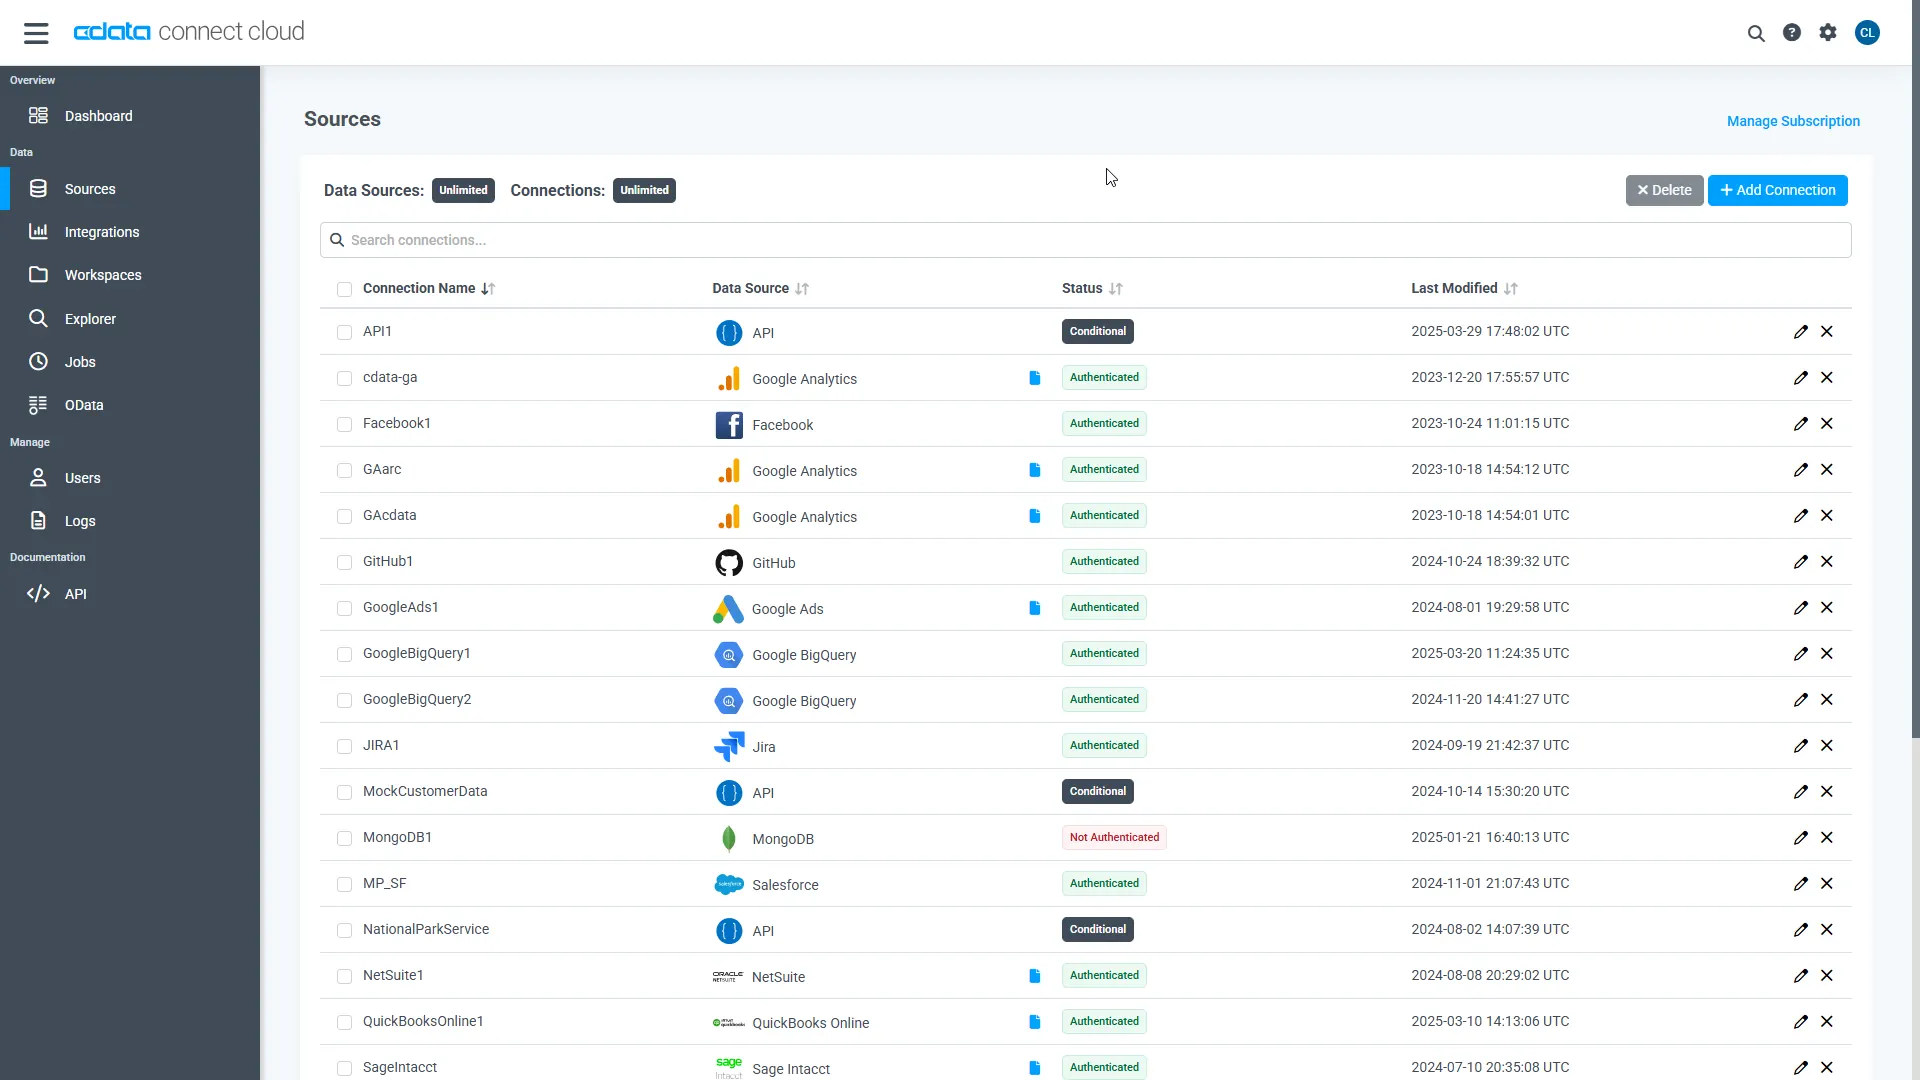
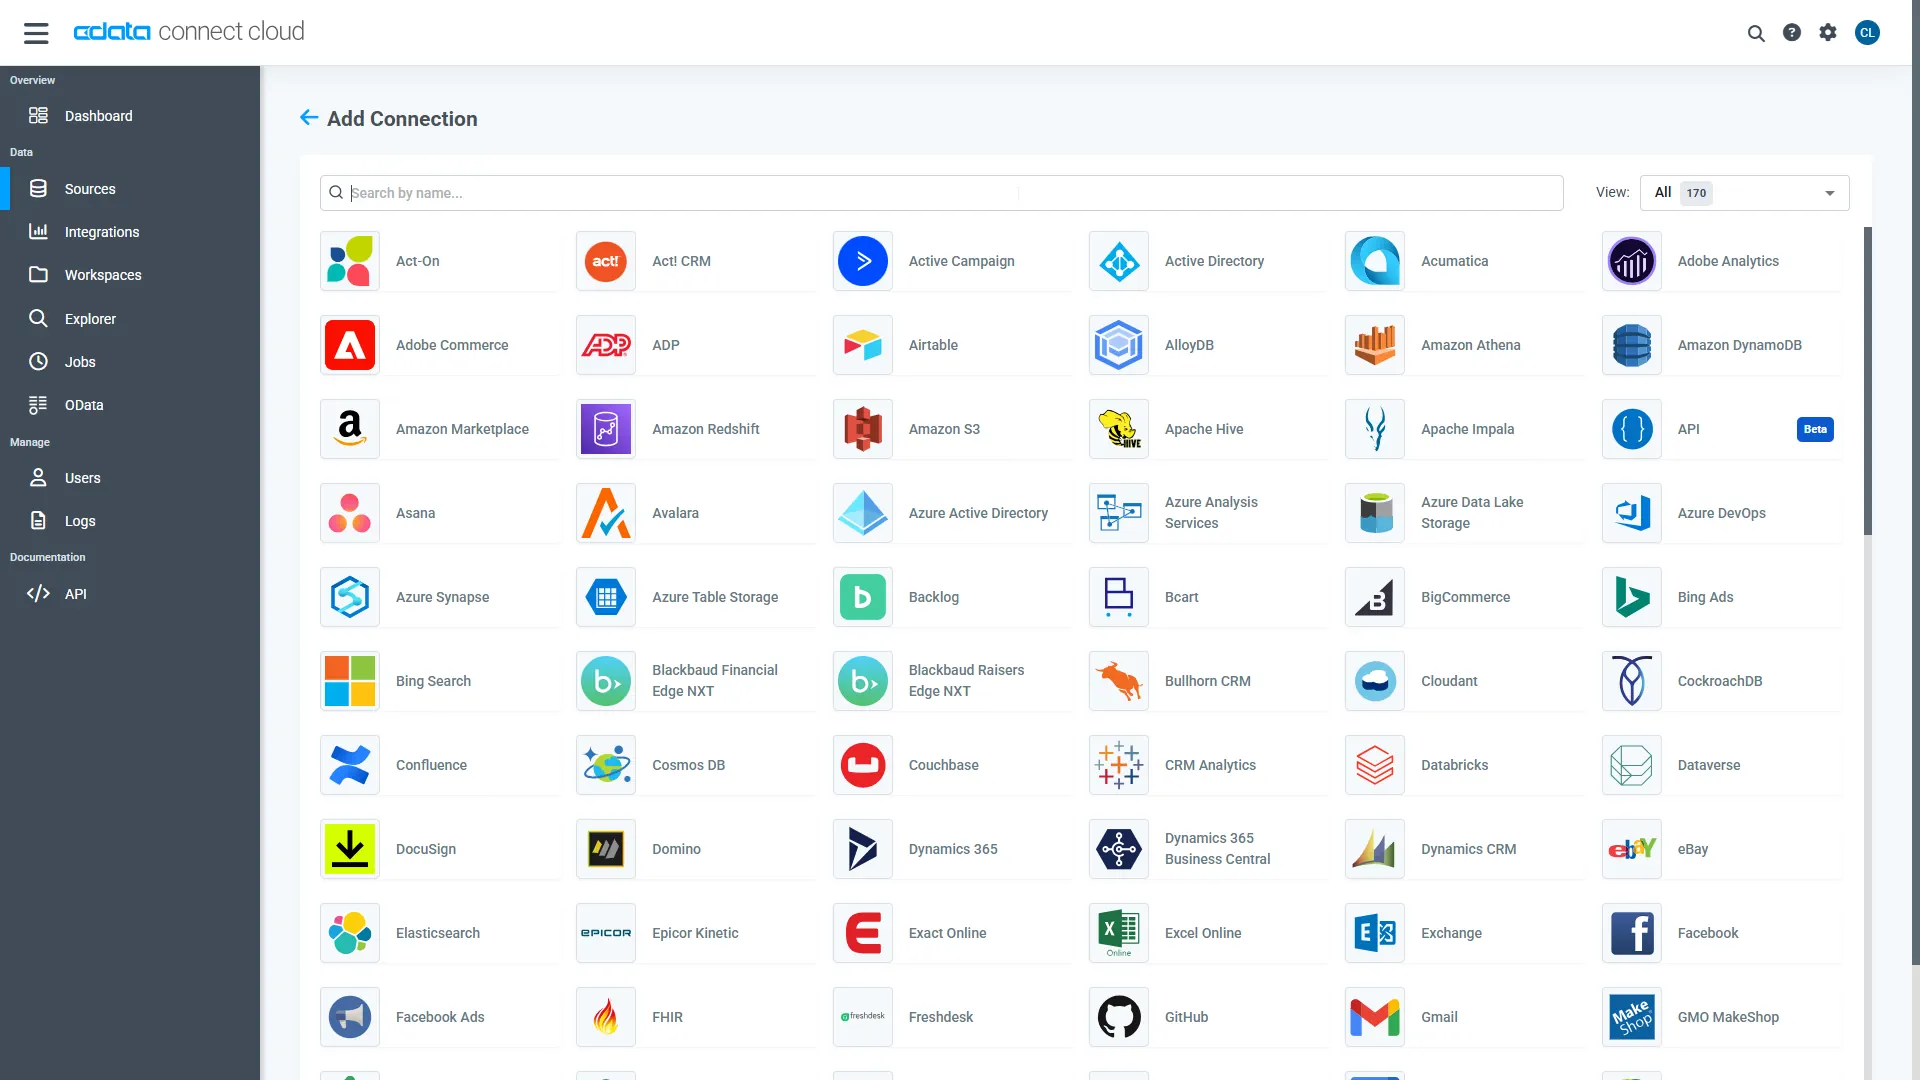
- Log into Connect AI, click Sources, and then click Add Connection
- Select "XML" from the Add Connection panel
-
Enter the necessary authentication properties to connect to XML.
Connecting to Local or Cloud-Stored (Box, Google Drive, Amazon S3, SharePoint) XML Files
CData Drivers let you work with XML files stored locally and stored in cloud storage services like Box, Amazon S3, Google Drive, or SharePoint, right where they are.
Setting connection properties for local files
Set the URI property to local folder path.
Setting connection properties for files stored in Amazon S3
To connect to XML file(s) within Amazon S3, set the URI property to the URI of the Bucket and Folder where the intended XML files exist. In addition, at least set these properties:
- AWSAccessKey: AWS Access Key (username)
- AWSSecretKey: AWS Secret Key
Setting connection properties for files stored in Box
To connect to XML file(s) within Box, set the URI property to the URI of the folder that includes the intended XML file(s). Use the OAuth authentication method to connect to Box.
Dropbox
To connect to XML file(s) within Dropbox, set the URI proprerty to the URI of the folder that includes the intended XML file(s). Use the OAuth authentication method to connect to Dropbox. Either User Account or Service Account can be used to authenticate.
SharePoint Online (SOAP)
To connect to XML file(s) within SharePoint with SOAP Schema, set the URI proprerty to the URI of the document library that includes the intended XML file. Set User, Password, and StorageBaseURL.
SharePoint Online REST
To connect to XML file(s) within SharePoint with REST Schema, set the URI proprerty to the URI of the document library that includes the intended XML file. StorageBaseURL is optional. If not set, the driver will use the root drive. OAuth is used to authenticate.
Google Drive
To connect to XML file(s) within Google Drive, set the URI property to the URI of the folder that includes the intended XML file(s). Use the OAuth authentication method to connect and set InitiateOAuth to GETANDREFRESH.
The DataModel property is the controlling property over how your data is represented into tables and toggles the following basic configurations.
- Document (default): Model a top-level, document view of your XML data. The data provider returns nested elements as aggregates of data.
- FlattenedDocuments: Implicitly join nested documents and their parents into a single table.
- Relational: Return individual, related tables from hierarchical data. The tables contain a primary key and a foreign key that links to the parent document.
See the Modeling XML Data chapter for more information on configuring the relational representation. You will also find the sample data used in the following examples. The data includes entries for people, the cars they own, and various maintenance services performed on those cars.
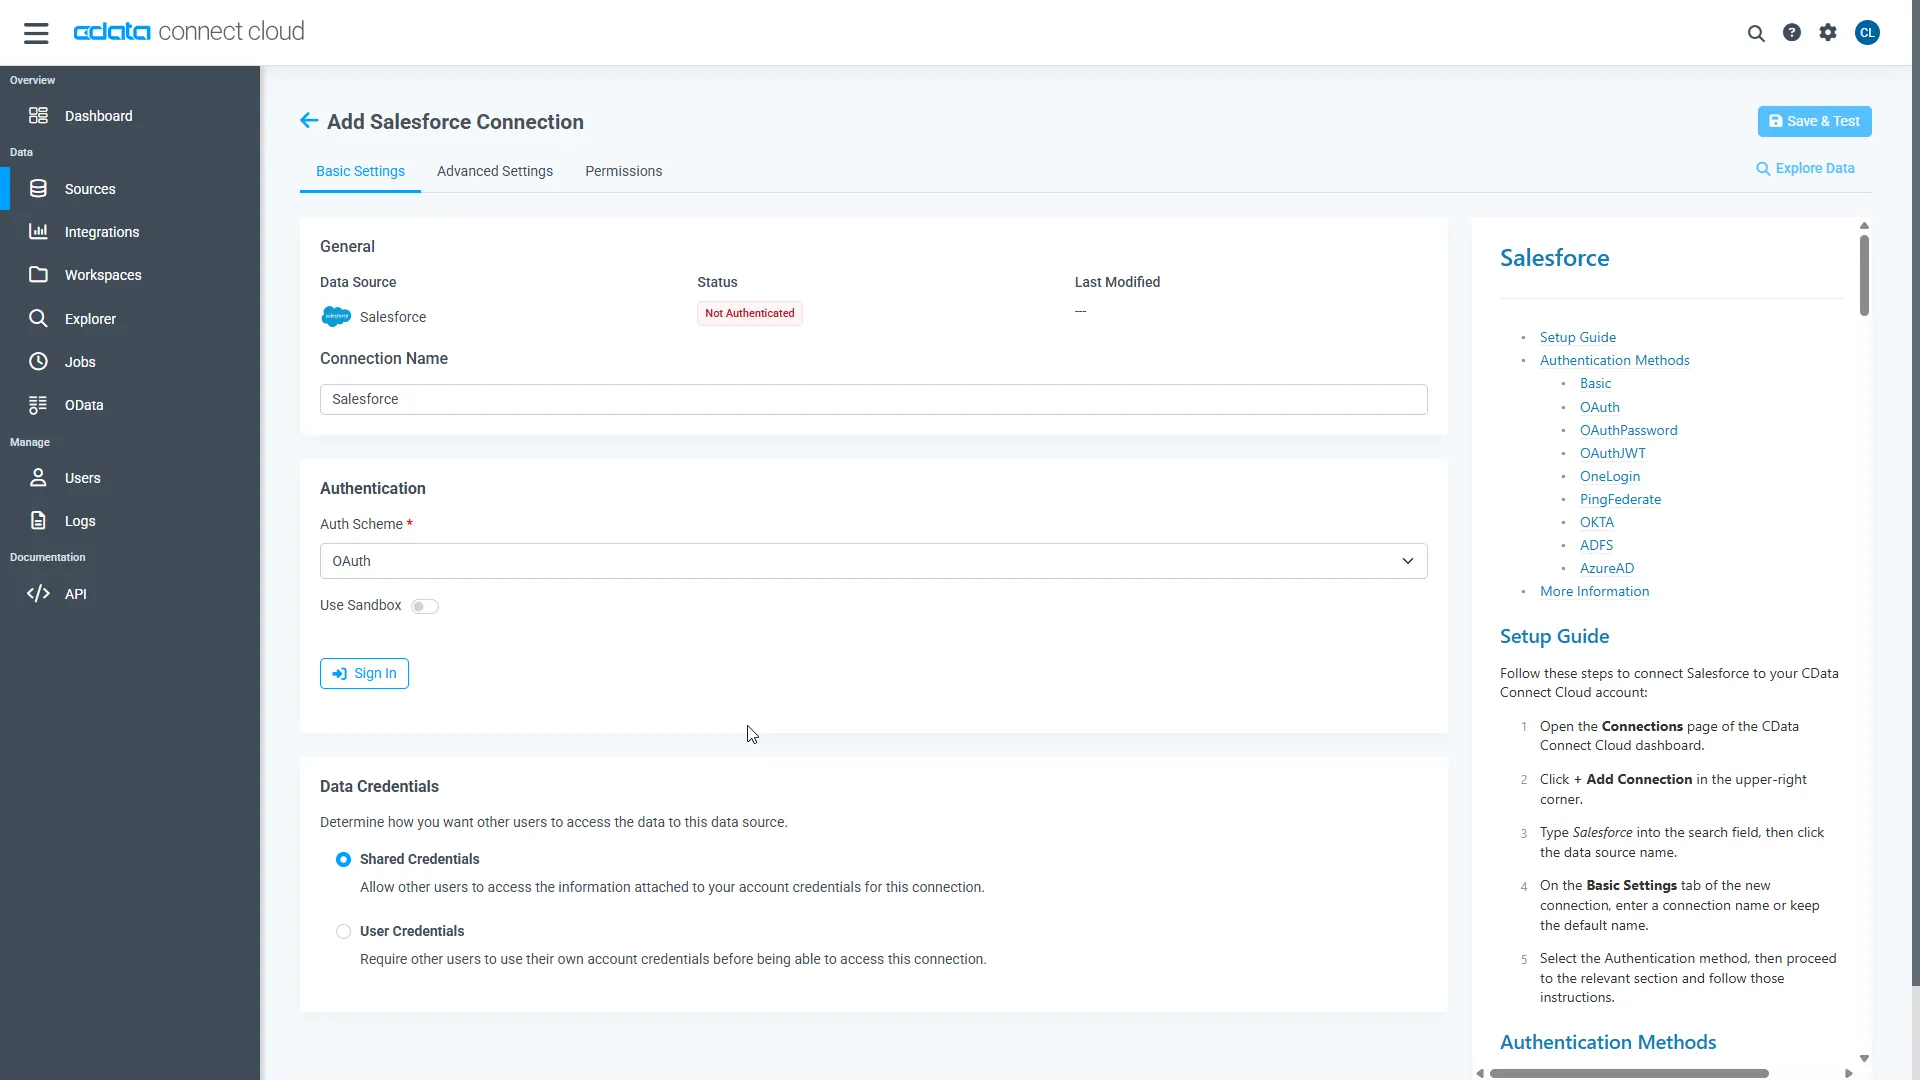
- Click Save & Test
-
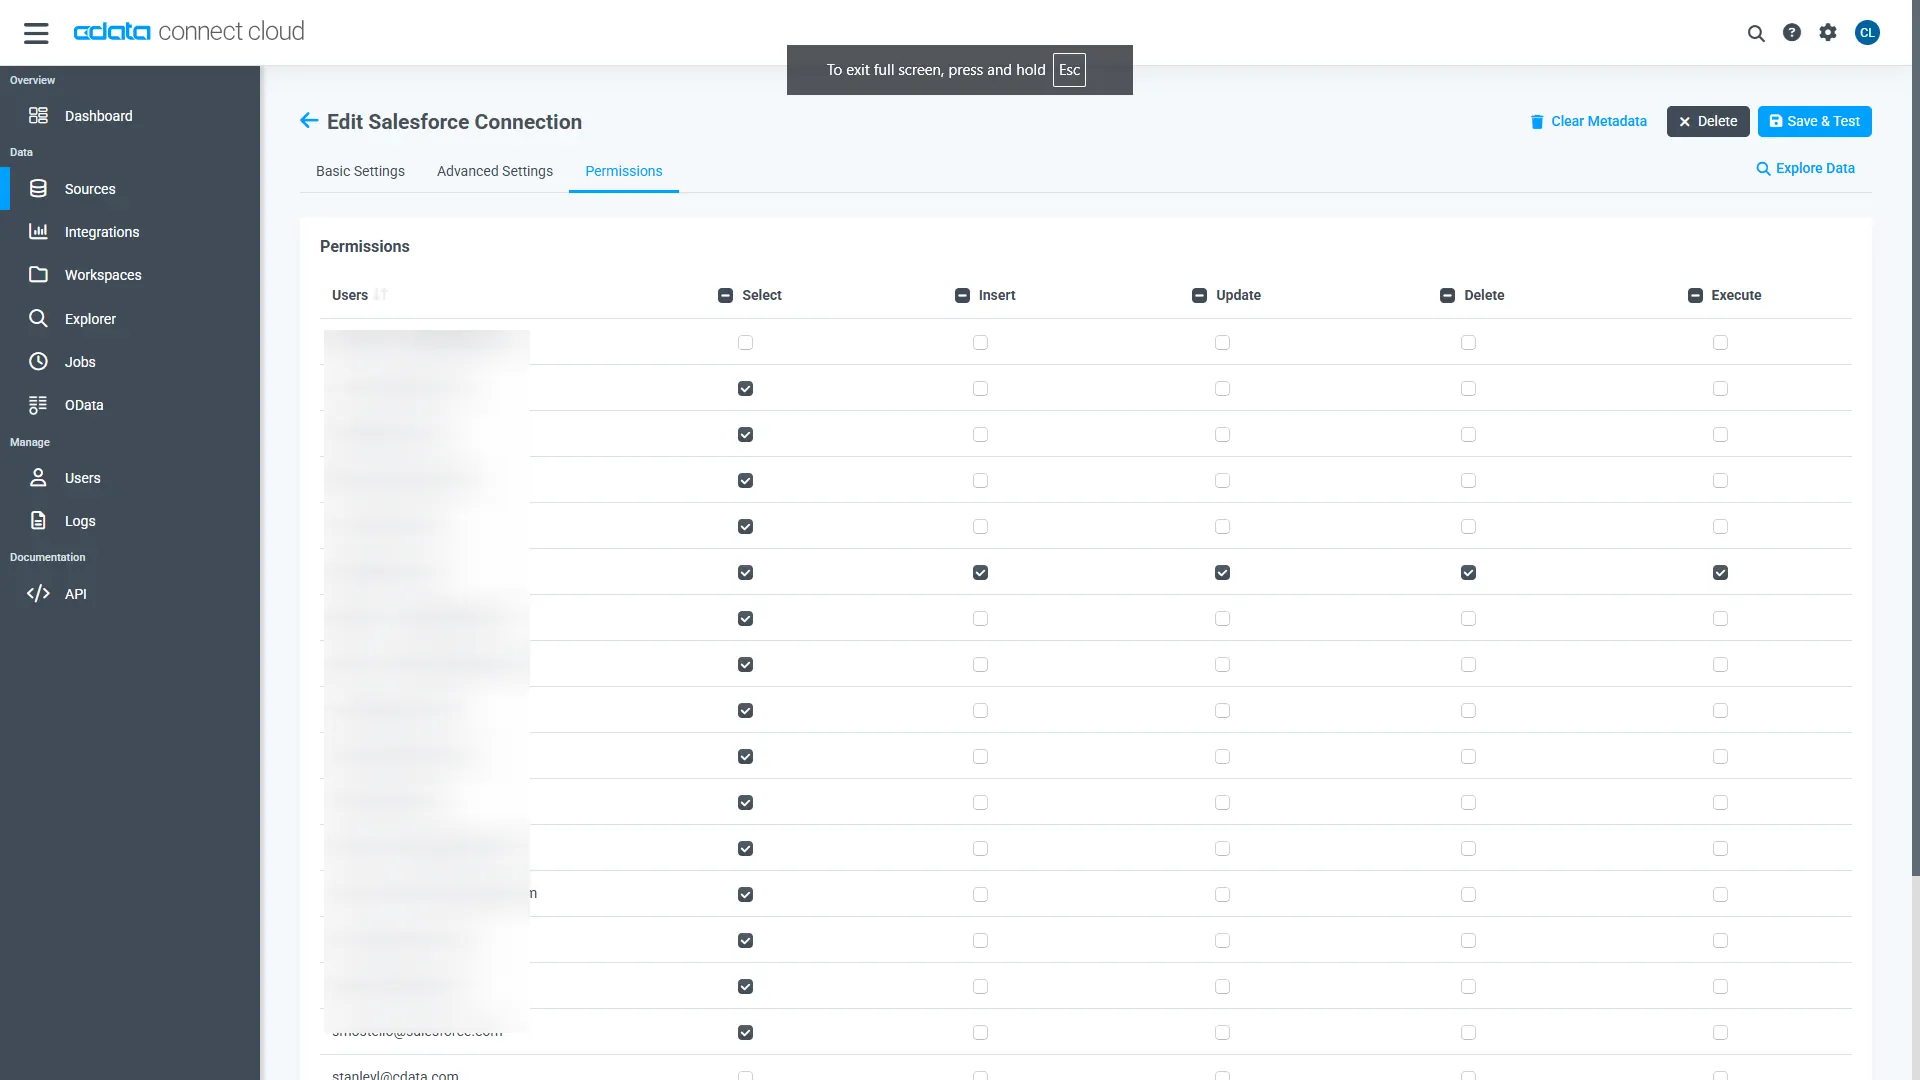
Navigate to the Permissions tab in the Add XML Connection page and update the User-based permissions.
Add a Personal Access Token
When connecting to Connect AI through the REST API, the OData API, or the Virtual SQL Server, a Personal Access Token (PAT) is used to authenticate the connection to Connect AI. It is best practice to create a separate PAT for each service to maintain granularity of access.
- Click on the Gear icon () at the top right of the Connect AI app to open the settings page.
- On the Settings page, go to the Access Tokens section and click Create PAT.
-
Give the PAT a name and click Create.
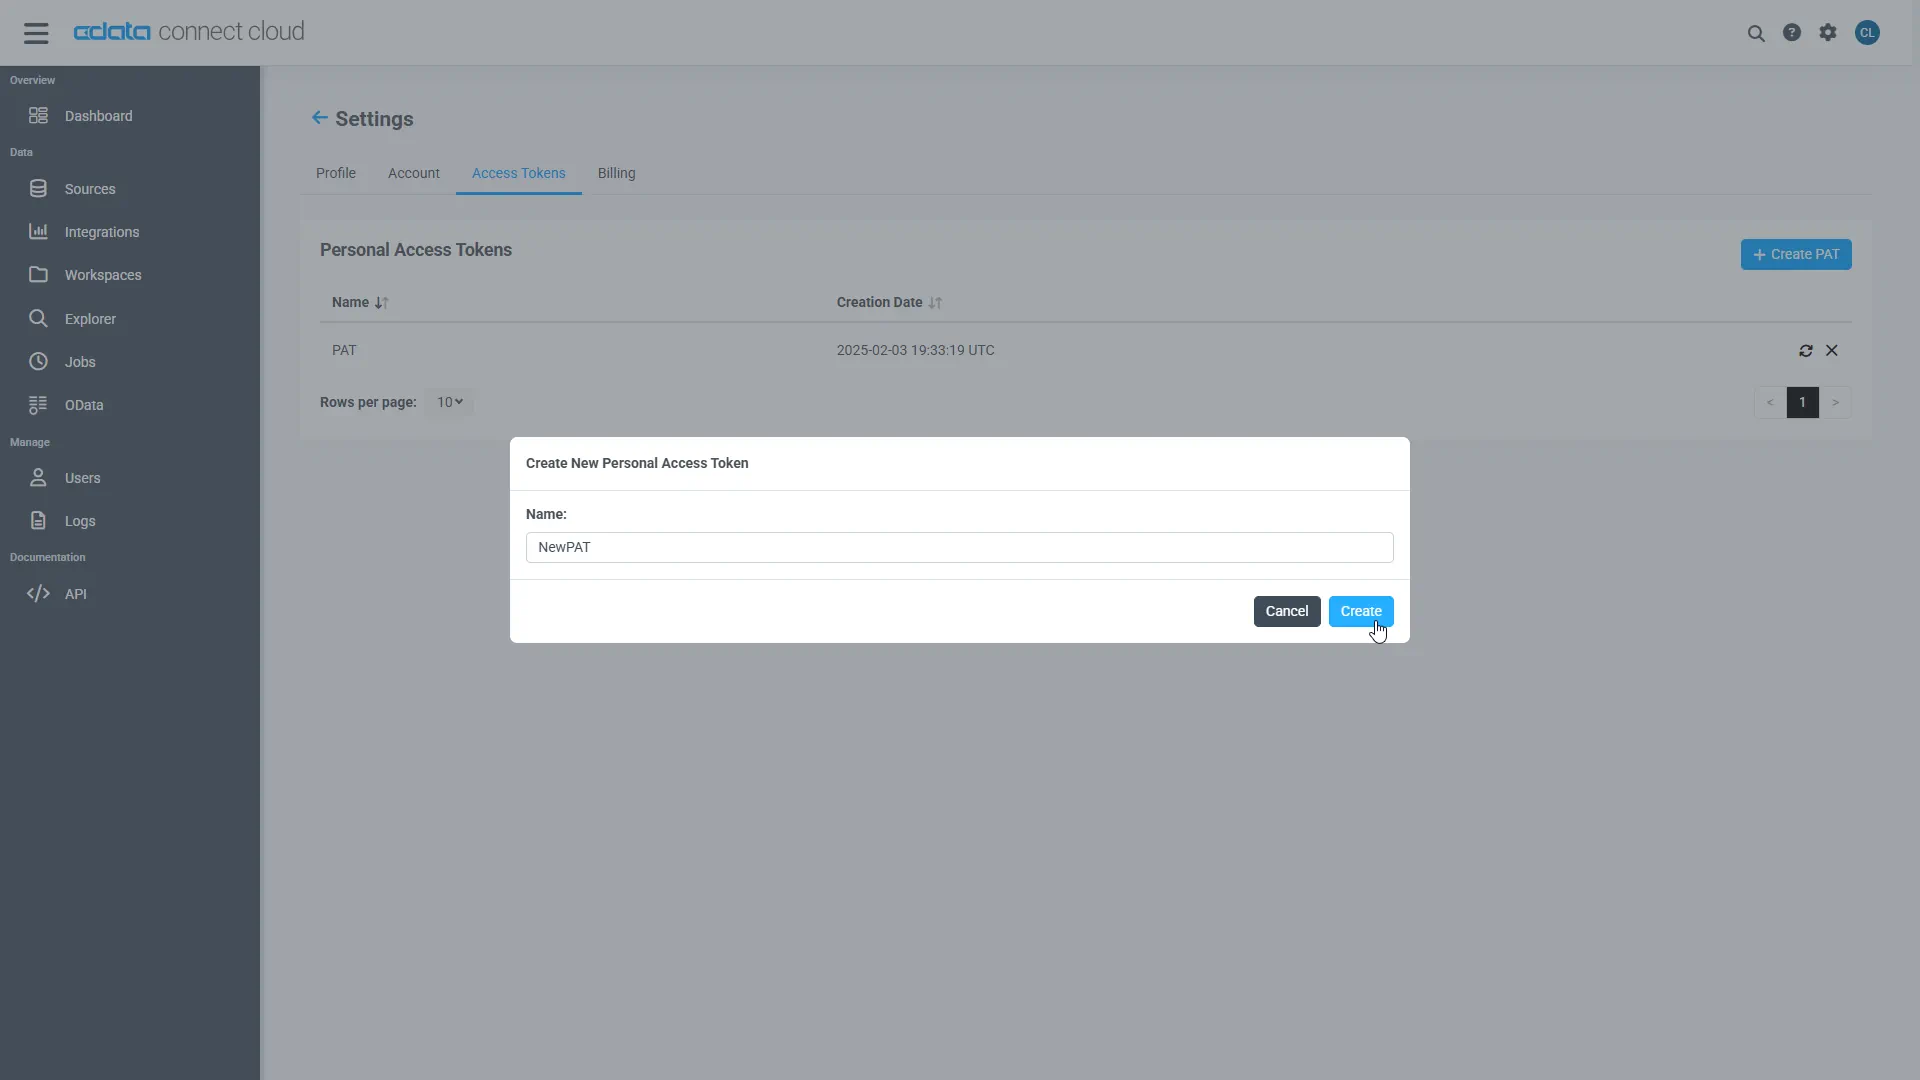
- The personal access token is only visible at creation, so be sure to copy it and store it securely for future use.
With the connection configured and a PAT generated, you are ready to connect to XML data from Databricks.
Connecting live XML data in Databricks
Follow these steps to establish a connection from Databricks to the CData Connect AI Virtual SQL Server API.
- Log into Databricks.
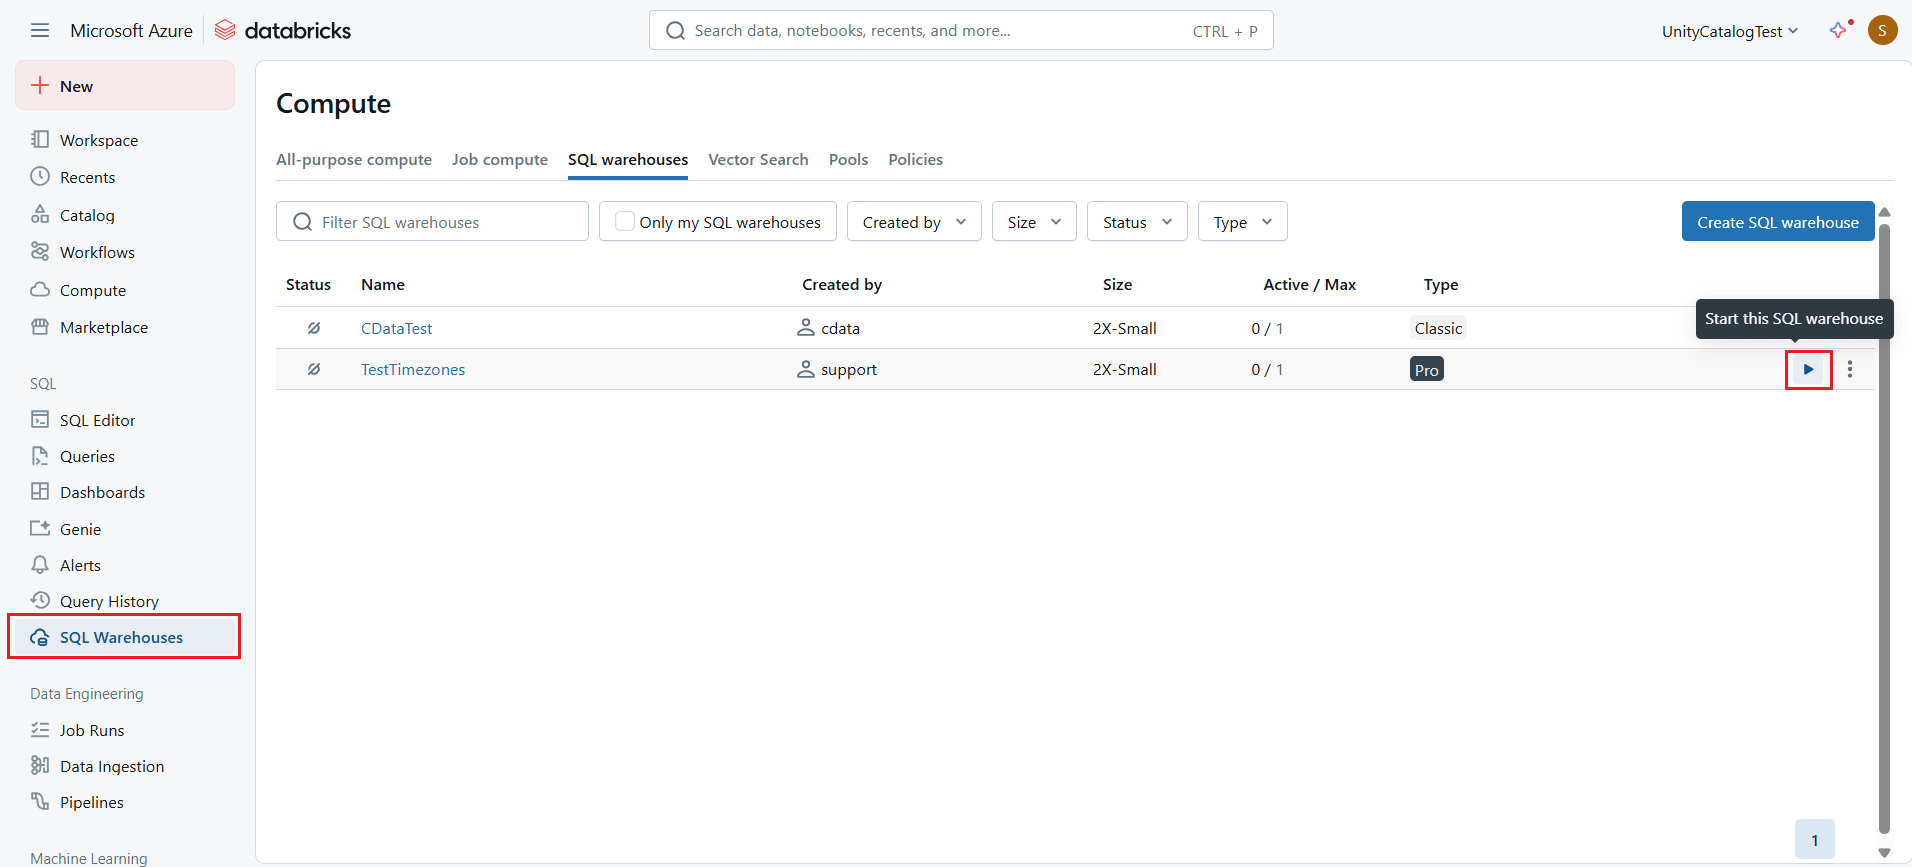
- Navigate to SQL Warehouses and start any warehouse of your choice.
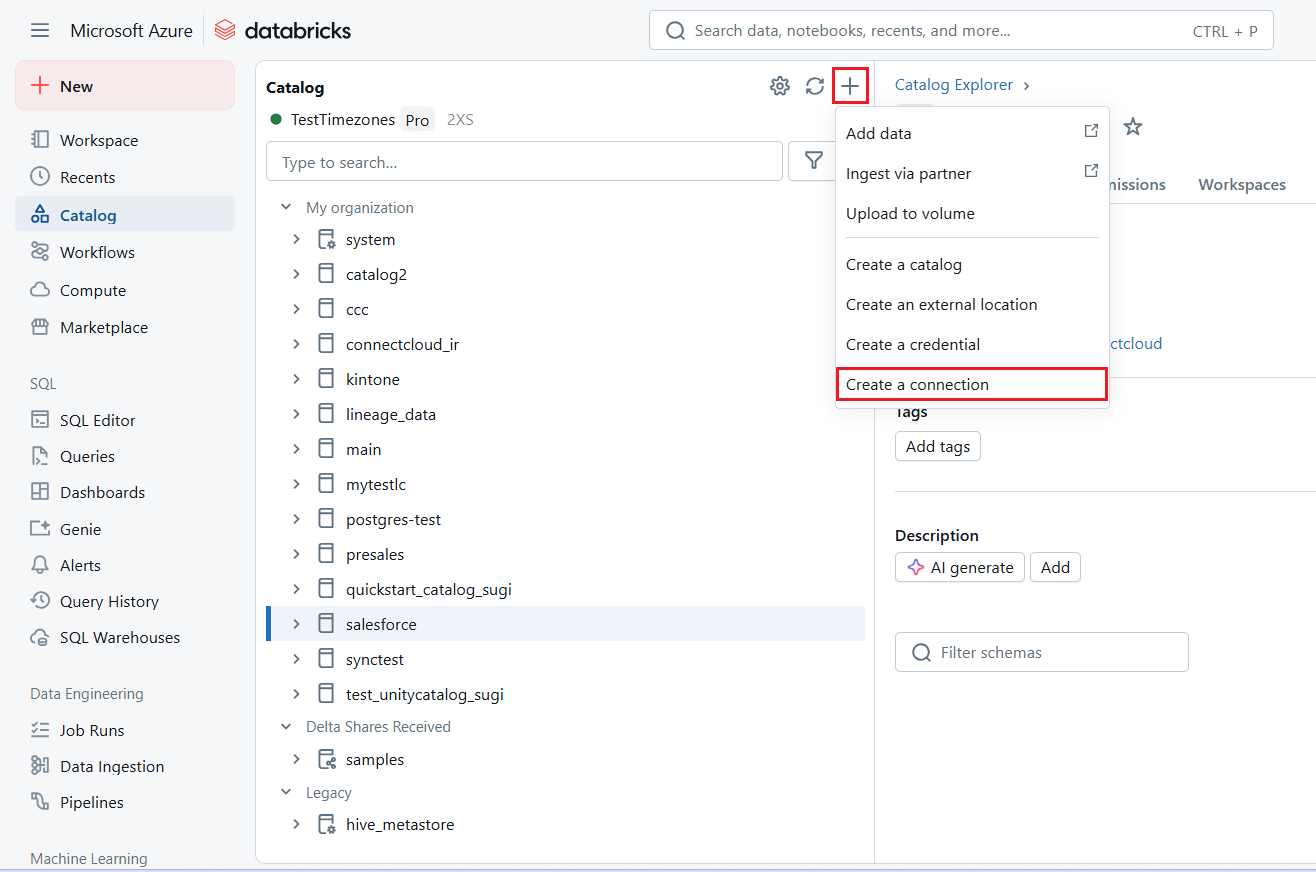
- In the navigation pane, select Catalog. Click and select Create a connection.
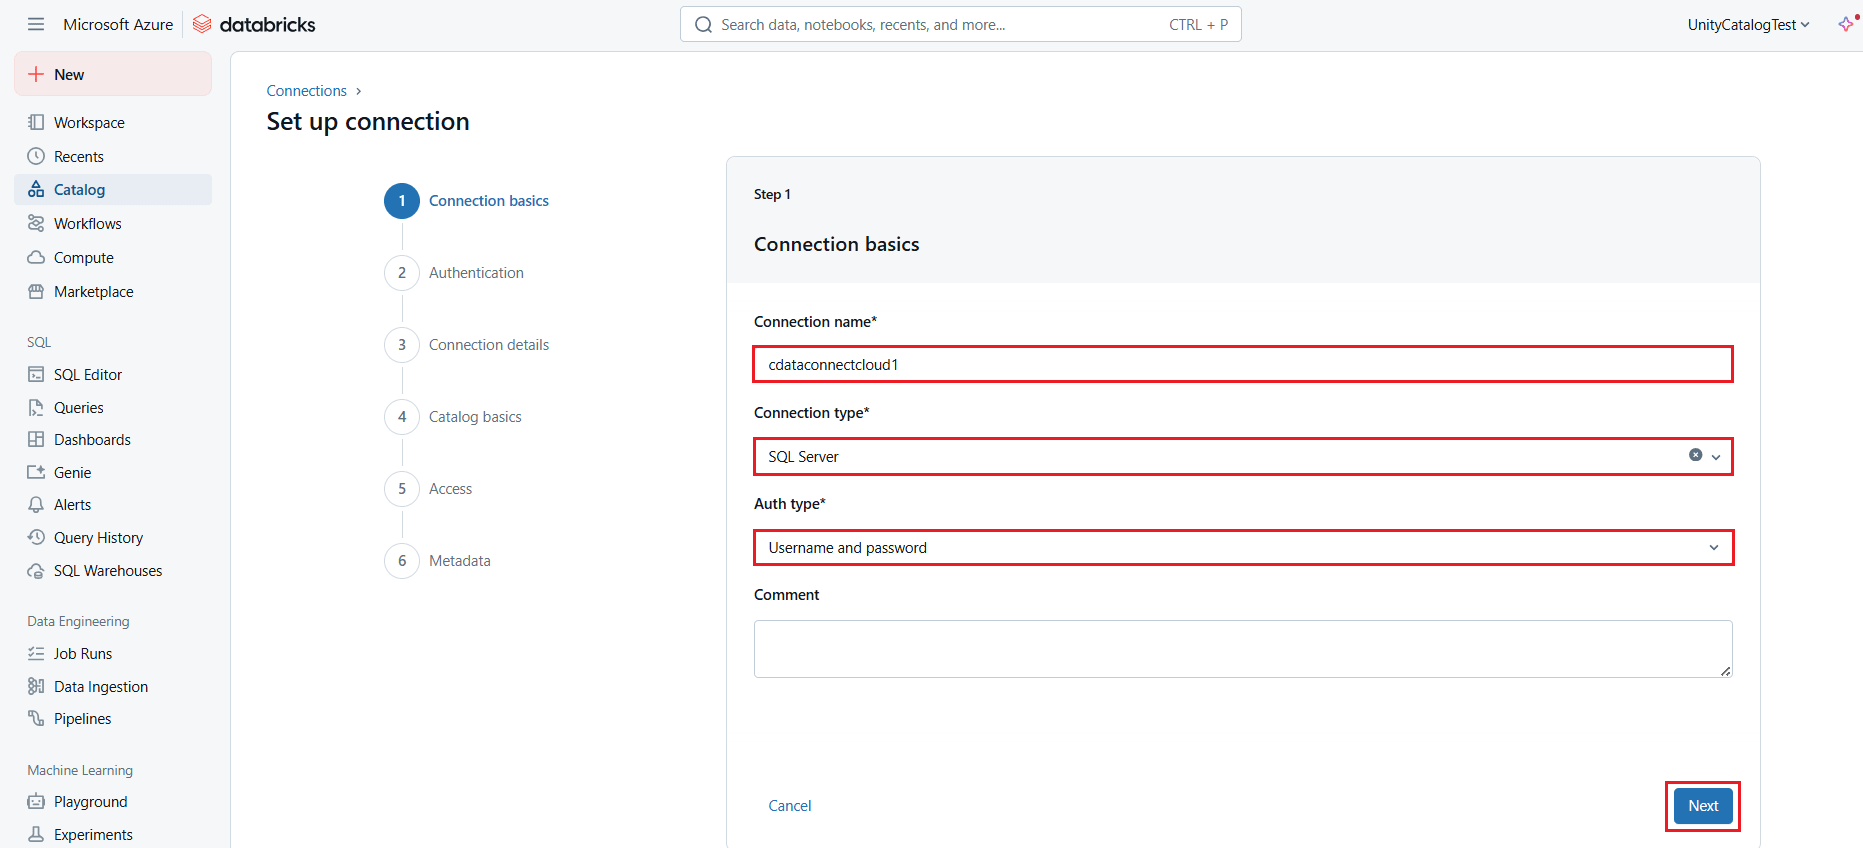
- In the Connection basics section (or Step 1 of Set up connection page), enter the following connection details and click Next:
- Connection name: a user-defined connection name.
- Connection type: select SQL Server from the drop-down list.
- Auth type: select Username and password.
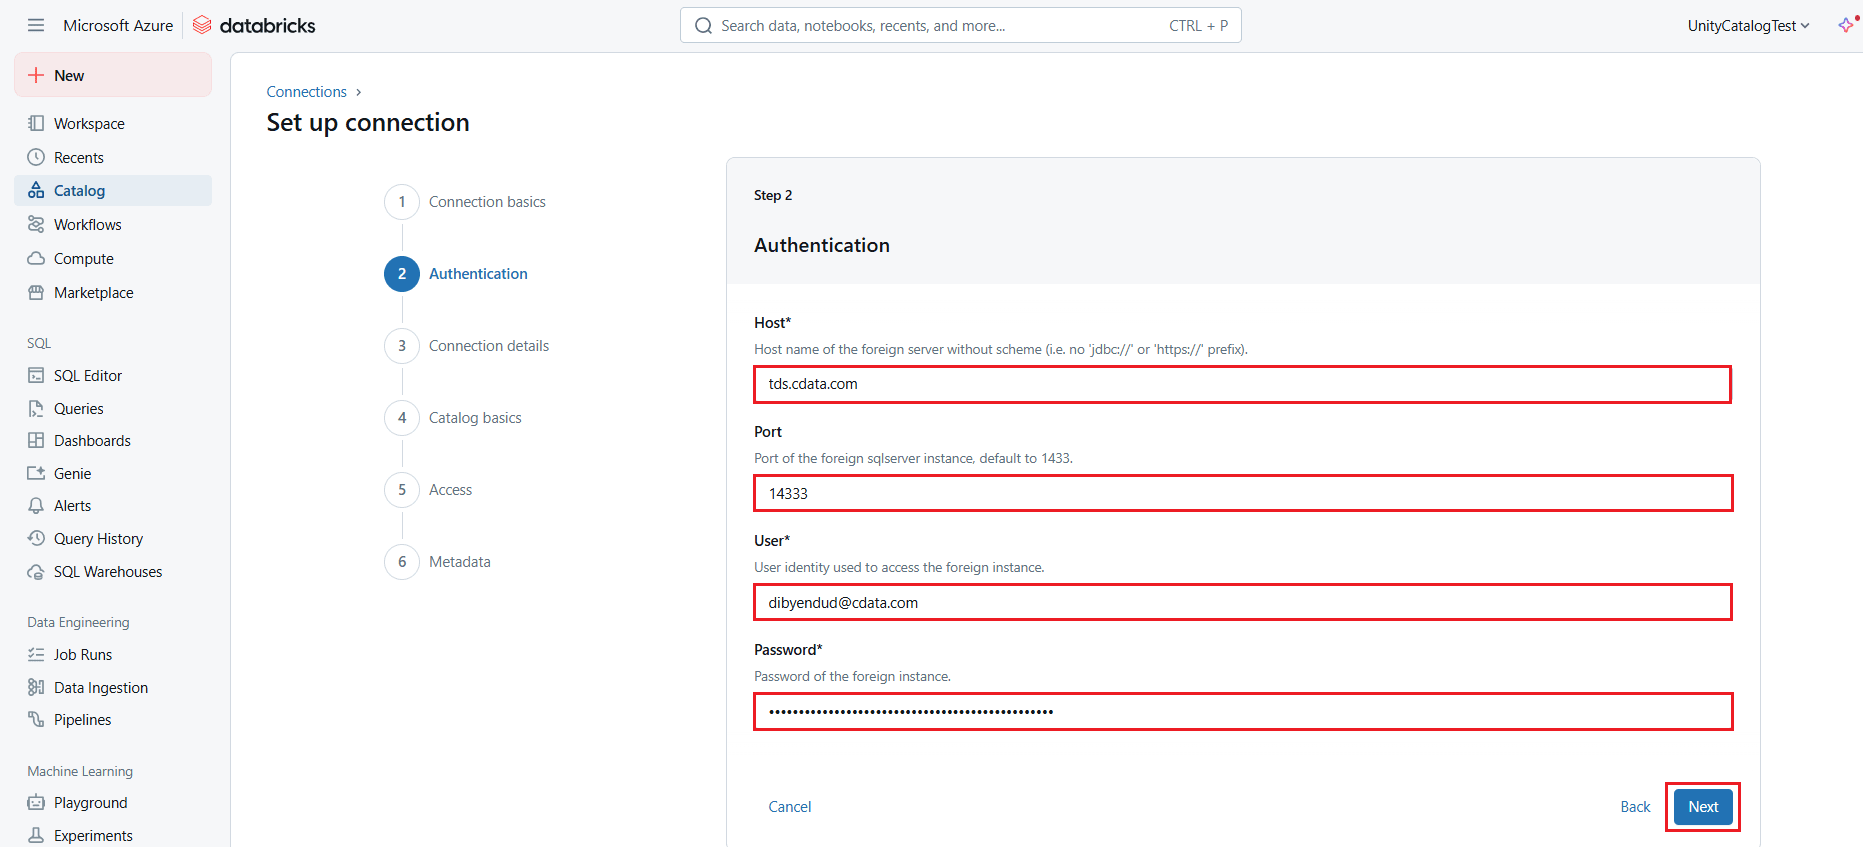
- In the Authentication section (or Step 2), enter the required authentication details, and click Next:
- Host: tds.cdata.com
- Port: 14333
- User: enter your CData Connect AI username, displayed in the top-right corner of the CData Connect AI interface. For example, [email protected]
- Password: enter the PAT generated and copied in the previous section.
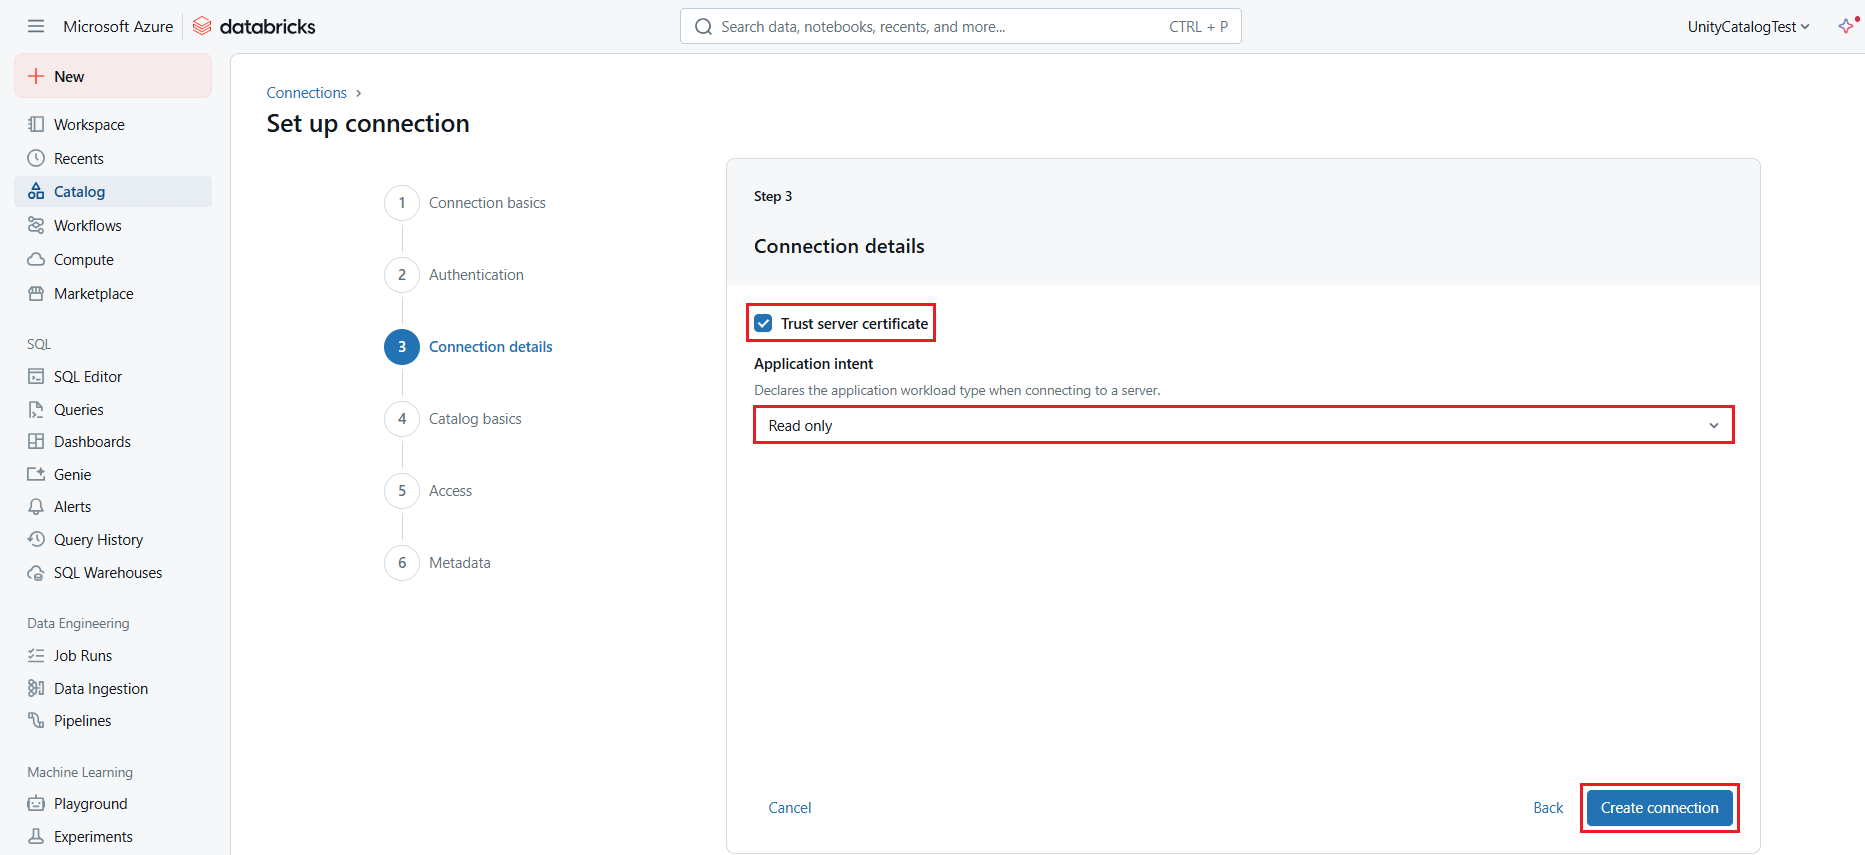
- In the Connection details section (or Step 3), enable the Trust server certificate checkbox and select the appropriate Application intent. Click Create Connection.
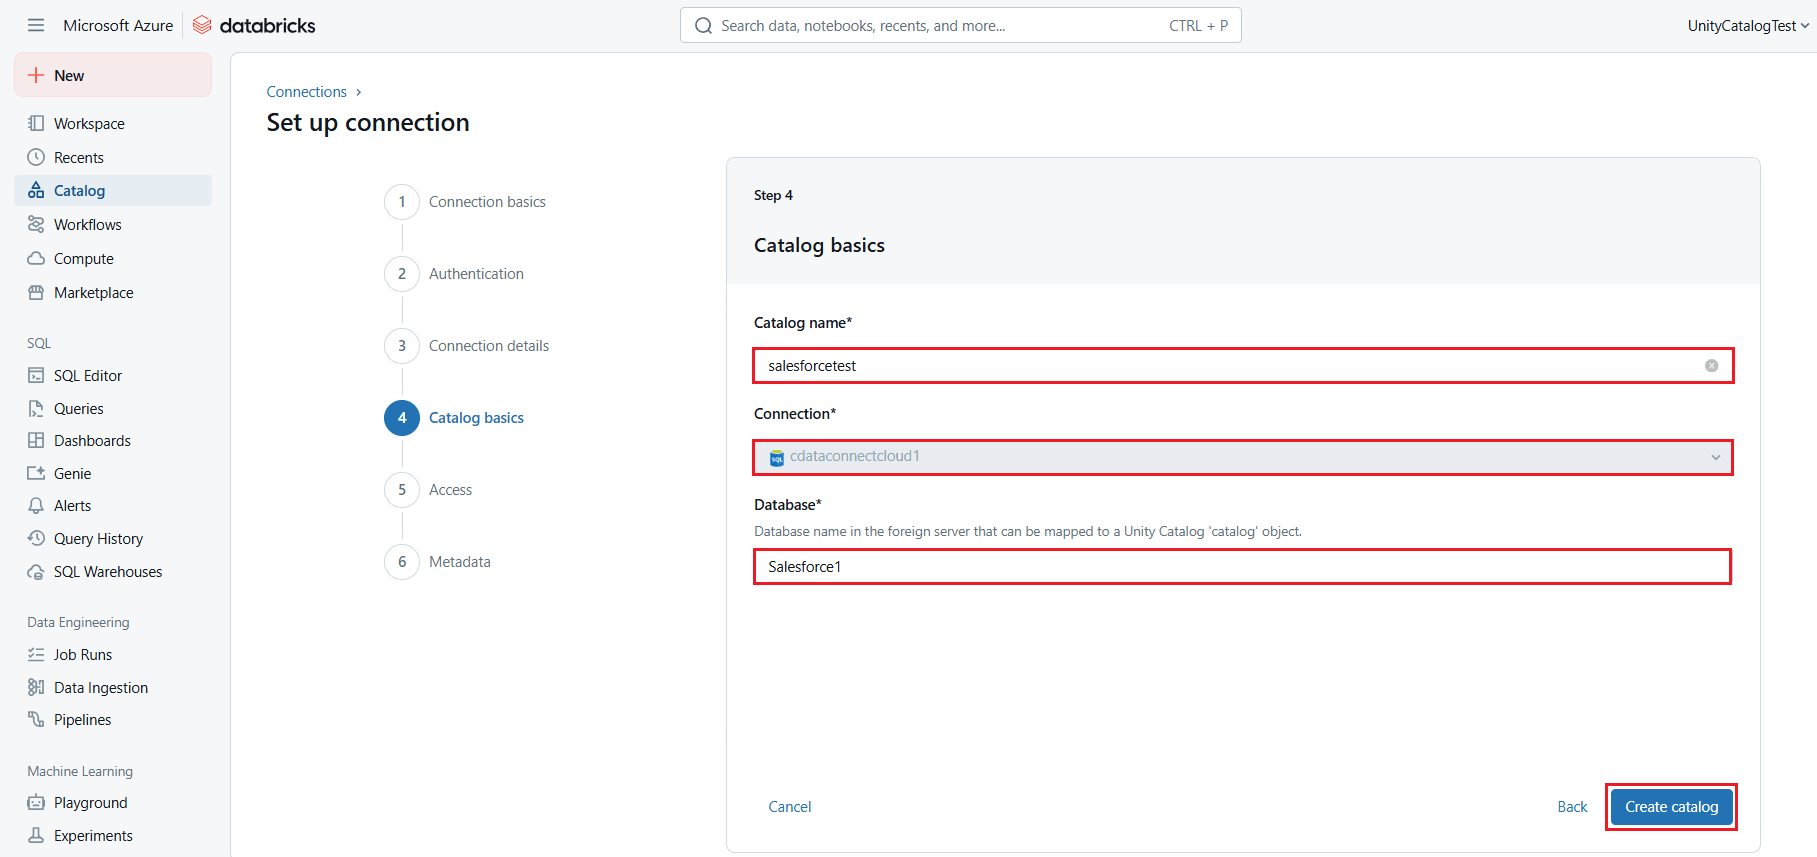
- In the Catalog basics section (or Step 4), enter the required details and click Create catalog:
- Catalog name: enter a name of your choice
- Connection: this will be the Databricks connection you defined earlier
- Database: enter your XML connection name (for example, XML1)
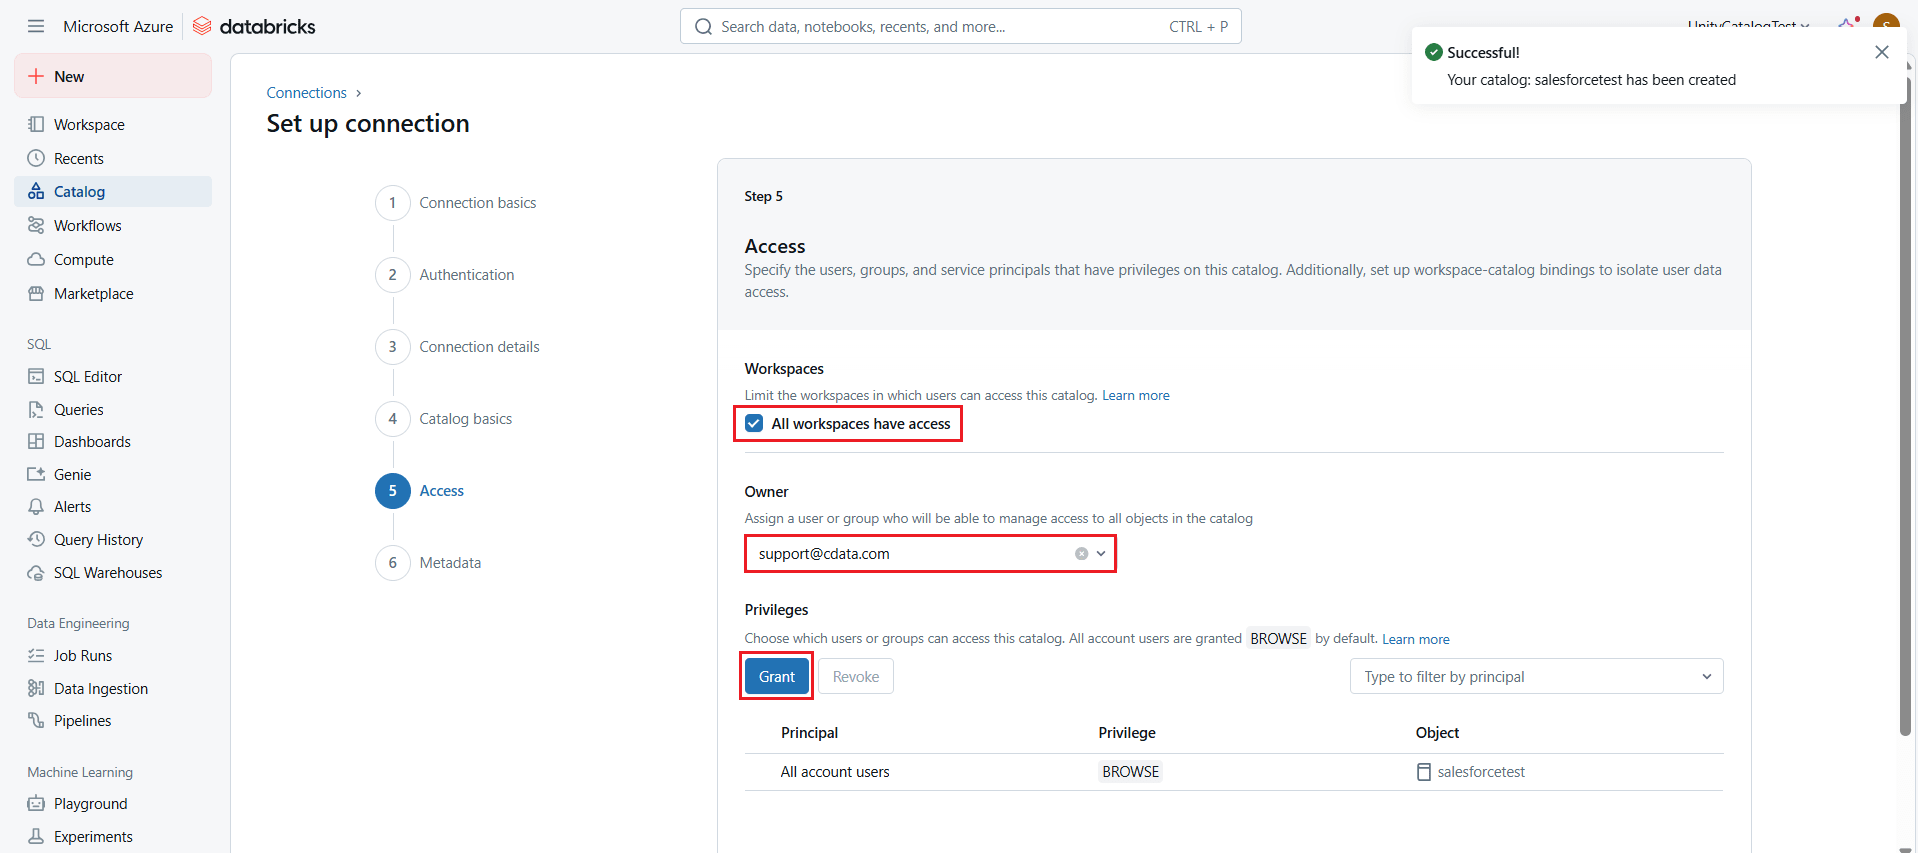
- In the Access section (or Step 5), assign the Workspace, User access rights, and Grant read or edit privileges to the catalog.
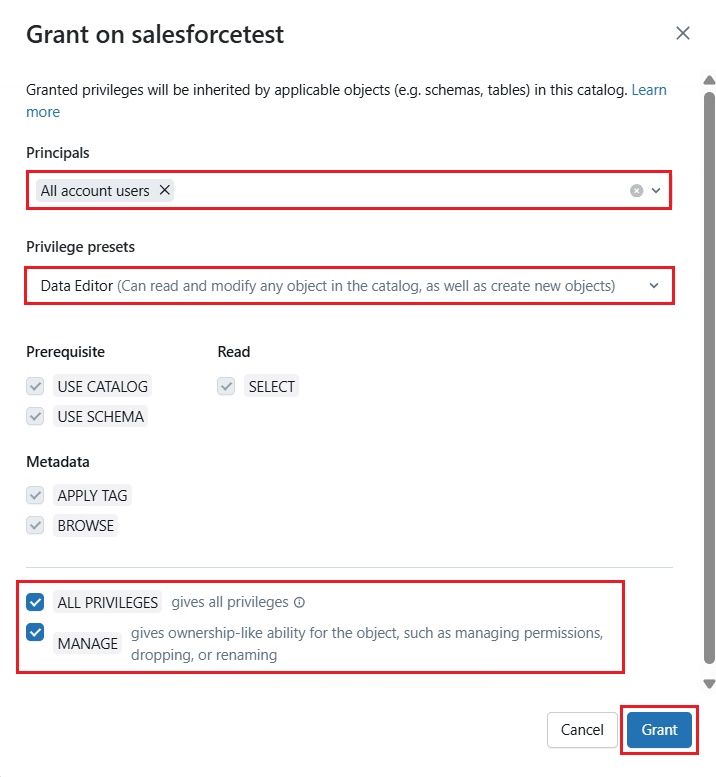
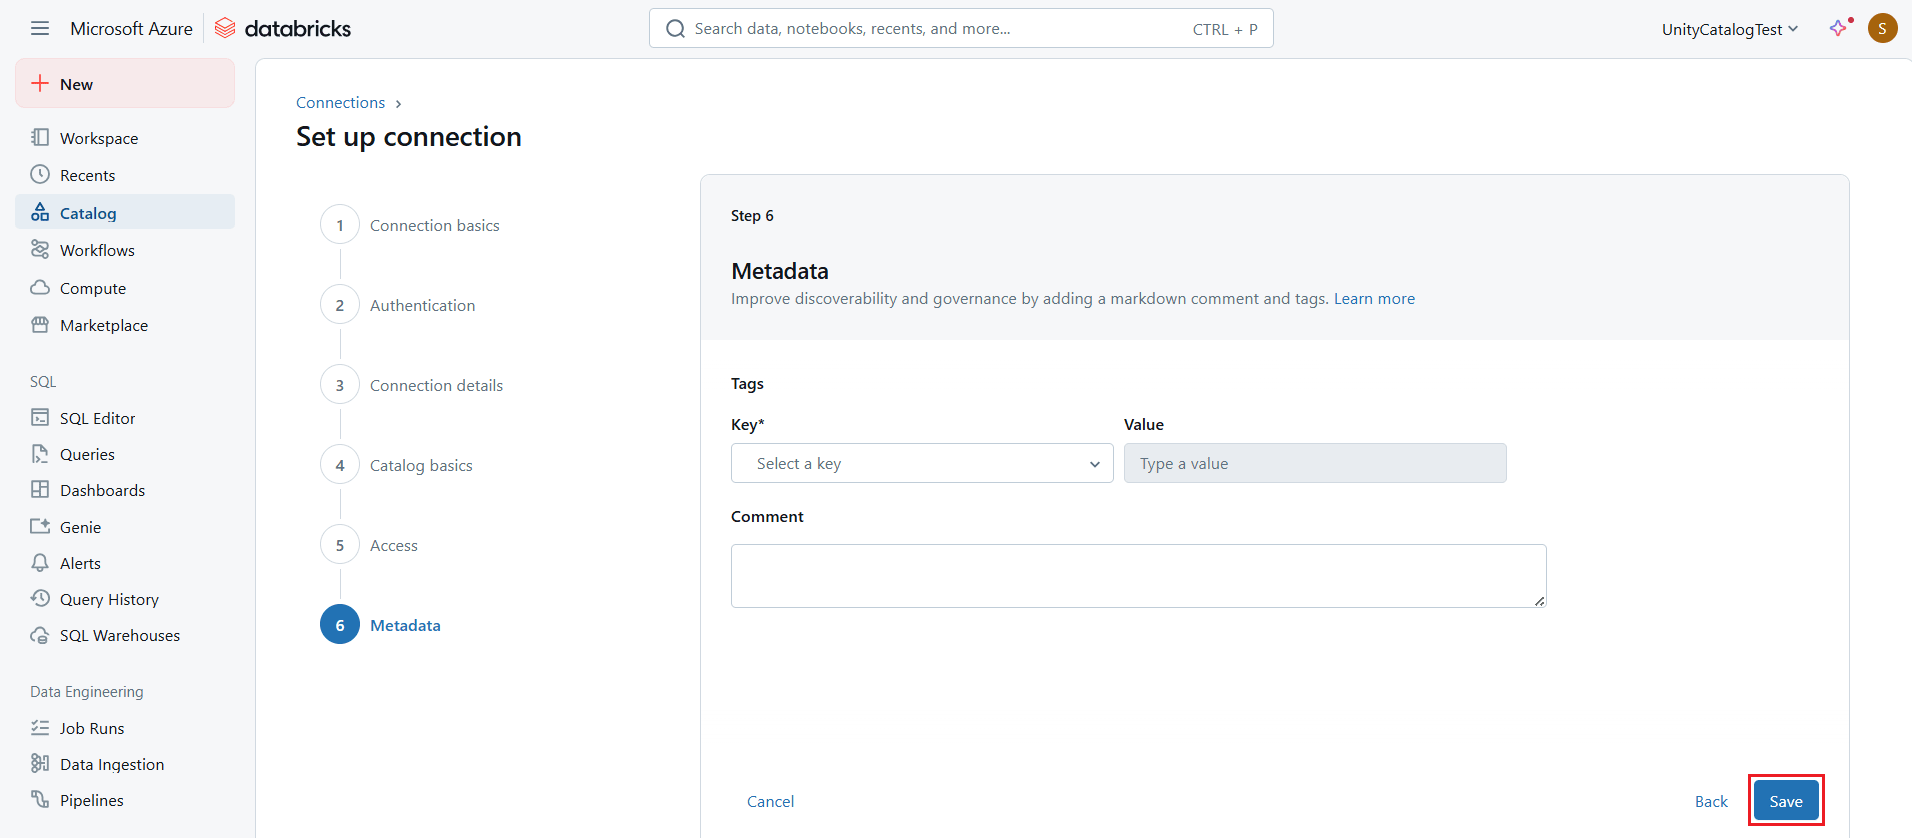
- Click Next > Save to save all the details for the catalog.
Access the catalog and visualize live XML data in Databricks
To access the newly created catalog and create a dashboard to visualize live XML data in Databricks, follow these steps:
- Select the catalog and expand it. A list of tables from XML will appear on the screen.
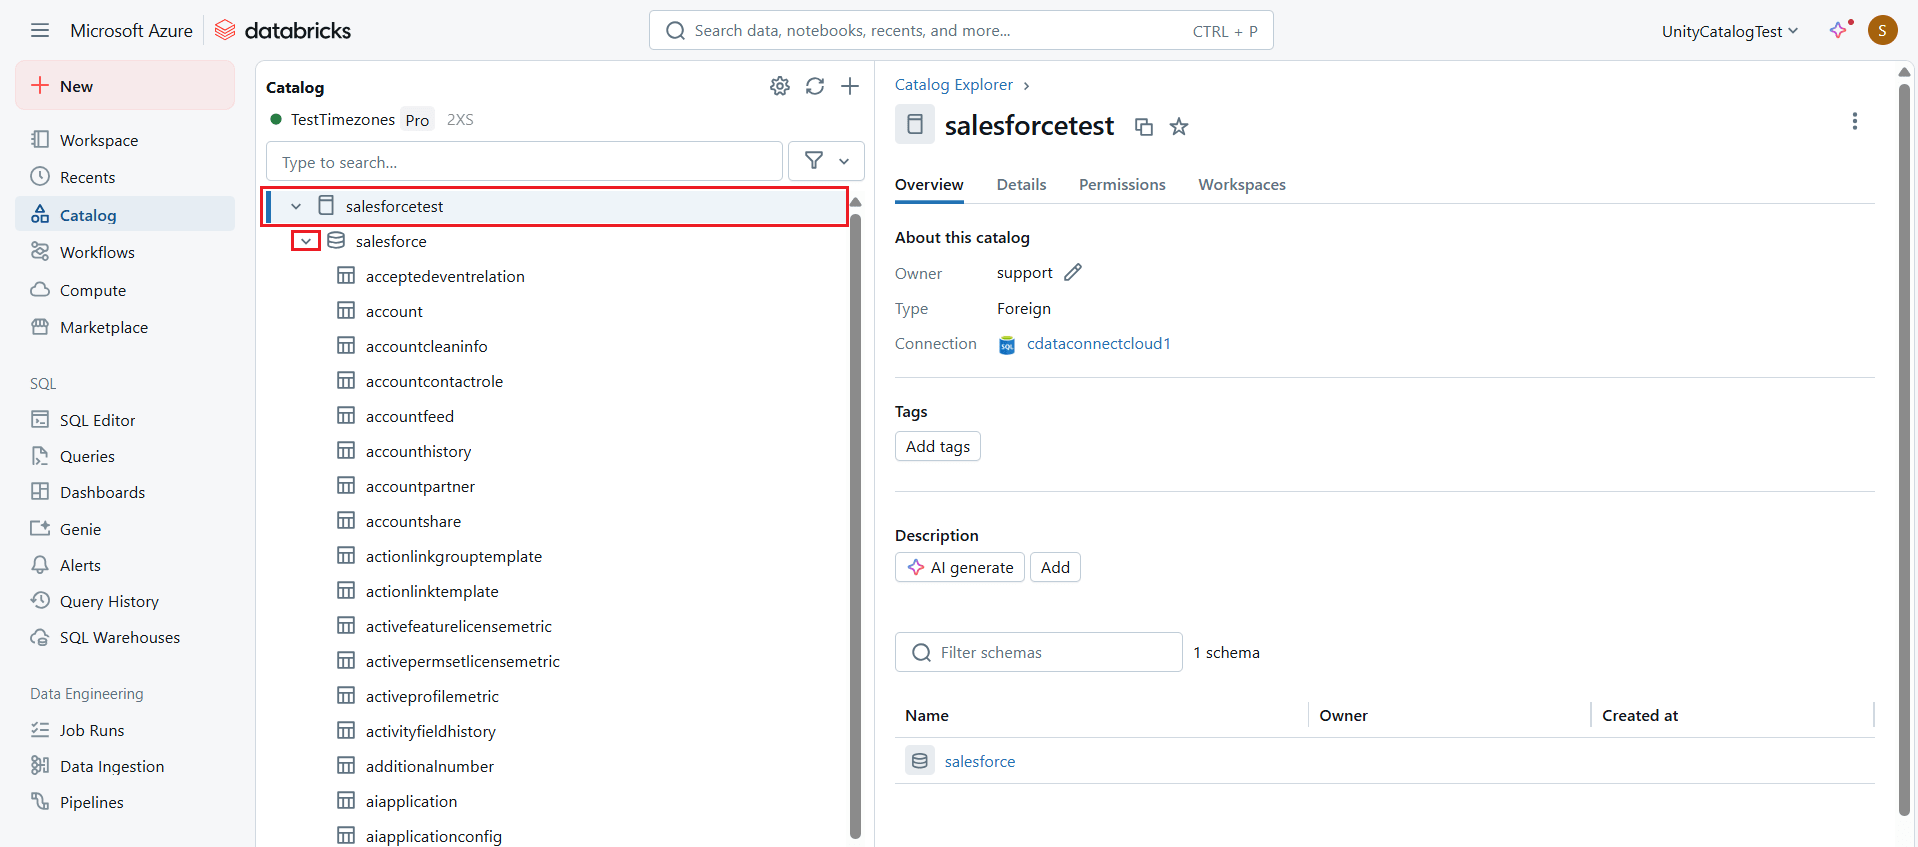
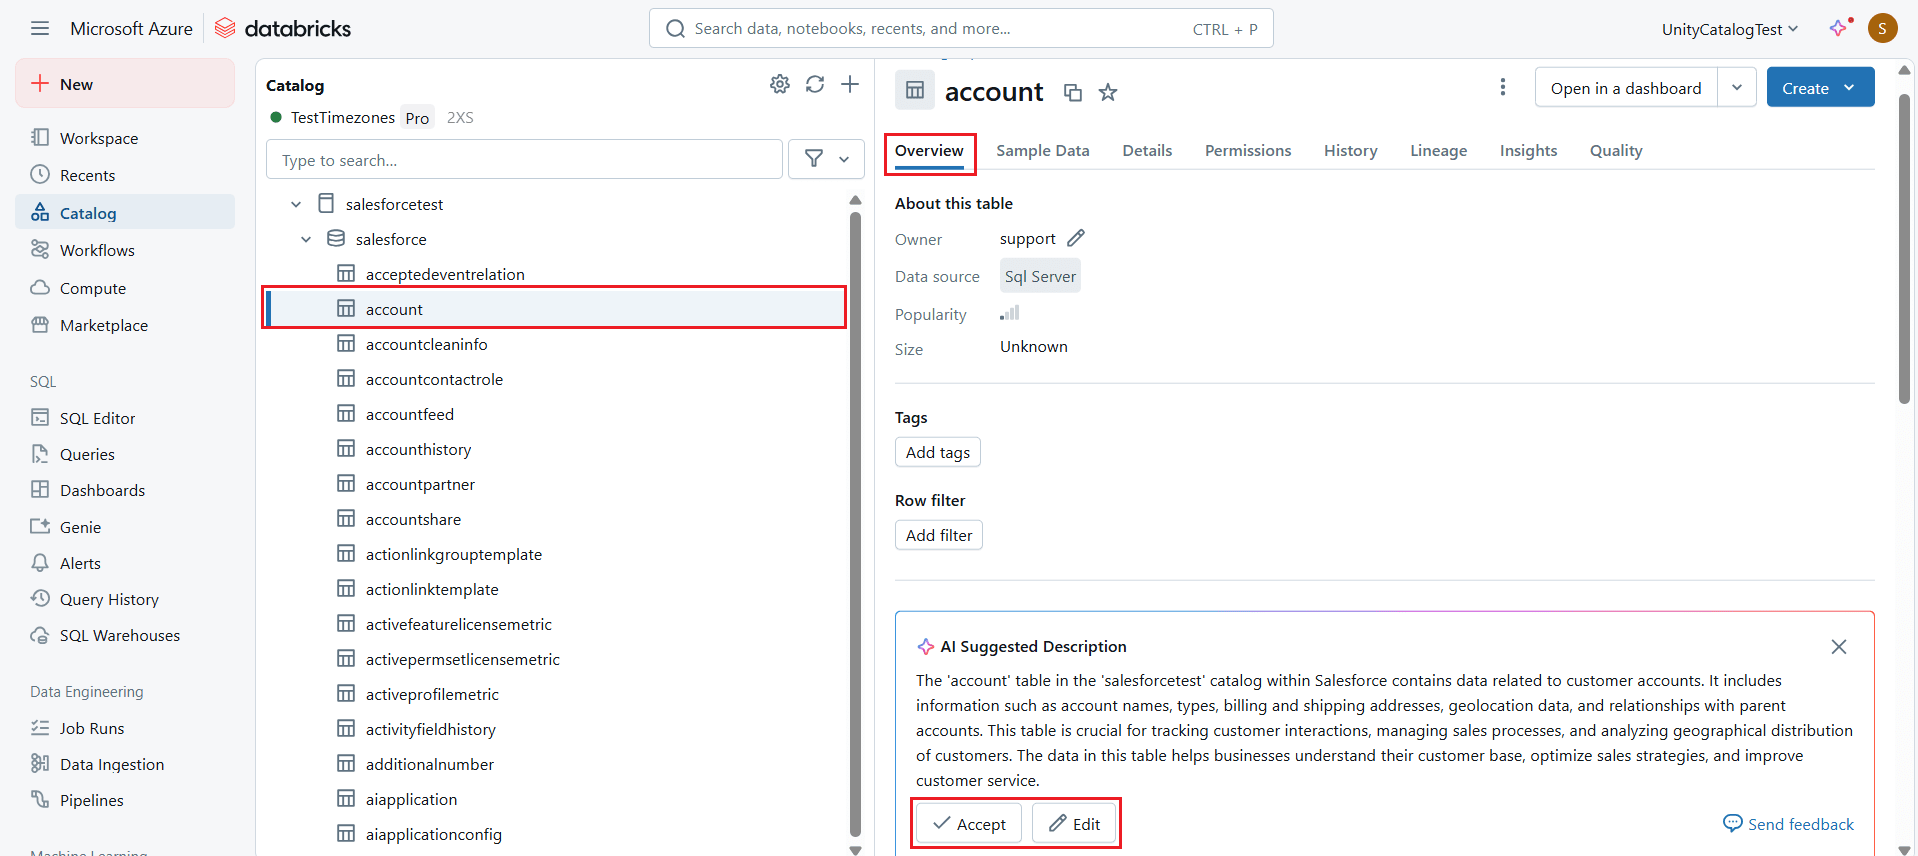
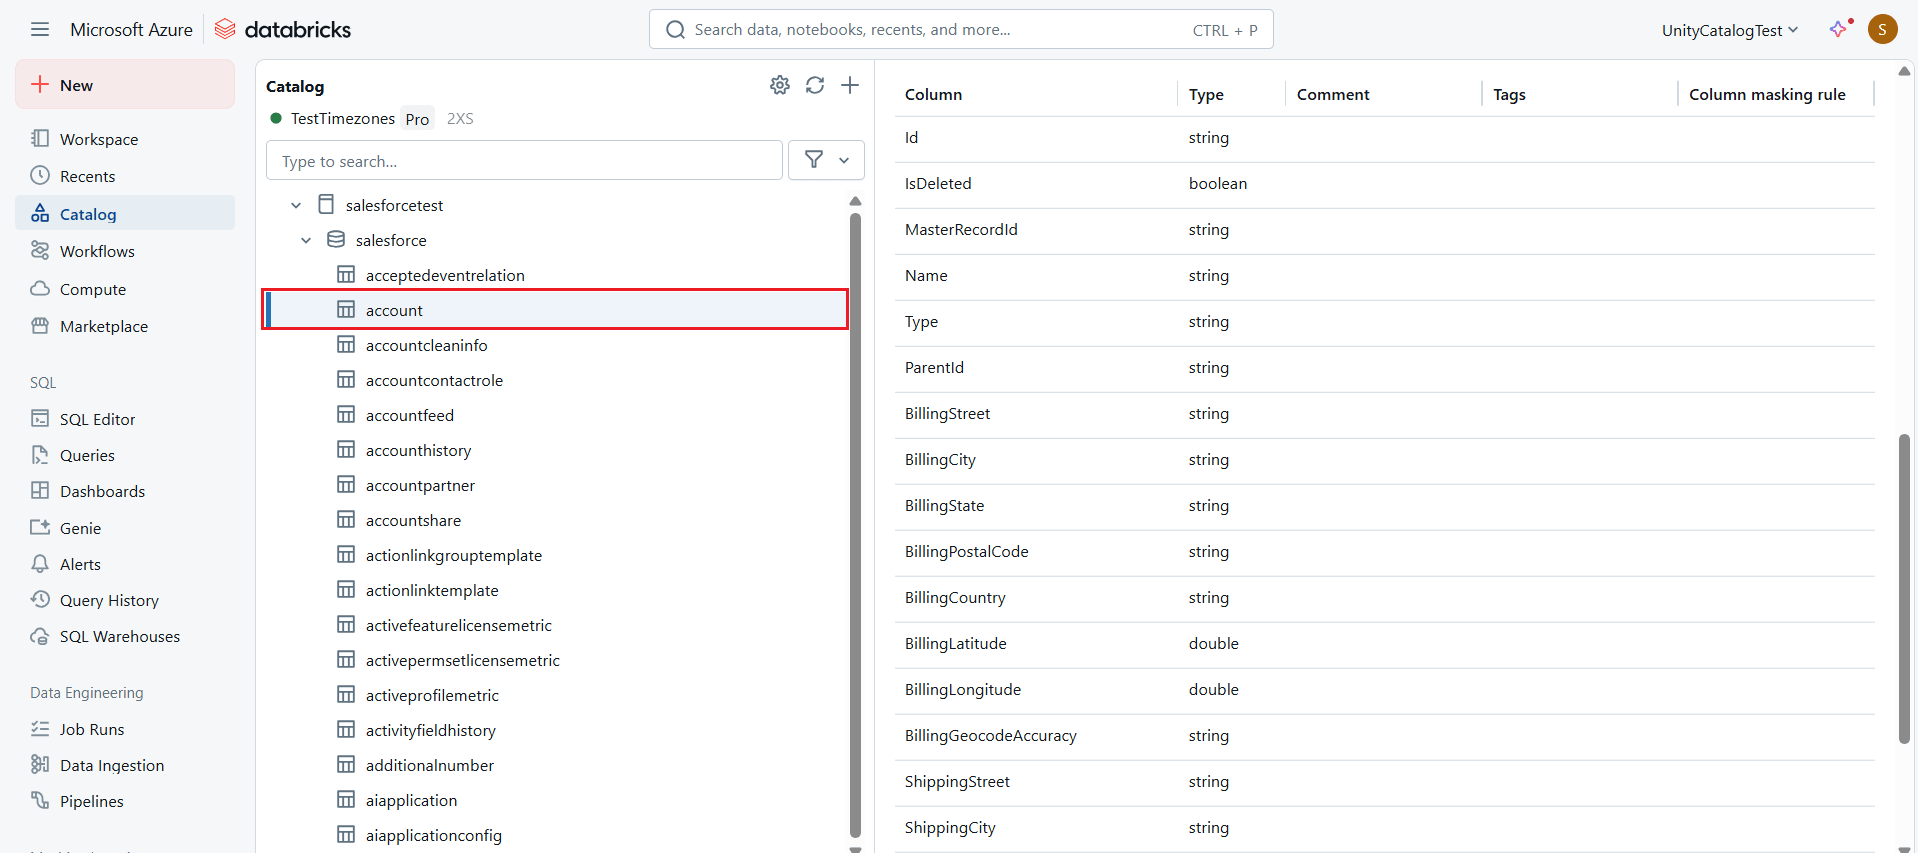
- Choose the desired table and click the Overview tab to view the table metadata.
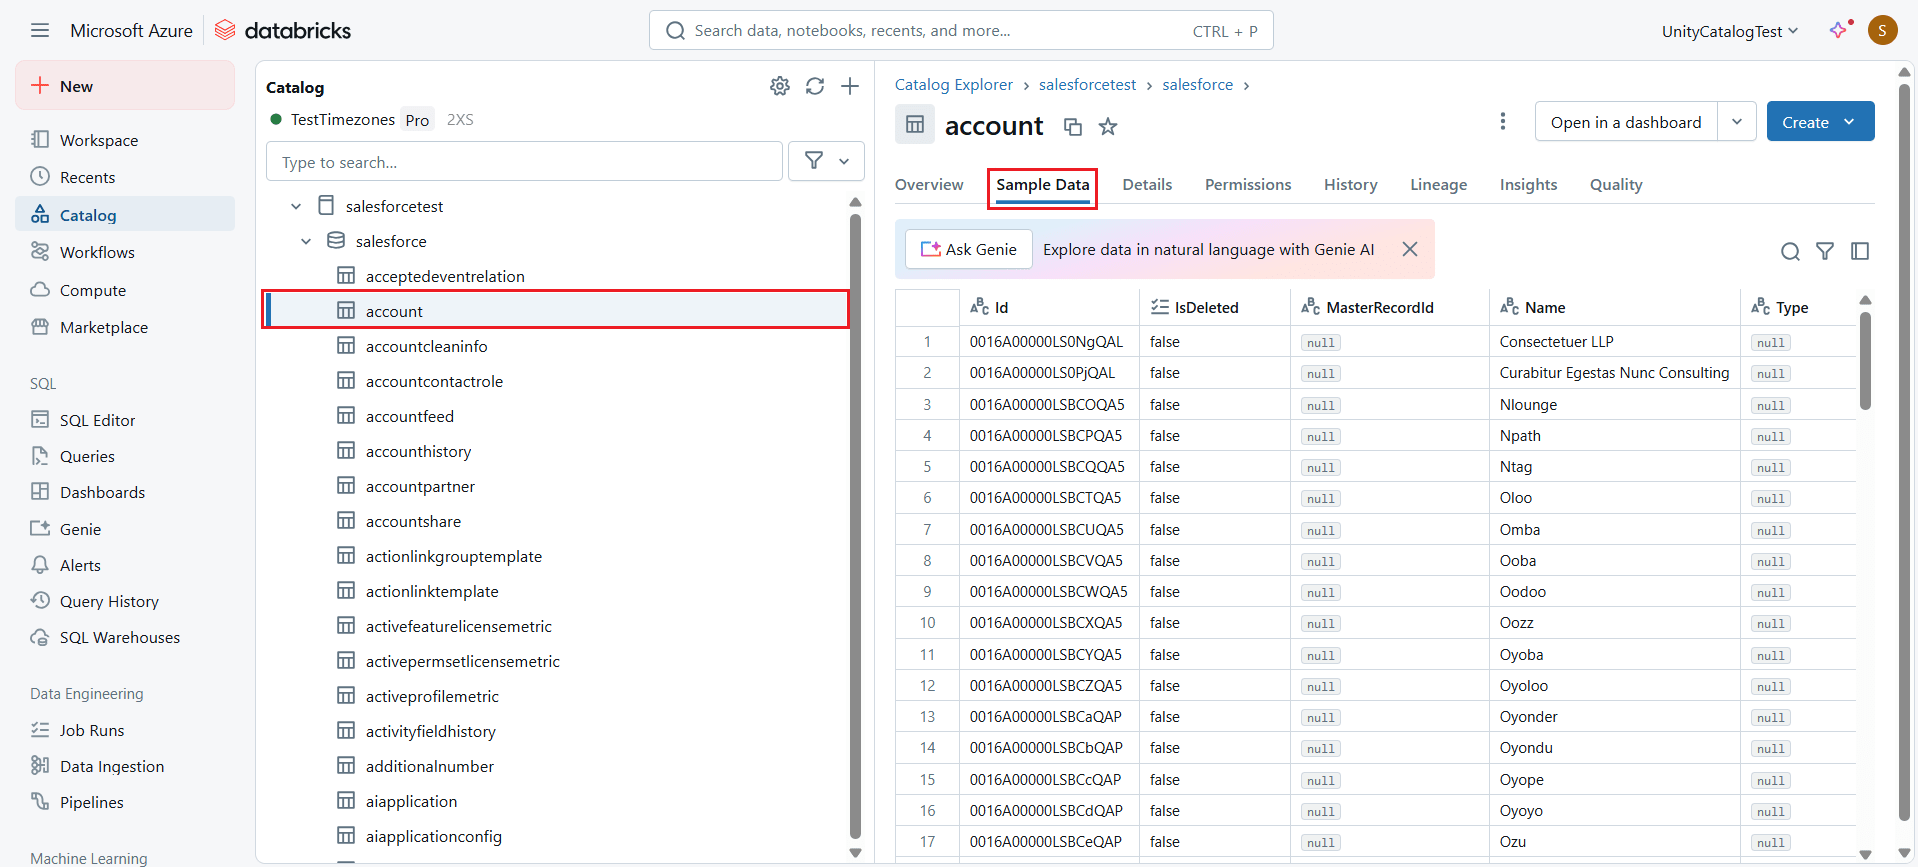
- Click the Sample Data tab to view real-time data in the table.
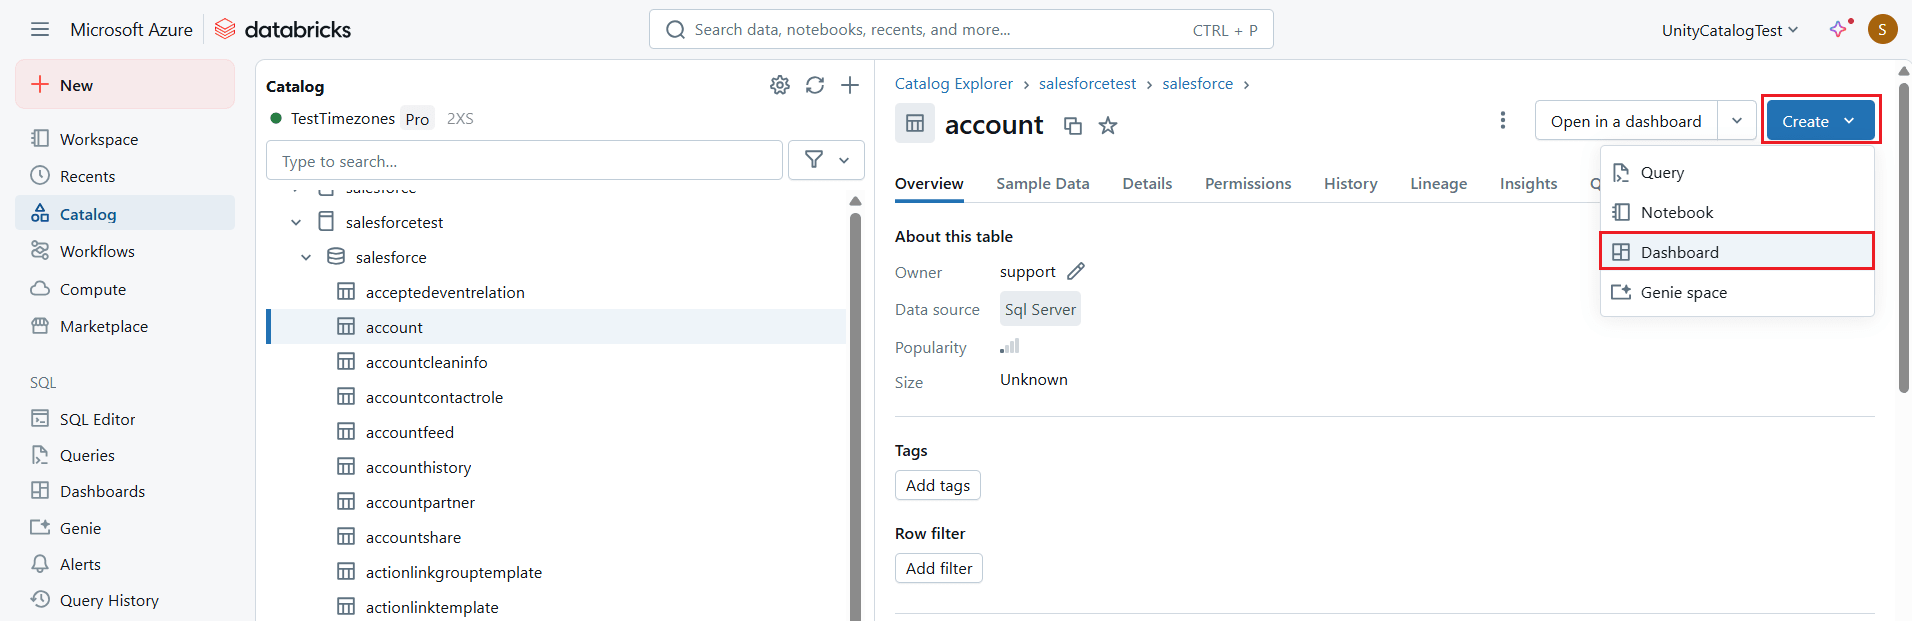
- Now, click Create at the top right corner and select Dashboard.
- Manually create a visualization by selecting at least one field in the visualization editor from the widget, or choose one of the visualization options suggested by Databricks AI.
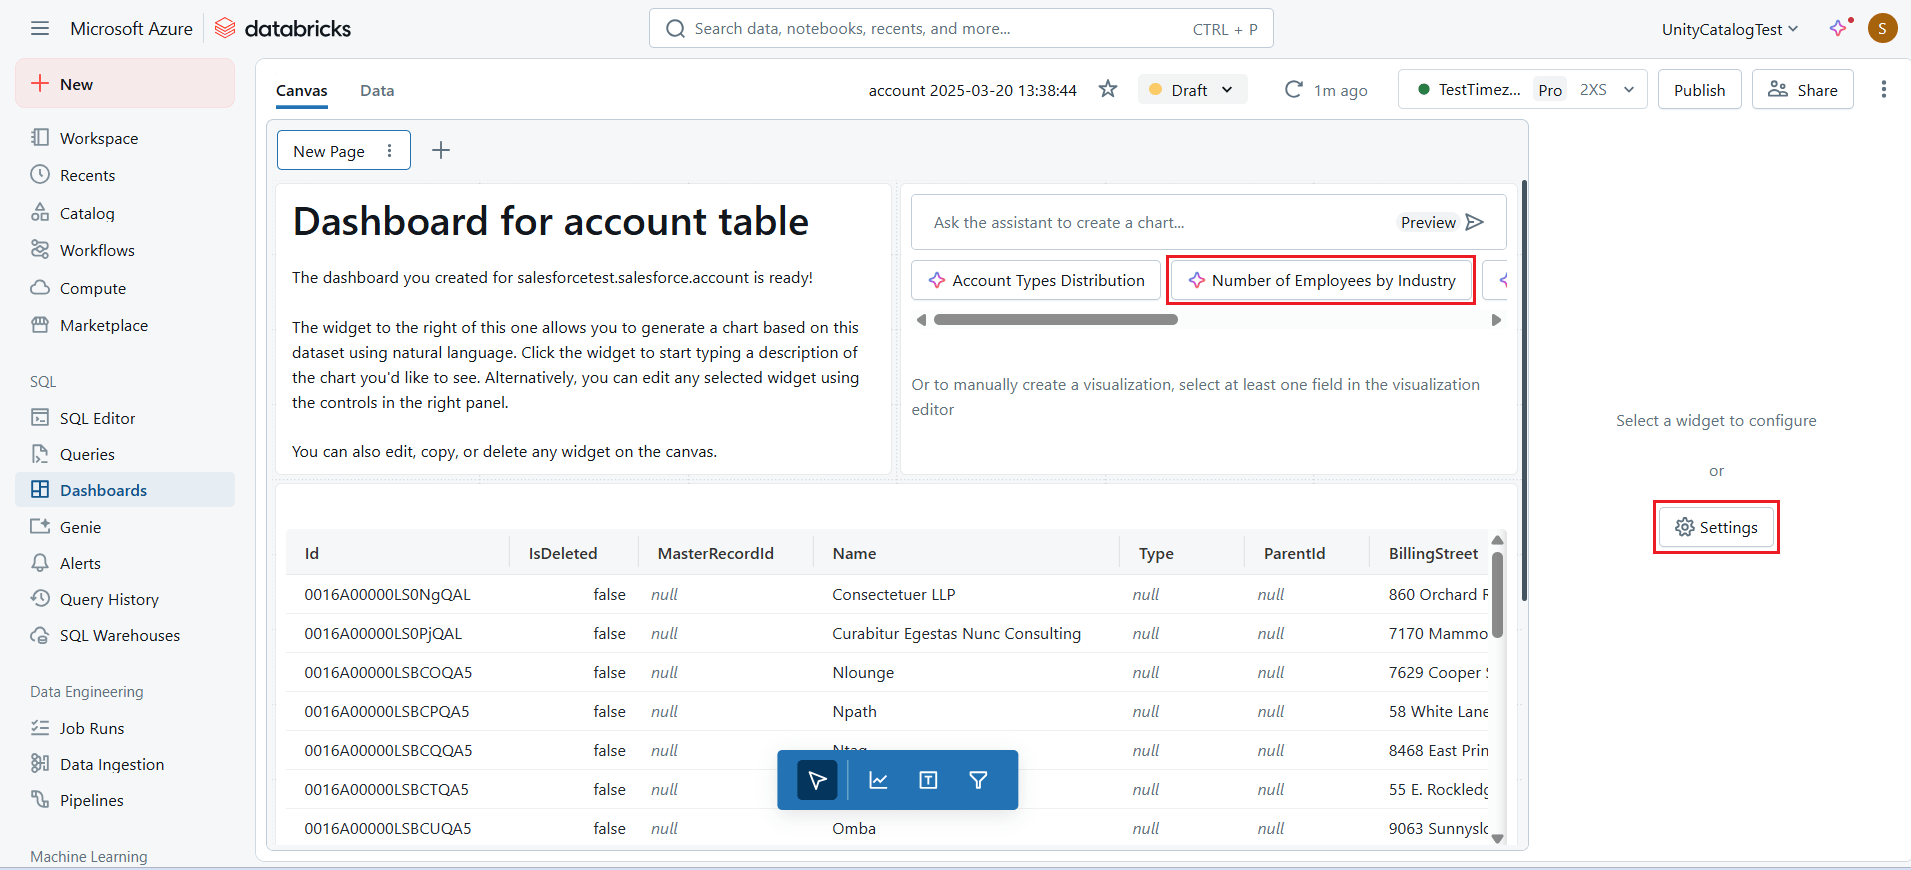
- Once the visualization is created, edit the details in the widget settings of the dashboard.
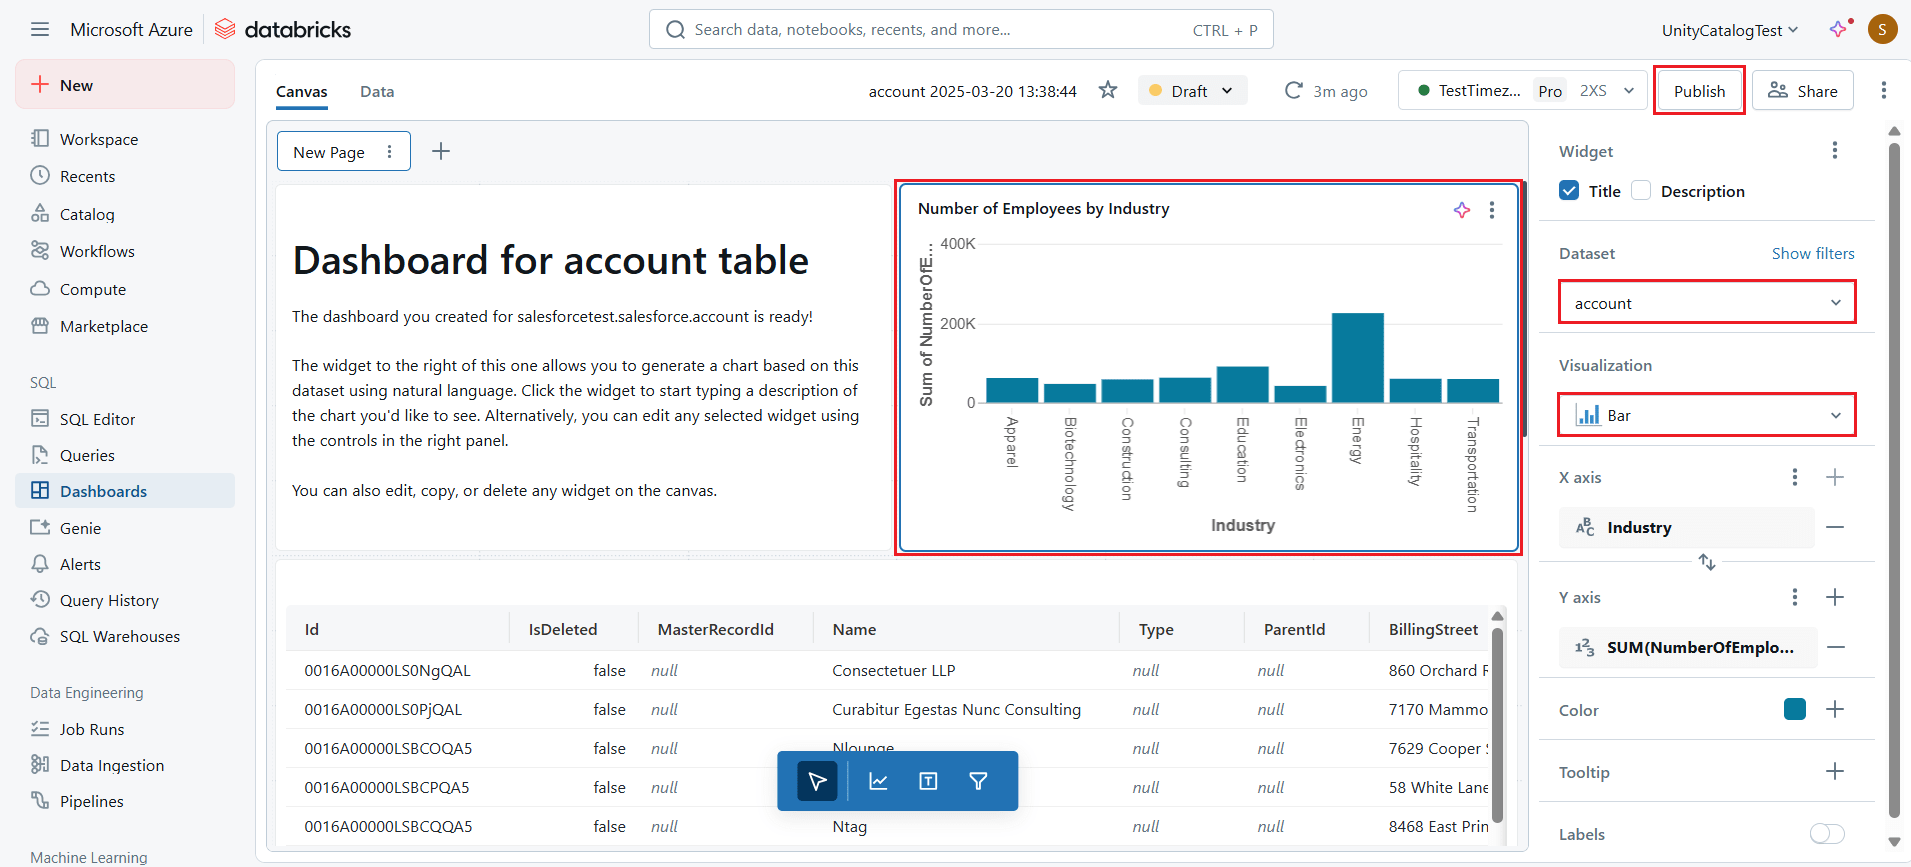
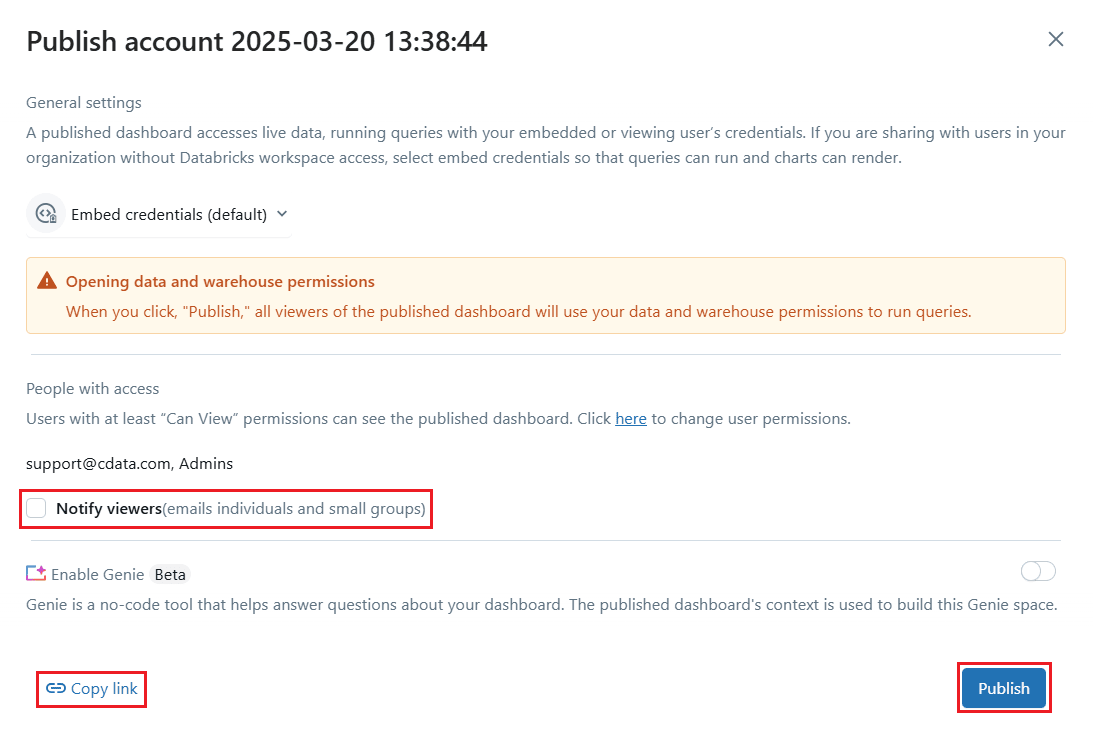
- Click Publish to publish the dashboard report.
Live access to XML data from cloud applications
At this stage, you have established a direct, cloud-to-cloud connection to live XML data in Databricks. This enables you to create dashboards to monitor and visualize your data seamlessly.
For more details on accessing live data from over 100 SaaS, Big Data, and NoSQL sources through cloud applications like Databricks, visit our Connect AI page. As always, let us know if you have any questions during your evaluation. Our world-class CData Support Team is always available to help!