


Getting Started with the CData Connect AI Python SDK for Kafka
The CData Connect AI Python SDK (cdata-connect-ai) is a DB-API 2.0 (PEP 249) compliant client that lets you fetch and act on live Kafka data with standard Python database code. Because Connect AI provides the connectivity: you install one package, authenticate with a Personal Access Token, and query Kafka (and every other source connected in Connect AI) using the same familiar connect() / cursor() / fetchall() pattern you already know from libraries like sqlite3 and psycopg2.
This guide walks through connecting Kafka in Connect AI, generating a Personal Access Token, installing the SDK, and reading (and, where supported, writing) live Kafka data.
Prerequisites
- An account in CData Connect AI
- Python 3.8 or higher
- An active Kafka account with valid credentials
Connect to Kafka in Connect AI
CData Connect AI uses a straightforward, point-and-click interface to connect to data sources.
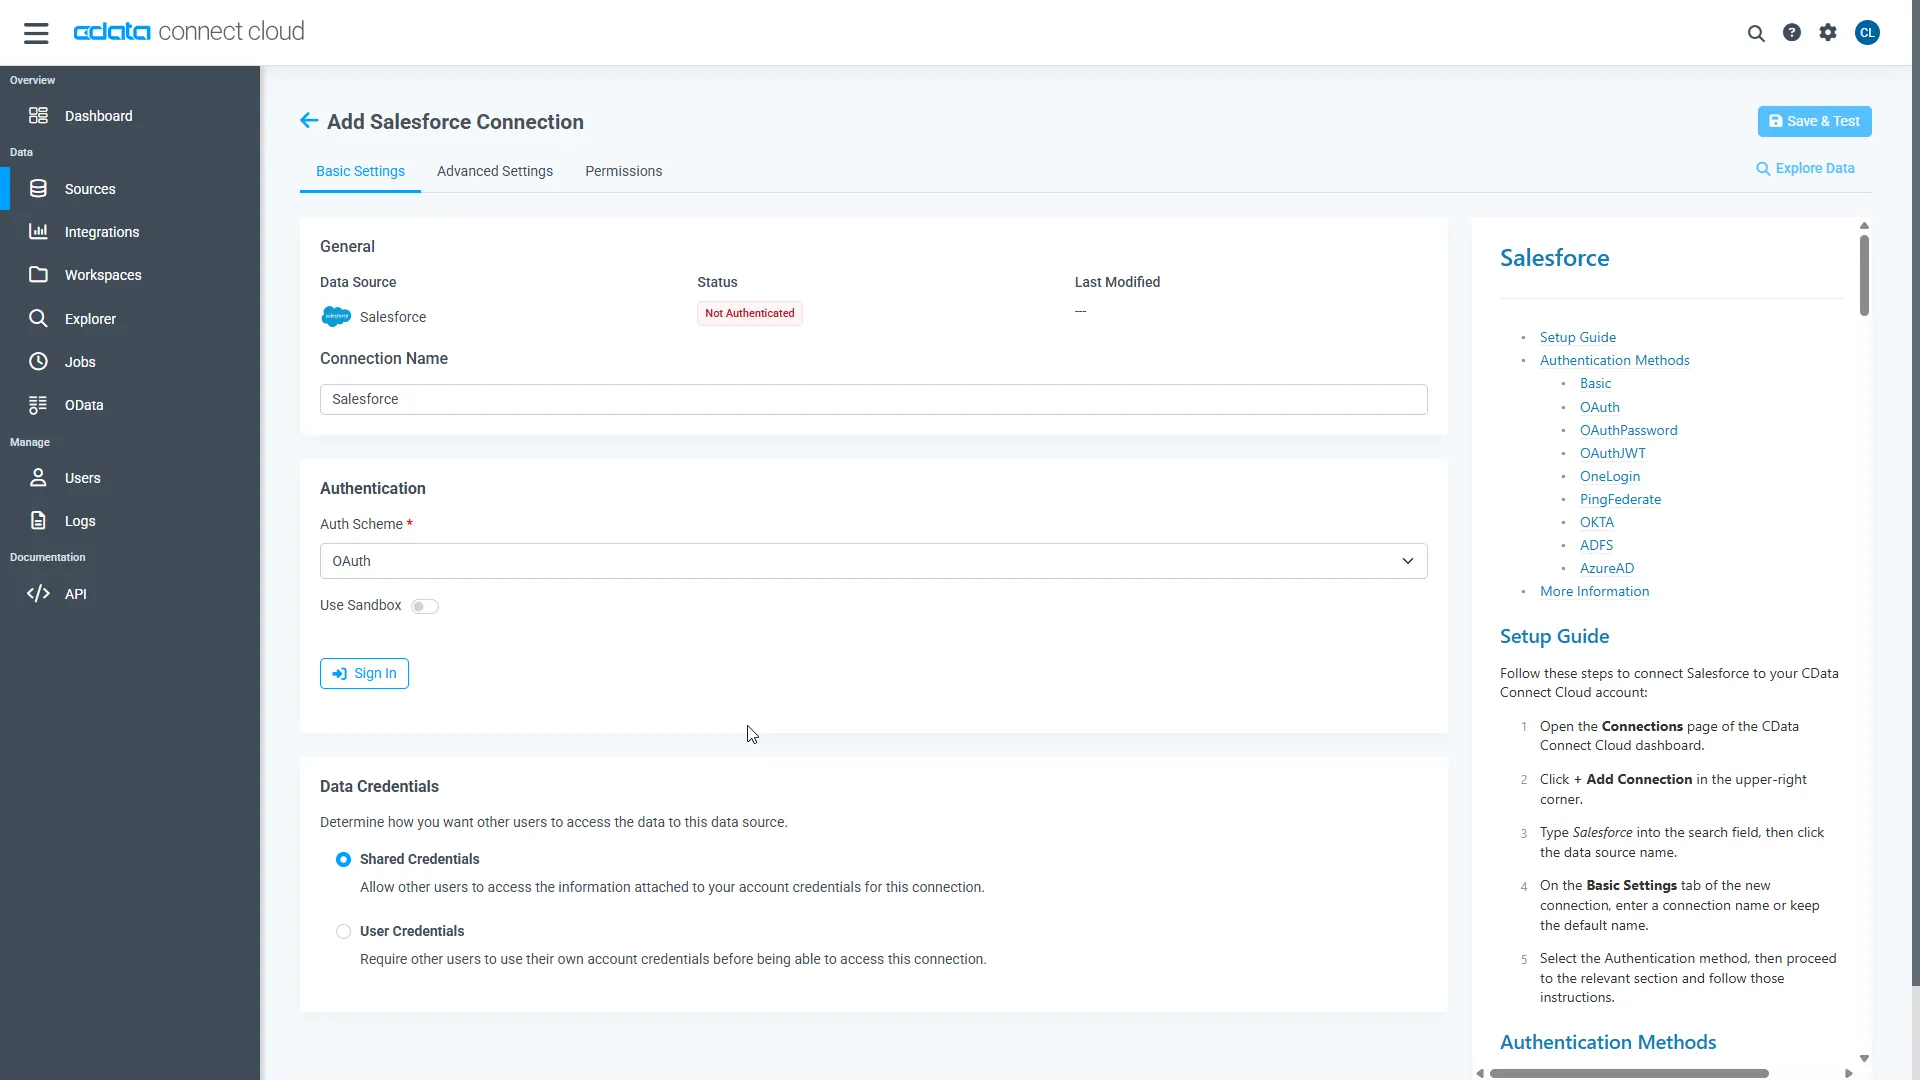
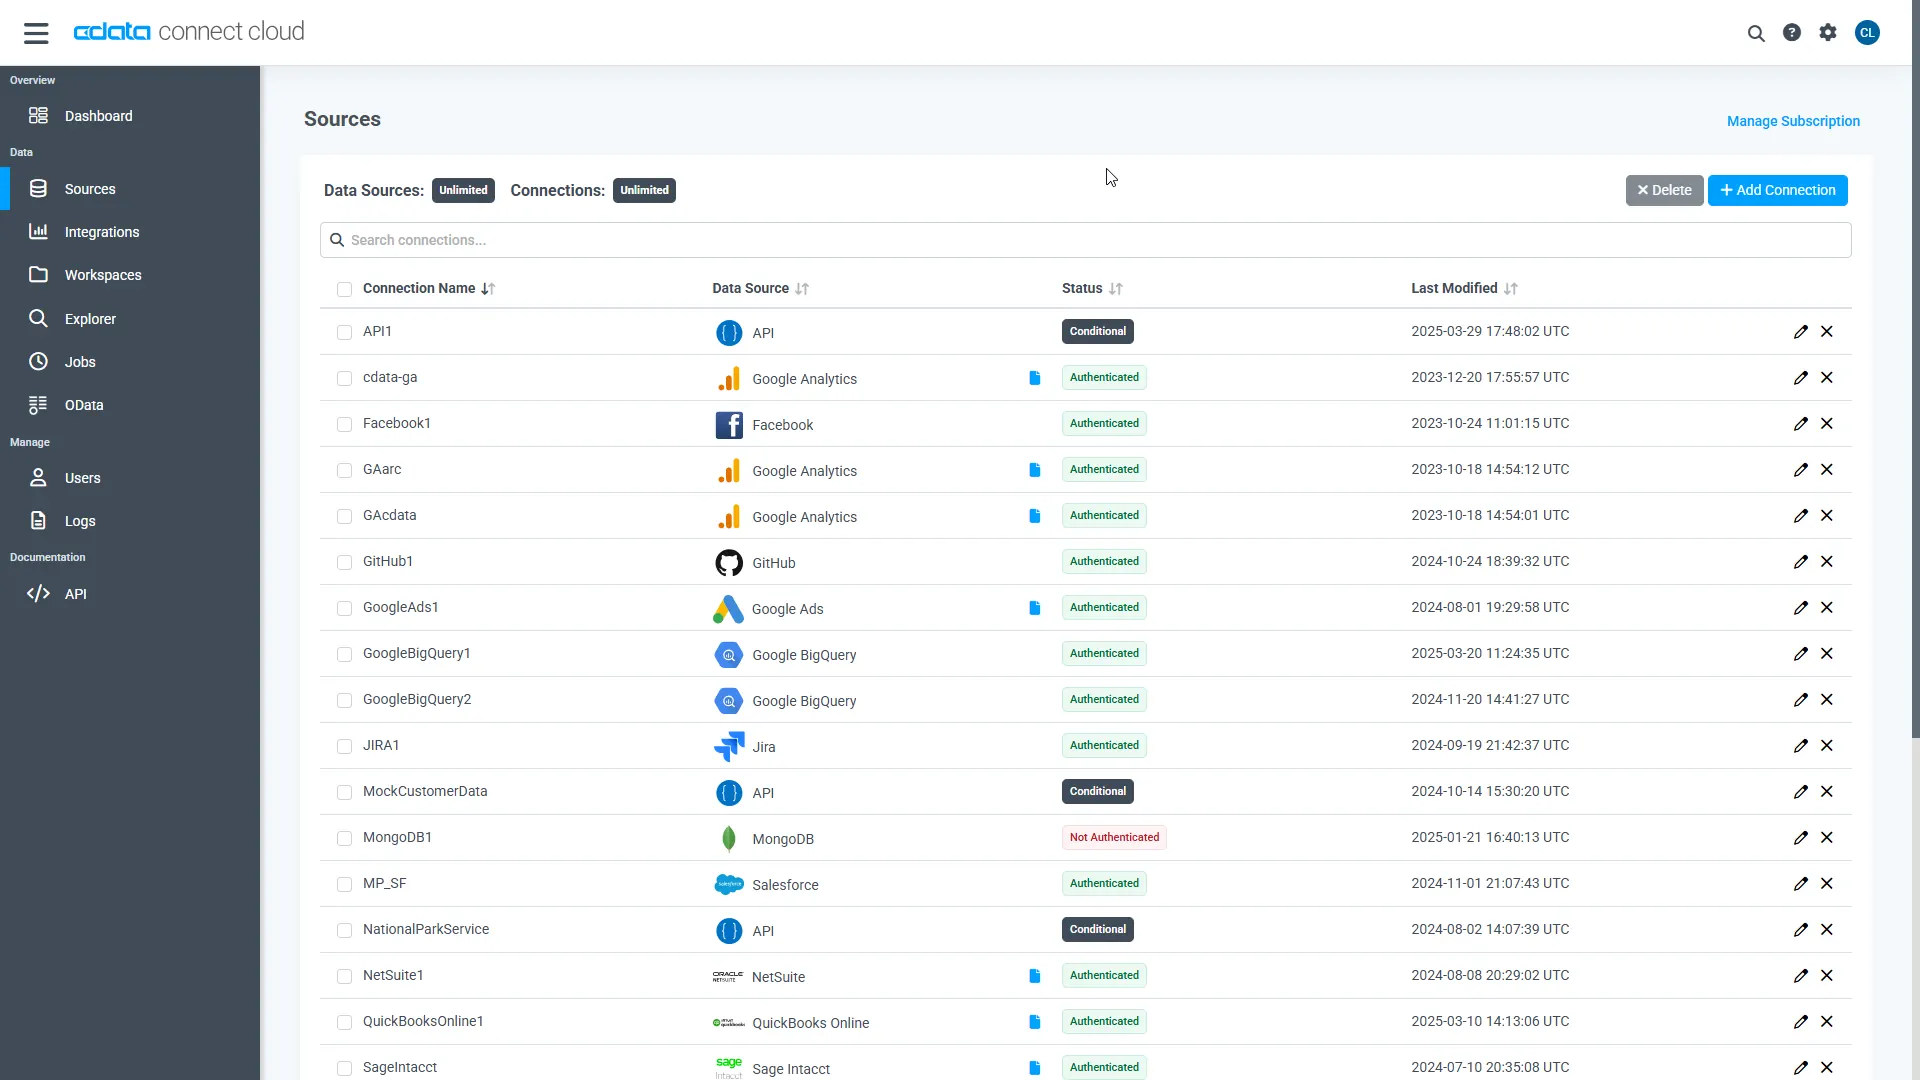
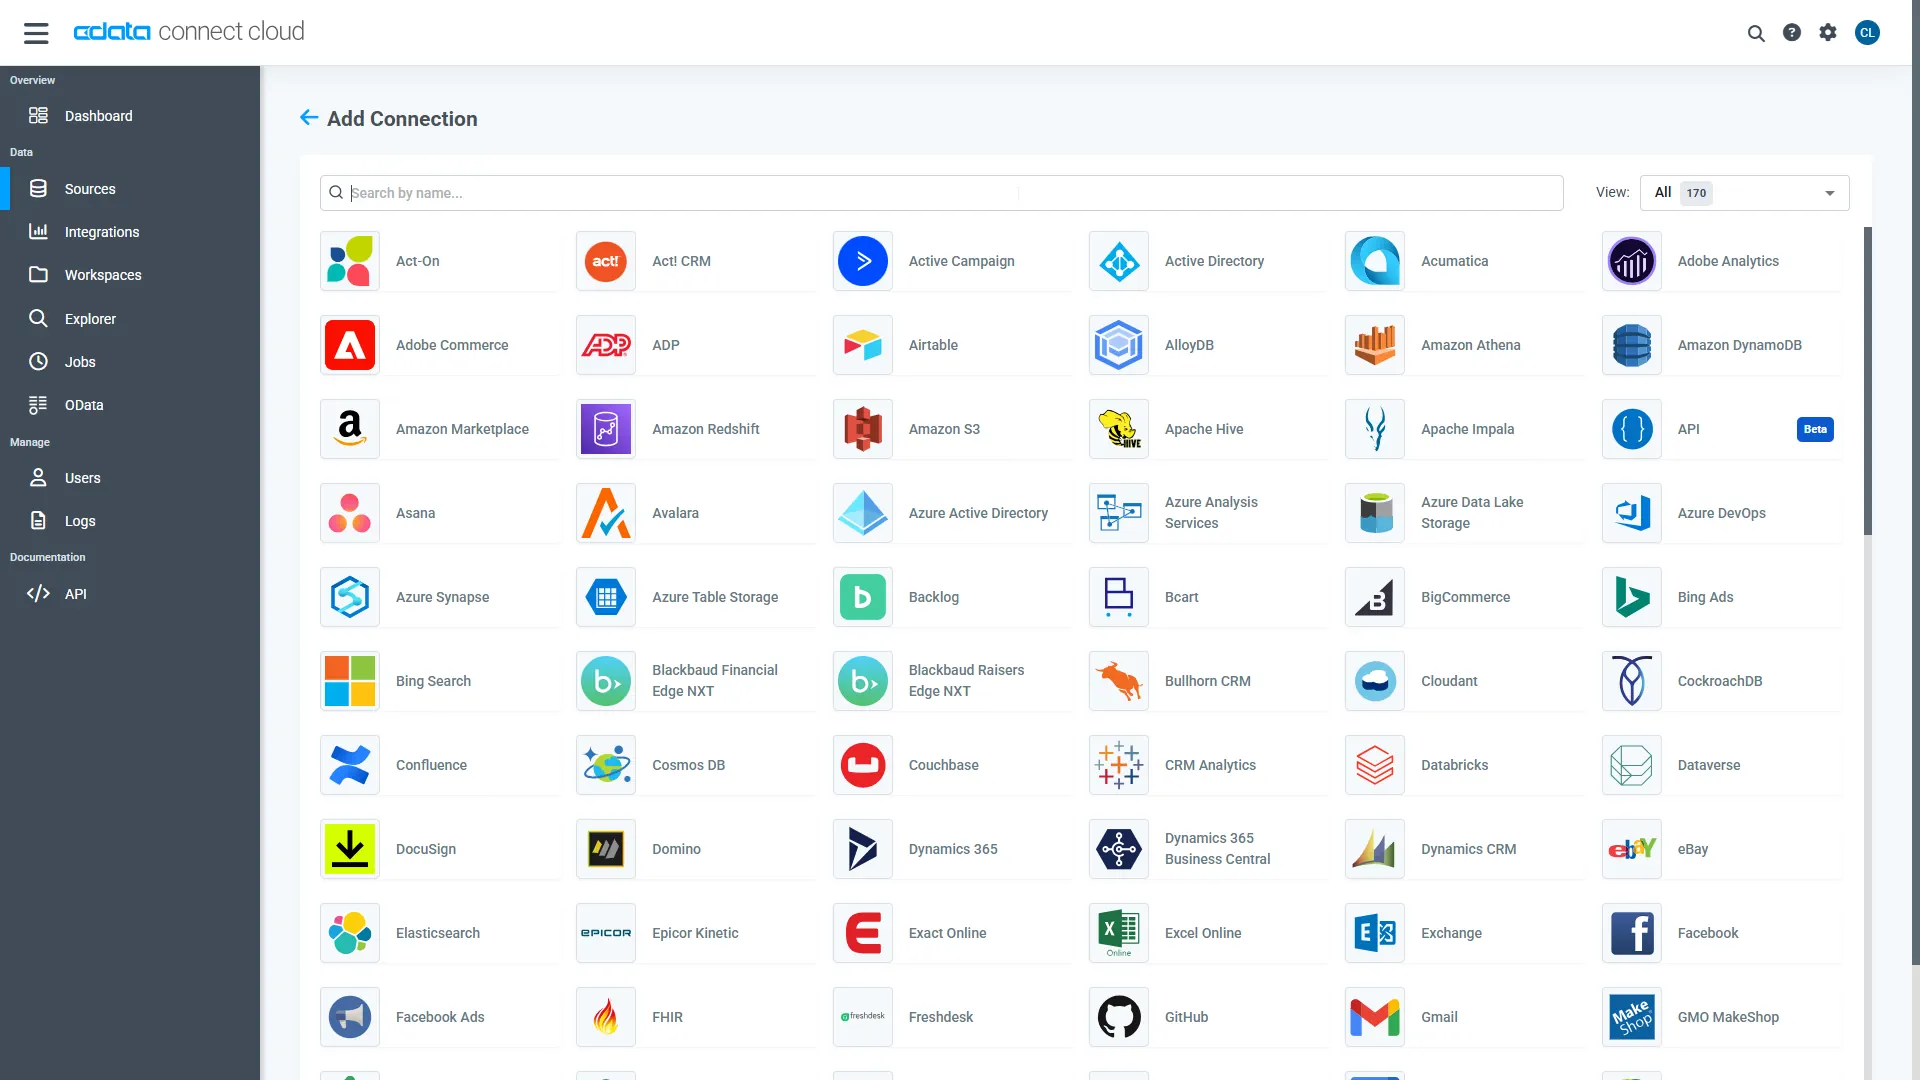
- Log into Connect AI, click Sources, and then click Add Connection
- Select "Kafka" from the Add Connection panel
-
Enter the necessary authentication properties to connect to Kafka.
Set BootstrapServers and the Topic properties to specify the address of your Apache Kafka server, as well as the topic you would like to interact with.
Authorization Mechanisms
- SASL Plain: The User and Password properties should be specified. AuthScheme should be set to 'Plain'.
- SASL SSL: The User and Password properties should be specified. AuthScheme should be set to 'Scram'. UseSSL should be set to true.
- SSL: The SSLCert and SSLCertPassword properties should be specified. UseSSL should be set to true.
- Kerberos: The User and Password properties should be specified. AuthScheme should be set to 'Kerberos'.
You may be required to trust the server certificate. In such cases, specify the TrustStorePath and the TrustStorePassword if necessary.
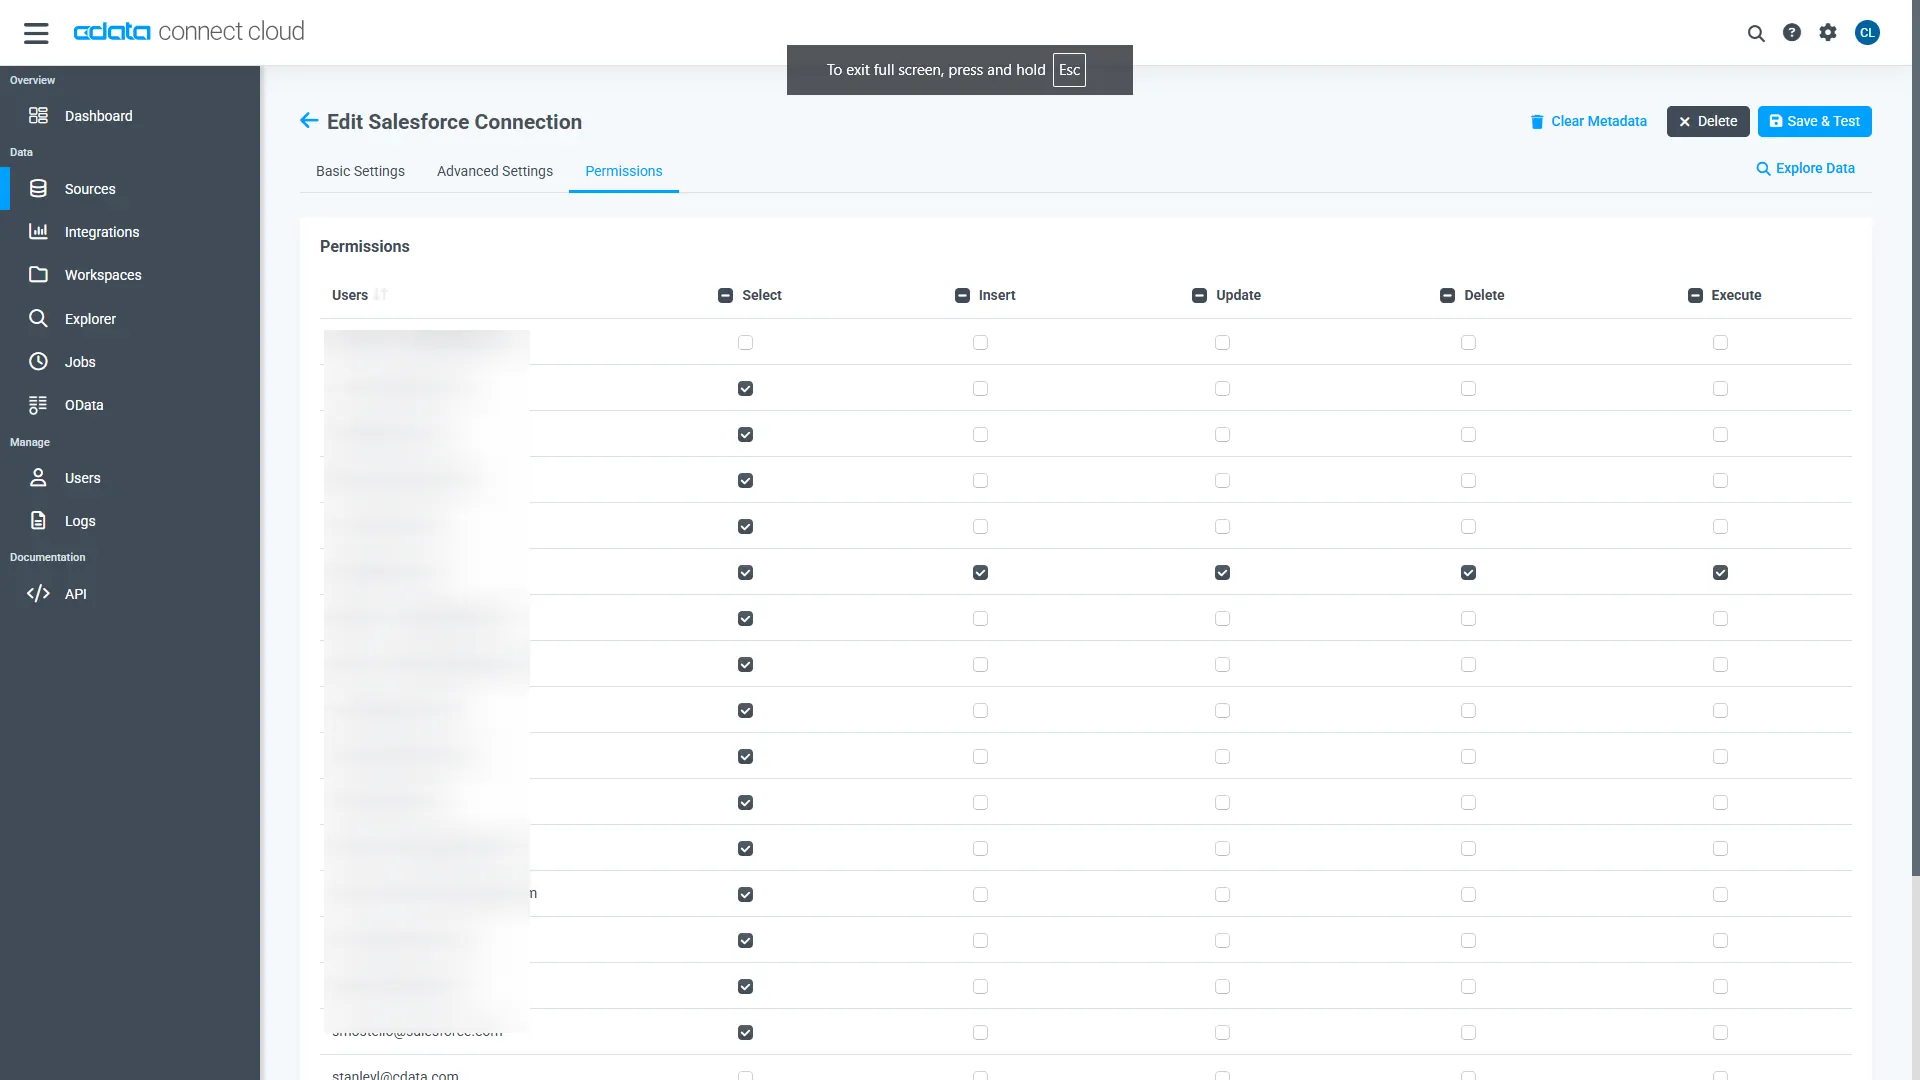
- Click Save & Test
- Navigate to the Permissions tab and update the user-based permissions.
Generate a Personal Access Token (PAT)
The Python SDK authenticates to Connect AI with your account email and a Personal Access Token (PAT). It is best practice to create a separate PAT for each application to maintain granularity of access.
- Click the Gear icon () at the top right of the Connect AI app to open the Settings page.
- On the Settings page, go to the Access Tokens section and click Create PAT.
- Give the PAT a name and click Create.
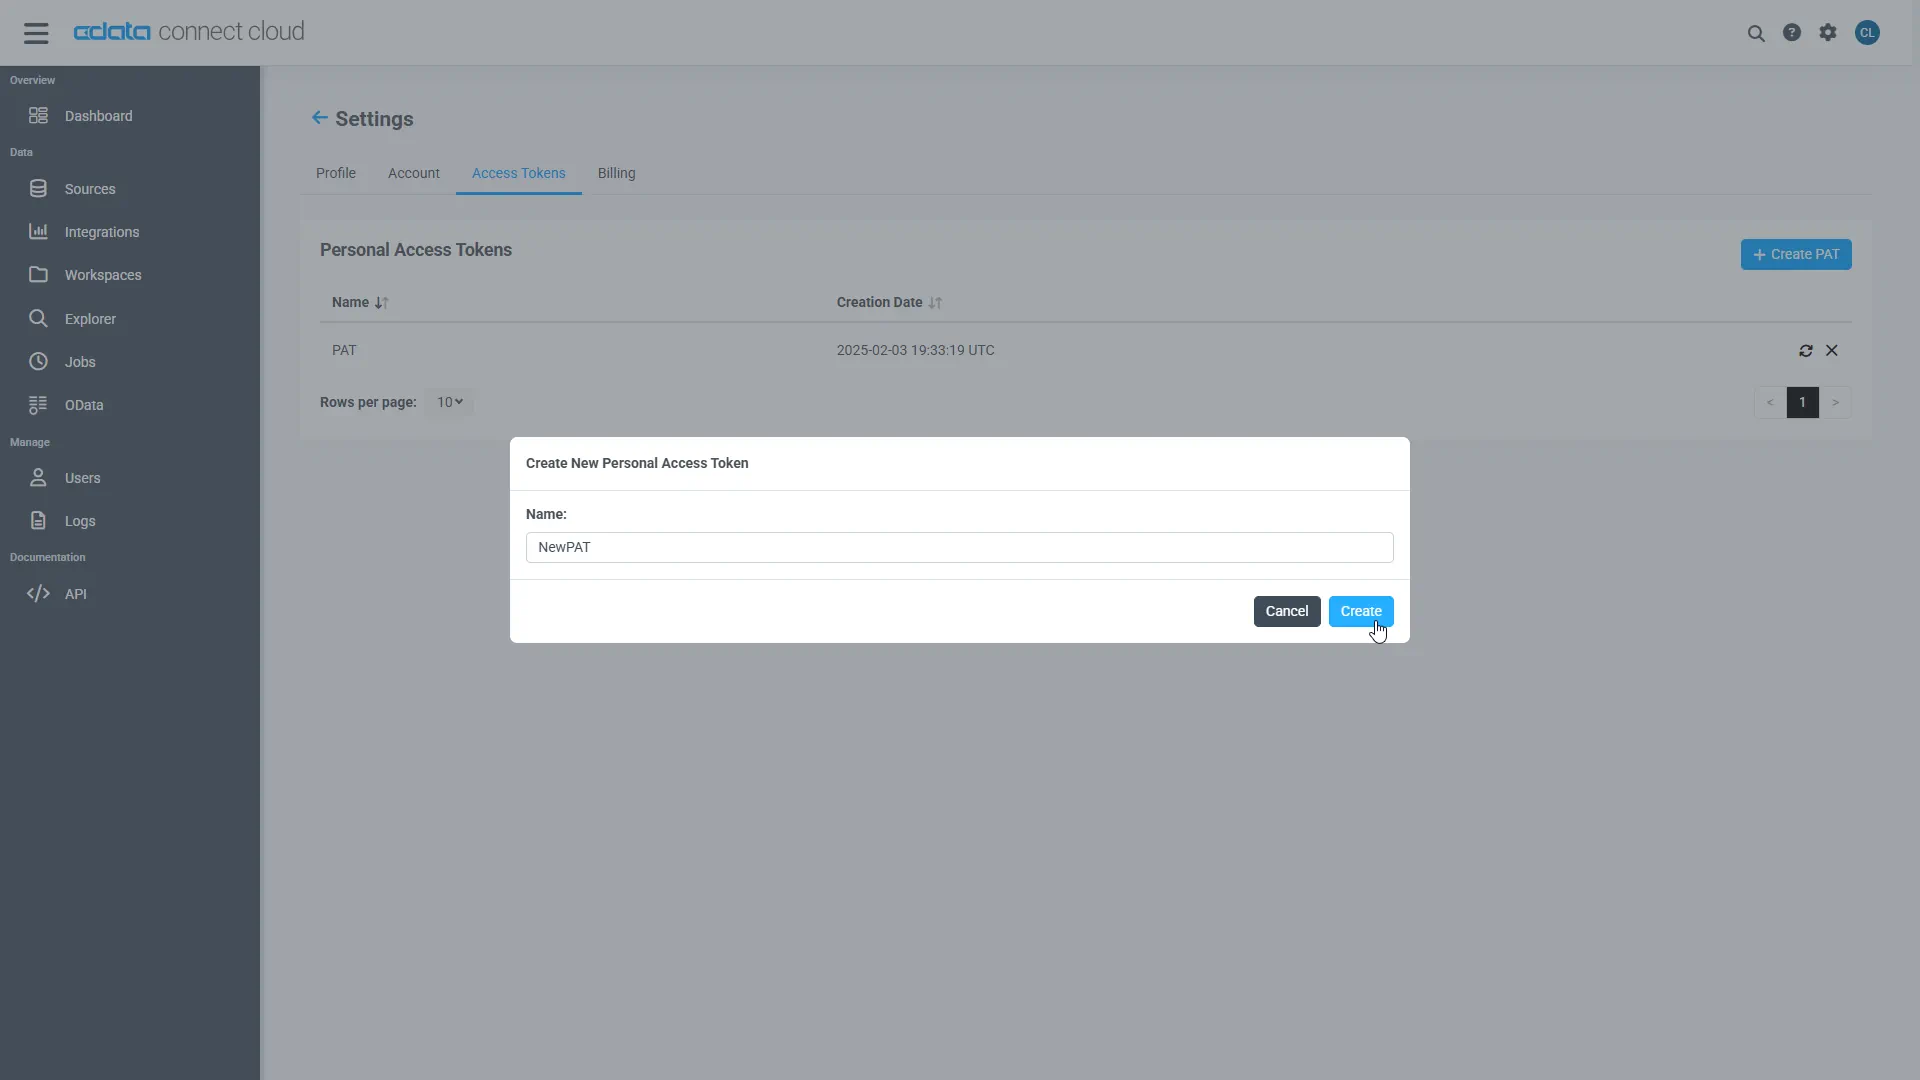
- The PAT is only visible at creation, so copy it and store it securely.
Install the SDK
Install the SDK from PyPI with pip:
pip install cdata-connect-ai
Connect and Run Your First Query
Connect with your account email and PAT, then query sys_tables to discover every table available across your connected sources. Identifiers in Connect AI are three-part: <Connection>.<Schema>.<Table>, where the connection name defaults to the source name (for example, ApacheKafka1).
import cdata_connect_ai

conn = cdata_connect_ai.connect(
    username="[email protected]",
    password="<your_pat>",
)
cur = conn.cursor()

# Discover what's available across your connected sources
cur.execute("SELECT CatalogName, SchemaName, TableName FROM sys_tables LIMIT 25")

for row in cur.fetchall():
    print(row)
Pick any table from the results and query it directly:
cur.execute(
    "SELECT Id, Column1 "
    "FROM [ApacheKafka1].[ApacheKafka].[SampleTable_1] "
    "LIMIT 10"
)

for row in cur.fetchall():
    print(row)
Write Back to Kafka
When the data source and your connection permissions allow it, the same cursor runs INSERT, UPDATE, and DELETE statements. Bind values with pyformat (%(name)s) parameters, exactly as you would for a filtered read, and check cursor.rowcount for the number of affected rows.
# Insert a new record
cur.execute(
    "INSERT INTO [ApacheKafka1].[ApacheKafka].[SampleTable_1] (Id) "
    "VALUES (%(newvalue)s)",
    {"newvalue": "Example value"},
)
print(f"Rows inserted: {cur.rowcount}")

# Update existing records
cur.execute(
    "UPDATE [ApacheKafka1].[ApacheKafka].[SampleTable_1] "
    "SET Column1 = %(newvalue)s "
    "WHERE Column2 = '100'",
    {"newvalue": "Updated value"},
)
print(f"Rows updated: {cur.rowcount}")

conn.close()
Note: Even for writable sources, a read-only PAT or connection permission will reject write operations. The same parameterized pattern also covers DELETE statements and stored procedures through cursor.callproc().
That is the entire workflow: one package, a PAT, and standard DB-API calls. Because the SDK returns a normal DB-API connection, it drops straight into the rest of the Python data ecosystem. From here you can load Kafka data into pandas, build ETL pipelines with petl, or power a Dash web app, all using this same connection.
More Information and Free Trial
Now you can query live Kafka data from Python through the CData Connect AI Python SDK. For more information on connecting to Kafka (and hundreds of other data sources), visit the Connect AI page. Sign up for a free trial and start working with live Kafka data in Python.